BONUS!!! CertShiken Databricks-Certified-Professional-Data-Engineerダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1dj7FlB2VZOVbTTDli4lbz1u8X8JXa-Wc
当社CertShikenは、製品の品質が非常に重要であることを深く知っているため、Databricks-Certified-Professional-Data-Engineerテストトレントの高品質の開発に注力しています。当社の製品を購入したすべてのお客様は、Databricks-Certified-Professional-Data-Engineerガイド急流に深い印象を残しています。もちろん、顧客は製品の高品質だけでなく、製品の効率性にも深い印象を残しています。 Databricks-Certified-Professional-Data-Engineer試験の質問は多くの時間を節約するのに役立ちます。Databricks-Certified-Professional-Data-Engineer試験準備を使用する場合、学習に20〜30時間を費やすだけで、Databricks-Certified-Professional-Data-Engineer試験に合格できます。
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Certificate Validity Period: | 2 years |
| Exam Duration: | 90 minutes |
| Exam Format: | Multiple Select, Multiple Choice |
| Real Exam Qty: | 60 |
| Exam Price: | $200 USD |
| Passing Score: | 70% |
| Available Languages: | English |
| Related Certifications: | Databricks Certified Associate Developer Databricks Certified Data Analyst Associate |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: 6+ months of hands-on experience with Databricks and data engineering concepts; familiarity with Python or Scala and SQL is strongly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/professional-data-engineer |
>> Databricks-Certified-Professional-Data-Engineerミシュレーション問題 <<
DatabricksのDatabricks-Certified-Professional-Data-Engineer試験の準備をしていたら、CertShikenは貴方が夢を実現することにヘルプを与えます。 CertShikenのDatabricksのDatabricks-Certified-Professional-Data-Engineer試験トレーニング資料は高品質のトレーニング資料で、100パーセントの合格率を保証できます。もしあなたが適当な時間を持って勉強できるのなら、CertShikenのDatabricksのDatabricks-Certified-Professional-Data-Engineer試験トレーニング資料を選びましょう。この資料を手に入れたら、楽に試験の準備をすることができます。
Databricks Certified Professional Data Engineer試験に合格することは、ビッグデータとクラウドコンピューティングのキャリアを追求している個人にとって重要な成果になる可能性があります。この認定は、候補者がApache Sparkの深い理解を持ち、それを活用してスケーラブルなビッグデータソリューションを設計および実装できることを示しています。さらに、この認定は業界の多くの企業に認められており、候補者が高収入の仕事を得る可能性を高めることができます。
質問 # 43
Which of the following commands results in the successful creation of a view on top of the delta stream(stream on delta table)?
正解:F
解説:
Explanation
The answer is
Spark.readStream.table("sales").createOrReplaceTempView("streaming_vw") When you load a Delta table as a stream source and use it in a streaming query, the query processes all of the data present in the table as well as any new data that arrives after the stream is started.
You can load both paths and tables as a stream, you also have the ability to ignore deletes and changes(updates, Merge, overwrites) on the delta table.
Here is more information,
https://docs.databricks.com/delta/delta-streaming.html#delta-table-as-a-source
質問 # 44
A data engineer is configuring Delta Sharing for a Databricks-to-Databricks scenario to optimize read performance. The recipient needs to perform time travel queries and streaming reads on shared sales data.
Which configuration will provide the optimal performance while enabling these capabilities?
正解:D
解説:
The official Delta Sharing guidance specifies that in order for recipients to use time travel queries and streaming reads , providers must share Delta tables WITH HISTORY . Sharing history ensures the Delta log is included, which enables efficient access to table snapshots and incremental data streams. Additionally, Change Data Feed (CDF) must be enabled prior to sharing if downstream consumers require streaming CDC queries. Without history, recipients cannot perform time travel or streaming queries. Open sharing supports static Delta tables but lacks streaming support. Therefore, sharing tables WITH HISTORY and enabling CDF is the required configuration for both performance and functionality.
質問 # 45
A table in the Lakehouse namedcustomer_churn_paramsis used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
正解:B
解説:
Explanation
This is the correct answer because the JSON posted to the Databricks REST API endpoint 2.0/jobs/create defines a new job with an existing cluster id and a notebook task, but also specifies a new cluster spec with some configurations. According to the documentation, if both an existing cluster id and a new cluster spec are provided, then a new cluster will be created for each run of the job with those configurations, and then terminated after completion. Therefore, the logic defined in the referenced notebook will be executed three times on new clusters with those configurations. Verified References: [Databricks Certified Data Engineer Professional], under "Monitoring & Logging" section; Databricks Documentation, under
"JobsClusterSpecNewCluster" section.
質問 # 46
Although the Databricks Utilities Secrets module provides tools to store sensitive credentials and avoid accidentally displaying them in plain text users should still be careful with which credentials are stored here and which users have access to using these secrets.
Which statement describes a limitation of Databricks Secrets?
正解:A
解説:
Explanation
This is the correct answer because it describes a limitation of Databricks Secrets. Databricks Secrets is a module that provides tools to store sensitive credentials and avoid accidentally displaying them in plain text.
Databricks Secrets allows creating secret scopes, which are collections of secrets that can be accessed by users or groups. Databricks Secrets also allows creating and managing secrets using the Databricks CLI or the Databricks REST API. However, a limitation of Databricks Secrets is that the Databricks REST API can be used to list secrets in plain text if the personal access token has proper credentials. Therefore, users should still be careful with which credentials are stored in Databricks Secrets and which users have access to using these secrets. Verified References: [Databricks Certified Data Engineer Professional], under "Databricks Workspace" section; Databricks Documentation, under "List secrets" section.
質問 # 47
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.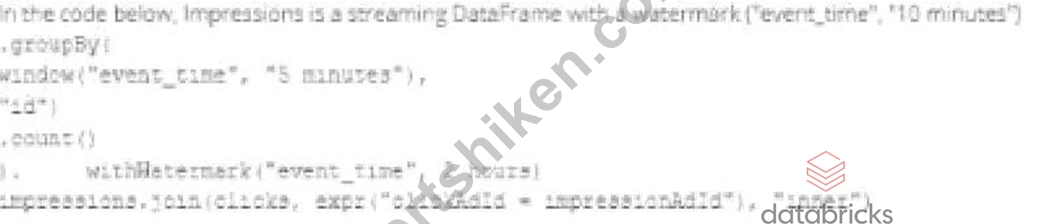
Which solution would improve the performance?




正解:D
解説:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time.
However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
質問 # 48
......
Databricks-Certified-Professional-Data-Engineer資格問題対応: https://www.certshiken.com/Databricks-Certified-Professional-Data-Engineer-shiken.html
ちなみに、CertShiken Databricks-Certified-Professional-Data-Engineerの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1dj7FlB2VZOVbTTDli4lbz1u8X8JXa-Wc