2026 Efficient Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional New Test Materials

Every Databricks aspirant wants to pass the Databricks Certified-Data-Engineer-Professional exam to achieve high-paying jobs and promotions. The biggest issue Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam applicants face is that they don't find credible platforms to buy Real Certified-Data-Engineer-Professional Exam Dumps. When candidates don't locate actual Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions they prepare from outdated material and ultimately lose resources.
| Section | Objectives |
|---|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Apply Change Data Feed to address streaming table limitations and improve latency
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
|
| Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 6. Create pipeline components using control flow operators such as if/else and foreach
- 7. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 8. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
|
| Data Modeling | - Design and optimize data models
- 1. Design dimensional models for analytical workloads with efficient querying and aggregation
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
>> Certified-Data-Engineer-Professional New Test Materials <<
Certified-Data-Engineer-Professional Latest Test Sample & Clearer Certified-Data-Engineer-Professional Explanation
Getcertkey provide you with a clear and excellent choice and reduce your troubles. Do you want early success? Do you want to quickly get Databricks Certification Certified-Data-Engineer-Professional Exam certificate? Hurry to add Getcertkey to your Shopping Cart. Getcertkey will give you a good guide to ensure you pass the exam. Using Getcertkey can quickly help you get the certificate you want.
Databricks Certified Data Engineer Professional Sample Questions (Q74-Q79):
NEW QUESTION # 74
A user new to Databricks is trying to troubleshoot long execution times for some pipeline logic they are working on. Presently, the user is executing code cell-by-cell, using display() calls to confirm code is producing the logically correct results as new transformations are added to an operation. To get a measure of average time to execute, the user is running each cell multiple times interactively.
Which of the following adjustments will get a more accurate measure of how code is likely to perform in production?
- A. Calling display () forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results.
- B. Production code development should only be done using an IDE; executing code against a local build of open source Spark and Delta Lake will provide the most accurate benchmarks for how code will perform in production.
- C. The Jobs Ul should be leveraged to occasionally run the notebook as a job and track execution time during incremental code development because Photon can only be enabled on clusters launched for scheduled jobs.
- D. Scala is the only language that can be accurately tested using interactive notebooks; because the best performance is achieved by using Scala code compiled to JARs. all PySpark and Spark SQL logic should be refactored.
- E. The only way to meaningfully troubleshoot code execution times in development notebooks Is to use production-sized data and production-sized clusters with Run All execution.
Answer: E
NEW QUESTION # 75
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
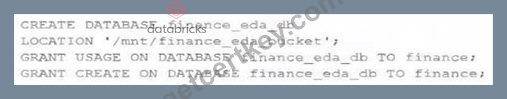
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
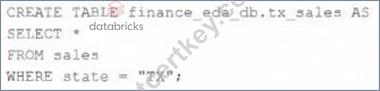
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. An managed table will be created in the storage container mounted to /mnt/finance_eda_bucket.
- B. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
- C. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
- D. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
- E. A managed table will be created in the DBFS root storage container.
Answer: A
Explanation:
https://docs.databricks.com/en/data-governance/unity-catalog/create-schemas.html#language-SQL
NEW QUESTION # 76
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is named store_saies_summary and the schema is as follows:

The table daily_store_sales contains all the information needed to update store_sales_summary.
The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
If daily_store_sales is implemented as a Type 1 table and the total_sales column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in the store_sales_summary table?
- A. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and overwrite the store_sales_summary table with each Update.
- B. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- C. Implement the appropriate aggregate logic as a Structured Streaming read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- D. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and append new rows nightly to the store_sales_summary table.
- E. Use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update.
Answer: A
NEW QUESTION # 77
A data engineer is designing an append-only pipeline that needs to handle both batch and streaming data in Delta Lake. The team wants to ensure that the streaming component can efficiently track which data has already been processed. Which configuration should be set to enable this?
- A. partitionBy
- B. overwriteSchema
- C. checkpointLocation
- D. mergeSchema
Answer: C
Explanation:
When working with Delta Lake streaming ingestion, checkpointing is critical for maintaining fault tolerance and ensuring exactly-once data processing semantics.
The checkpointLocation parameter defines the directory where Spark Structured Streaming stores progress information, offsets, and metadata. This allows the engine to resume processing from the last committed offset without reprocessing previously ingested data.
Without checkpointing, each stream restart would reprocess all data, leading to duplicates.
Parameters like partitionBy or schema options (mergeSchema / overwriteSchema) affect table structure, not data lineage tracking. Therefore, the correct and required configuration for efficient streaming state management is checkpointLocation.
NEW QUESTION # 78
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
- A. All records are cached to an operational database and then the filter is applied
- B. The Delta log is scanned for min and max statistics for the latitude column
- C. The Parquet file footers are scanned for min and max statistics for the latitude column
- D. All records are cached to attached storage and then the filter is applied
- E. The Hive metastore is scanned for min and max statistics for the latitude column
Answer: B
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column.
NEW QUESTION # 79
......
There are totally three versions of Certified-Data-Engineer-Professional practice materials which are the most suitable versions for you: PDF, software and app versions. We promise ourselves and exam candidates to make these Certified-Data-Engineer-Professional preparation prep top notch. So if you are in a dark space, our Certified-Data-Engineer-Professional Study Guide can inspire you make great improvements. With the high pass rate of our Certified-Data-Engineer-Professional learing engine as 98% to 100%, you can be confident and ready to pass the exam easily.
Certified-Data-Engineer-Professional Latest Test Sample: https://www.getcertkey.com/Certified-Data-Engineer-Professional_braindumps.html
- Databricks Certified Data Engineer Professional sure pass guide - Certified-Data-Engineer-Professional pdf study torrent 🦝 Open website ( www.examcollectionpass.com ) and search for “ Certified-Data-Engineer-Professional ” for free download 🤙Certified-Data-Engineer-Professional Actual Test
- Real Certified-Data-Engineer-Professional Exam 🎪 Certified-Data-Engineer-Professional Latest Test Labs ✳ Exam Certified-Data-Engineer-Professional Testking 🎀 Easily obtain free download of ▶ Certified-Data-Engineer-Professional ◀ by searching on ➥ www.pdfvce.com 🡄 🤪Flexible Certified-Data-Engineer-Professional Testing Engine
- Exam Certified-Data-Engineer-Professional Topics 🙁 Exam Certified-Data-Engineer-Professional Introduction 🖼 Latest Braindumps Certified-Data-Engineer-Professional Ebook 🌮 Immediately open ➡ www.dumpsquestion.com ️⬅️ and search for ⮆ Certified-Data-Engineer-Professional ⮄ to obtain a free download 👴Exam Certified-Data-Engineer-Professional Topics
- Customizable Practice Test for Improved Success in Databricks Certified-Data-Engineer-Professional Certification Exam 📱 Open ➽ www.pdfvce.com 🢪 and search for “ Certified-Data-Engineer-Professional ” to download exam materials for free 🏹Certified-Data-Engineer-Professional Latest Test Labs
- Exam Certified-Data-Engineer-Professional Testking 🎀 Certified-Data-Engineer-Professional Actual Test 🐾 Exam Certified-Data-Engineer-Professional Introduction 🪀 Download ▛ Certified-Data-Engineer-Professional ▟ for free by simply searching on ➤ www.easy4engine.com ⮘ 🐑Exam Certified-Data-Engineer-Professional Simulations
- Certified-Data-Engineer-Professional Exam Braindumps 🏰 Latest Certified-Data-Engineer-Professional Exam Discount 🏀 Certified-Data-Engineer-Professional Reliable Test Topics 👬 Immediately open ⇛ www.pdfvce.com ⇚ and search for 「 Certified-Data-Engineer-Professional 」 to obtain a free download 🧂Real Certified-Data-Engineer-Professional Exam
- Exam Certified-Data-Engineer-Professional Simulations ☃ Real Certified-Data-Engineer-Professional Exam Questions 🔀 Certified-Data-Engineer-Professional Latest Test Labs 🌽 Simply search for ➤ Certified-Data-Engineer-Professional ⮘ for free download on ⏩ www.vce4dumps.com ⏪ 🥙Exam Certified-Data-Engineer-Professional Topics
- Databricks Certified-Data-Engineer-Professional New Test Materials: Databricks Certified Data Engineer Professional - Certification Success Guaranteed, Easy Way of Training 🧁 Download 《 Certified-Data-Engineer-Professional 》 for free by simply entering ☀ www.pdfvce.com ️☀️ website ❓Certified-Data-Engineer-Professional Reliable Test Topics
- Customizable Practice Test for Improved Success in Databricks Certified-Data-Engineer-Professional Certification Exam 🌼 Simply search for 《 Certified-Data-Engineer-Professional 》 for free download on “ www.exam4labs.com ” 🤞Exam Certified-Data-Engineer-Professional Topics
- Certified-Data-Engineer-Professional Actual Test 👾 Latest Certified-Data-Engineer-Professional Exam Questions Vce 🔛 Flexible Certified-Data-Engineer-Professional Testing Engine 🦈 ➤ www.pdfvce.com ⮘ is best website to obtain ➡ Certified-Data-Engineer-Professional ️⬅️ for free download ⚜Certified-Data-Engineer-Professional Actual Test
- Latest Certified-Data-Engineer-Professional Exam Question 🤹 Practice Test Certified-Data-Engineer-Professional Fee 🐏 Certified-Data-Engineer-Professional Reliable Practice Materials ➡ Search on ✔ www.dumpsmaterials.com ️✔️ for 「 Certified-Data-Engineer-Professional 」 to obtain exam materials for free download 🔟Latest Certified-Data-Engineer-Professional Test Answers
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes