BTW, DOWNLOAD part of PracticeDump DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1LhUAMazRNMBjcXPZKtq1p3FtOrLpqQ_q
In today's technological world, more and more students are taking the Designing and Implementing a Data Science Solution on Azure (DP-100) exam online. While this can be a convenient way to take a Designing and Implementing a Data Science Solution on Azure (DP-100) exam dumps, it can also be stressful. Luckily, PracticeDump's best Microsoft DP-100 exam questions can help you prepare for your Microsoft DP-100 Certification Exam and reduce your stress. If you are preparing for the Designing and Implementing a Data Science Solution on Azure (DP-100) exam dumps our DP-100 Questions help you to get high scores in your Designing and Implementing a Data Science Solution on Azure (DP-100) exam.
| Topic | Details |
|---|---|
Manage Azure resources for machine learning (25-30%) | |
| Create an Azure Machine Learning workspace | - create an Azure Machine Learning workspace - configure workspace settings - manage a workspace by using Azure Machine Learning studio |
| Manage data in an Azure Machine Learning workspace | - select Azure storage resources - register and maintain datastores - create and manage datasets |
| Manage compute for experiments in Azure Machine Learning | - determine the appropriate compute specifications for a training workload - create compute targets for experiments and training - configure Attached Compute resources including Azure Databricks - monitor compute utilization |
| Implement security and access control in Azure Machine Learning | - determine access requirements and map requirements to built-in roles - create custom roles - manage role membership - manage credentials by using Azure Key Vault |
| Set up an Azure Machine Learning development environment | - create compute instances - share compute instances - access Azure Machine Learning workspaces from other development environments |
| Set up an Azure Databricks workspace | - create an Azure Databricks workspace - create an Azure Databricks cluster - create and run notebooks in Azure Databricks - link and Azure Databricks workspace to an Azure Machine Learning workspace |
Run Experiments and Train Models (20-25%) | |
| Create models by using the Azure Machine Learning Designer | - create a training pipeline by using Azure Machine Learning designer - ingest data in a designer pipeline - use designer modules to define a pipeline data flow - use custom code modules in designer |
| Run model training scripts | - create and run an experiment by using the Azure Machine Learning SDK - configure run settings for a script - consume data from a dataset in an experiment by using the Azure Machine Learning SDK - run a training script on Azure Databricks compute - run code to train a model in an Azure Databricks notebook |
| Generate metrics from an experiment run | - log metrics from an experiment run - retrieve and view experiment outputs - use logs to troubleshoot experiment run errors - use MLflow to track experiments - track experiments running in Azure Databricks |
| Use Automated Machine Learning to create optimal models | - use the Automated ML interface in Azure Machine Learning studio - use Automated ML from the Azure Machine Learning SDK - select pre-processing options - select the algorithms to be searched - define a primary metric - get data for an Automated ML run - retrieve the best model |
| Tune hyperparameters with Azure Machine Learning | - select a sampling method - define the search space - define the primary metric - define early termination options - find the model that has optimal hyperparameter values |
Deploy and operationalize machine learning solutions (35-40%) | |
>> DP-100 Real Exam Questions <<
We have applied the latest technologies to the design of our DP-100 exam prep not only on the content but also on the displays. As a consequence you are able to keep pace with the changeable world and remain your advantages with our DP-100 training braindumps. Besides, you can consolidate important knowledge for you personally and design customized study schedule or to-do list on a daily basis. As long as you follow with our DP-100 Study Guide, you are doomed to achieve your success.
The Microsoft DP-100 exam comprises of multiple-choice questions and performance-based tasks that measure the candidate's ability to implement data solutions, analyze data, and create machine learning models using Azure technologies. DP-100 Exam is designed to evaluate the candidate's skills in various areas such as data preprocessing, model selection, data visualization, and deployment.
NEW QUESTION # 419
You are building an intelligent solution using machine learning models.
The environment must support the following requirements:
* Data scientists must build notebooks in a cloud environment
* Data scientists must use automatic feature engineering and model building in machine learning pipelines.
* Notebooks must be deployed to retrain using Spark instances with dynamic worker allocation.
* Notebooks must be exportable to be version controlled locally.
You need to create the environment.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.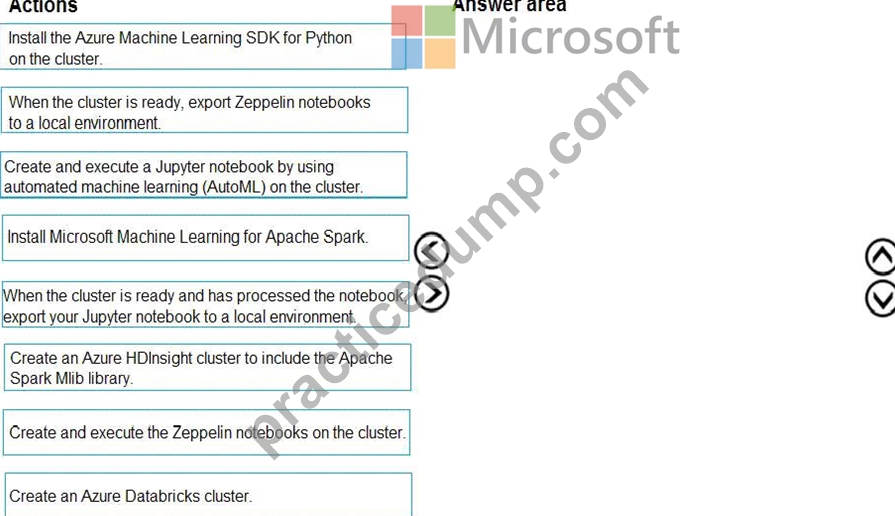
Answer:
Explanation: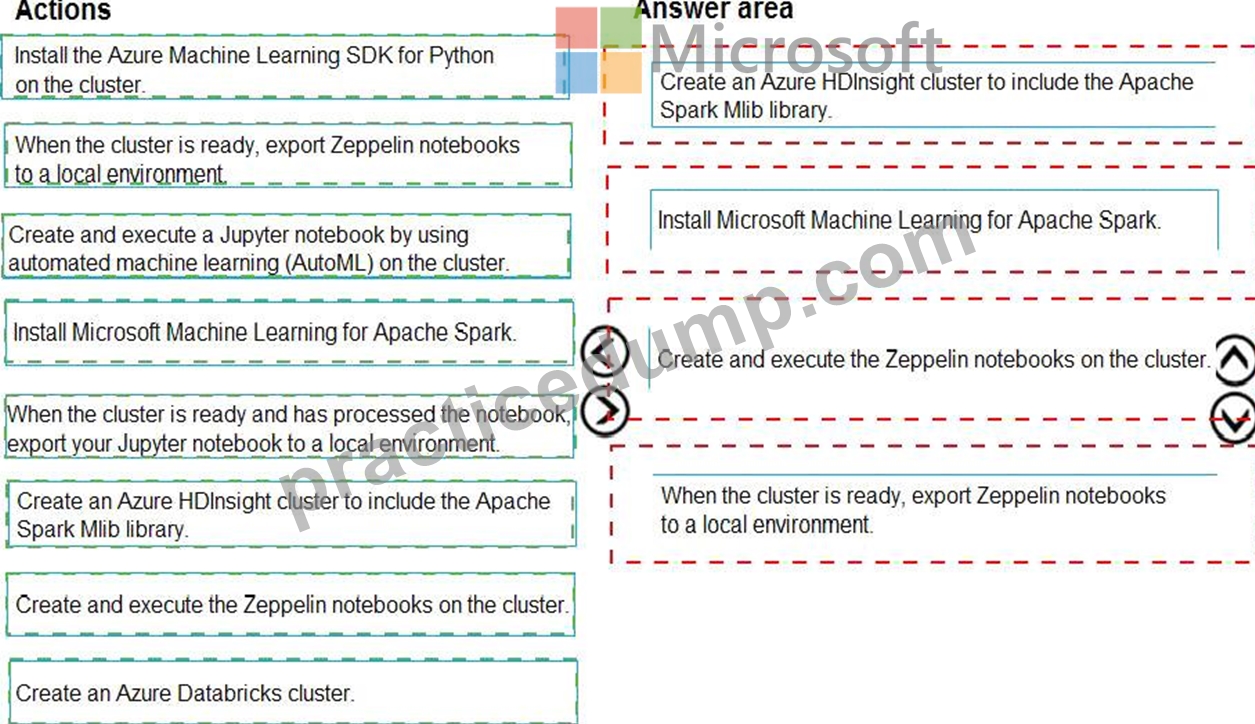
Explanation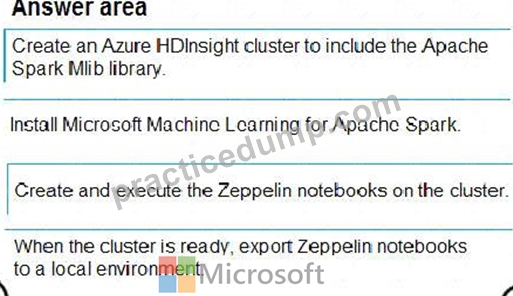
Step 1: Create an Azure HDInsight cluster to include the Apache Spark Mlib library Step 2: Install Microsot Machine Learning for Apache Spark You install AzureML on your Azure HDInsight cluster.
Microsoft Machine Learning for Apache Spark (MMLSpark) provides a number of deep learning and data science tools for Apache Spark, including seamless integration of Spark Machine Learning pipelines with Microsoft Cognitive Toolkit (CNTK) and OpenCV, enabling you to quickly create powerful, highly-scalable predictive and analytical models for large image and text datasets.
Step 3: Create and execute the Zeppelin notebooks on the cluster
Step 4: When the cluster is ready, export Zeppelin notebooks to a local environment.
Notebooks must be exportable to be version controlled locally.
References:
https://docs.microsoft.com/en-us/azure/hdinsight/spark/apache-spark-zeppelin-notebook
https://azuremlbuild.blob.core.windows.net/pysparkapi/intro.html
NEW QUESTION # 420
Hotspot Question
You are evaluating a Python NumPy array that contains six data points defined as follows:
data = [10, 20, 30, 40, 50, 60]
You must generate the following output by using the k-fold algorithm implantation in the Python Scikit-learn machine learning library:
train: [10 40 50 60], test: [20 30]
train: [20 30 40 60], test: [10 50]
train: [10 20 30 50], test: [40 60]
You need to implement a cross-validation to generate the output.
How should you complete the code segment? To answer, select the appropriate code segment in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.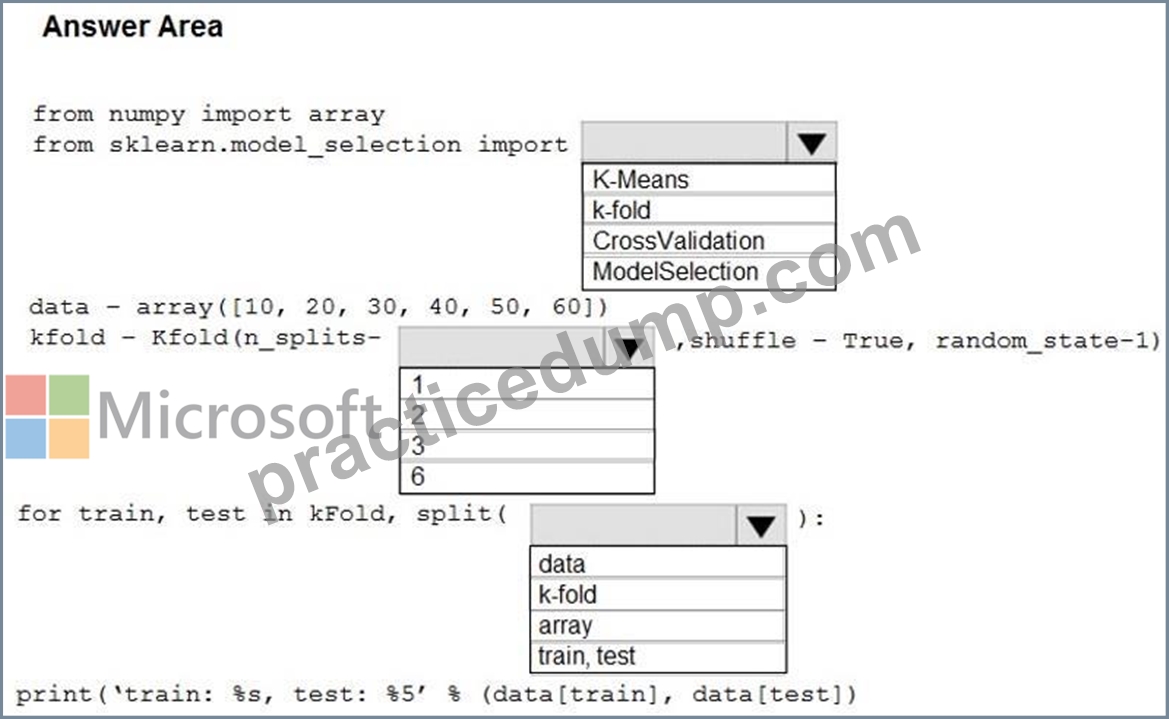
Answer:
Explanation: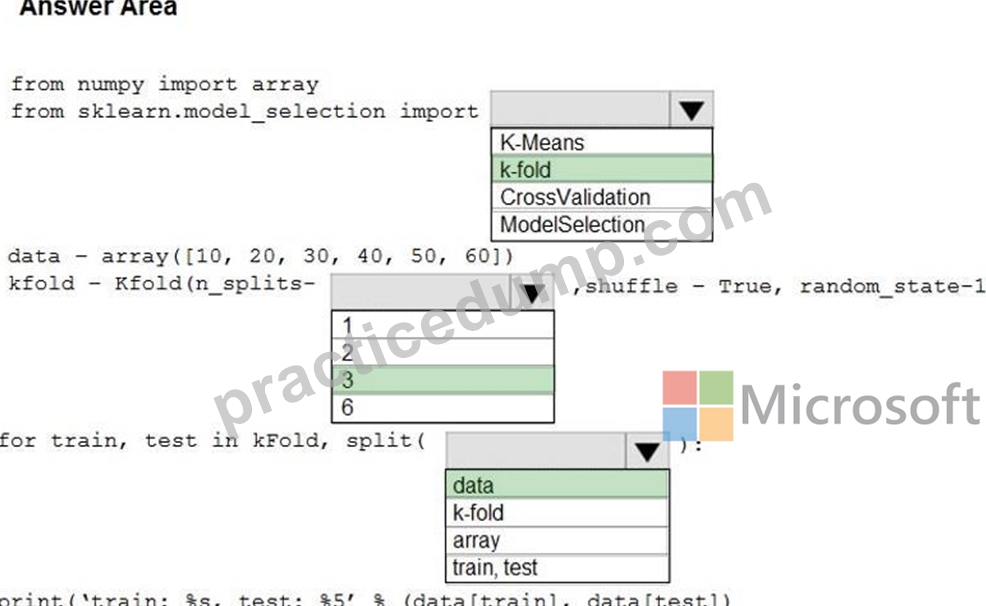
Explanation:
Box 1: k-fold
Box 2: 3
K-Folds cross-validator provides train/test indices to split data in train/test sets. Split dataset into k consecutive folds (without shuffling by default). The parameter n_splits ( int, default=3) is the number of folds. Must be at least 2.
Box 3: data
Example: Example:
>>>
>>> from sklearn.model_selection import KFold
>>> X = np.array([[1, 2], [3, 4], [1, 2], [3, 4]])
>>> y = np.array([1, 2, 3, 4])
>>> kf = KFold(n_splits=2)
>>> kf.get_n_splits(X)
>>> print(kf)
KFold(n_splits=2, random_state=None, shuffle=False)
>>> for train_index, test_index in kf.split(X):
... print("TRAIN:", train_index, "TEST:", test_index)
... X_train, X_test = X[train_index], X[test_index]
... y_train, y_test = y[train_index], y[test_index]
TRAIN: [2 3] TEST: [0 1]
TRAIN: [0 1] TEST: [2 3]
References:
https://scikit-learn.org/stable/modules/generated/sklearn.model_selection.KFold.html
NEW QUESTION # 421
You are using C-Support Vector classification to do a multi-class classification with an unbalanced training dataset. The C-Support Vector classification using Python code shown below: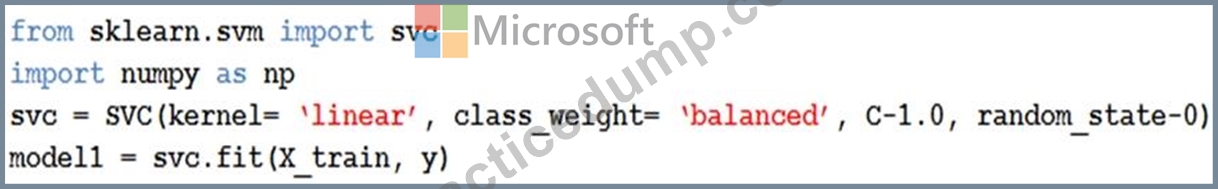
You need to evaluate the C-Support Vector classification code.
Which evaluation statement should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.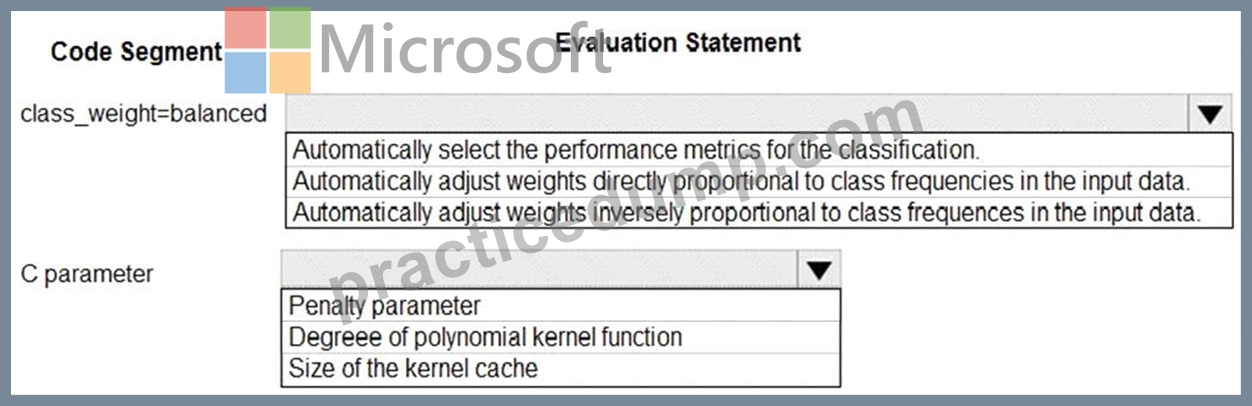
Answer:
Explanation: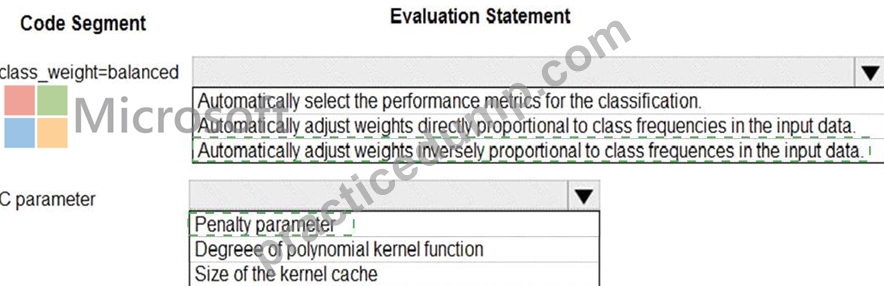
Explanation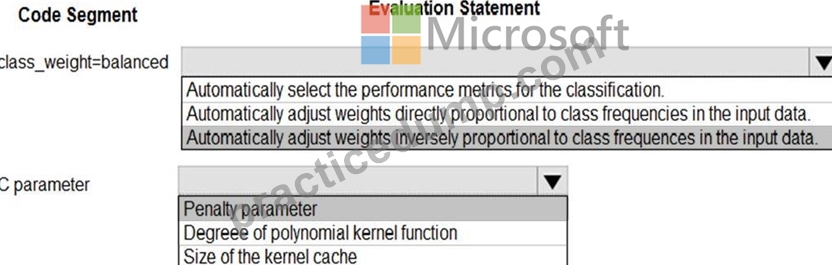
Box 1: Automatically adjust weights inversely proportional to class frequencies in the input data The "balanced" mode uses the values of y to automatically adjust weights inversely proportional to class frequencies in the input data as n_samples / (n_classes * np.bincount(y)).
Box 2: Penalty parameter
Parameter: C : float, optional (default=1.0)
Penalty parameter C of the error term.
References:
https://scikit-learn.org/stable/modules/generated/sklearn.svm.SVC.html
NEW QUESTION # 422
You are developing code to analyse a dataset that includes age information for a large group of diabetes patients. You create an Azure Machine Learning workspace and install all required libraries. You set the privacy budget to 1.0).
You must analyze the dataset and preserve data privacy. The code must run twice before the privacy budget is depleted.
You need to complete the code.
Which values should you use? To answer, select the appropriate options m the answer area.
NOTE: Each correct selection is worth one point.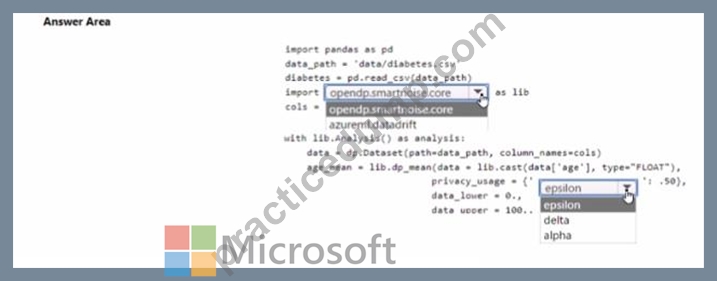
Answer:
Explanation: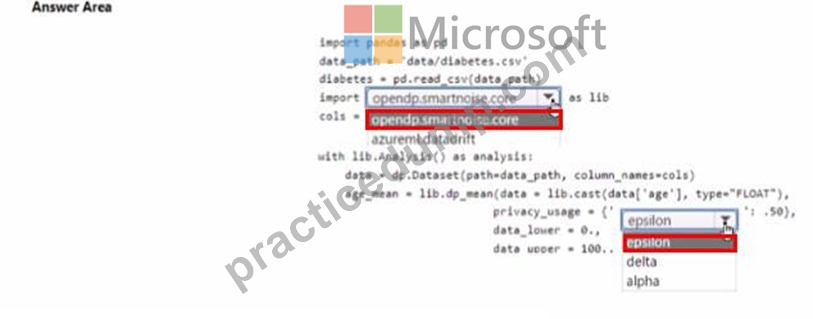
NEW QUESTION # 423
You are evaluating a Python NumPy array that contains six data points defined as follows:
data = [10, 20, 30, 40, 50, 60]
You must generate the following output by using the k-fold algorithm implantation in the Python Scikit-learn machine learning library:
train: [10 40 50 60], test: [20 30]
train: [20 30 40 60], test: [10 50]
train: [10 20 30 50], test: [40 60]
You need to implement a cross-validation to generate the output.
How should you complete the code segment? To answer, select the appropriate code segment in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.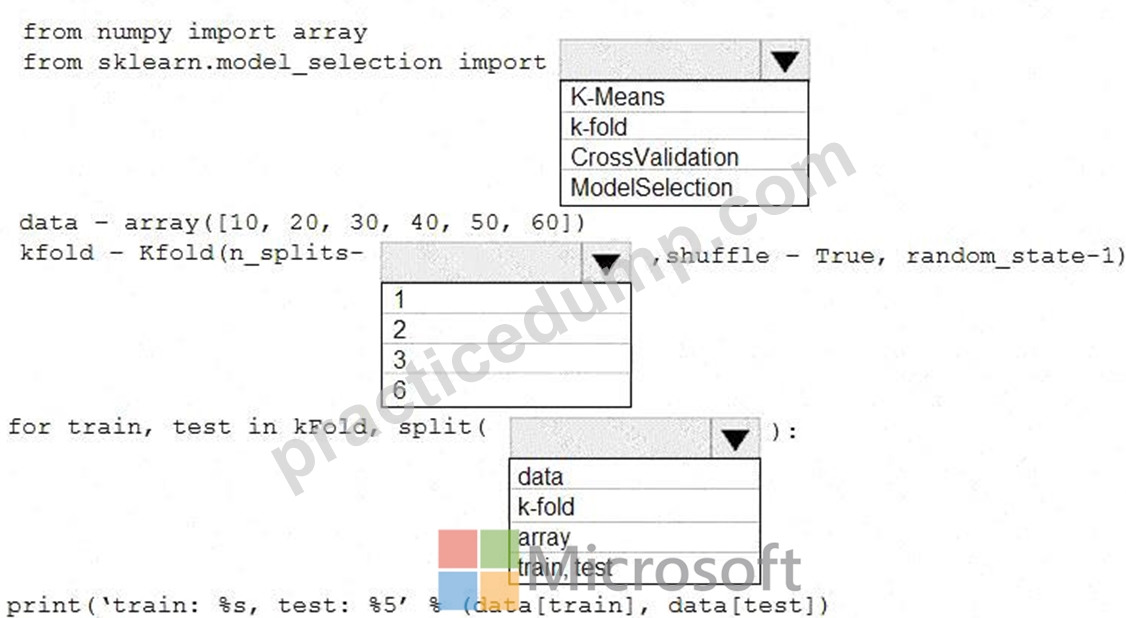
Answer:
Explanation: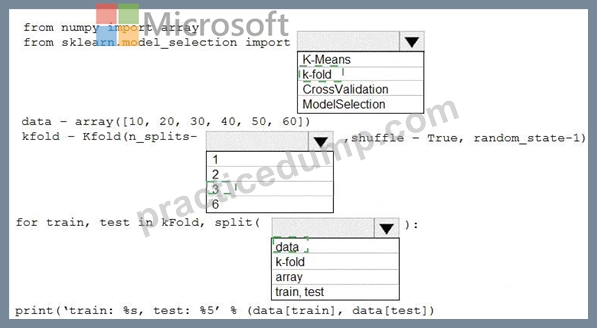
Explanation: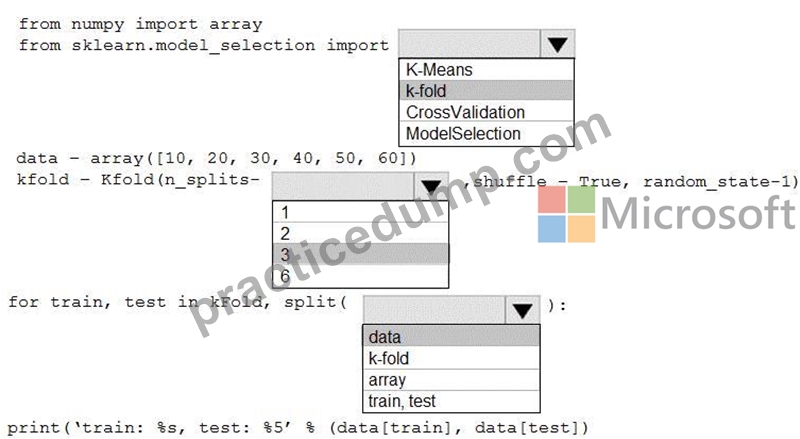
Box 1: k-fold
Box 2: 3
K-Folds cross-validator provides train/test indices to split data in train/test sets. Split dataset into k consecutive folds (without shuffling by default).
The parameter n_splits ( int, default=3) is the number of folds. Must be at least 2.
Box 3: data
Example: Example:
> > >
> > > from sklearn.model_selection import KFold
> > > X = np.array([[1, 2], [3, 4] , [1, 2], [3, 4]] )
> > > y = np.array([1, 2, 3, 4])
> > > kf = KFold(n_splits=2)
> > > kf.get_n_splits(X)
2
> > > print(kf)
KFold(n_splits=2, random_state=None, shuffle=False)
> > > for train_index, test_index in kf.split(X):
print( " TRAIN: " , train_index, " TEST: " , test_index)
X_train, X_test = X[train_index], X[test_index]
y_train, y_test = y[train_index], y[test_index]
TRAIN: [2 3] TEST: [0 1]
TRAIN: [0 1] TEST: [2 3]
References:
https://scikit-learn.org/stable/modules/generated/sklearn.model_selection.KFold.html
NEW QUESTION # 424
......
DP-100 High Passing Score: https://www.practicedump.com/DP-100_actualtests.html
DOWNLOAD the newest PracticeDump DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1LhUAMazRNMBjcXPZKtq1p3FtOrLpqQ_q