Fantastic Reliable Databricks-Certified-Data-Engineer-Professional Exam Dumps - 100% Pass Databricks-Certified-Data-Engineer-Professional Exam

Dear every IT candidates, here, I will recommend TorrentValid Databricks-Certified-Data-Engineer-Professional exam training material to all of you. If you use Databricks Databricks-Certified-Data-Engineer-Professional test bootcamp, you will not need to purchase anything else or attend other training. We promise that you can pass your Databricks-Certified-Data-Engineer-Professional Certification at first attempt. The high pass rate has helped lots of IT candidates get their IT certification. In case of failure, we promise to give you full refund. No help, full refund!
| Section | Weight | Objectives |
|---|
| Databricks Lakehouse Platform | 24% | - Lakehouse Architecture
- Unity Catalog
- Delta Lake
- Data Management
|
| Data Quality and Governance | 12% | - Data Quality
- Governance
- Data Lineage
|
| Data Processing | 28% | - ETL Pipelines
- Structured Streaming
- Data Transformation
- Spark SQL
|
| Data Modeling and Storage | 20% | - Storage Optimization
- Data Modeling
- File Formats
|
| Monitoring and Troubleshooting | 16% | - Monitoring
- Troubleshooting
- Performance Optimization
|
>> Reliable Databricks-Certified-Data-Engineer-Professional Exam Dumps <<
Pass Guaranteed Quiz Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam –Reliable Reliable Exam Dumps
The Databricks Databricks-Certified-Data-Engineer-Professional exam questions are being offered in three different formats. The names of these formats are Databricks Databricks-Certified-Data-Engineer-Professional PDF dumps file, desktop practice test software, and web-based practice test software. All these three Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions formats are easy to use and assist you in Databricks Databricks-Certified-Data-Engineer-Professional exam preparation.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q233-Q238):
NEW QUESTION # 233
A developer has successfully configured their credentials for Databricks Repos and cloned a remote Git repository. They do not have privileges to make changes to the main branch, which is the only branch currently visible in their workspace. Which approach allows this user to share their code updates without the risk of overwriting the work of their teammates?
- A. Use Repos to pull changes from the remote Git repository; commit and push changes to a branch that appeared as changes were pulled.
- B. Use repos to merge all difference and make a pull request back to the remote repository.
- C. Use repos to create a fork of the remote repository commit all changes and make a pull request on the source repository
- D. Use Repos to merge all differences and make a pull request back to the remote repository.
- E. Use Repos to create a new branch commit all changes and push changes to the remote Git repertory.
Answer: E
Explanation:
In Databricks Repos, when a user does not have privileges to make changes directly to the main branch of a cloned remote Git repository, the recommended approach is to create a new branch within the Databricks workspace. The developer can then make changes in this new branch, commit those changes, and push the new branch to the remote Git repository. This workflow allows for isolated development without affecting the main branch, enabling the developer to propose changes via a pull request from the new branch to the main branch in the remote repository. This method adheres to common Git collaboration workflows, fostering code review and collaboration while ensuring the integrity of the main branch.
NEW QUESTION # 234
The business reporting tem requires that data for their dashboards be updated every hour. The total processing time for the pipeline that extracts transforms and load the data for their pipeline runs in 10 minutes.
Assuming normal operating conditions, which configuration will meet their service-level agreement requirements with the lowest cost?
- A. Schedule a job to execute the pipeline once hour on a new job cluster.
- B. Schedule a Structured Streaming job with a trigger interval of 60 minutes.
- C. Schedule a jo to execute the pipeline once and hour on a dedicated interactive cluster.
- D. Configure a job that executes every time new data lands in a given directory.
Answer: A
Explanation:
Scheduling a job to execute the data processing pipeline once an hour on a new job cluster is the most cost-effective solution given the scenario. Job clusters are ephemeral in nature; they are spun up just before the job execution and terminated upon completion, which means you only incur costs for the time the cluster is active. Since the total processing time is only 10 minutes, a new job cluster created for each hourly execution minimizes the running time and thus the cost, while also fulfilling the requirement for hourly data updates for the business reporting team's dashboards.
NEW QUESTION # 235
A Delta Lake table representing metadata about content from user has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE Based on the above schema, which column is a good candidate for partitioning the Delta Table?
- A. Post_time
- B. Date
- C. User_id
- D. Post_id
- E. latitude
Answer: B
Explanation:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, the date column is a good candidate for partitioning for several reasons:
Time-Based Queries: If queries frequently filter or group by date, partitioning by the date column can significantly improve performance by limiting the amount of data scanned. Granularity: The date column likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
Data Skew: Other columns like post_id or user_id might lead to uneven partition sizes (data skew), which can negatively impact performance.
Partitioning by post_time could also be considered, but typically date is preferred due to its more manageable granularity.
NEW QUESTION # 236
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impressions led to monetizable clicks.
In the code below, Impressions is a streaming DataFrame with a watermark ("event_time", "10 minutes")
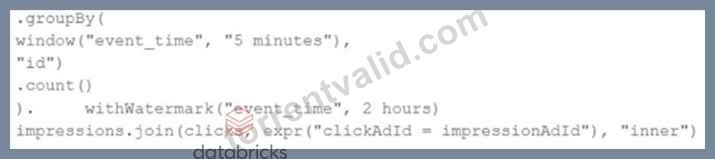
The data engineer notices the query slowing down significantly.
Which solution would improve the performance?
- A. Joining on event time constraint: clickTime == impressionTime using a leftOuter join
- B. Joining on event time constraint: clickTime >= impressionTime AND clickTime <= impressionTime interval 1 hour
- C. Joining on event time constraint: clickTime >= impressionTime - interval 3 hours and removing watermarks
- D. Joining on event time constraint: clickTime + 3 hours < impressionTime - 2 hours
Answer: B
NEW QUESTION # 237
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
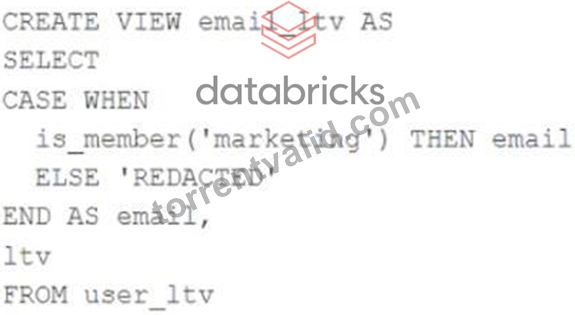
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. Three columns will be returned, but one column will be named "redacted" and contain only null values.
- B. The email, age. and ltv columns will be returned with the values in user ltv.
- C. Only the email and itv columns will be returned; the email column will contain all null values.
- D. Only the email and ltv columns will be returned; the email column will contain the string
"REDACTED" in each row. - E. The email and ltv columns will be returned with the values in user itv.
Answer: D
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
NEW QUESTION # 238
......
There are numerious Databricks-Certified-Data-Engineer-Professional exam dumps for the candidates to select for their preparation the exams, some candidates may get confused by so many choice. Our Databricks-Certified-Data-Engineer-Professional learning materials have free demo for the candidates, and they will have a general idea about the Databricks-Certified-Data-Engineer-Professional Learning Materials. You can obtain the Databricks-Certified-Data-Engineer-Professional learning materials for about ten minutes. The payment is also quite easy: online payment with credit card, and the private information of the you is also guaranteed.
Valid Dumps Databricks-Certified-Data-Engineer-Professional Book: https://www.torrentvalid.com/Databricks-Certified-Data-Engineer-Professional-valid-braindumps-torrent.html
- Free PDF Databricks - Perfect Reliable Databricks-Certified-Data-Engineer-Professional Exam Dumps ❓ Go to website ➡ www.prep4sures.top ️⬅️ open and search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 to download for free 😁Databricks-Certified-Data-Engineer-Professional Valid Exam Simulator
- Databricks-Certified-Data-Engineer-Professional Visual Cert Exam ☘ Test Databricks-Certified-Data-Engineer-Professional Passing Score 🥚 Databricks-Certified-Data-Engineer-Professional Valid Test Registration 🎬 Open ✔ www.pdfvce.com ️✔️ and search for “ Databricks-Certified-Data-Engineer-Professional ” to download exam materials for free 🐵Databricks-Certified-Data-Engineer-Professional Free Practice
- Databricks-Certified-Data-Engineer-Professional Study Demo 🧭 Databricks-Certified-Data-Engineer-Professional Dump 🛰 Databricks-Certified-Data-Engineer-Professional Dump 🤣 Search for { Databricks-Certified-Data-Engineer-Professional } and download it for free on ➠ www.examdiscuss.com 🠰 website 🐙Reliable Databricks-Certified-Data-Engineer-Professional Braindumps Sheet
- Databricks-Certified-Data-Engineer-Professional Training Pdf Material - Databricks-Certified-Data-Engineer-Professional Latest Study Material - Databricks-Certified-Data-Engineer-Professional Test Practice Vce 🔲 Open website ▶ www.pdfvce.com ◀ and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ for free download 🤹Exam Databricks-Certified-Data-Engineer-Professional Actual Tests
- Databricks-Certified-Data-Engineer-Professional Guide Torrent and Databricks-Certified-Data-Engineer-Professional Study Tool - Databricks-Certified-Data-Engineer-Professional Exam Torrent 🏡 Go to website ➤ www.prepawaypdf.com ⮘ open and search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 to download for free 🐤Databricks-Certified-Data-Engineer-Professional Exam Braindumps
- Free PDF Databricks-Certified-Data-Engineer-Professional - High Hit-Rate Reliable Databricks Certified Data Engineer Professional Exam Exam Dumps 😸 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ and download exam materials for free through ⇛ www.pdfvce.com ⇚ 🐁Learning Databricks-Certified-Data-Engineer-Professional Mode
- Pass Guaranteed Quiz Databricks - Databricks-Certified-Data-Engineer-Professional –Professional Reliable Exam Dumps 🦱 Open ⮆ www.prepawaypdf.com ⮄ and search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ to download exam materials for free 🍚Databricks-Certified-Data-Engineer-Professional Hot Questions
- Reliable Databricks-Certified-Data-Engineer-Professional Braindumps Sheet 🔏 Regualer Databricks-Certified-Data-Engineer-Professional Update 🏞 Regualer Databricks-Certified-Data-Engineer-Professional Update 🧥 Search for 《 Databricks-Certified-Data-Engineer-Professional 》 and download exam materials for free through ▷ www.pdfvce.com ◁ 🦏Exam Databricks-Certified-Data-Engineer-Professional Introduction
- Databricks-Certified-Data-Engineer-Professional Training Pdf Material - Databricks-Certified-Data-Engineer-Professional Latest Study Material - Databricks-Certified-Data-Engineer-Professional Test Practice Vce 🏭 Open ➡ www.vceengine.com ️⬅️ and search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 to download exam materials for free 😹Latest Databricks-Certified-Data-Engineer-Professional Test Report
- Databricks-Certified-Data-Engineer-Professional Training Pdf Material - Databricks-Certified-Data-Engineer-Professional Latest Study Material - Databricks-Certified-Data-Engineer-Professional Test Practice Vce 👽 ☀ www.pdfvce.com ️☀️ is best website to obtain ▶ Databricks-Certified-Data-Engineer-Professional ◀ for free download 🦱Latest Real Databricks-Certified-Data-Engineer-Professional Exam
- Test Databricks-Certified-Data-Engineer-Professional Passing Score 🏋 Latest Real Databricks-Certified-Data-Engineer-Professional Exam ⏬ Databricks-Certified-Data-Engineer-Professional Hot Questions 🛫 Search for 「 Databricks-Certified-Data-Engineer-Professional 」 and obtain a free download on ➡ www.prepawayete.com ️⬅️ 🦘Databricks-Certified-Data-Engineer-Professional Valid Exam Simulator
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, users.playground.ru, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, semasocial.com, Disposable vapes