Quiz Databricks - Databricks-Certified-Professional-Data-Engineer Useful Latest Test Fee

Our Databricks-Certified-Professional-Data-Engineer study material is the most popular examination question bank for candidates. Databricks-Certified-Professional-Data-Engineer study material has helped thousands of candidates successfully pass the exam and has been praised by all users since it was appearance. Databricks-Certified-Professional-Data-Engineer study material has the most authoritative test counseling platform, and each topic in Databricks-Certified-Professional-Data-Engineer Study Materials is carefully written by experts who are engaged in researching in the field of professional qualification exams all the year round. They have a very keen sense of change in the direction of the exam, so that they can accurately grasp the important points of the exam.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Processing with Spark | 25-30% | - Python and SQL for data engineering
- 1. Spark APIs in Python
- 2. Performance optimization techniques
- 3. Built-in and user-defined functions
- Spark DataFrames and Spark SQL
- 1. DataFrame operations and transformations
- 2. Window functions
- 3. Spark SQL queries and functions
|
| Topic 2: Data Ingestion | 15-20% | - Streaming ingestion
- 1. Structured streaming fundamentals
- 2. Kafka integration
- Batch ingestion methods
- 1. DBR autoloader
- 2. Spark APIs for ingestion
- 3. Integration with external systems
|
| Topic 3: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Task dependencies and orchestration
- 2. Jobs and job scheduling
- 3. Monitoring and alerting
|
| Topic 4: Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Optimize and Z-order
- 2. ACID transactions
- 3. Time travel and data versioning
- Delta Lake operations
- 1. Merge, update, delete operations
- 2. Schema evolution and enforcement
- 3. Delta Live Tables
|
| Topic 5: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Differences between data lake, data warehouse, and lakehouse
- 2. Bronze, silver, gold data layers
- 3. Data governance fundamentals
|
>> Latest Databricks-Certified-Professional-Data-Engineer Test Fee <<
Free PDF 2026 Valid Databricks Latest Databricks-Certified-Professional-Data-Engineer Test Fee
To meet the different and specific versions of consumers, and find the greatest solution to help you review, we made three versions for you. Three versions of Databricks Certified Professional Data Engineer Exam prepare torrents available on our test platform, including PDF version, PC version and APP online version. The trait of the software version is very practical. It can simulate real test environment, you can feel the atmosphere of the Databricks Certified Professional Data Engineer Exam exam in advance by the software version, and install the software version several times. PDF version of Databricks-Certified-Professional-Data-Engineer Exam torrents is convenient to read and remember, it also can be printed into papers so that you are able to write some notes or highlight the emphasis. PC version of our Databricks-Certified-Professional-Data-Engineer test braindumps only supports windows users and it is also one of our popular types to choose.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q75-Q80):
NEW QUESTION # 75
Which configuration parameter directly affects the size of a spark-partition upon ingestion of data into Spark?
- A. spark.sql.files.maxPartitionBytes
- B. spark.sql.autoBroadcastJoinThreshold
- C. spark.sql.adaptive.advisoryPartitionSizeInBytes
- D. spark.sql.adaptive.coalescePartitions.minPartitionNum
- E. spark.sql.files.openCostInBytes
Answer: A
Explanation:
Explanation
This is the correct answer because spark.sql.files.maxPartitionBytes is a configuration parameter that directly affects the size of a spark-partition upon ingestion of data into Spark. This parameter configures the maximum number of bytes to pack into a single partition when reading files from file-based sources such as Parquet, JSON and ORC. The default value is 128 MB, which means each partition will be roughly 128 MB in size, unless there are too many small files or only one large file. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Configuration" section; Databricks Documentation, under "Available Properties - spark.sql.files.maxPartitionBytes" section.
NEW QUESTION # 76
A nightly job ingests data into a Delta Lake table using the following code:
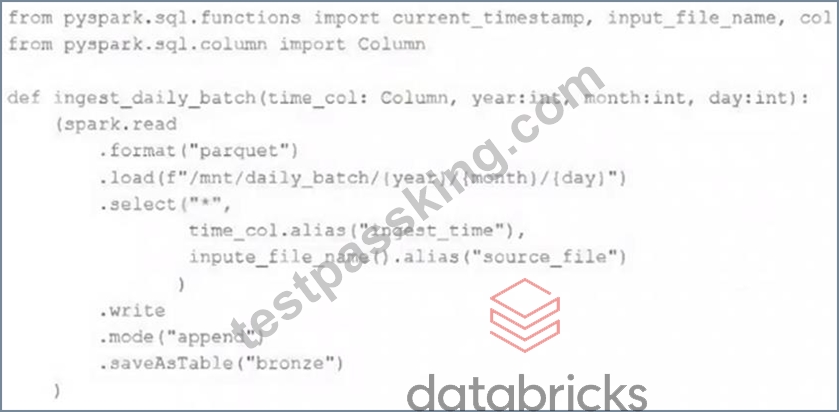
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
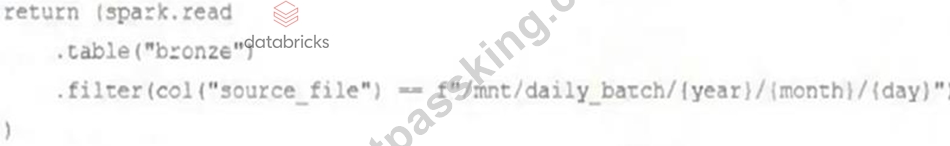
Which code snippet completes this function definition?
def new_records():
- A. return spark.readStream.load("bronze")
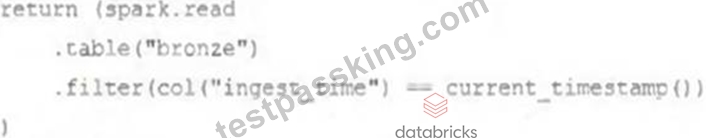
- B. return spark.read.option("readChangeFeed", "true").table ("bronze")
- C.
- D. return spark.readStream.table("bronze")
Answer: C
Explanation:
Explanation
This is the correct answer because it completes the function definition that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline. The object returned by this function is a DataFrame that contains all change events from a Delta Lake table that has enabled change data feed. The readChangeFeed option is set to true to indicate that the DataFrame should read changes from the table, and the table argument specifies the name of the table to read changes from. The DataFrame will have a schema that includes four columns: operation, partition, value, and timestamp. The operation column indicates the type of change event, such as insert, update, or delete. The partition column indicates the partition where the change event occurred. The value column contains the actual data of the change event as a struct type. The timestamp column indicates the time when the change event was committed. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Read changes in batch queries" section.
NEW QUESTION # 77
What is the main difference between the bronze layer and silver layer in a medallion architecture?
- A. Duplicates are removed in bronze, schema is applied in silver
- B. Bronze is raw copy of ingested data, silver contains data with production schema and optimized for ELT/ETL throughput
- C. Bad data is filtered in Bronze, silver is a copy of bronze data
- D. Silver may contain aggregated data
Answer: B
Explanation:
Explanation
Medallion Architecture - Databricks
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.
A diagram of a house Description automatically generated with low confidence

NEW QUESTION # 78
A data engineer wants to reflector the following DLT code, which includes multiple definition with very similar code:
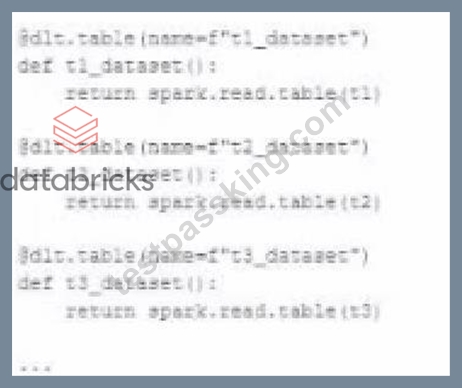
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
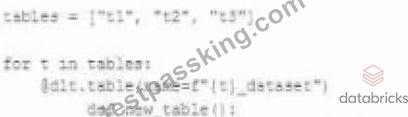
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for tables.
How can the data engineer fix this?
- A. Convert the list of configuration values to a dictionary of table settings, using different input the for loop.
- B. Wrap the loop inside another table definition, using generalized names and properties to replace with those from the inner table
- C. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- D. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
Answer: D
Explanation:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names. Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
NEW QUESTION # 79
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
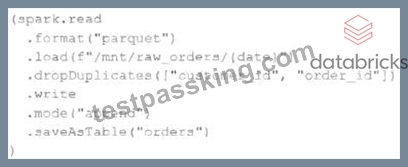
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- B. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
- C. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
- D. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- E. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
Answer: C
Explanation:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "DROP DUPLICATES" section.
NEW QUESTION # 80
......
The customer is God. Databricks-Certified-Professional-Data-Engineer learning dumps provide all customers with high quality after-sales service. After your payment is successful, we will dispatch a dedicated IT staff to provide online remote assistance for you to solve problems in the process of download and installation. During your studies, Databricks-Certified-Professional-Data-Engineer study tool will provide you with efficient 24-hour online services. You can email us anytime, anywhere to ask any questions you have about our Databricks-Certified-Professional-Data-Engineer Study Tool. At the same time, Databricks-Certified-Professional-Data-Engineer test question will also generate a report based on your practice performance to make you aware of the deficiencies in your learning process and help you develop a follow-up study plan so that you can use the limited energy where you need it most. So with Databricks-Certified-Professional-Data-Engineer study tool you can easily pass the exam.
Databricks-Certified-Professional-Data-Engineer Interactive Questions: https://www.testpassking.com/Databricks-Certified-Professional-Data-Engineer-exam-testking-pass.html
- New Databricks-Certified-Professional-Data-Engineer Test Dumps 🧣 Databricks-Certified-Professional-Data-Engineer Test Pdf 🚞 Databricks-Certified-Professional-Data-Engineer Reliable Test Cost 🎪 Open ▶ www.exam4labs.com ◀ and search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 to download exam materials for free 💅Databricks-Certified-Professional-Data-Engineer Reliable Test Cost
- Study Databricks-Certified-Professional-Data-Engineer Center 😮 Latest Databricks-Certified-Professional-Data-Engineer Test Questions 👇 Study Databricks-Certified-Professional-Data-Engineer Center 🥟 The page for free download of ➠ Databricks-Certified-Professional-Data-Engineer 🠰 on 「 www.pdfvce.com 」 will open immediately 🎎Study Databricks-Certified-Professional-Data-Engineer Center
- Pass Guaranteed Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam –High Pass-Rate Latest Test Fee 🦘 Search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ on ⏩ www.testkingpass.com ⏪ immediately to obtain a free download 🐬Databricks-Certified-Professional-Data-Engineer Online Bootcamps
- Exam Dumps Databricks-Certified-Professional-Data-Engineer Provider 🪂 Databricks-Certified-Professional-Data-Engineer Exam Vce Free 🍸 Latest Databricks-Certified-Professional-Data-Engineer Dumps ⚾ Easily obtain ( Databricks-Certified-Professional-Data-Engineer ) for free download through ▷ www.pdfvce.com ◁ 📃Real Databricks-Certified-Professional-Data-Engineer Dumps Free
- Useful Latest Databricks-Certified-Professional-Data-Engineer Test Fee, Databricks-Certified-Professional-Data-Engineer Interactive Questions 🛬 Copy URL ( www.vceengine.com ) open and search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ to download for free 😉Study Databricks-Certified-Professional-Data-Engineer Center
- Useful Latest Databricks-Certified-Professional-Data-Engineer Test Fee, Databricks-Certified-Professional-Data-Engineer Interactive Questions 🪒 Easily obtain free download of ➤ Databricks-Certified-Professional-Data-Engineer ⮘ by searching on ⮆ www.pdfvce.com ⮄ 📁Databricks-Certified-Professional-Data-Engineer Actual Tests
- Get a 30% Special Discount on Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps 🌌 Open website [ www.practicevce.com ] and search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ for free download 🐺Databricks-Certified-Professional-Data-Engineer Reliable Test Cost
- Valid Databricks Latest Databricks-Certified-Professional-Data-Engineer Test Fee - Databricks-Certified-Professional-Data-Engineer Free Download 🖐 Open website [ www.pdfvce.com ] and search for { Databricks-Certified-Professional-Data-Engineer } for free download 📞New Databricks-Certified-Professional-Data-Engineer Test Dumps
- Latest Databricks-Certified-Professional-Data-Engineer Exam Experience 🦅 Databricks-Certified-Professional-Data-Engineer New Test Materials 🐔 New Databricks-Certified-Professional-Data-Engineer Test Labs 🔗 Easily obtain free download of { Databricks-Certified-Professional-Data-Engineer } by searching on ✔ www.easy4engine.com ️✔️ 🏤Databricks-Certified-Professional-Data-Engineer Actual Tests
- Study Databricks-Certified-Professional-Data-Engineer Center 😅 Databricks-Certified-Professional-Data-Engineer New Test Materials 🙉 New Databricks-Certified-Professional-Data-Engineer Test Dumps ⬛ Easily obtain free download of ➥ Databricks-Certified-Professional-Data-Engineer 🡄 by searching on ✔ www.pdfvce.com ️✔️ 👺Databricks-Certified-Professional-Data-Engineer Questions Answers
- Get a 30% Special Discount on Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps 😵 Go to website ⏩ www.torrentvce.com ⏪ open and search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ to download for free 🔊Databricks-Certified-Professional-Data-Engineer Reliable Test Cram
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes