P.S. Free & New ARA-C01 dumps are available on Google Drive shared by PassTestking: https://drive.google.com/open?id=1JjevH0xpIGqjc3IT_K5R23ixEystWNzQ
We can produce the best ARA-C01 exam prep and can get so much praise in the international market. On the one hand, the software version can simulate the real examination for you and you can download our ARA-C01 study materials. On the other hand, you can finish practicing all the contents in our ARA-C01 practice materials within 20 to 30 hours. What's more, during the whole year after purchasing, you will get the latest version of our study materials for free. You can see it is clear that there are only benefits for you to buy our ARA-C01 learning guide, just have a try right!
| Section | Objectives |
|---|---|
| Topic 1: Data Sharing and Collaboration | - Secure data sharing
|
| Topic 2: Data Pipelines and Data Engineering | - Data ingestion and transformation
|
| Topic 3: Data Architecture and Design | - Data modeling and schema design
|
| Topic 4: Security, Governance, and Compliance | - Data governance
|
| Topic 5: Performance and Optimization | - Cost optimization
|
Our ARA-C01 practice torrent offers you more than 99% pass guarantee, which means that if you study our materials by heart and take our suggestion into consideration, you will absolutely get the certificate and achieve your goal. On the other hand, You can free download the demo of our ARA-C01 Study Guide before you buy our ARA-C01 exam questions. Meanwhile, if you want to keep studying this ARA-C01 study guide, you can enjoy the well-rounded services on ARA-C01 test prep.
NEW QUESTION # 162
What built-in Snowflake features make use of the change tracking metadata for a table? (Choose two.)
Answer: A,B
Explanation:
In Snowflake, the change tracking metadata for a table is utilized by the MERGE command and the STREAM object. The MERGE command uses change tracking to determine how to apply updates and inserts efficiently based on differences between source and target tables. STREAM objects, on the other hand, specifically capture and store change data, enabling incremental processing based on changes made to a table since the last stream offset was committed.References: Snowflake Documentation on MERGE and STREAM Objects.
NEW QUESTION # 163
Create a task and a stream following the below steps. So, when the
system$stream_has_data('rawstream1') condition returns false, what will happen to the task ?
-- Create a landing table to store raw JSON data.
-- Snowpipe could load data into this table. create or replace table raw (var variant);
-- Create a stream to capture inserts to the landing table.
-- A task will consume a set of columns from this stream. create or replace stream rawstream1 on table raw;
-- Create a second stream to capture inserts to the landing table.
-- A second task will consume another set of columns from this stream. create or replace stream rawstream2 on table raw;
-- Create a table that stores the names of office visitors identified in the raw data. create or replace table names (id int, first_name string, last_name string);
-- Create a table that stores the visitation dates of office visitors identified in the raw data.
create or replace table visits (id int, dt date);
-- Create a task that inserts new name records from the rawstream1 stream into the names table
-- every minute when the stream contains records.
-- Replace the 'etl_wh' warehouse with a warehouse that your role has USAGE privilege on. create or replace task raw_to_names
warehouse = etl_wh schedule = '1 minute' when
system$stream_has_data('rawstream1') as
merge into names n
using (select var:id id, var:fname fname, var:lname lname from rawstream1) r1 on n.id = to_number(r1.id)
when matched then update set n.first_name = r1.fname, n.last_name = r1.lname
when not matched then insert (id, first_name, last_name) values (r1.id, r1.fname, r1.lname)
;
-- Create another task that merges visitation records from the rawstream1 stream into the visits table
-- every minute when the stream contains records.
-- Records with new IDs are inserted into the visits table;
-- Records with IDs that exist in the visits table update the DT column in the table.
-- Replace the 'etl_wh' warehouse with a warehouse that your role has USAGE privilege on. create or replace task raw_to_visits
warehouse = etl_wh schedule = '1 minute' when
system$stream_has_data('rawstream2') as
merge into visits v
using (select var:id id, var:visit_dt visit_dt from rawstream2) r2 on v.id = to_number(r2.id) when matched then update set v.dt = r2.visit_dt
when not matched then insert (id, dt) values (r2.id, r2.visit_dt)
;
-- Resume both tasks.
alter task raw_to_names resume;
alter task raw_to_visits resume;
-- Insert a set of records into the landing table. insert into raw
select parse_json(column1) from values
('{"id": "123","fname": "Jane","lname": "Smith","visit_dt": "2019-09-17"}'),
('{"id": "456","fname": "Peter","lname": "Williams","visit_dt": "2019-09-17"}');
-- Query the change data capture record in the table streams select * from rawstream1;
select * from rawstream2;
Answer: C
NEW QUESTION # 164
What does a Snowflake Architect need to consider when implementing a Snowflake Connector for Kafka?
Answer: A
NEW QUESTION # 165
An Architect would like to save quarter-end financial results for the previous six years.
Which Snowflake feature can the Architect use to accomplish this?
Answer: A
Explanation:
Zero-copy cloning is a Snowflake feature that can be used to save quarter-end financial results for the previous six years. Zero-copy cloning allows creating a copy of a database, schema, table, or view without duplicating the data or metadata. The clone shares the same data files as the original object, but tracks any changes made to the clone or the original separately. Zero-copy cloning can be used to create snapshots of data at different points in time, such as quarter-end financial results, and preserve them for future analysis or comparison. Zero-copy cloning is fast, efficient, and does not consume any additional storage space unless the data is modified1.
References:
* Zero-Copy Cloning | Snowflake Documentation
NEW QUESTION # 166
An Architect runs the following SQL query: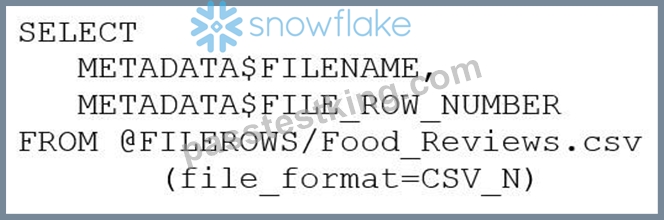
How can this query be interpreted?
Answer: D
Explanation:
A stage is a named location in Snowflake that can store files for data loading and unloading. A stage can be internal or external, depending on where the files are stored.
The query in the question uses the LIST function to list the files in a stage named FILEROWS. The function returns a table with various columns, including FILE_ROW_NUMBER, which is the line number of the file in the stage.
Therefore, the query can be interpreted as listing the files in a stage named FILEROWS and showing the line number of each file in the stage.
Reference:
1: Stages
2: LIST Function
NEW QUESTION # 167
......
PassTestking is aware of your busy routine; therefore, it has made the SnowPro Advanced Architect Certification ARA-C01 dumps format to facilitate you to prepare for the SnowPro Advanced Architect Certification ARA-C01 exam. We adhere strictly to the syllabus set by Snowflake ARA-C01 Certification Exam. What will make your ARA-C01 test preparation easy is its compatibility with all devices such as PCs, tablets, laptops, and androids.
ARA-C01 PDF: https://www.passtestking.com/Snowflake/ARA-C01-practice-exam-dumps.html
2026 Latest PassTestking ARA-C01 PDF Dumps and ARA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1JjevH0xpIGqjc3IT_K5R23ixEystWNzQ