BONUS!!! Download part of FreePdfDump DY0-001 dumps for free: https://drive.google.com/open?id=1_CoxffI0NkJ53mExd0z8G4QVjoutx6Ih
Of course, when we review a qualifying exam, we can't be closed-door. We should pay attention to the new policies and information related to the test DY0-001 certification. For the convenience of the users, the DY0-001 test materials will be updated on the homepage and timely update the information related to the qualification examination. Annual qualification examination, although content broadly may be the same, but as the policy of each year, the corresponding examination pattern grading standards and hot spots will be changed, as a result, the DY0-001 Test Prep can help users to spend the least time, you can know the test information directly what you care about on the learning platform that provided by us, let users save time and used their time in learning the new hot spot concerning about the knowledge content.
| Certification Vendor: | CompTIA |
|---|---|
| Exam Name: | CompTIA DataAI Certification Exam |
| Exam Number: | DY0-001 |
| Exam Price: | $544 USD |
| Certificate Validity Period: | 3 years |
| Exam Duration: | 165 minutes |
| Passing Score: | Pass/Fail (no numerical score) |
| Real Exam Qty: | Up to 90 |
| Exam Format: | Multiple Choice, Performance-Based Questions (PBQs) |
| Related Certifications: | CompTIA Data+ CompTIA AI Essentials |
| Available Languages: | Japanese, English |
| Recommended Training: | CompTIA Official Study Guide CompTIA CertMaster Learn for DataAI |
| Exam Registration: | Pearson VUE Scheduling CompTIA Official Registration |
| Sample Questions: | CompTIA DY0-001 Sample Questions |
| Exam Way: | Online proctored or in-person at Pearson VUE test centers |
| Pre Condition: | No mandatory prerequisites; recommended 5+ years of experience in data science, analytics, or related fields |
| Official Syllabus URL: | https://www.comptia.org/certifications/dataai |
We boost the professional and dedicated online customer service team. They are working for the whole day, weak and year to reply the clients' question about our DY0-001 study question and solve the clients' problem as quickly as possible. If the clients have any problem about the use of our DY0-001 Exam Practice materials and the refund issue they can contact our online customer service at any time, our online customer service personnel will reply them quickly. So you needn’t worry about you will encounter the great difficulties when you use our DY0-001 test pdf.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 61
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set: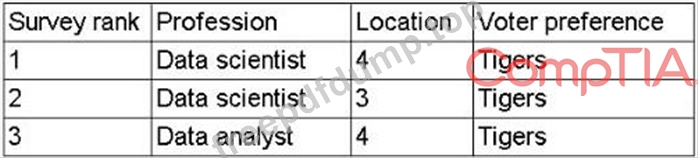
(Screenshot shows survey rankings for just two professions and a few locations, all voting for "Tigers") Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
Answer: D
Explanation:
# Extrapolated data refers to making predictions about data points that fall outside the observed range or distribution. Since the sample data (80%) is heavily skewed toward a small subset of professions and locations, predicting results for the remaining, unrepresented professions and regions involves extrapolation.
Why the other options are incorrect:
* A: Interpolation occurs within the bounds of observed data - not the issue here.
* C: In-sample data refers to training data, which is overrepresented in this case.
* D: Out-of-sample data is a concern in generalization but extrapolation is more specific here.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Extrapolation introduces risk when models are used outside the range of data they were trained on, especially if certain subgroups are underrepresented."
-
NEW QUESTION # 62
Given matrix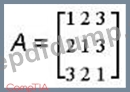
Which of the following is AT?


Answer: A
Explanation:
Transposing swaps rows and columns, so the (i, j) entry becomes the (j, i) entry.
NEW QUESTION # 63
A data scientist is building an inferential model with a single predictor variable. A scatter plot of the independent variable against the real-number dependent variable shows a strong relationship between them.
The predictor variable is normally distributed with very few outliers. Which of the following algorithms is the best fit for this model, given the data scientist wants the model to be easily interpreted?
Answer: D
Explanation:
The scenario provided describes a modeling problem with the following characteristics:
* A single continuous predictor variable (independent variable).
* A continuous real-number dependent variable.
* The relationship between the variables appears strong and linear, as observed from the scatter plot.
* The predictor variable is normally distributed with minimal outliers.
* The goal is to maintain interpretability in the model.
Based on the above, the most appropriate modeling technique is:
Linear Regression: This is a statistical method used to model the linear relationship between a continuous dependent variable and one or more independent variables. In simple linear regression, a straight line (y = mx
+ b) represents the relationship, where the slope and intercept can be easily interpreted. This method is preferred when the relationship is linear, the assumptions of normality and homoscedasticity are satisfied, and interpretability is required.
Why the other options are incorrect:
* A. Logistic Regression: This is used when the dependent variable is categorical (e.g., binary classification), not continuous. Therefore, not suitable for this case.
* B. Exponential Regression: Applied when the data shows an exponential growth or decay pattern, which is not implied here.
* D. Probit Regression: Similar to logistic regression but based on a normal cumulative distribution.
Used for categorical outcomes, not continuous variables.
Exact Extract and Official References:
* CompTIA DataX (DY0-001) Official Study Guide, Domain: Modeling, Analysis, and Outcomes:
"Linear regression is the most interpretable form of regression modeling. It assumes a linear relationship between independent and dependent variables and is ideal for inferential modeling when interpretability is important." (Section 3.1, Model Selection Criteria)
* Data Science Fundamentals, by CompTIA and DS Institute:
"Linear regression is a robust and interpretable statistical method used for modeling continuous outcomes. It provides coefficients which help in understanding the strength and direction of the relationship." (Chapter 4, Regression Techniques)
NEW QUESTION # 64
A data scientist wants to predict a person's travel destination. The options are:
* Branson, Missouri, United States
* Mount Kilimanjaro, Tanzania
* Disneyland Paris, Paris, France
* Sydney Opera House, Sydney, Australia
Which of the following models would best fit this use case?
Answer: A
Explanation:
# Linear Discriminant Analysis (LDA) is a supervised classification method used to predict a categorical target (such as travel destination) based on multiple input features. It models decision boundaries between classes - which is appropriate when predicting a fixed set of destinations.
Why the other options are incorrect:
* B: k-means is unsupervised and doesn't use labeled output like travel destination.
* C: Latent Semantic Analysis is used for extracting relationships from textual data - not categorical prediction.
* D: PCA reduces dimensionality but doesn't classify.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.1:"Linear Discriminant Analysis is used when the response variable is categorical and the objective is classification."
* Classification Techniques Guide, Chapter 7:"LDA excels in multi-class prediction when the input data is continuous and the output is a known category."
-
NEW QUESTION # 65
Which of the following problem-solving approaches is a set of guidelines to handle highly variable and not fully apparent situations?
Answer: A
Explanation:
Heuristics are rule-of-thumb strategies that guide problem solving in complex, uncertain situations where a fixed algorithm or plan isn't feasible.
NEW QUESTION # 66
......
Latest DY0-001 Training: https://www.freepdfdump.top/DY0-001-valid-torrent.html
BONUS!!! Download part of FreePdfDump DY0-001 dumps for free: https://drive.google.com/open?id=1_CoxffI0NkJ53mExd0z8G4QVjoutx6Ih