Certified-Data-Engineer-Professional VCE Dumps - Latest Certified-Data-Engineer-Professional Test Testking

BONUS!!! Download part of RealValidExam Certified-Data-Engineer-Professional dumps for free: https://drive.google.com/open?id=1eH5vYbAKB6fwJW4H252-YRsnujQu2JQE
Continuous improvement is a good thing. If you keep making progress and transcending yourself, you will harvest happiness and growth. The goal of our Certified-Data-Engineer-Professional latest exam guide is prompting you to challenge your limitations. People always complain that they do nothing perfectly. The fact is that they never insist on one thing and give up quickly. Our Certified-Data-Engineer-Professional Study Dumps will assist you to overcome your shortcomings and become a persistent person. Once you have made up your minds to change, come to purchase our Certified-Data-Engineer-Professional training practice.
| Section | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 5. Create pipeline components using control flow operators such as if/else and foreach
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 8. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Develop User-Defined Functions using Pandas/Python UDF
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
|
>> Certified-Data-Engineer-Professional VCE Dumps <<
Latest Certified-Data-Engineer-Professional Test Testking, New Certified-Data-Engineer-Professional Exam Experience
Our RealValidExam's Certified-Data-Engineer-Professional exam dumps and answers are researched by experienced IT team experts. These Certified-Data-Engineer-Professional test training materials are the most accurate in current market. You can download Certified-Data-Engineer-Professional free demo on RealValidExam.COM, it will be a good helper to help you pass Certified-Data-Engineer-Professional certification exam.
Databricks Certified Data Engineer Professional Sample Questions (Q187-Q192):
NEW QUESTION # 187
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
- B. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- C. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
- D. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
- E. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
Answer: C
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types.
NEW QUESTION # 188
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
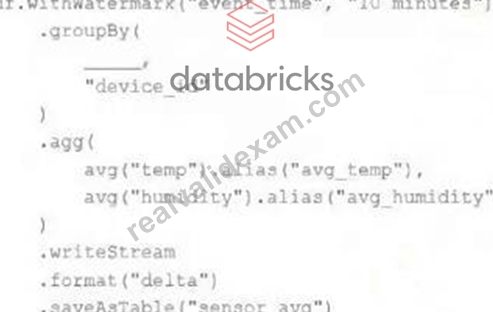
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. "event_time"
- B. window("event_time", "5 minutes").alias("time")
- C. window("event_time", "10 minutes").alias("time")
- D. lag("event_time", "10 minutes").alias("time")
- E. to_interval("event_time", "5 minutes").alias("time")
Answer: B
Explanation:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five- minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time".
NEW QUESTION # 189
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table:
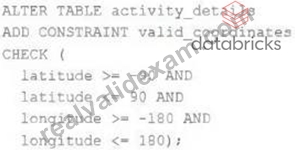
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
- A. The activity details table already contains records that violate the constraints; all existing data must pass CHECK constraints in order to add them to an existing table.
- B. Because another team uses this table to support a frequently running application, two-phase locking is preventing the operation from committing.
- C. The activity details table already contains records; CHECK constraints can only be added prior to inserting values into a table.
- D. The current table schema does not contain the field valid coordinates; schema evolution will need to be enabled before altering the table to add a constraint.
- E. The activity details table already exists; CHECK constraints can only be added during initial table creation.
Answer: A
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and
180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation.
NEW QUESTION # 190
What describes a primary technical challenge in ensuring consistent PII masking across all nodes in large-scale, distributed Databricks batch and streaming pipelines?
- A. PII masking is only required for direct identifiers.
- B. Masking functions must be standardized and managed through Unity Catalog, with enforcement applied across all relevant datasets to avoid any data inconsistency.
- C. Native masking in Databricks automatically synchronizes with all downstream external Databricks systems.
- D. Dynamic data masking is applied only at rest, so it does not affect query performance.
Answer: B
Explanation:
Consistent PII masking in distributed batch and streaming pipelines requires centrally defined and governed masking logic. Standardizing masking functions and enforcing them through Unity Catalog ensures that the same rules are applied uniformly across all datasets and execution paths, preventing inconsistencies across nodes and workloads.
NEW QUESTION # 191
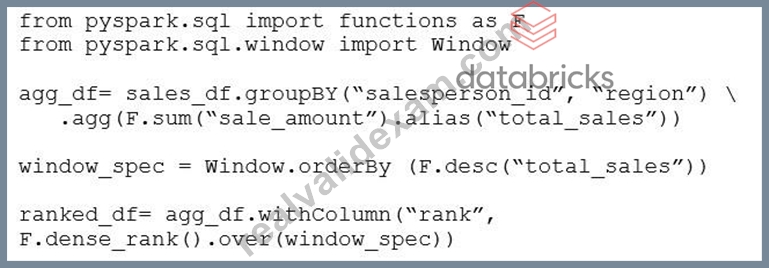
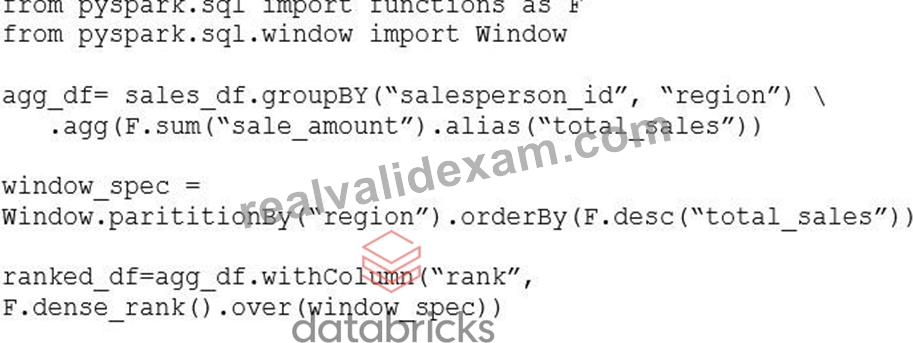
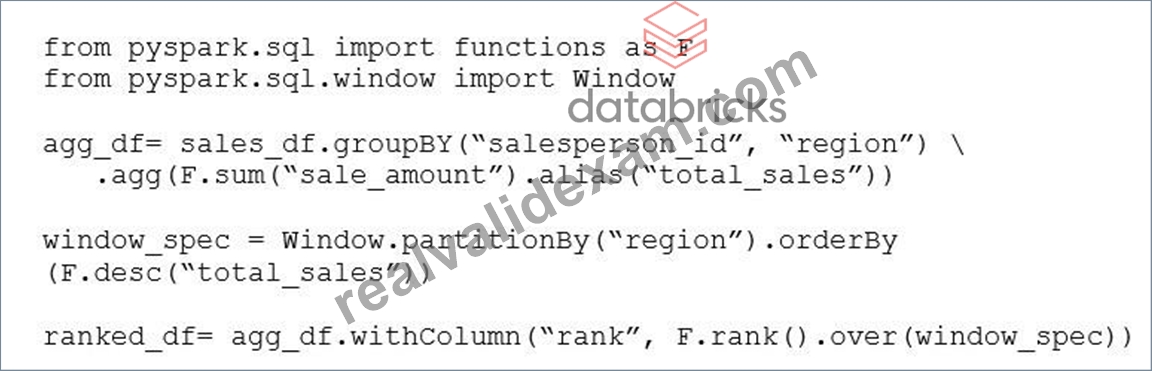
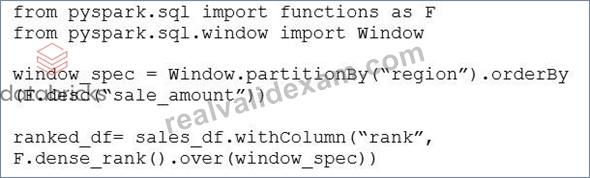
A data engineer is analyzing a large, partitioned retail dataset in Databricks, where each row represents a sale made by a salesperson. The dataset contains millions of records with the following schema:
sales_df: [salesperson_id: string, region: string, sale_amount: double, sale_date: date] The data engineer needs to generate a DataFrame that ranks salespeople within each region based on their total cumulative sales, with the highest seller ranked as 1. If multiple salespeople have the same total sales, they should share the same rank.
The data engineer wants to implement this logic using a PySpark window function and the dense_rank () function.
Which code snippet will perform this ranking?
Answer: B
Explanation:
This approach first aggregates sales by salesperson and region to compute total cumulative sales. It then applies a window function partitioned by region and ordered by total sales in descending order, using dense_rank to assign ranks so that salespeople with equal totals share the same rank and the highest total receives rank 1.
NEW QUESTION # 192
......
Different with other similar education platforms on the internet, the Databricks Certified Data Engineer Professional guide torrent has a high hit rate, in the past, according to data from the students' learning to use the Certified-Data-Engineer-Professional test torrent, 99% of these students can pass the qualification test and acquire the qualification of their yearning, this powerfully shows that the information provided by the Certified-Data-Engineer-Professional Study Tool suit every key points perfectly, targeted training students a series of patterns and problem solving related routines, and let students answer up to similar topic.
Latest Certified-Data-Engineer-Professional Test Testking: https://www.realvalidexam.com/Certified-Data-Engineer-Professional-real-exam-dumps.html
- Latest Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional VCE Dumps 😍 The page for free download of ▶ Certified-Data-Engineer-Professional ◀ on 【 www.pdfdumps.com 】 will open immediately 🦝Certified-Data-Engineer-Professional Practice Braindumps
- Certified-Data-Engineer-Professional Related Exams 🍪 Certified-Data-Engineer-Professional Exam Preparation 🐬 Certified-Data-Engineer-Professional Practice Braindumps 🖱 Copy URL ➠ www.pdfvce.com 🠰 open and search for [ Certified-Data-Engineer-Professional ] to download for free ⚡Reliable Certified-Data-Engineer-Professional Test Prep
- Certified-Data-Engineer-Professional Official Cert Guide 🐆 Certified-Data-Engineer-Professional Book Free 💬 Certified-Data-Engineer-Professional Reliable Exam Pass4sure ➕ Open ⏩ www.troytecdumps.com ⏪ enter ⏩ Certified-Data-Engineer-Professional ⏪ and obtain a free download 🌐Certified-Data-Engineer-Professional New Real Test
- Certified-Data-Engineer-Professional Actual Torrent: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Pass-King Materials - Certified-Data-Engineer-Professional Actual Exam 🕚 Open ▶ www.pdfvce.com ◀ and search for 【 Certified-Data-Engineer-Professional 】 to download exam materials for free 🅿Reliable Certified-Data-Engineer-Professional Test Prep
- Pass Guaranteed Quiz Authoritative Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional VCE Dumps 🍁 Search for 「 Certified-Data-Engineer-Professional 」 on { www.prepawayexam.com } immediately to obtain a free download ⌛New Certified-Data-Engineer-Professional Exam Notes
- Certified-Data-Engineer-Professional Practice Braindumps 🥍 Certified-Data-Engineer-Professional Reliable Exam Pass4sure ↗ Certified-Data-Engineer-Professional New Exam Bootcamp 🍇 Enter ⏩ www.pdfvce.com ⏪ and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🐎Certified-Data-Engineer-Professional Official Cert Guide
- Databricks Certified-Data-Engineer-Professional Dumps PDF Obtain Exam Results Simply 2026 🍺 Search on ▶ www.exam4labs.com ◀ for ( Certified-Data-Engineer-Professional ) to obtain exam materials for free download 📖Valid Certified-Data-Engineer-Professional Test Camp
- Reliable Certified-Data-Engineer-Professional Test Voucher ✉ Certified-Data-Engineer-Professional Pdf Free 🥧 Reliable Certified-Data-Engineer-Professional Test Voucher 👧 Copy URL ➤ www.pdfvce.com ⮘ open and search for ( Certified-Data-Engineer-Professional ) to download for free ⚖Certified-Data-Engineer-Professional New Exam Bootcamp
- Pass Guaranteed Quiz Authoritative Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional VCE Dumps 🍾 Search for [ Certified-Data-Engineer-Professional ] and easily obtain a free download on “ www.testkingpass.com ” 🍎Certified-Data-Engineer-Professional Exam Preparation
- Certified-Data-Engineer-Professional Actual Torrent: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Pass-King Materials - Certified-Data-Engineer-Professional Actual Exam 🚐 Search for 「 Certified-Data-Engineer-Professional 」 and download exam materials for free through ➡ www.pdfvce.com ️⬅️ 🚘Certified-Data-Engineer-Professional Test Registration
- Pass Guaranteed Quiz Authoritative Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional VCE Dumps 🌝 Immediately open ▛ www.exam4labs.com ▟ and search for “ Certified-Data-Engineer-Professional ” to obtain a free download 🎩Certified-Data-Engineer-Professional Exam Preparation
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.fundable.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
2026 Latest RealValidExam Certified-Data-Engineer-Professional PDF Dumps and Certified-Data-Engineer-Professional Exam Engine Free Share: https://drive.google.com/open?id=1eH5vYbAKB6fwJW4H252-YRsnujQu2JQE