Users can start using the product of UpdateDumps instantly after purchasing it, so they can start preparing for Microsoft certification test quickly. Three formats are being provided to customers so that they can access them in every possible way according to their needs. After discussing it with many Microsoft professionals and getting their positive feedback, the study material has been made. Many exam applicants have used the prep material and rated it the best because they have passed the Microsoft DP-750 Certification Exam in a single try.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
>> Valid DP-750 Test Online <<
These Microsoft DP-750 questions can be customized by the user according to their needs. This customization feature so that customers can adjust the time as they want. They can change the settings of the time and questions as per need while giving the Microsoft DP-750 tests. These Microsoft DP-750 exam questions train candidates to maintain discipline so that they can solve the real Microsoft DP-750 questions on time while giving their final DP-750 exam.
NEW QUESTION # 31
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
df.dropna(subset=['order_amount']) is the idiomatic PySpark way to remove rows where a specific column contains a null. It inspects only the columns listed in subset and drops any row where those columns are null.
The resulting DataFrame contains only rows where order_amount is not null - exactly what the requirement asks for.
The subset parameter is important: without it, dropna() would drop rows where ANY column is null, which could incorrectly exclude rows that have nulls in other columns but a valid order_amount. By specifying subset=['order_amount'], the filter is applied precisely and only to the column in question.
This method is semantically equivalent to df.filter(df.order_amount.isNotNull()) and to the SQL clause WHERE order_amount IS NOT NULL. Both are correct - dropna with a subset is arguably the more readable Pythonic approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 32
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.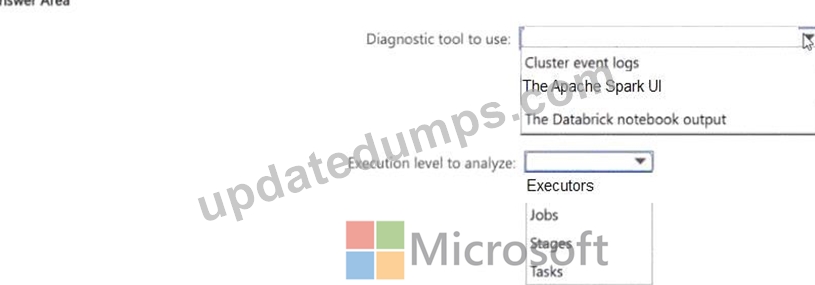
Answer:
Explanation: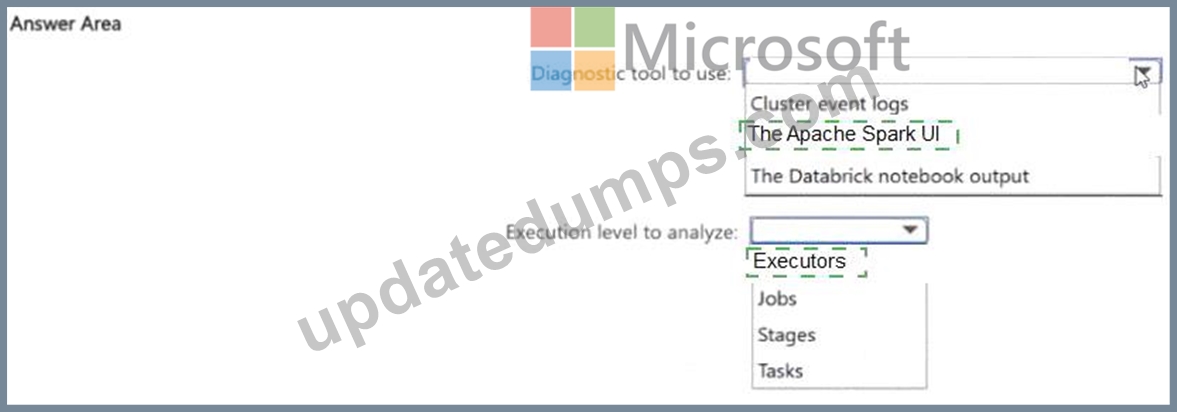
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it's accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it's processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that's data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 33
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.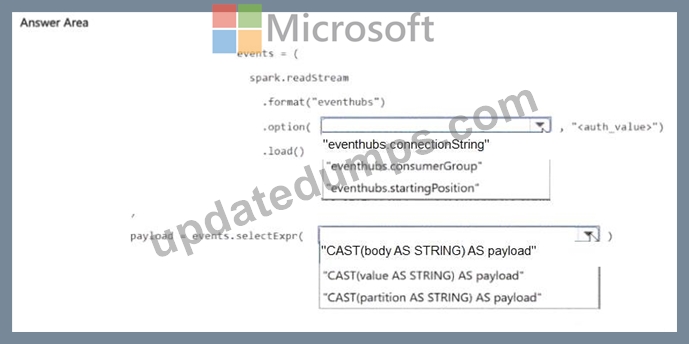
Answer:
Explanation: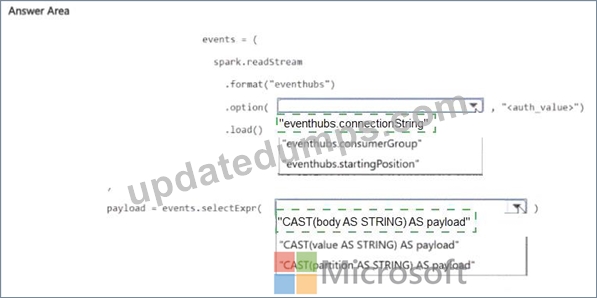
Explanation:
Reading from Azure Event Hubs in Spark Structured Streaming requires three things:
An EventHubsConf object built with the Event Hubs connection string (eventhubs.connectionString). This object is then converted to a map with .toMap before being passed to Spark.
spark.readStream.format('eventhubs').options(**ehConf).load() to create the streaming DataFrame. The
'eventhubs' format is provided by the azure-eventhubs-spark connector library.
A cast('string') on the body column to decode the binary payload. Event Hubs delivers messages with the raw event bytes in a column called body - without the cast, you get binary data rather than the readable JSON or text payload.
This is the standard, documented integration pattern for connecting Azure Databricks to Event Hubs with Structured Streaming, providing the checkpoint-based exactly-once semantics required by the Contoso telemetry pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/storage/events/eventhubs
NEW QUESTION # 34
You need to ingest real-time IoT data into Delta Lake with exactly-once guarantees. Which approach should you use?
Answer: A
Explanation:
Structured Streaming with checkpointing ensures fault tolerance and exactly-once processing semantics in Databricks. It tracks processed offsets and recovers from failures automatically.
Batch ingestion cannot guarantee real-time processing. Copy activity is not designed for streaming workloads and manual ingestion is not scalable or reliable.
NEW QUESTION # 35
You have an Azure Databricks workspace that is enabled for Unity Catalog You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
* New data must be available in near-real time (NRT).
* The data must be stored in managed Delta tables.
* The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: A
Explanation:
The correct answer is A - Auto Loader.
Auto Loader is exactly the right tool for this scenario: new CSV files land in ADLS Gen2, and they need to be ingested into managed Delta tables in near-real time with minimal custom code. Auto Loader uses file-system notifications or incremental directory listing to detect new arrivals, processes only the newly added files (skipping previously ingested ones), and writes results into Delta tables - all with schema inference and evolution support built in.
Option B (scheduled Spark batch jobs) adds latency tied to the schedule interval and requires custom 'what files have I already processed' tracking. Option C (external table referencing CSV files) exposes the raw files for querying but doesn't load data into managed Delta tables - it also can't provide NRT updates as files change. Option D (Azure Data Factory pipeline) introduces external orchestration overhead and is a heavier solution for something Auto Loader handles natively in a few lines of PySpark.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 36
......
As old saying goes, god will help those who help themselves. So you must keep inspiring yourself no matter what happens. At present, our DP-750 study materials are able to motivate you a lot. Our products will help you overcome your laziness. Also, you will have a pleasant learning of our DP-750 Study Materials. Boring learning is out of style. Our study materials will stimulate your learning interests. Then you will concentrate on learning our DP-750 study materials. Nothing can divert your attention.
DP-750 Free Download: https://www.updatedumps.com/Microsoft/DP-750-updated-exam-dumps.html