BTW, DOWNLOAD part of DumpsTests NCM-MCI dumps from Cloud Storage: https://drive.google.com/open?id=1ulJ4VlsikzXDaGACfIEvdw0ORdHsSHhw
There are three versions of NCM-MCI training materials for the candidate of you, and different versions have different advantages, you can use it in accordance with your own habit. Free update for each version for one year, namely, you don’t need to buy the same version for many times, and the update version will send to you automatically. You will get the latest version of NCM-MCI Training Materials.
| Section | Objectives |
|---|---|
| Topic 1: Nutanix Platform Architecture | - Cluster design and scalability - AHV hypervisor concepts and architecture - Prism management components |
| Topic 2: Networking and Security | - Virtual networking concepts (VPC, subnetting) - Traffic flow and network troubleshooting - Microsegmentation and security policies |
| Topic 3: Multicloud Infrastructure Operations | - Hybrid and multicloud deployment models - Workload mobility and migration - Infrastructure lifecycle management (LCM) |
| Topic 4: Storage and Data Services | - Replication and disaster recovery - Data protection and snapshots - Storage containers and data distribution |
| Topic 5: Performance and Troubleshooting | - Performance monitoring and optimization - Cluster health analysis - Issue diagnosis and remediation |
The Nutanix NCM-MCI practice questions come with three easy-to-use and install formats. The certification for the Nutanix NCM-MCI exam is a valuable, well-recognized professional credential. You can develop your skills and become a recognized specialist with the Nutanix Certified Master - Multicloud Infrastructure v6.10 NCM-MCI Certification in addition to learning about new technology requirements.
NEW QUESTION # 10
Task 12
An administrator needs to create a report named VMs_Power_State that lists the VMs in the cluster and their basic details including the power state for the last month.
No other entities should be included in the report.
The report should run monthly and should send an email to admin@syberdyne.net when it runs.
Generate an instance of the report named VMs_Power_State as a CSV and save the zip file as Desktop\Files\VMs_Power_state.zip Note: Make sure the report and zip file are named correctly. The SMTP server will not be configured.
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To create a report named VMs_Power_State that lists the VMs in the cluster and their basic details including the power state for the last month, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Report.
Enter VMs_Power_State as the report name and a description if required. Click Next.
Under the Custom Views section, select Data Table. Click Next.
Under the Entity Type option, select VM. Click Next.
Under the Custom Columns option, add the following variables: Name, Cluster Name, vCPUs, Memory, Power State. Click Next.
Under the Time Period option, select Last Month. Click Next.
Under the Report Settings option, select Monthly from the Schedule drop-down menu. Enter admin@syberdyne.net as the Email Recipient. Select CSV as the Report Output Format. Click Next.
Review the report details and click Finish.
To generate an instance of the report named VMs_Power_State as a CSV and save the zip file as Desktop\Files\VMs_Power_state.zip, you can follow these steps:
Log in to Prism Central and click on Operations on the left menu.
Select Reports from the drop-down menu and find the VMs_Power_State report from the list. Click on Run Now.
Wait for the report to be generated and click on Download Report. Save the file as Desktop\Files\VMs_Power_state.zip.
1. Open the Report section on Prism Central (Operations > Reports)
2. Click on the New Report button to start the creation of your custom report
3. Under the Custom Views section, select Data Table
4. Provide a title to your custom report, as well as a description if required.
5. Under the Entity Type option, select VM
6. This report can include all as well as a selection of the VMs
7. Click on the Custom Columns option and add the below variables:
a. Name - Name of the listed Virtual Machine
b. vCPUs - A combination of the vCores and vCPU's assigned to the Virtual Machine c. Memory - Amount of memory assigned to the Virtual Machine d. Disk Capacity - The total amount of assigned virtual disk capacity e. Disk Usage - The total used virtual disk capacity f. Snapshot Usage - The total amount of capacity used by snapshots (Excluding Protection Domain snapshots)
8. Under the Aggregation option for Memory and Disk Usage accept the default Average option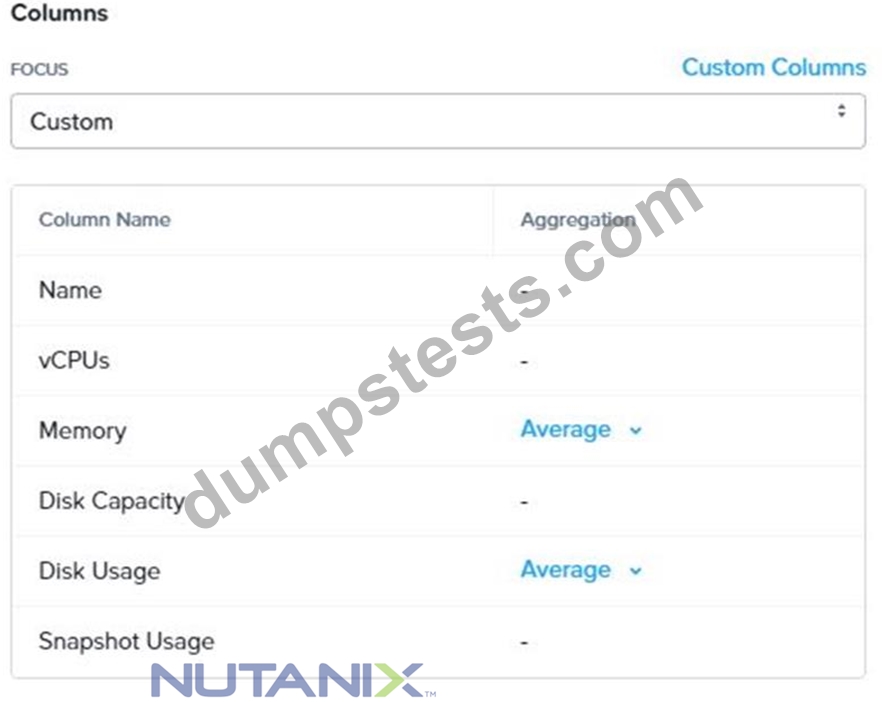
9. Click on the Add button to add this custom selection to your report
10. Next click on the Save and Run Now button on the bottom right of the screen
11. Provide the relevant details on this screen for your custom report: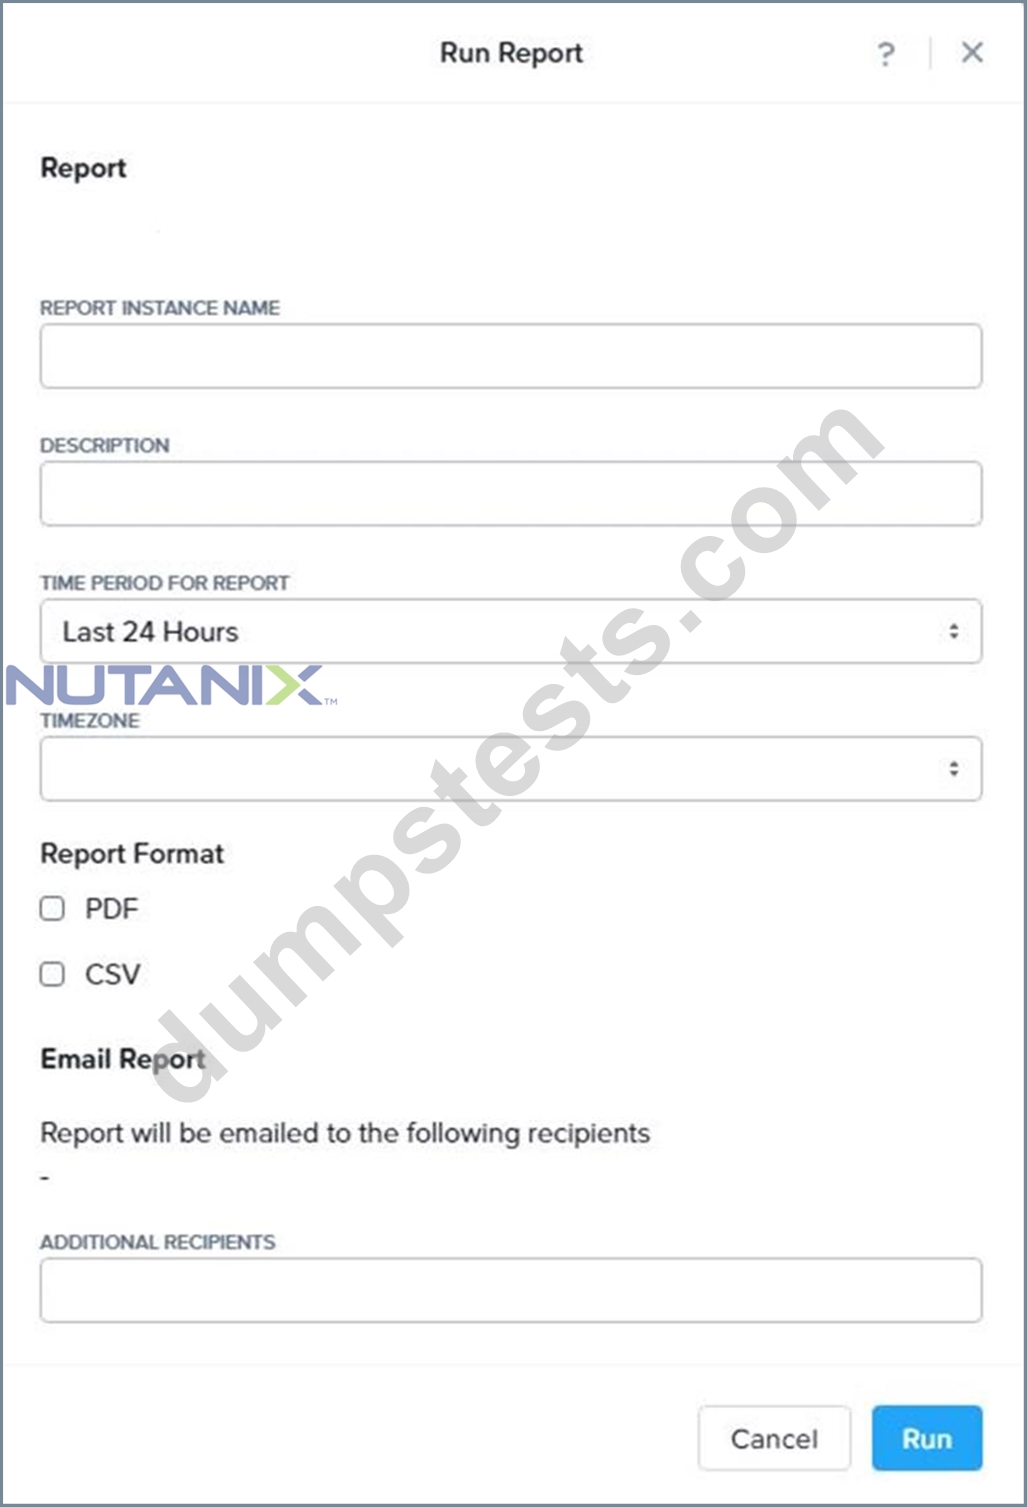
12. You can leave the Time Period For Report variable at the default of Last 24 Hours
13. Specify a report output of preference (PDF or CSV) and if required Additional Recipients for this report to be mailed to. The report can also simply be downloaded after this creation and initial run if required
14. Below is an example of this report in a CSV format:
NEW QUESTION # 11
Task 3
An administrator needs to assess performance gains provided by AHV Turbo at the guest level. To perform the test the administrator created a Windows 10 VM named Turbo with the following configuration.
1 vCPU
8 GB RAM
SATA Controller
40 GB vDisk
The stress test application is multi-threaded capable, but the performance is not as expected with AHV Turbo enabled. Configure the VM to better leverage AHV Turbo.
Note: Do not power on the VM. Configure or prepare the VM for configuration as best you can without powering it on.
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To configure the VM to better leverage AHV Turbo, you can follow these steps:
Log in to Prism Element of cluster A using the credentials provided.
Go to VM > Table and select the VM named Turbo.
Click on Update and go to Hardware tab.
Increase the number of vCPUs to match the number of multiqueues that you want to enable. For example, if you want to enable 8 multiqueues, set the vCPUs to 8. This will improve the performance of multi-threaded workloads by allowing them to use multiple processors.
Change the SCSI Controller type from SATA to VirtIO. This will enable the use of VirtIO drivers, which are required for AHV Turbo.
Click Save to apply the changes.
Power off the VM if it is running and mount the Nutanix VirtIO ISO image as a CD-ROM device. You can download the ISO image from Nutanix Portal.
Power on the VM and install the latest Nutanix VirtIO drivers for Windows 10. You can follow the instructions from Nutanix Support Portal.
After installing the drivers, power off the VM and unmount the Nutanix VirtIO ISO image.
Power on the VM and log in to Windows 10.
Open a command prompt as administrator and run the following command to enable multiqueue for the VirtIO NIC:
ethtool -L eth0 combined 8
Replace eth0 with the name of your network interface and 8 with the number of multiqueues that you want to enable. You can use ipconfig /all to find out your network interface name.
Restart the VM for the changes to take effect.
You have now configured the VM to better leverage AHV Turbo. You can run your stress test application again and observe the performance gains.
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA00e000000LKPdCAO change vCPU to 2/4 ?
Change SATA Controller to SCSI:
acli vm.get Turbo
Output Example:
Turbo {
config {
agent_vm: False
allow_live_migrate: True
boot {
boot_device_order: "kCdrom"
boot_device_order: "kDisk"
boot_device_order: "kNetwork"
uefi_boot: False
}
cpu_passthrough: False
disable_branding: False
disk_list {
addr {
bus: "ide"
index: 0
}
cdrom: True
device_uuid: "994b7840-dc7b-463e-a9bb-1950d7138671"
empty: True
}
disk_list {
addr {
bus: "sata"
index: 0
}
container_id: 4
container_uuid: "49b3e1a4-4201-4a3a-8abc-447c663a2a3e"
device_uuid: "622550e4-fb91-49dd-8fc7-9e90e89a7b0e"
naa_id: "naa.6506b8dcda1de6e9ce911de7d3a22111"
storage_vdisk_uuid: "7e98a626-4cb3-47df-a1e2-8627cf90eae6"
vmdisk_size: 10737418240
vmdisk_uuid: "17e0413b-9326-4572-942f-68101f2bc716"
}
flash_mode: False
hwclock_timezone: "UTC"
machine_type: "pc"
memory_mb: 2048
name: "Turbo"
nic_list {
connected: True
mac_addr: "50:6b:8d:b2:a5:e4"
network_name: "network"
network_type: "kNativeNetwork"
network_uuid: "86a0d7ca-acfd-48db-b15c-5d654ff39096"
type: "kNormalNic"
uuid: "b9e3e127-966c-43f3-b33c-13608154c8bf"
vlan_mode: "kAccess"
}
num_cores_per_vcpu: 2
num_threads_per_core: 1
num_vcpus: 2
num_vnuma_nodes: 0
vga_console: True
vm_type: "kGuestVM"
}
is_rf1_vm: False
logical_timestamp: 2
state: "Off"
uuid: "9670901f-8c5b-4586-a699-41f0c9ab26c3"
}
acli vm.disk_create Turbo clone_from_vmdisk=17e0413b-9326-4572-942f-68101f2bc716 bus=scsi remove the old disk acli vm.disk_delete 17e0413b-9326-4572-942f-68101f2bc716 disk_addr=sata.0
NEW QUESTION # 12
Task 8
Depending on the order you perform the exam items, the access information and credentials could change. Please refer to the other item performed on Cluster B if you have problems accessing the cluster.
The infosec team has requested that audit logs for API Requests and replication capabilities be enabled for all clusters for the top 4 severity levels and pushed to their syslog system using highest reliability possible. They have requested no other logs to be included.
Syslog configuration:
Syslog Name: Corp_syslog
Syslop IP: 34.69.43.123
Port: 514
Ensure the cluster is configured to meet these requirements.
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To configure the cluster to meet the requirements of the infosec team, you need to do the following steps:
Log in to Prism Central and go to Network > Syslog Servers > Configure Syslog Server. Enter Corp_syslog as the Server Name, 34.69.43.123 as the IP Address, and 514 as the Port. Select TCP as the Transport Protocol and enable RELP (Reliable Logging Protocol). This will create a syslog server with the highest reliability possible.
Click Edit against Data Sources and select Cluster B as the cluster. Select API Requests and Replication as the data sources and set the log level to CRITICAL for both of them. This will enable audit logs for API requests and replication capabilities for the top 4 severity levels (EMERGENCY, ALERT, CRITICAL, and ERROR) and push them to the syslog server. Click Save.
Repeat step 2 for any other clusters that you want to configure with the same requirements.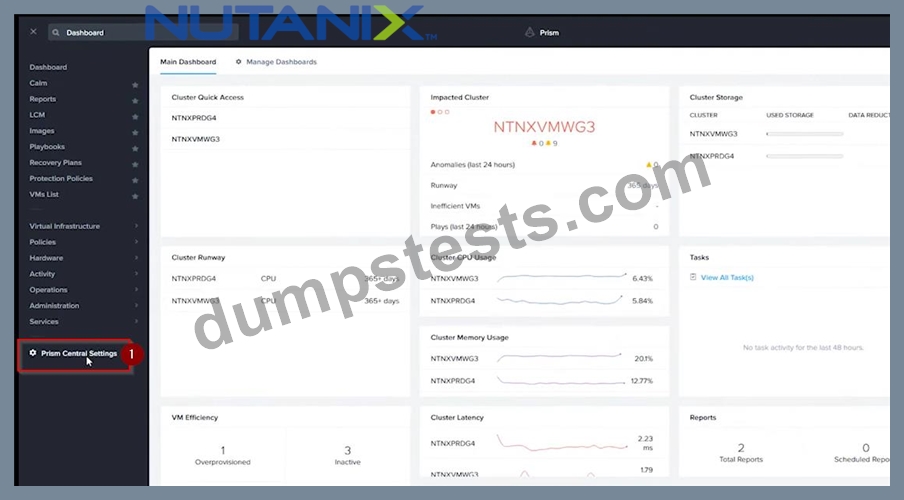
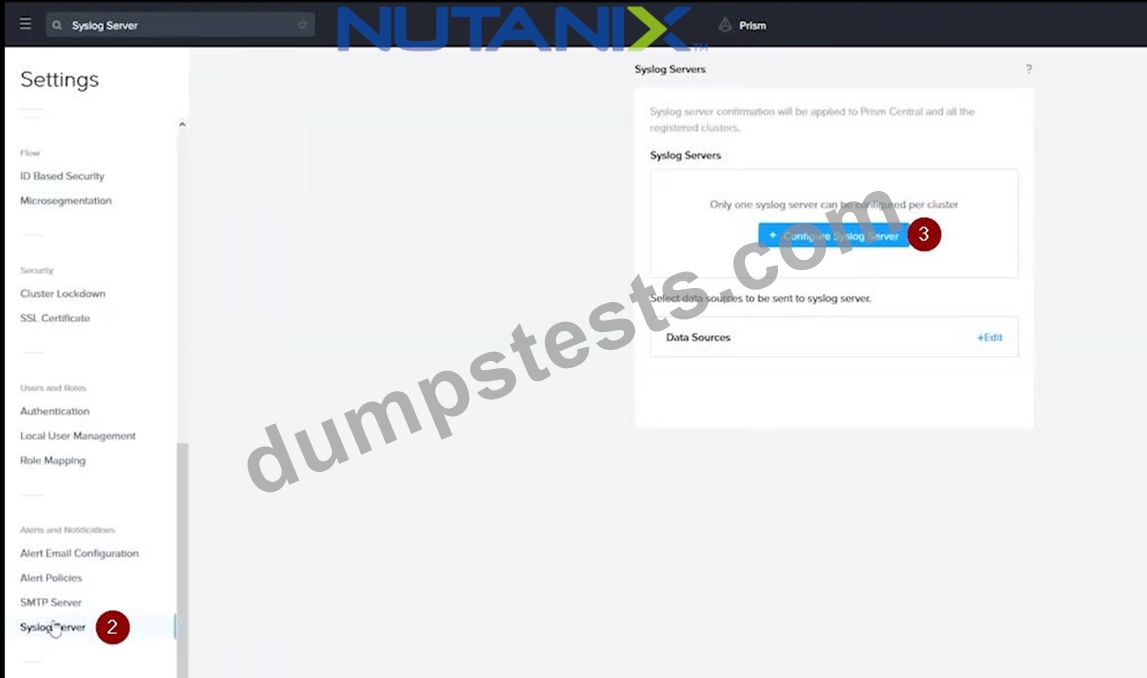
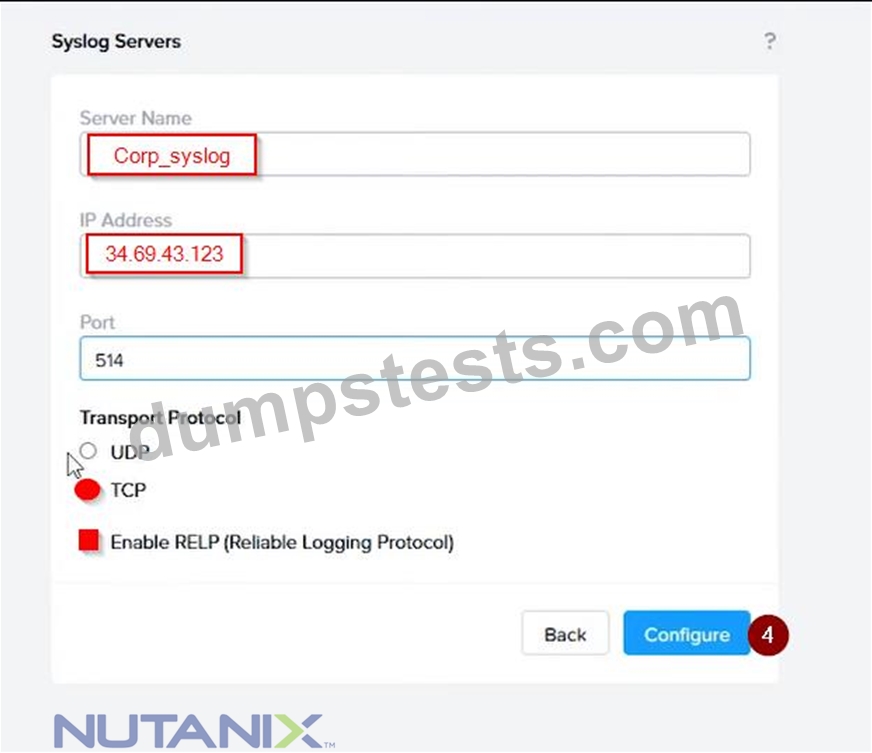
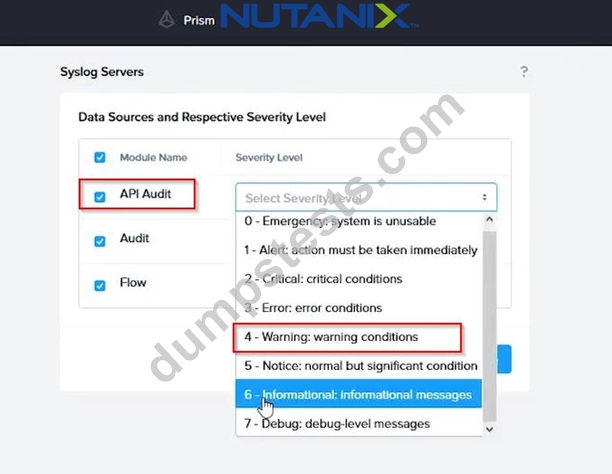
To configure the Nutanix clusters to enable audit logs for API Requests and replication capabilities, and push them to the syslog system with the highest reliability possible, you can follow these steps:
Log in to the Nutanix Prism web console using your administrator credentials.
Navigate to the "Settings" section or the configuration settings interface within Prism.
Locate the "Syslog Configuration" or "Logging" option and click on it.
Configure the syslog settings as follows:
Syslog Name: Enter "Corp_syslog" as the name for the syslog configuration.
Syslog IP: Set the IP address to "34.69.43.123", which is the IP address of the syslog system.
Port: Set the port to "514", which is the default port for syslog.
Enable the option for highest reliability or persistent logging, if available. This ensures that logs are sent reliably and not lost in case of network interruptions.
Save the syslog configuration.
Enable Audit Logs for API Requests:
In the Nutanix Prism web console, navigate to the "Cluster" section or the cluster management interface.
Select the desired cluster where you want to enable audit logs.
Locate the "Audit Configuration" or "Security Configuration" option and click on it.
Look for the settings related to audit logs and API requests. Enable the audit logging feature and select the top 4 severity levels to be logged.
Save the audit configuration.
Enable Audit Logs for Replication Capabilities:
In the Nutanix Prism web console, navigate to the "Cluster" section or the cluster management interface.
Select the desired cluster where you want to enable audit logs.
Locate the "Audit Configuration" or "Security Configuration" option and click on it.
Look for the settings related to audit logs and replication capabilities. Enable the audit logging feature and select the top 4 severity levels to be logged.
Save the audit configuration.
After completing these steps, the Nutanix clusters will be configured to enable audit logs for API Requests and replication capabilities. The logs will be sent to the specified syslog system with the highest reliability possible.
ncli
<ncli> rsyslog-config set-status enable=false
<ncli> rsyslog-config add-server name=Corp_Syslog ip-address=34.69.43.123 port=514 network-protocol=tdp relp-enabled=false
<ncli> rsyslog-config add-module server-name= Corp_Syslog module-name=APLOS level=INFO
<ncli> rsyslog-config add-module server-name= Corp_Syslog module-name=CEREBRO level=INFO
<ncli> rsyslog-config set-status enable=true
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA00e0000009CEECA2
NEW QUESTION # 13
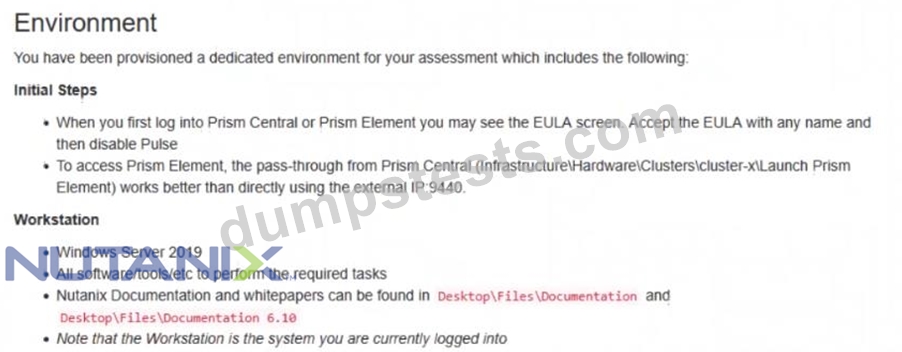
Refer to the exhibit.
Task1
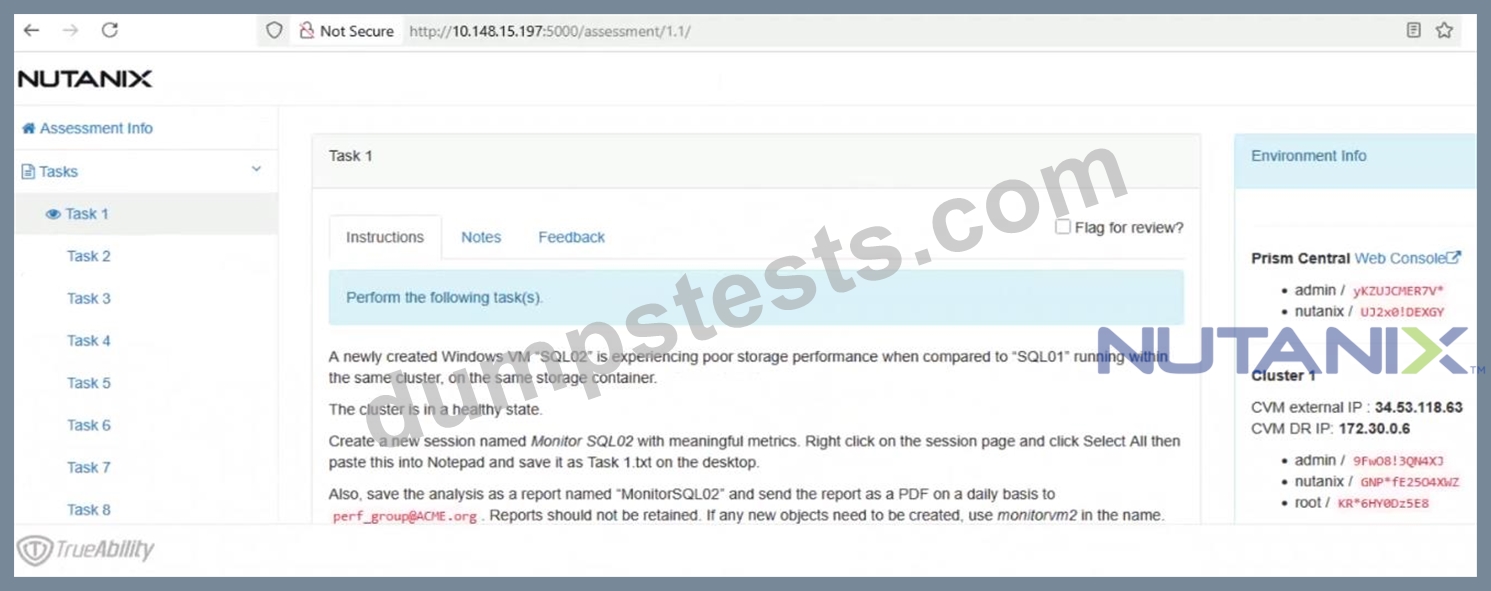
A newly created Windows VM "SQL02" is experiencing poor storage performance when compared to "SQL01" running within the same cluster, on the same storage container.
The cluster is in a healthy state.
Create a new session named Monitor SQL02 with meaningful metrics. Right click on the session page and click Select All then paste this into Notepad and save it as Task 1.txt on the desktop.
Also, save the analysis as a report named "MonitorSQL02" and send the report as a PDF on a daily basis to perf_group@ACME.org. Reports should not be retained. If any new objects need to be created, use monitorvm2 in the name.
Finally, correct the issue within "SQL02"
Notes:
Do not power on the VMs.
While you will be creating a session, you will need to examine the VM configurations to determine the issue.
Do not delete the VM to resolve the issue, any other destructive change is acceptable
Answer:
Explanation:
See the Explanation
Explanation:
This is a classic Nutanix performance troubleshooting scenario. The issue is almost certainly that the VM was created using the wrong Disk Bus Type (IDE or SATA instead of SCSI).
Here is the step-by-step solution to complete Task 1.
Part 1: Analysis and Reporting
Create the Session
Log in to Prism Central (or Prism Element, depending on the exam environment, but Analysis is usually a PC feature).
Navigate to Operations -> Analysis.
Click New Session.
Name: Monitor SQL02
Entity: Search for and select the VM named SQL02.
Metrics: Since the issue is storage performance, search for and add these specific metrics:
Hypervisor IOPS (or Controller IOPS)
Hypervisor IO Latency (or Controller IO Latency)
Hypervisor IO Bandwidth
Click Save.
Save Session Data (Task 1.txt)
Open the "Monitor SQL02" session you just created.
(Per instructions): Right-click anywhere on the chart/data area -> Click Select All.
Copy the selected text (Ctrl+C).
Open Notepad on the provided desktop.
Paste the data.
Save the file as Task 1.txt on the Desktop.
Create and Schedule the Report
While still in the Analysis session, click the Create Report (or "Add to Report") button.
Report Name: MonitorSQL02
Report Settings:
Format: PDF
Frequency: Daily
Email Recipient: perf_group@ACME.org
Retention: 0 (or "Do not retain", as requested).
Note: If the system forces you to create a new Report object and MonitorSQL02 is rejected, use monitorvm2 as the name per the instructions.
Save/Schedule the report.
Part 2: Diagnose and Fix the Issue
The Issue:
VM SQL02 was likely created with its data disks set to IDE or SATA.
Why this causes poor performance: IDE/SATA are emulated hardware with high CPU overhead and low queue depths (single-threaded).
The Standard: SQL01 (the healthy VM) is using SCSI, which is multithreaded and optimized for virtualization.
The Fix (Steps):
Navigate to the VM list in Prism.
Select SQL02 and click Update (or Edit).
Scroll down to the Disks section.
Identify the data disk(s). You will see the Bus Type listed as IDE or SATA.
Do not delete the VM. instead, perform a disk conversion (destructive change to the disk is allowed, but we want to keep the data).
Method to Convert (Clone to SCSI):
Hover over the IDE/SATA disk to see the path/filename of the vDisk (or write it down).
Click Add New Disk.
Operation: select Clone from ADSF file.
Path: Browse to the storage container and select the file associated with the current IDE disk.
Bus Type: Select SCSI (This is the critical fix).
Index: Ensure it doesn't conflict with existing disks (usually index 1 or higher for data).
Click Add.
Once the new SCSI disk is added, find the original IDE/SATA disk and click the X to remove it.
Click Save.
Note: You do not need to power on the VM to verify. The change from IDE to SCSI allows the VM to use the Nutanix VirtIO drivers for maximum storage performance.
NEW QUESTION # 14
Task 16
Running NCC on a cluster prior to an upgrade results in the following output FAIL: CVM System Partition /home usage at 93% (greater than threshold, 90%) Identify the CVM with the issue, remove the fil causing the storage bloat, and check the health again by running the individual disk usage health check only on the problematic CVM do not run NCC health check Note: Make sure only the individual health check is executed from the affected node
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To identify the CVM with the issue, remove the file causing the storage bloat, and check the health again, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and find the NCC health check output file from the list. You can use the date and time information to locate the file. The file name should be something like ncc-output-YYYY-MM-DD-HH-MM-SS.log.
Open the file and look for the line that says FAIL: CVM System Partition /home usage at 93% (greater than threshold, 90%). Note down the IP address of the CVM that has this issue. It should be something like X.X.X.X.
Log in to the CVM using SSH or console with the username and password provided.
Run the command du -sh /home/* to see the disk usage of each file and directory under /home. Identify the file that is taking up most of the space. It could be a log file, a backup file, or a temporary file. Make sure it is not a system file or a configuration file that is needed by the CVM.
Run the command rm -f /home/<filename> to remove the file causing the storage bloat. Replace <filename> with the actual name of the file.
Run the command ncc health_checks hardware_checks disk_checks disk_usage_check --cvm_list=X.X.X.X to check the health again by running the individual disk usage health check only on the problematic CVM. Replace X.X.X.X with the IP address of the CVM that you noted down earlier.
Verify that the output shows PASS: CVM System Partition /home usage at XX% (less than threshold, 90%). This means that the issue has been resolved.
#access to CVM IP by Putty
allssh df -h #look for the path /dev/sdb3 and select the IP of the CVM
ssh CVM_IP
ls
cd software_downloads
ls
cd nos
ls -l -h
rm files_name
df -h
ncc health_checks hardware_checks disk_checks disk_usage_check
NEW QUESTION # 15
......
DumpsTests is a reputable and highly regarded platform that provides comprehensive preparation resources for the Nutanix Certified Master - Multicloud Infrastructure v6.10 (NCM-MCI). For years, DumpsTests has been offering real, valid, and updated NCM-MCI Exam Questions, resulting in numerous successful candidates who now work for renowned global brands.
Valid Dumps NCM-MCI Files: https://www.dumpstests.com/NCM-MCI-latest-test-dumps.html
P.S. Free & New NCM-MCI dumps are available on Google Drive shared by DumpsTests: https://drive.google.com/open?id=1ulJ4VlsikzXDaGACfIEvdw0ORdHsSHhw