Dumps DY0-001 Collection | Trusted DY0-001 Exam Resource

P.S. Free 2026 CompTIA DY0-001 dumps are available on Google Drive shared by Pass4Test: https://drive.google.com/open?id=1xKxjEFEu8AEZY7olEYnove4heZ-b6nZ9
Our experts have the best experience of developing and compiling the content and the displays of the DY0-001 exam questions. Hence, they have created three different versions of the DY0-001 study guide for you to choose: the PDF,Software and APP online which offered by us to provide you practice at any time and condition. All these three versions of our DY0-001 Training Materials contain the best information you require to prapare and pass the exam. Don't hesitate, our DY0-001 practice engine won't let you down!
CompTIA DY0-001 Exam Overview:
>> Dumps DY0-001 Collection <<
Trusted DY0-001 Exam Resource, DY0-001 Actual Tests
The Pass4Test is a leading platform that has been helping the CompTIA DataAI Certification Exam (DY0-001) exam candidates in exam preparation and boosting their confidence to pass the final DY0-001 exam. The Pass4Test is offering real, valid, and updated CompTIA DataAI Certification Exam (DY0-001) practice questions. These CompTIA DataAI Certification Exam (DY0-001) exam questions are verified by CompTIA DY0-001 exam trainers.
| Topic | Details |
|---|
| Topic 1 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| Topic 2 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
| Topic 3 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
| Topic 4 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
| Topic 5 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
CompTIA DataAI Certification Exam Sample Questions (Q17-Q22):
NEW QUESTION # 17
Which of the following types of layers is used to downsample feature detection when using a convolutional neural network?
- A. Pooling
- B. Hidden
- C. Output
- D. Input
Answer: A
Explanation:
# Pooling layers are used in Convolutional Neural Networks (CNNs) to reduce the spatial dimensions (width and height) of the feature maps. This helps in downsampling, reducing computational complexity, and controlling overfitting by summarizing the features (e.g., max pooling or average pooling).
Why the other options are incorrect:
* B: Input layers receive raw data and do not perform downsampling.
* C: Output layers generate the final prediction.
* D: Hidden layers process data but do not specifically perform downsampling unless designed to do so (e.g., convolutional or pooling sublayers).
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.3:"Pooling layers are used to downsample feature maps and are critical in CNNs for reducing dimensions."
-
NEW QUESTION # 18
A data scientist receives an update on a business case about a machine that has thousands of error codes. The data scientist creates the following summary statistics profile while reviewing the logs for each machine:
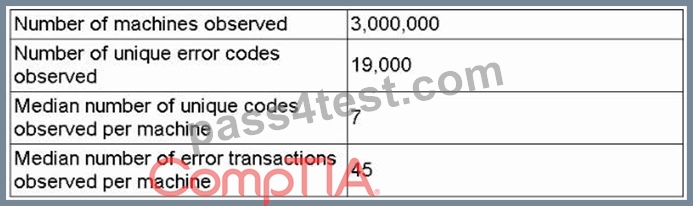
| Number of machines observed | 3,000,000
| Number of unique error codes observed | 19,000
| Median number of unique codes per machine | 7
| Median number of error transactions | 45
Which of the following is the most likely concern with respect to data design for model ingestion?
- A. Granularity misalignment
- B. Sparse matrix
- C. Multivariate outliers
- D. Insufficient features
Answer: B
Explanation:
# With 19,000 unique error codes and only 7 codes per machine (on median), the data structure will likely consist of a very large number of binary features (e.g., one-hot encoded error codes), most of which will be 0 for any given machine. This leads to a sparse matrix-where the majority of elements are zero-which poses computational and modeling challenges.
Why the other options are incorrect:
* B: Granularity misalignment would mean mismatched levels (e.g., mixing daily and hourly data), which is not the issue here.
* C: There are many features (error codes), not too few.
* D: Multivariate outliers involve unusual combinations across features, not sparsity.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.3:"High-cardinality categorical features can result in sparse matrices, especially when one-hot encoded for models."
NEW QUESTION # 19
A movie production company would like to find the actors appearing in its top movies using data from the tables below. The resulting data must show all movies in Table 1, enriched with actors listed in Table 2.
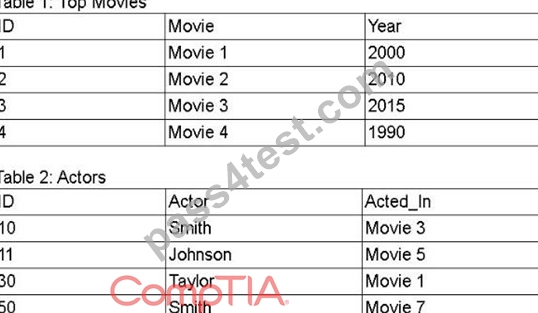
Which of the following query operations achieves the desired data set?
- A. Perform a LEFT JOIN on Table 1 using column Movie, with Table 2 using column Acted_In.
- B. Perform an INTERSECT between Table 1 using column Movie, and Table 2 using column Acted_In.
- C. Perform an INNER JOIN between Table 1 using column Movie, and Table 2 using column Acted_In.
- D. Perform a UNION between Table 1 using column Movie, and Table 2 using column Acted_In.
Answer: A
Explanation:
A LEFT JOIN returns every row from Table 1 (all top movies) and brings in matching actors from Table 2 where the Movie = Acted_In, leaving NULLs for movies without listed actors.
NEW QUESTION # 20
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set:
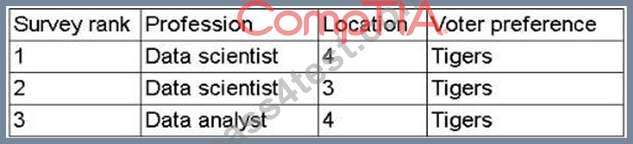
Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
- A. Extrapolated data
- B. Interpolated data
- C. Out-of-sample data
- D. In-sample data
Answer: C
Explanation:
The aggregated feedback covers only 80% of respondents, mostly from a few professions and locations, so the model hasn't "seen" the remaining 20% (and those underrepresented groups). Its performance on those unseen subsets (out-of-sample data) is therefore the primary concern for how well it will predict the actual vote.
NEW QUESTION # 21
A data analyst wants to find the latitude and longitude of a mailing address. Which of the following is the best method to use?
- A. Binning
- B. Geocoding
- C. One-hot encoding
- D. Imputing
Answer: B
Explanation:
# Geocoding is the process of converting addresses (like "1600 Amphitheatre Parkway, Mountain View, CA") into geographic coordinates (latitude and longitude), which is essential for spatial data analysis and mapping.
Why other options are incorrect:
* A: One-hot encoding is for converting categorical variables into binary vectors.
* B: Binning is for grouping continuous variables into categories.
* D: Imputing fills in missing data values, unrelated to geographic location retrieval.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 6.3:"Geocoding is a technique to convert textual location data into coordinate-based data for geographic analysis."
-
NEW QUESTION # 22
......
Trusted DY0-001 Exam Resource: https://www.pass4test.com/DY0-001.html
- Books DY0-001 PDF 🤶 DY0-001 PDF Guide 🦱 New DY0-001 Test Cram 🧃 Search on ➽ www.practicevce.com 🢪 for ⇛ DY0-001 ⇚ to obtain exam materials for free download 🆓DY0-001 Valid Dumps Files
- Valid DY0-001 Test Sims 🍭 Well DY0-001 Prep 🐤 DY0-001 Reliable Study Plan 🍤 Go to website { www.pdfvce.com } open and search for 【 DY0-001 】 to download for free 👗DY0-001 Reliable Exam Book
- Key DY0-001 Concepts 😟 DY0-001 Exam Demo 🧺 DY0-001 Study Reference 🐭 ▛ www.troytecdumps.com ▟ is best website to obtain “ DY0-001 ” for free download 🍫Reliable DY0-001 Test Materials
- DY0-001 New Guide Files ⬆ Reliable DY0-001 Test Materials 🔤 DY0-001 Latest Real Exam 🥯 Easily obtain free download of ⮆ DY0-001 ⮄ by searching on ▶ www.pdfvce.com ◀ 🥇DY0-001 New Guide Files
- Valid Dumps DY0-001 Collection Offers Candidates Latest-updated Actual CompTIA CompTIA DataAI Certification Exam Exam Products 🧓 Search for { DY0-001 } and obtain a free download on ➽ www.exam4labs.com 🢪 📀DY0-001 Latest Real Exam
- Solve All Your Exam Preparation Problems With CompTIA DY0-001 Exam Dumps 🍠 Go to website { www.pdfvce.com } open and search for ➥ DY0-001 🡄 to download for free 🐰DY0-001 Exam Demo
- Free PDF Latest DY0-001 - Dumps CompTIA DataAI Certification Exam Collection 🐵 Open website 《 www.pdfdumps.com 》 and search for 【 DY0-001 】 for free download 🛀DY0-001 New Test Materials
- Well DY0-001 Prep 🚨 Key DY0-001 Concepts 🔪 Books DY0-001 PDF 🍘 Easily obtain [ DY0-001 ] for free download through 《 www.pdfvce.com 》 🧩DY0-001 Valuable Feedback
- DY0-001 PDF Guide 🧯 Reliable DY0-001 Test Materials 🤶 DY0-001 Exam Demo 🔇 Search for 【 DY0-001 】 and easily obtain a free download on ▛ www.vceengine.com ▟ 👏DY0-001 New Guide Files
- Valid Dumps DY0-001 Collection Offers Candidates Latest-updated Actual CompTIA CompTIA DataAI Certification Exam Exam Products 🎲 Search for { DY0-001 } and easily obtain a free download on ➡ www.pdfvce.com ️⬅️ 🥜DY0-001 Exam Demo
- DY0-001 New Guide Files 🥗 DY0-001 Study Reference 🟦 DY0-001 Valid Dumps Files 🌰 Search for 《 DY0-001 》 and download exam materials for free through ( www.dumpsmaterials.com ) 🕴DY0-001 Reliable Study Plan
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.twosapp.com, www.stes.tyc.edu.tw, quay.io, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free & New DY0-001 dumps are available on Google Drive shared by Pass4Test: https://drive.google.com/open?id=1xKxjEFEu8AEZY7olEYnove4heZ-b6nZ9