The Certified-Data-Engineer-Professional vce braindumps of our TestsDumps contain questions and correct answers and detailed answer explanations and analysis, which apply to any level of candidates. Our IT experts has studied Databricks real exam for long time and created professional study guide. So you will pass the test with high rate If you practice the Certified-Data-Engineer-Professional Dumps latest seriously and skillfully.
| Section | Weight | Objectives |
|---|---|---|
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Implement scalable Python/SQL code and project structures |
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
>> Reliable Certified-Data-Engineer-Professional Test Testking <<
As we all know that, first-class quality always comes with the first-class service. There are also good-natured considerate after sales services offering help on our Certified-Data-Engineer-Professional study materials. All your questions about our Certified-Data-Engineer-Professional practice braindumps are deemed as prior tasks to handle. So if you have any question about our Certified-Data-Engineer-Professional Exam Quiz, just contact with us and we will help you immediately. That is why our Certified-Data-Engineer-Professional learning questions gain a majority of praise around the world.
NEW QUESTION # 240
A data engineer is configuring a Databricks Asset Bundle to deploy a job with granular permissions.
The requirements are:
- Grant the data-engineers group CAN_MANAGE access to the job.
- Ensure the auditors' group can view the job but not modify/run it.
- Avoid granting unintended permissions to other users/groups.
How should the data engineer deploy the job while meeting the requirements?
Answer: D
Explanation:
Databricks Asset Bundles (DABs) allow jobs, clusters, and permissions to be defined as code in YAML configuration files. According to the Databricks documentation on job permissions and bundle deployment, when defining permissions within a job resource, they must be scoped directly under that specific job's definition. This ensures that permissions are applied only to the intended job resource and not inadvertently propagated to other jobs or resources.
In this scenario, the data engineer must grant the data-engineers group CAN_MANAGE access, allowing them to configure, edit, and manage the job, while the auditors group should only have CAN_VIEW, giving them read-only access to see configurations and results without the ability to modify or execute. Importantly, no additional groups should be granted permissions, in order to follow the principle of least privilege.
Options A and B introduce unnecessary or unintended groups (like admin-team in A) or define permissions outside of the job scope (as in B). Option C improperly separates the permissions block outside the job resource, which is not aligned with Databricks bundle best practices.
Option D is the correct approach because it defines the job resource my-job with its name, tasks, clusters, and the exact intended permissions (CAN_MANAGE for data-engineers and CAN_VIEW for auditors). This aligns with Databricks' principle of least privilege and ensures compliance with governance standards in Unity Catalog-enabled workspaces.
NEW QUESTION # 241
A data engineering team is setting up a Git project to automate integration tests using Databricks Asset Bundles and the Git provider's CI/CD functionalities. When a pull containing changes to their pipleline is sent, they need to run a Job to test their data pipeline. What is the correct databricks bundle command sequence to be executed from the Git provider's CI/CD automation for this task?
Answer: A
Explanation:
The correct sequence is to first validate the bundle to ensure the configuration is correct, then deploy it to provision or update the defined resources, and finally run the job to execute the integration tests. This aligns with CI/CD best practices by catching configuration issues early and only running tests after a successful deployment.
NEW QUESTION # 242
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed: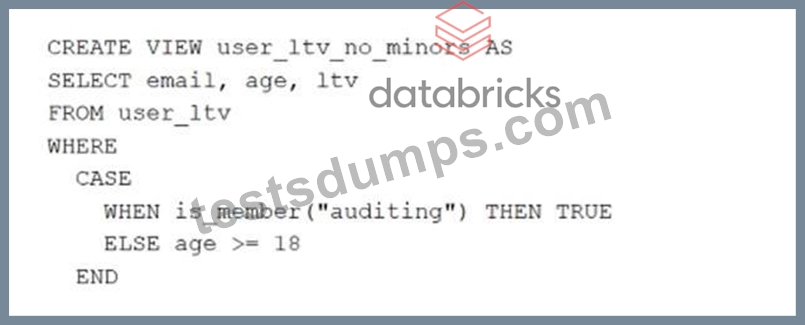
An analyst who is not a member of the auditing group executes the following query:
SELECT * FROM user_ltv_no_minors
Which statement describes the results returned by this query?
Answer: E
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 243
A Structured Streaming job deployed to production has been experiencing delays during peak hours of the day. At present, during normal execution, each microbatch of data is processed in less than 3 seconds. During peak hours of the day, execution time for each microbatch becomes very inconsistent, sometimes exceeding 30 seconds. The streaming write is currently configured with a trigger interval of 10 seconds.
Holding all other variables constant and assuming records need to be processed in less than 10 seconds, which adjustment will meet the requirement?
Answer: A
Explanation:
The adjustment that will meet the requirement of processing records in less than 10 seconds is to decrease the trigger interval to 5 seconds. This is because triggering batches more frequently may prevent records from backing up and large batches from causing spill. Spill is a phenomenon where the data in memory exceeds the available capacity and has to be written to disk, which can slow down the processing and increase the execution time. By reducing the trigger interval, the streaming query can process smaller batches of data more quickly and avoid spill. This can also improve the latency and throughput of the streaming job.
NEW QUESTION # 244
A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor.
When evaluating the Ganglia Metrics for this cluster, which indicator would signal a bottleneck caused by code executing on the driver?
Answer: D
Explanation:
This is the correct answer because it indicates a bottleneck caused by code executing on the driver. A bottleneck is a situation where the performance or capacity of a system is limited by a single component or resource. A bottleneck can cause slow execution, high latency, or low throughput. A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor. When evaluating the Ganglia Metrics for this cluster, one can look for indicators that show how the cluster resources are being utilized, such as CPU, memory, disk, or network. If the overall cluster CPU utilization is around 25%, it means that only one out of the four nodes (driver + 3 executors) is using its full CPU capacity, while the other three nodes are idle or underutilized. This suggests that the code executing on the driver is taking too long or consuming too much CPU resources, preventing the executors from receiving tasks or data to process. This can happen when the code has driver-side operations that are not parallelized or distributed, such as collecting large amounts of data to the driver, performing complex calculations on the driver, or using non-Spark libraries on the driver.
NEW QUESTION # 245
......
Now on the Internet, a lot of online learning platform management is not standard, some web information may include some viruses, cause far-reaching influence to pay end users and adverse effect. If you purchase our Certified-Data-Engineer-Professional test torrent this issue is impossible. We hire experienced staff to handle this issue perfectly. We are sure that our products and payment process are surely safe and anti-virus. If you have any question about downloading and using our Certified-Data-Engineer-Professional Study Tool, we have professional staff to remotely handle for you immediately, let users to use the Databricks Certified Data Engineer Professional guide torrent in a safe environment, bring more comfortable experience for the user.
Reliable Certified-Data-Engineer-Professional Braindumps Ebook: https://www.testsdumps.com/Certified-Data-Engineer-Professional_real-exam-dumps.html