無料でクラウドストレージから最新のCertShiken ACD-301 PDFダンプをダウンロードする:https://drive.google.com/open?id=1D48FpkJ7T44rBBsjzN6VwX5Je3qLEN0O
ACD-301試験問題はグローバルなものであるとAppian誇らしく言えます。 したがって、どんな種類のACD-301テストトレントを求めても、当社のアフターサービスサービススタッフは、最も専門的な方法でACD-301練習問題の問題を解決するお手伝いをします。 ACD-301のAppian Certified Lead Developer学習ツールを目指しているお客様は世界中のさまざまな国から来ており、間違いなく時間差があるため、ACD-301トレーニングガイドで1日24時間、7日間、思いやりのあるCertShikenオンラインアフターサービスを提供します 週に数日、いつでもどこでも気軽にご連絡ください。
| Section | Objectives |
|---|---|
| Topic 1: Platform Management | - Implement administration console settings - Schedule, execute, and troubleshoot application deployments across environments - Describe basic platform enterprise architecture and how it's used - Troubleshoot and resolve issues at the environment level, involving Appian Support when necessary |
| Topic 2: Proactively Design for Scalability and Performance | - Build and maintain scalable applications - Monitor and troubleshoot issues at the application level - Design and implement performant Appian components - Plan and evaluate load testing |
| Topic 3: Extending Appian | - Program advanced APIs that allow Appian to communicate with external systems - Evaluate and implement authentication using connected systems - Design and troubleshoot advanced integrations - Evaluate existing plug-ins and recognize when to develop custom plug-ins - Evaluate advanced document generation options |
| Topic 4: Project and Resource Management | - Recommend the protocols and procedures involved in Appian governance - Manage and lead essential activities across an Agile team - Interpret client requirements and recommend technical design options |
| Topic 5: Application Design and Development | - Evaluate how Appian can meet user requirements - Evaluate and design applications for consistency and reusability - Implement best practices for multiple application development - Design applications leveraging Appian functionality |
| Topic 6: Data Management | - Determine the best way to leverage data fabric, data types, and data migration - Implement advanced database features - Plan, execute, and troubleshoot data migrations - Analyze, evaluate, and troubleshoot high-volume database structures - Diagnose and troubleshoot data fabric complexities - Analyze and design secure data models |
IT技術の急速な発展につれて、IT認証試験の問題は常に変更されています。したがって、CertShikenのACD-301問題集も絶えずに更新されています。それに、CertShikenの教材を購入すれば、CertShikenは一年間の無料アップデート・サービスを提供してあげます。問題が更新される限り、CertShikenは直ちに最新版のACD-301資料を送ってあげます。そうすると、あなたがいつでも最新バージョンの資料を持っていることが保証されます。CertShikenはあなたが試験に合格するのを助けることができるだけでなく、あなたは最新の知識を学ぶのを助けることもできます。このような素晴らしい資料をぜひ見逃さないでください。
質問 # 26
Users must be able to navigate throughout the application while maintaining complete visibility in the application structure and easily navigate to previous locations. Which Appian Interface Pattern would you recommend?
正解:D
解説:
Comprehensive and Detailed In-Depth Explanation:
The requirement emphasizes navigation with complete visibility of the application structure and the ability to return to previous locations easily. The Breadcrumbs pattern is specifically designed to meet this need. According to Appian's design best practices, the Breadcrumbs pattern provides a visual trail of the user's navigation path, showing the hierarchy of pages or sections within the application. This allows users to understand their current location relative to the overall structure and quickly navigate back to previous levels by clicking on the breadcrumb links.
Option A (Billboards as Cards): This pattern is useful for presenting high-level options or choices on a homepage in a visually appealing way. However, it does not address navigation visibility or the ability to return to previous locations, making it irrelevant to the requirement.
Option B (Activity History): This pattern tracks and displays a log of activities or actions within the application, typically for auditing or monitoring purposes. It does not enhance navigation or provide visibility into the application structure.
Option C (Drilldown Report): This pattern allows users to explore detailed data within reports by drilling into specific records. While it supports navigation within data, it is not designed for general application navigation or maintaining structural visibility.
Option D (Breadcrumbs): This is the correct choice as it directly aligns with the requirement. Per Appian's Interface Patterns documentation, Breadcrumbs improve usability by showing a hierarchical path (e.g., Home > Section > Subsection) and enabling backtracking, fulfilling both visibility and navigation needs.
質問 # 27
You are designing a process that is anticipated to be executed multiple times a day. This process retrieves data from an external system and then calls various utility processes as needed. The main process will not use the results of the utility processes, and there are no user forms anywhere.
Which design choice should be used to start the utility processes and minimize the load on the execution engines?
正解:D
解説:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, designing a process that executes frequently (multiple times a day) and calls utility processes without using their results requires optimizing performance and minimizing load on Appian's execution engines. The absence of user forms indicates a backend process, so user experience isn't a concern-only engine efficiency matters. Let's evaluate each option:
A . Use the Start Process Smart Service to start the utility processes:
The Start Process Smart Service launches a new process instance independently, creating a separate process in the Work Queue. While functional, it increases engine load because each utility process runs as a distinct instance, consuming engine resources and potentially clogging the Java Work Queue, especially with frequent executions. Appian's performance guidelines discourage unnecessary separate process instances for utility tasks, favoring integrated subprocesses, making this less optimal.
B . Start the utility processes via a subprocess synchronously:
Synchronous subprocesses (e.g., a!startProcess with isAsync: false) execute within the main process flow, blocking until completion. For utility processes not used by the main process, this creates unnecessary delays, increasing execution time and engine load. With frequent daily executions, synchronous subprocesses could strain engines, especially if utility processes are slow or numerous. Appian's documentation recommends asynchronous execution for non-dependent, non-blocking tasks, ruling this out.
C . Use Process Messaging to start the utility process:
Process Messaging (e.g., sendMessage() in Appian) is used for inter-process communication, not for starting processes. It's designed to pass data between running processes, not initiate new ones. Attempting to use it for starting utility processes would require additional setup (e.g., a listening process) and isn't a standard or efficient method. Appian's messaging features are for coordination, not process initiation, making this inappropriate.
D . Start the utility processes via a subprocess asynchronously:
This is the best choice. Asynchronous subprocesses (e.g., a!startProcess with isAsync: true) execute independently of the main process, offloading work to the engine without blocking or delaying the parent process. Since the main process doesn't use the utility process results and there are no user forms, asynchronous execution minimizes engine load by distributing tasks across time, reducing Work Queue pressure during frequent executions. Appian's performance best practices recommend asynchronous subprocesses for non-dependent, utility tasks to optimize engine utilization, making this ideal for minimizing load.
Conclusion: Starting the utility processes via a subprocess asynchronously (D) minimizes engine load by allowing independent execution without blocking the main process, aligning with Appian's performance optimization strategies for frequent, backend processes.
Appian Documentation: "Process Model Performance" (Synchronous vs. Asynchronous Subprocesses).
Appian Lead Developer Certification: Process Design Module (Optimizing Engine Load).
Appian Best Practices: "Designing Efficient Utility Processes" (Asynchronous Execution).
質問 # 28
For each requirement, match the most appropriate approach to creating or utilizing plug-ins Each approach will be used once.
Note: To change your responses, you may deselect your response by clicking the blank space at the top of the selection list.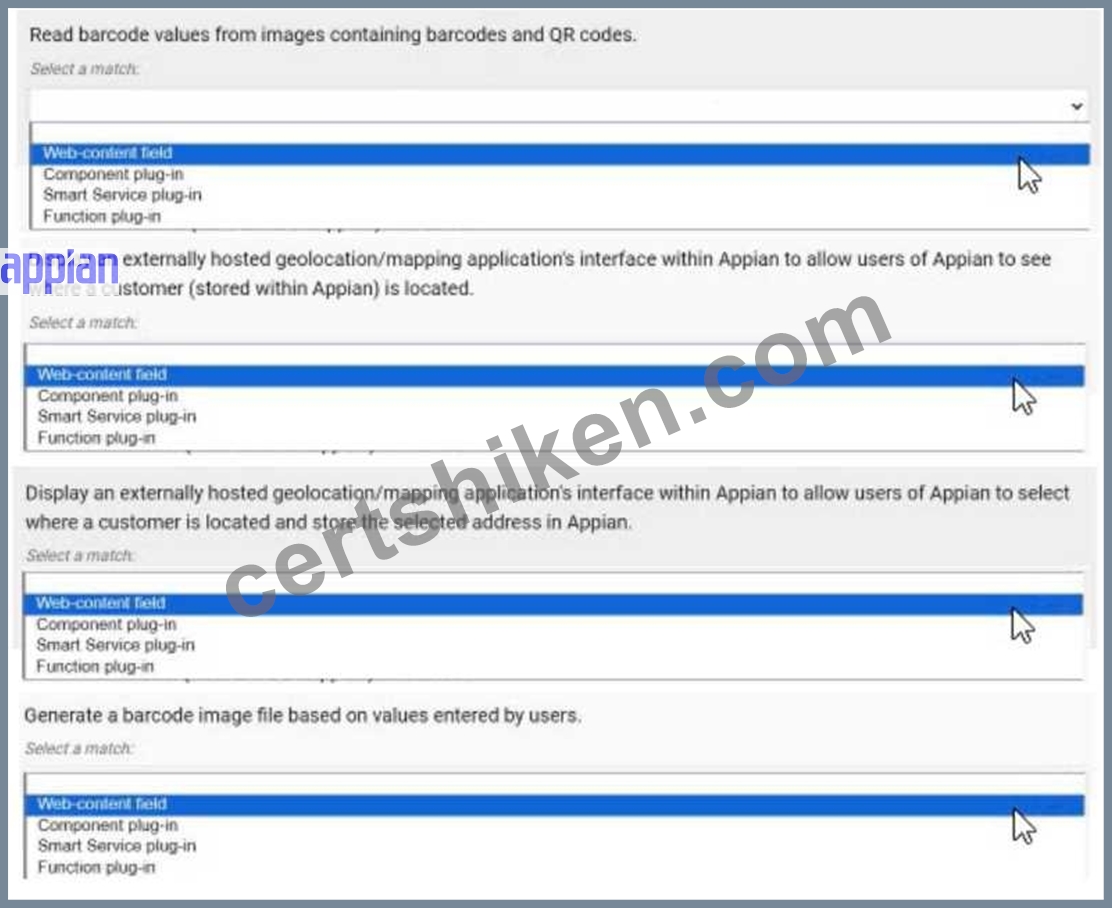
正解:
解説:
質問 # 29
A customer wants to integrate a CSV file once a day into their Appian application, sent every night at 1:00 AM. The file contains hundreds of thousands of items to be used daily by users as soon as their workday starts at 8:00 AM. Considering the high volume of data to manipulate and the nature of the operation, what is the best technical option to process the requirement?
正解:B
解説:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, handling a daily CSV integration with hundreds of thousands of items requires a solution that balances performance, scalability, and Appian's architectural strengths. The timing (1:00 AM integration, 8:00 AM availability) and data volume necessitate efficient processing and minimal runtime overhead. Let's evaluate each option based on Appian's official documentation and best practices:
A . Use an Appian Process Model, initiated after every integration, to loop on each item and update it to the business requirements:
This approach involves parsing the CSV in a process model and using a looping mechanism (e.g., a subprocess or script task with fn!forEach) to process each item. While Appian process models are excellent for orchestrating workflows, they are not optimized for high-volume data processing. Looping over hundreds of thousands of records would strain the process engine, leading to timeouts, memory issues, or slow execution-potentially missing the 8:00 AM deadline. Appian's documentation warns against using process models for bulk data operations, recommending database-level processing instead. This is not a viable solution.
B . Build a complex and optimized view (relevant indices, efficient joins, etc.), and use it every time a user needs to use the data:
This suggests loading the CSV into a table and creating an optimized database view (e.g., with indices and joins) for user queries via a!queryEntity. While this improves read performance for users at 8:00 AM, it doesn't address the integration process itself. The question focuses on processing the CSV ("manipulate" and "operation"), not just querying. Building a view assumes the data is already loaded and transformed, leaving the heavy lifting of integration unaddressed. This option is incomplete and misaligned with the requirement's focus on processing efficiency.
C . Create a set of stored procedures to handle the volume and the complexity of the expectations, and call it after each integration:
This is the best choice. Stored procedures, executed in the database, are designed for high-volume data manipulation (e.g., parsing CSV, transforming data, and applying business logic). In this scenario, you can configure an Appian process model to trigger at 1:00 AM (using a timer event) after the CSV is received (e.g., via FTP or Appian's File System utilities), then call a stored procedure via the "Execute Stored Procedure" smart service. The stored procedure can efficiently bulk-load the CSV (e.g., using SQL's BULK INSERT or equivalent), process the data, and update tables-all within the database's optimized environment. This ensures completion by 8:00 AM and aligns with Appian's recommendation to offload complex, large-scale data operations to the database layer, maintaining Appian as the orchestration layer.
D . Process what can be completed easily in a process model after each integration, and complete the most complex tasks using a set of stored procedures:
This hybrid approach splits the workload: simple tasks (e.g., validation) in a process model, and complex tasks (e.g., transformations) in stored procedures. While this leverages Appian's strengths (orchestration) and database efficiency, it adds unnecessary complexity. Managing two layers of processing increases maintenance overhead and risks partial failures (e.g., process model timeouts before stored procedures run). Appian's best practices favor a single, cohesive approach for bulk data integration, making this less efficient than a pure stored procedure solution (C).
Conclusion: Creating a set of stored procedures (C) is the best option. It leverages the database's native capabilities to handle the high volume and complexity of the CSV integration, ensuring fast, reliable processing between 1:00 AM and 8:00 AM. Appian orchestrates the trigger and integration (e.g., via a process model), while the stored procedure performs the heavy lifting-aligning with Appian's performance guidelines for large-scale data operations.
Appian Documentation: "Execute Stored Procedure Smart Service" (Process Modeling > Smart Services).
Appian Lead Developer Certification: Data Integration Module (Handling Large Data Volumes).
Appian Best Practices: "Performance Considerations for Data Integration" (Database vs. Process Model Processing).
質問 # 30
As part of an upcoming release of an application, a new nullable field is added to a table that contains customer dat a. The new field is used by a report in the upcoming release and is calculated using data from another table.
Which two actions should you consider when creating the script to add the new field?
正解:D、E
解説:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, adding a new nullable field to a database table for an upcoming release requires careful planning to ensure data integrity, report functionality, and rollback capability. The field is used in a report and calculated from another table, so the script must handle both deployment and potential reversibility. Let's evaluate each option:
A . Create a script that adds the field and leaves it null:
Adding a nullable field and leaving it null is technically feasible (e.g., using ALTER TABLE ADD COLUMN in SQL), but it doesn't address the report's need for calculated data. Since the field is used in a report and calculated from another table, leaving it null risks incomplete or incorrect reporting until populated, delaying functionality. Appian's data management best practices recommend populating data during deployment for immediate usability, making this insufficient as a standalone action.
B . Create a rollback script that removes the field:
This is a critical action. In Appian, database changes (e.g., adding a field) must be reversible in case of deployment failure or rollback needs (e.g., during testing or PROD issues). A rollback script that removes the field (e.g., ALTER TABLE DROP COLUMN) ensures the database can return to its original state, minimizing risk. Appian's deployment guidelines emphasize rollback scripts for schema changes, making this essential for safe releases.
C . Create a script that adds the field and then populates it:
This is also essential. Since the field is nullable, calculated from another table, and used in a report, populating it during deployment ensures immediate functionality. The script can use SQL (e.g., UPDATE table SET new_field = (SELECT calculated_value FROM other_table WHERE condition)) to populate data, aligning with Appian's data fabric principles for maintaining data consistency. Appian's documentation recommends populating new fields during deployment for reporting accuracy, making this a key action.
D . Create a rollback script that clears the data from the field:
Clearing data (e.g., UPDATE table SET new_field = NULL) is less effective than removing the field entirely. If the deployment fails, the field's existence with null values could confuse reports or processes, requiring additional cleanup. Appian's rollback strategies favor reverting schema changes completely (removing the field) rather than leaving it with nulls, making this less reliable and unnecessary compared to B.
E . Add a view that joins the customer data to the data used in calculation:
Creating a view (e.g., CREATE VIEW customer_report AS SELECT ... FROM customer_table JOIN other_table ON ...) is useful for reporting but isn't a prerequisite for adding the field. The scenario focuses on the field addition and population, not reporting structure. While a view could optimize queries, it's a secondary step, not a primary action for the script itself. Appian's data modeling best practices suggest views as post-deployment optimizations, not script requirements.
Conclusion: The two actions to consider are B (create a rollback script that removes the field) and C (create a script that adds the field and then populates it). These ensure the field is added with data for immediate report usability and provide a safe rollback option, aligning with Appian's deployment and data management standards for schema changes.
Appian Documentation: "Database Schema Changes" (Adding Fields and Rollback Scripts).
Appian Lead Developer Certification: Data Management Module (Schema Deployment Strategies).
Appian Best Practices: "Managing Data Changes in Production" (Populating and Rolling Back Fields).
質問 # 31
......
すべてのお客様に24時間のオンラインアフターサービスを提供します。 ACD-301の実際の試験のインストールまたは使用について質問がある場合は、専門のアフターサービススタッフがウォームリモートサービスを提供します。 ACD-301学習教材に関する限り、解決することができます。メールでお問い合わせいただく場合でも、オンラインでお問い合わせいただく場合でも、できるだけ早く問題を解決できるようサポートいたします。心配する必要はまったくありません。ACD-301トレーニングの質問のインストールまたは使用を懸念しているお客様がいるかもしれません。これについて心配する必要はありません。
ACD-301合格体験談: https://www.certshiken.com/ACD-301-shiken.html
さらに、CertShiken ACD-301ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1D48FpkJ7T44rBBsjzN6VwX5Je3qLEN0O