bestehen Sie Databricks-Machine-Learning-Professional Ihre Prüfung mit unserem Prep Databricks-Machine-Learning-Professional Ausbildung Material & kostenloser Dowload Torrent

BONUS!!! Laden Sie die vollständige Version der It-Pruefung Databricks-Machine-Learning-Professional Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1MrYDRoh9UmTTei5J6Bk4dUGnIA8bu4b9
Laut Umfragen haben die Databricks Databricks-Machine-Learning-Professional Prüfung heutzutage hohe Konjunktur in IT-Zertifizierungen. Tatsächlich ist die Databricks-Machine-Learning-Professional Zertifizierungsprüfung sehr wichtig. Und jetzt ist Databricks-Machine-Learning-Professional Prüfung öffentlich zertifiziert. Außerdem kann diese Prüfung Ihre ausgezeichnete IT-Fähigkeit beweisen. Aber es ist sehr schwer, Databricks Databricks-Machine-Learning-Professional Prüfung zu bestehen. Und die Schwierigkeit ist so groß wie ihre Bedeutung. Trotzt dieser Schwierigkeit sorgen Sie sich bitte nicht um den Erfolg, die Prüfung ablegen, weil It-Pruefung Ihnen helfen kann, diese schwierige Databricks-Machine-Learning-Professional Prüfung zu bestehen.
Databricks Databricks-Machine-Learning-Professional Prüfungsplan:
| Thema | Einzelheiten |
|---|
| Thema 1 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Thema 2 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Thema 3 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Thema 4 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Thema 5 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Thema 6 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Thema 7 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Thema 8 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Thema 9 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Thema 10 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Thema 11 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
>> Databricks-Machine-Learning-Professional Lernhilfe <<
Databricks-Machine-Learning-Professional Zertifizierungsantworten - Databricks-Machine-Learning-Professional Lernressourcen
Wenn Sie Ihre IT-Fähigkeiten erhöhen und die Databricks Databricks-Machine-Learning-Professional Zertifizierungsprüfung einmalig bestehen möchten, können Sie auf It-Pruefung vertrauen. Denn It-Pruefung kann Ihnen helfen, das Prüfungszertifikat zu bekommen, indem wir Ihnen die zutreffendesten und genauesten Fragenkataloge zur Databricks Databricks-Machine-Learning-Professional Zertifizierungsprüfung anbieten. Wenn Sie mit dem Kaufen noch zögern, können Sie die Demo auf unserer Webseite It-Pruefung herunterladen. Wir sind sicher, dass Sie nicht enttäuscht sein werden.
Databricks Certified Machine Learning Professional Databricks-Machine-Learning-Professional Prüfungsfragen mit Lösungen (Q54-Q59):
54. Frage
What does an Estimator do in Spark ML?
- A. Stores features
- B. Transforms a dataset
- C. Trains a model using data
- D. Evaluates model performance
Antwort: C
Begründung:
An Estimator learns from data and produces a Transformer.
55. Frage
A Machine Learning Engineer uses Lakehouse Monitoring to track their credit scoring model's performance. The existing profile metrics table contains three aggregate metrics:
- adefault_risk_score
- payment_history_score
- credit_utilization_score
They need to:
1. Create a composite risk rating that combines these three scores using weights of 0.5, 0.3, and 0.2 respectively.
2. Monitor drift of this composite score against an established baseline.
Which approach should be used to implement both requirements within Lakehouse Monitoring?
- A. Use a scheduled notebook to calculate the composite score and manually insert both the score and drift values into the profile metrics table.
- B. Create a derived metric for the composite_risk_rating calculation and create a drift metric on this derived metric.
- C. Create an aggregate metric for composite_risk_rating and configure a separate drift metric to monitor changes.
- D. Create two separate aggregate metrics: one for the composite score calculation and another for drift detection.
Antwort: B
Begründung:
Lakehouse Monitoring supports derived metrics that are computed from existing profile metrics using custom expressions. By defining a derived metric for the composite_risk_rating using the specified weights, the composite score becomes a first-class metric in the monitoring framework.
A drift metric can then be directly configured on this derived metric to compare current values against the baseline, fulfilling both the composite calculation and drift monitoring requirements in a native, governed way.
56. Frage
In order to connect an MLflow Model Registry Webhook to a Databricks Job, the Job ID must be provided to the code block used to create the webhook. Which approach can be used to obtain a Databricks Job ID?
- A. All of these approaches
- B. The Job ID field in the Job details section of the specific Job page in the UI
- C. The Job ID field returned in a query using the Jobs API
- D. The Job ID field in the Jobs page in the UI
Antwort: A
Begründung:
A Databricks Job ID can be obtained in multiple ways - it is displayed directly in the Jobs page, in the Job details section of a specific Job, and can also be retrieved programmatically through the Databricks Jobs API. Any of these methods can be used to supply the Job ID when configuring an MLflow Model Registry Webhook.
57. Frage
A machine learning engineer has deployed a model recommender using MLflow Model Serving.
They now want to query the version of that model that is in the Production stage of the MLflow Model Registry. Which of the following model URIs can be used to query the described model version?
- A. https://<databricks-instance>/model-serving/recommender/stage-production/invocations
- B. The version number of the model version in Production is necessary to complete this task.
- C. https://<databricks-instance>/model-serving/recommender/Production/invocations
- D. https://<databricks-instance>/model/recommender/Production/invocations
- E. https://<databricks-instance>/model/recommender/stage-production/invocations
Antwort: B
58. Frage
A data scientist would like to switch from manually using MLflow logging to MLflow Autologging for all machine learning libraries used in a notebook.
They begin by adding mlflow.autolog()to the top of the below code block:
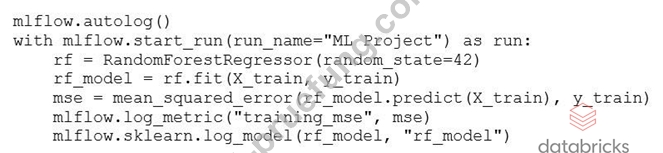
The data scientist is now trying to determine which line of code will kick off the MLflow Autologging process.
Which line of code within the above code block will start the MLflow Autologging process?
- A. mlflow.sklearn.log_model(rf_model, "rf_model")
- B. rf_model = rf.fit(X_train, y_train)
- C. with mlflow.start_run(run_name="ML Project") as run:
- D. mlflow.log_metric("training_mse", mse)
Antwort: B
Begründung:
The MLflow Autologging process is triggered when a model's training function is called. In this case, rf.fit(X_train, y_train) starts the autologging process because mlflow.autolog() automatically tracks parameters, metrics, and the model when a supported estimator (like RandomForestRegressor) is fitted. The context manager mlflow.start_run() only initiates an MLflow run, but the actual autologging begins during the .fit() execution.
59. Frage
......
Wir versprechen, dass Sie die Databricks Databricks-Machine-Learning-Professional Zertifizierungsprüfung bestehen würden, wenn Sie die Fragenpool von It-Pruefung zur Databricks Databricks-Machine-Learning-Professional Prüfung gekauft haben. Falls Sie die Databricks-Machine-Learning-Professional Prüfung nicht bestehen oder die Databricks-Machine-Learning-Professional Schulungsunterlagen irgendein Qualitätsproblem haben, erstatten wir Ihnen alle Ihre an uns geleistete Zahlung. Darüber hinaus werden Sie eihjähriger Aktualisierung genießen, nachdem Sie unsere Schulungsunterlagen zur Databricks Databricks-Machine-Learning-Professional Prüfung gekauft haben.
Databricks-Machine-Learning-Professional Zertifizierungsantworten: https://www.it-pruefung.com/Databricks-Machine-Learning-Professional.html
- Databricks-Machine-Learning-Professional Dumps 🐪 Databricks-Machine-Learning-Professional Dumps Deutsch 🌏 Databricks-Machine-Learning-Professional Dumps Deutsch 🥺 Suchen Sie auf 【 www.zertpruefung.ch 】 nach kostenlosem Download von ⮆ Databricks-Machine-Learning-Professional ⮄ 🥗Databricks-Machine-Learning-Professional Dumps Deutsch
- Databricks-Machine-Learning-Professional Databricks Certified Machine Learning Professional neueste Studie Torrent - Databricks-Machine-Learning-Professional tatsächliche prep Prüfung 😠 Suchen Sie auf der Webseite ✔ www.itzert.com ️✔️ nach ✔ Databricks-Machine-Learning-Professional ️✔️ und laden Sie es kostenlos herunter ✡Databricks-Machine-Learning-Professional Originale Fragen
- Databricks-Machine-Learning-Professional Studienmaterialien: Databricks Certified Machine Learning Professional - Databricks-Machine-Learning-Professional Torrent Prüfung - Databricks-Machine-Learning-Professional wirkliche Prüfung 🎓 Suchen Sie jetzt auf ➠ www.itzert.com 🠰 nach ☀ Databricks-Machine-Learning-Professional ️☀️ und laden Sie es kostenlos herunter 🟥Databricks-Machine-Learning-Professional Lernhilfe
- bestehen Sie Databricks-Machine-Learning-Professional Ihre Prüfung mit unserem Prep Databricks-Machine-Learning-Professional Ausbildung Material - kostenloser Dowload Torrent 🕓 URL kopieren [ www.itzert.com ] Öffnen und suchen Sie ⇛ Databricks-Machine-Learning-Professional ⇚ Kostenloser Download 🏰Databricks-Machine-Learning-Professional Examsfragen
- Databricks-Machine-Learning-Professional Probesfragen 🗾 Databricks-Machine-Learning-Professional Prüfungsunterlagen 🥈 Databricks-Machine-Learning-Professional Dumps Deutsch 🤓 Suchen Sie jetzt auf ⇛ www.zertsoft.com ⇚ nach ▛ Databricks-Machine-Learning-Professional ▟ und laden Sie es kostenlos herunter 🥏Databricks-Machine-Learning-Professional Prüfungsunterlagen
- Reliable Databricks-Machine-Learning-Professional training materials bring you the best Databricks-Machine-Learning-Professional guide exam: Databricks Certified Machine Learning Professional 🔄 Erhalten Sie den kostenlosen Download von “ Databricks-Machine-Learning-Professional ” mühelos über “ www.itzert.com ” 🎉Databricks-Machine-Learning-Professional Lernhilfe
- Databricks-Machine-Learning-Professional Schulungsangebot - Databricks-Machine-Learning-Professional Simulationsfragen - Databricks-Machine-Learning-Professional kostenlos downloden 📿 Suchen Sie jetzt auf ▶ www.zertpruefung.de ◀ nach “ Databricks-Machine-Learning-Professional ” um den kostenlosen Download zu erhalten 🦈Databricks-Machine-Learning-Professional Lerntipps
- Databricks-Machine-Learning-Professional Lerntipps 👧 Databricks-Machine-Learning-Professional Originale Fragen 🏳 Databricks-Machine-Learning-Professional Exam Fragen 🔰 Suchen Sie auf der Webseite ☀ www.itzert.com ️☀️ nach [ Databricks-Machine-Learning-Professional ] und laden Sie es kostenlos herunter 🤪Databricks-Machine-Learning-Professional Probesfragen
- Databricks Databricks-Machine-Learning-Professional Quiz - Databricks-Machine-Learning-Professional Studienanleitung - Databricks-Machine-Learning-Professional Trainingsmaterialien 💘 Suchen Sie einfach auf ⇛ www.itzert.com ⇚ nach kostenloser Download von 「 Databricks-Machine-Learning-Professional 」 🐡Databricks-Machine-Learning-Professional Deutsch Prüfung
- Databricks-Machine-Learning-Professional Testengine 💚 Databricks-Machine-Learning-Professional Deutsch Prüfung 🥓 Databricks-Machine-Learning-Professional Online Prüfungen 🕒 Sie müssen nur zu ⮆ www.itzert.com ⮄ gehen um nach kostenloser Download von ( Databricks-Machine-Learning-Professional ) zu suchen ⏲Databricks-Machine-Learning-Professional Exam Fragen
- Databricks-Machine-Learning-Professional Studienmaterialien: Databricks Certified Machine Learning Professional - Databricks-Machine-Learning-Professional Torrent Prüfung - Databricks-Machine-Learning-Professional wirkliche Prüfung 🍣 Geben Sie ⇛ www.zertfragen.com ⇚ ein und suchen Sie nach kostenloser Download von ➠ Databricks-Machine-Learning-Professional 🠰 👏Databricks-Machine-Learning-Professional Testengine
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, portfolium.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.twosapp.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Laden Sie die vollständige Version der It-Pruefung Databricks-Machine-Learning-Professional Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1MrYDRoh9UmTTei5J6Bk4dUGnIA8bu4b9