DOWNLOAD the newest TroytecDumps DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1fzTVk85M5403mPaEF4ZKSm1Ou70-aLsJ
Passing the DP-600 exam with least time while achieving aims effortlessly is like a huge dreams for some exam candidates. Actually, it is possible with our proper DP-600 learning materials. To discern what ways are favorable for you to practice and what is essential for exam syllabus, our experts made great contributions to them. All DP-600 Practice Engine is highly interrelated with the exam. You will figure out this is great opportunity for you.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
Our DP-600 exam torrent is available in different versions. Whether you like to study on a computer or enjoy reading paper materials, our test prep can meet your needs. Our PDF version of the DP-600 quiz guide is available for customers to print. You can print it out, so you can practice it repeatedly conveniently. And our DP-600 exam torrent make it easy for you to take notes on it so that your free time can be well utilized and you can often consolidate your knowledge. Everything you do will help you successfully pass the exam and get the card. The version of APP and PC of our DP-600 Exam Torrent is also popular. They can simulate real operation of test environment and users can test DP-600 test prep in mock exam in limited time. They are very practical and they have online error correction and other functions. The characteristic that three versions of DP-600 exam torrent all have is that they have no limit of the number of users, so you don’t encounter failures anytime you want to learn our DP-600 quiz guide. The three different versions can help customers solve any questions and meet their all needs.
NEW QUESTION # 197
You are analyzing customer purchases in a Fabric notebook by using PySpanc You have the following DataFrames:
You need to join the DataFrames on the customer_id column. The solution must minimize data shuffling. You write the following code.
Which code should you run to populate the results DataFrame?



Answer: D
Explanation:
The correct code to populate the results DataFrame with minimal data shuffling is Option A. Using the broadcast function in PySpark is a way to minimize data movement by broadcasting the smaller DataFrame (customers) to each node in the cluster. This is ideal when one DataFrame is much smaller than the other, as in this case with customers. References = You can refer to the official Apache Spark documentation for more details on joins and the broadcast hint.
NEW QUESTION # 198
Case Study 1 - Contoso
Overview
Contoso, Ltd. is a US-based health supplements company. Contoso has two divisions named Sales and Research. The Sales division contains two departments named Online Sales and Retail Sales. The Research division assigns internally developed product lines to individual teams of researchers and analysts.
Existing Environment
Identity Environment
Contoso has a Microsoft Entra tenant named contoso.com. The tenant contains two groups named ResearchReviewersGroup1 and ResearchReviewersGroup2.
Data Environment
Contoso has the following data environment:
- The Sales division uses a Microsoft Power BI Premium capacity.
- The semantic model of the Online Sales department includes a fact table named Orders that uses Import made. In the system of origin, the OrderID value represents the sequence in which orders are created.
- The Research department uses an on-premises, third-party data warehousing product.
- Fabric is enabled for contoso.com.
- An Azure Data Lake Storage Gen2 storage account named storage1 contains Research division data for a product line named Productline1. - The data is in the delta format.
- A Data Lake Storage Gen2 storage account named storage2 contains Research division data for a product line named Productline2. The data is in the CSV format.
Requirements
Planned Changes
Contoso plans to make the following changes:
- Enable support for Fabric in the Power BI Premium capacity used by the Sales division.
- Make all the data for the Sales division and the Research division available in Fabric.
- For the Research division, create two Fabric workspaces named Productline1ws and Productine2ws.
- In Productline1ws, create a lakehouse named Lakehouse1.
- In Lakehouse1, create a shortcut to storage1 named ResearchProduct.
Data Analytics Requirements
Contoso identifies the following data analytics requirements:
- All the workspaces for the Sales division and the Research division must support all Fabric experiences.
- The Research division workspaces must use a dedicated, on-demand capacity that has per- minute billing.
- The Research division workspaces must be grouped together logically to support OneLake data hub filtering based on the department name.
- For the Research division workspaces, the members of ResearchReviewersGroup1 must be able to read lakehouse and warehouse data and shortcuts by using SQL endpoints.
- For the Research division workspaces, the members of ResearchReviewersGroup2 must be able to read lakehouse data by using Lakehouse explorer.
- All the semantic models and reports for the Research division must use version control that supports branching.
Data Preparation Requirements
Contoso identifies the following data preparation requirements:
- The Research division data for Productline1 must be retrieved from Lakehouse1 by using Fabric notebooks.
- All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer.
Semantic Model Requirements
Contoso identifies the following requirements for implementing and managing semantic models:
- The number of rows added to the Orders table during refreshes must be minimized.
- The semantic models in the Research division workspaces must use Direct Lake mode.
General Requirements
Contoso identifies the following high-level requirements that must be considered for all solutions:
- Follow the principle of least privilege when applicable.
- Minimize implementation and maintenance effort when possible.
You need to refresh the Orders table of the Online Sales department. The solution must meet the semantic model requirements.
What should you include in the solution?
Answer: C
Explanation:
We need to retrieve the maximum OrderID in the destination table to minimize the number of rows added during refresh. this would be an incremental load. can be done with data flows.
NEW QUESTION # 199
You have a Fabric tenant that contains a lakehouse.
You plan to query sales data files by using the SQL endpoint. The files will be in an Amazon Simple Storage Service (Amazon S3) storage bucket.
You need to recommend which file format to use and where to create a shortcut.
Which two actions should you include in the recommendation? Each correct answer presents part of the solution.
NOTE: Each correct answer is worth one point.
Answer: D,E
Explanation:
You should use the Parquet format (B) for the sales data files because it is optimized for performance with large datasets in analytical processing and create a shortcut in the Tables section (D) to facilitate SQL queries through the lakehouse's SQL endpoint. References = The best practices for working with file formats and shortcuts in a lakehouse environment are covered in the lakehouse and SQL endpoint documentation provided by the cloud data platform services.
NEW QUESTION # 200
You have a Fabric tenant that contains a data warehouse named DW1. DW1 contains a table named DimCustomer. DimCustomer contains the fields shown in the following table.
You need to identify duplicate email addresses in DimCustomer. The solution must return a maximum of 1,000 records.
Which four T-SQL statements should you run in sequence? To answer, move the appropriate statements from the list of statements to the answer area and arrange them in the correct order.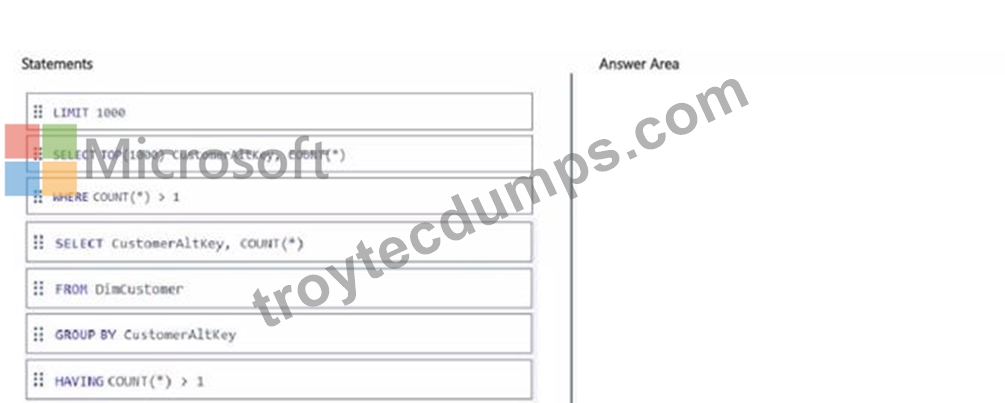
Answer:
Explanation:
NEW QUESTION # 201
You have a Fabric workspace that contains a warehouse named DW1. DW1 contains the following tables and columns.
You need to summarize order quantities by year and product. The solution must include the yearly sum of order quantities for all the products in each row.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Comprehensive Detailed Explanation
We need to write a query that summarizes order quantities by year and product, and also include the yearly total for all products in each row.
Step 1: What the query needs
Extract the year from SalesOrderDetail.ModifiedDate.
Join with the Product table to get the product name.
Aggregate with SUM(OrderQty).
Return grouped data by year and product, with an additional subtotal row per year (all products combined).
Step 2: Evaluate the SELECT Clause
We must extract the year using:
YEAR(so.ModifiedDate) AS OrderDate
This converts the ModifiedDate column into a year value for grouping.
Step 3: Evaluate the GROUP BY options
CUBE(YEAR, P.Name) # Produces all combinations of year totals, product totals, and grand totals. Too many combinations, not required.
GROUPING SETS # Could achieve the result but requires explicitly listing the sets. Less direct.
ROLLUP(YEAR, P.Name) # Produces grouping by (Year, Product) and then a subtotal per Year. Exactly what is required.
YEAR only # Would group only by year, losing per-product breakdown.
Correct: ROLLUP(YEAR(so.ModifiedDate), P.Name)
Step 4: Completed Query
SELECT
YEAR(so.ModifiedDate) AS OrderDate,
p.Name,
SUM(so.OrderQty) AS OrderQty
FROM dbo.SalesOrderDetail so
INNER JOIN dbo.Product p
ON p.ProductID = so.ProductID
GROUP BY ROLLUP(YEAR(so.ModifiedDate), p.Name);
Why This Works
YEAR(so.ModifiedDate) extracts year for grouping.
ROLLUP(YEAR, P.Name) provides both product-level totals and yearly subtotals.
Ensures the requirement: "include the yearly sum of order quantities for all the products in each row." References GROUP BY ROLLUP in T-SQL Aggregate functions in Microsoft Fabric warehouses
NEW QUESTION # 202
......
You final purpose is to get the DP-600 certificate. So it is important to choose good study materials. In fact, our aim is the same with you. Our DP-600 study materials have strong strengths to help you pass the exam. Maybe you still have doubts about our DP-600 exam materials. We have statistics to prove the truth. First of all, our sales volumes are the highest in the market. You can browse our official websites to check our sales volumes. At the same time, many people pass the exam for the first time under the guidance of our DP-600 Practice Exam.
Sample DP-600 Questions Pdf: https://www.troytecdumps.com/DP-600-troytec-exam-dumps.html
What's more, part of that TroytecDumps DP-600 dumps now are free: https://drive.google.com/open?id=1fzTVk85M5403mPaEF4ZKSm1Ou70-aLsJ