P.S. Free & New DP-750 dumps are available on Google Drive shared by Lead1Pass: https://drive.google.com/open?id=1ensIoyLefziLrF9yHbN6Zwc2hv7VmbIl
Testing yourself is an effective way to enhance your knowledge and become familiar with the DP-750 exam format. Rather than viewing the DP-750 test as a potentially intimidating event, Lead1Pass Implementing Data Engineering Solutions Using Azure Databricks (DP-750) desktop and web-based practice exams help candidates assess and improve their knowledge. If your DP-750 Practice Exams (desktop and web-based) results aren't ideal, it's better to experience that shock during a mock exam rather than the DP-750 actual test.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 2: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 4: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
>> Exam Microsoft DP-750 Pass Guide <<
Our experts offer help by diligently working on the content of DP-750 learning questions more and more accurate. Being an exam candidate in this area, we believe after passing the exam by the help of our DP-750 practice materials, you will only learn a lot from this DP-750 Exam but can handle many problems emerging in a long run. You can much more benefited form our DP-750 study guide. Don't hesitate, it is worthy to purchase!
NEW QUESTION # 20
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
- Ensure that authentication does NOT require storing credentials in
Databricks.
- Ensure that users can access the files, but NOT modify the files.
- Follow the principle of least privilege.
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.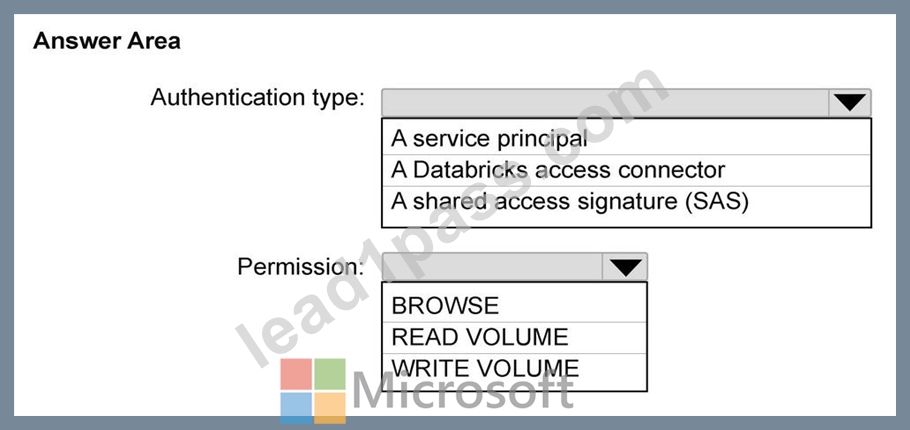
Answer:
Explanation: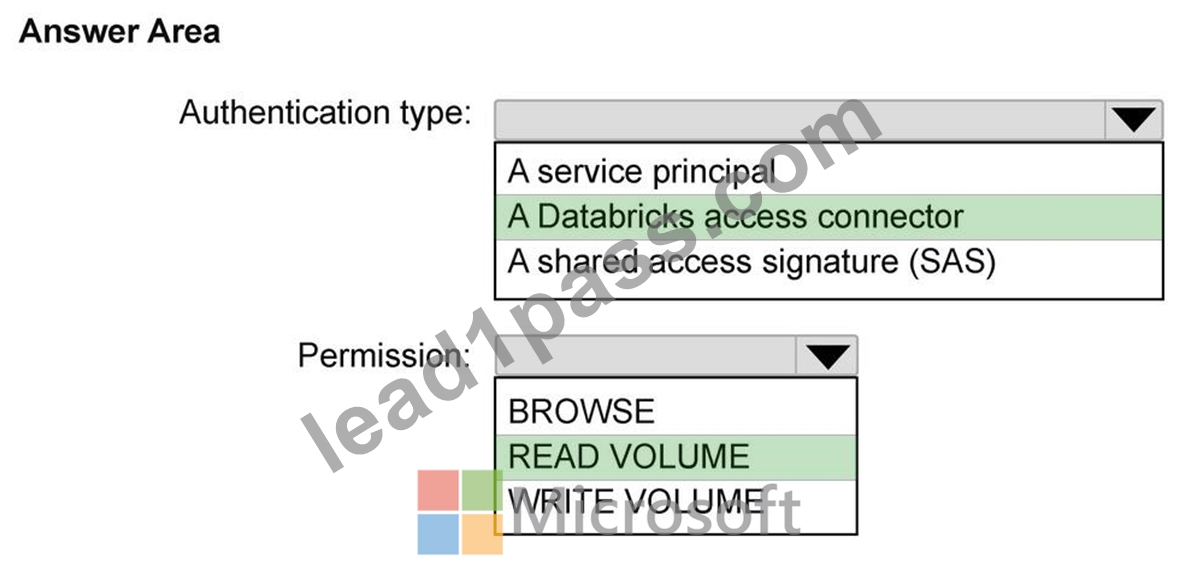
NEW QUESTION # 21
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
Answer: C
Explanation:
The correct answer is A. Photon is Azure Databricks' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso's requirement for 'fast and consistent performance for BI workloads' and 'production ingestion workloads that can scale automatically during telemetry spikes.' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what's needed - telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
NEW QUESTION # 22
What is the best way to reduce Databricks compute cost for intermittent workloads?
Answer: C
Explanation:
Autoscaling adjusts resources based on workload demand, and auto-termination shuts down idle clusters, reducing cost significantly. All-purpose clusters are always on. Increasing size raises cost. Single-node clusters limit scalability and are not suitable for production workloads.
NEW QUESTION # 23
You have an Azure Databticks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group!
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
* Can create tables in schema1
* Can modify and query tables
* Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.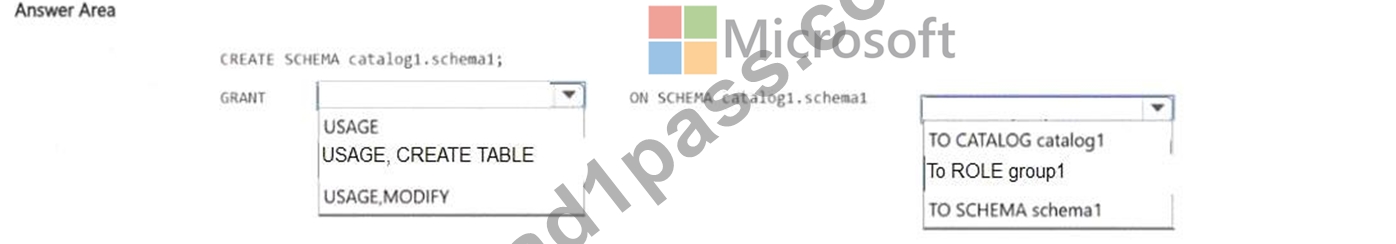
Answer:
Explanation: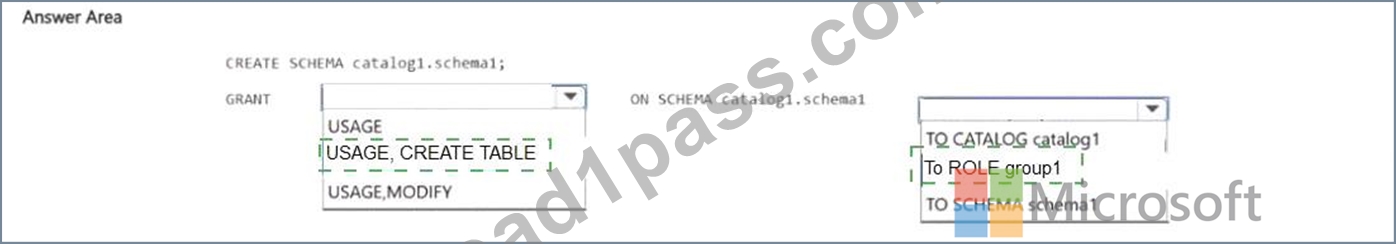
Explanation:
The correct SQL grants group1 the ability to work within the schema without delegating that ability to anyone else:
GRANT USE SCHEMA ON schema1 TO group1 - required as a prerequisite to access any object inside the schema.
GRANT CREATE TABLE ON SCHEMA schema1 TO group1 - allows creating new tables.
GRANT SELECT, MODIFY ON SCHEMA schema1 TO group1 - SELECT for queries, MODIFY for INSERT/UPDATE/DELETE operations.
Crucially, MANAGE is NOT granted. In Unity Catalog, MANAGE is what allows a principal to grant and revoke privileges on the schema and its objects. Leaving it out means group1 can do all the data work but cannot redistribute those permissions - precisely what the requirement 'Cannot grant permissions for the schema and its objects' demands.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/manage- privileges/privileges
NEW QUESTION # 24
You have an Azure Databricks workspace named Workspace1. You create a compute cluster named Cluser1 that will be used to ingest data.
You need to install the required libraries on Cluster 1. The solution must use Unity Catalog for access control.
What should you do?
Answer: B
Explanation:
The correct answer is B. The %pip install command (or pip3 in a terminal context) creates an isolated, per- session library environment in notebooks, which is the Unity Catalog-compatible approach. Unity Catalog workspaces require cluster access mode set to 'Shared' or 'Single User,' and %pip installs work seamlessly within those modes without requiring cluster restarts.
Option A (custom dependency script) introduces extra maintenance work for every environment change - exactly what the question says to avoid. Option C installs libraries at the cluster level and requires a manual restart, which disrupts other users sharing the cluster and bypasses the per-notebook isolation model that Unity Catalog recommends. Option D uploads libraries to the Workspace file system (legacy DBFS approach), which is being deprecated in favour of Unity Catalog Volumes for library storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/libraries/notebooks-python-libraries
NEW QUESTION # 25
......
Our DP-750 exam guide have also set a series of explanation about the complicated parts certificated by the syllabus and are based on the actual situation to stimulate exam circumstance in order to provide you a high-quality and high-efficiency user experience. In addition, the DP-750 exam guide function as a time-counter, and you can set fixed time to fulfill your task, so that promote your efficiency in real test. The key strong-point of our DP-750 Test Guide is that we impart more important knowledge with fewer questions and answers, with those easily understandable DP-750 study braindumps, you will find more interests in them and experience an easy learning process.
DP-750 Exam Reference: https://www.lead1pass.com/Microsoft/DP-750-practice-exam-dumps.html
2026 Latest Lead1Pass DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1ensIoyLefziLrF9yHbN6Zwc2hv7VmbIl