P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by Dumpexams: https://drive.google.com/open?id=1-XxU1qSzyfS7jwAaRokxqjFMiNiSVX3j
As to the rapid changes happened in this MLA-C01 exam, experts will fix them and we assure your MLA-C01 exam simulation you are looking at now are the newest version. Materials trends are not always easy to forecast on our study guide, but they have predictable pattern for them by ten-year experience who often accurately predict points of knowledge occurring in next MLA-C01 Preparation materials.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
As we all know, HR form many companies hold the view that candidates who own a MLA-C01 professional certification are preferred, because they are more likely to solve potential problems during work. And the MLA-C01 certification vividly demonstrates the fact that they are better learners. Concentrated all our energies on the study MLA-C01 learning guide we never change the goal of helping candidates pass the exam. Our MLA-C01 test questions’ quality is guaranteed by our experts’ hard work. So what are you waiting for? Just choose our MLA-C01 exam materials, and you won’t be regret.
NEW QUESTION # 11
A company uses Amazon SageMakerAI to support ML workflows such as model training and deployment.
Select the correct registry from the following list to meet the requirements for each use case with the LEAST operational overhead. Each registry should be selected one or more times. (Select FOUR.)
* Amazon Elastic Container Registry (Amazon ECR)
* SageMaker Model Registry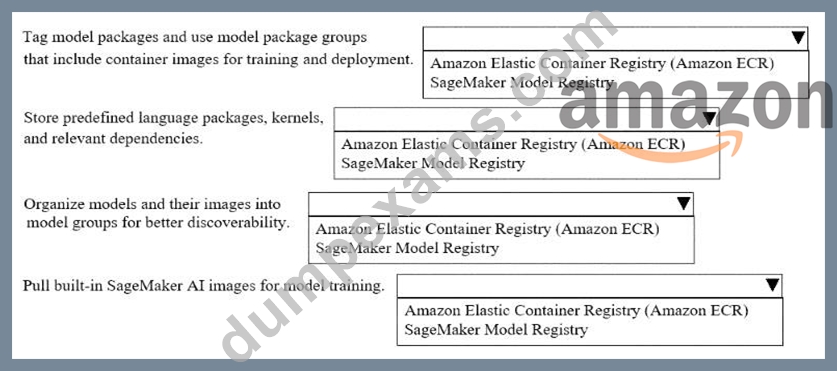
Answer:
Explanation: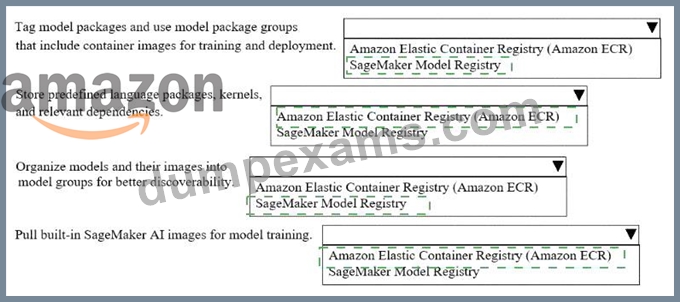
Explanation:
* Tag model packages and use model package groups that include container images for training and deployment # SageMaker Model Registry
* Store predefined language packages, kernels, and relevant dependencies # Amazon Elastic Container Registry (Amazon ECR)
* Organize models and their images into model groups for better discoverability # SageMaker Model Registry
* Pull built-in SageMaker AI images for model training # Amazon Elastic Container Registry (Amazon ECR) The correct hotspot mapping is based on the different purposes of SageMaker Model Registry and Amazon ECR.
For model packages, model package groups, and model discoverability, the correct choice is SageMaker Model Registry. AWS documentation states that a model package group is a collection of versioned model packages, and each version can contain the model artifacts, metadata, and container information used for deployment. AWS also documents that registered models can be organized into groups to support governance, discoverability, and lifecycle management. That is why both "tag model packages and use model package groups" and "organize models and their images into model groups" map to SageMaker Model Registry.
For storing software environments and pulling training images, the correct choice is Amazon ECR. AWS documentation says SageMaker uses Docker container images, and these images contain the software stack such as frameworks, language packages, kernels, and dependencies. AWS also states that SageMaker provides prebuilt Docker images for training and inference, and these are referenced through Amazon ECR image URIs. Therefore, both "store predefined language packages, kernels, and relevant dependencies" and
"pull built-in SageMaker AI images for model training" map to Amazon ECR.
NEW QUESTION # 12
A company uses AWS CodePipeline to orchestrate a continuous integration and continuous delivery (CI/CD) pipeline for ML models and applications.
Select and order the steps from the following list to describe a CI/CD process for a successful deployment.
Select each step one time. (Select and order FIVE.)
. CodePipeline deploys ML models and applications to production.
CodePipeline detects code changes and starts to build automatically.
. Human approval is provided after testing is successful.
. The company builds and deploys ML models and applications to staging servers for testing.
. The company commits code changes or new training datasets to a Git repository.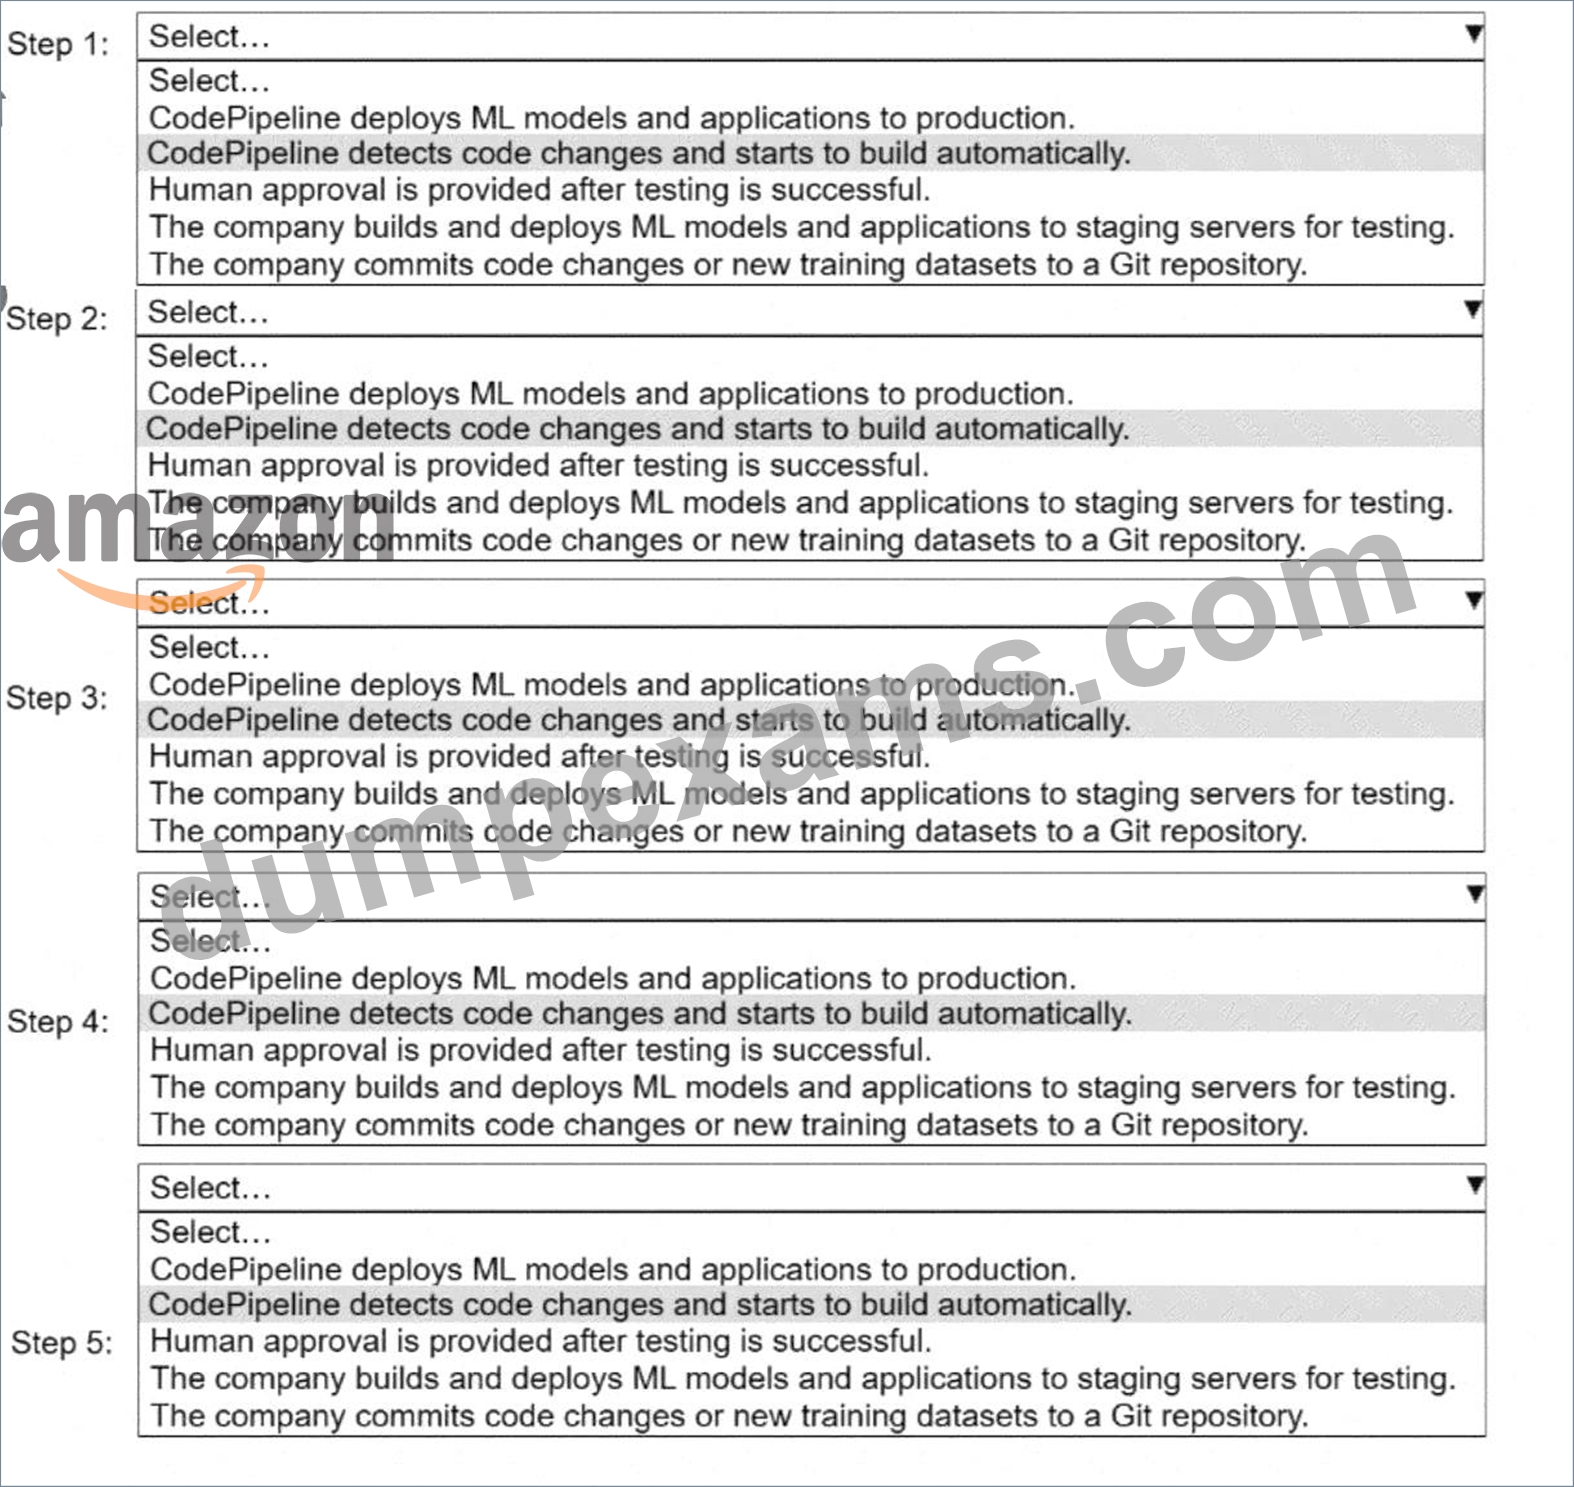
Answer:
Explanation: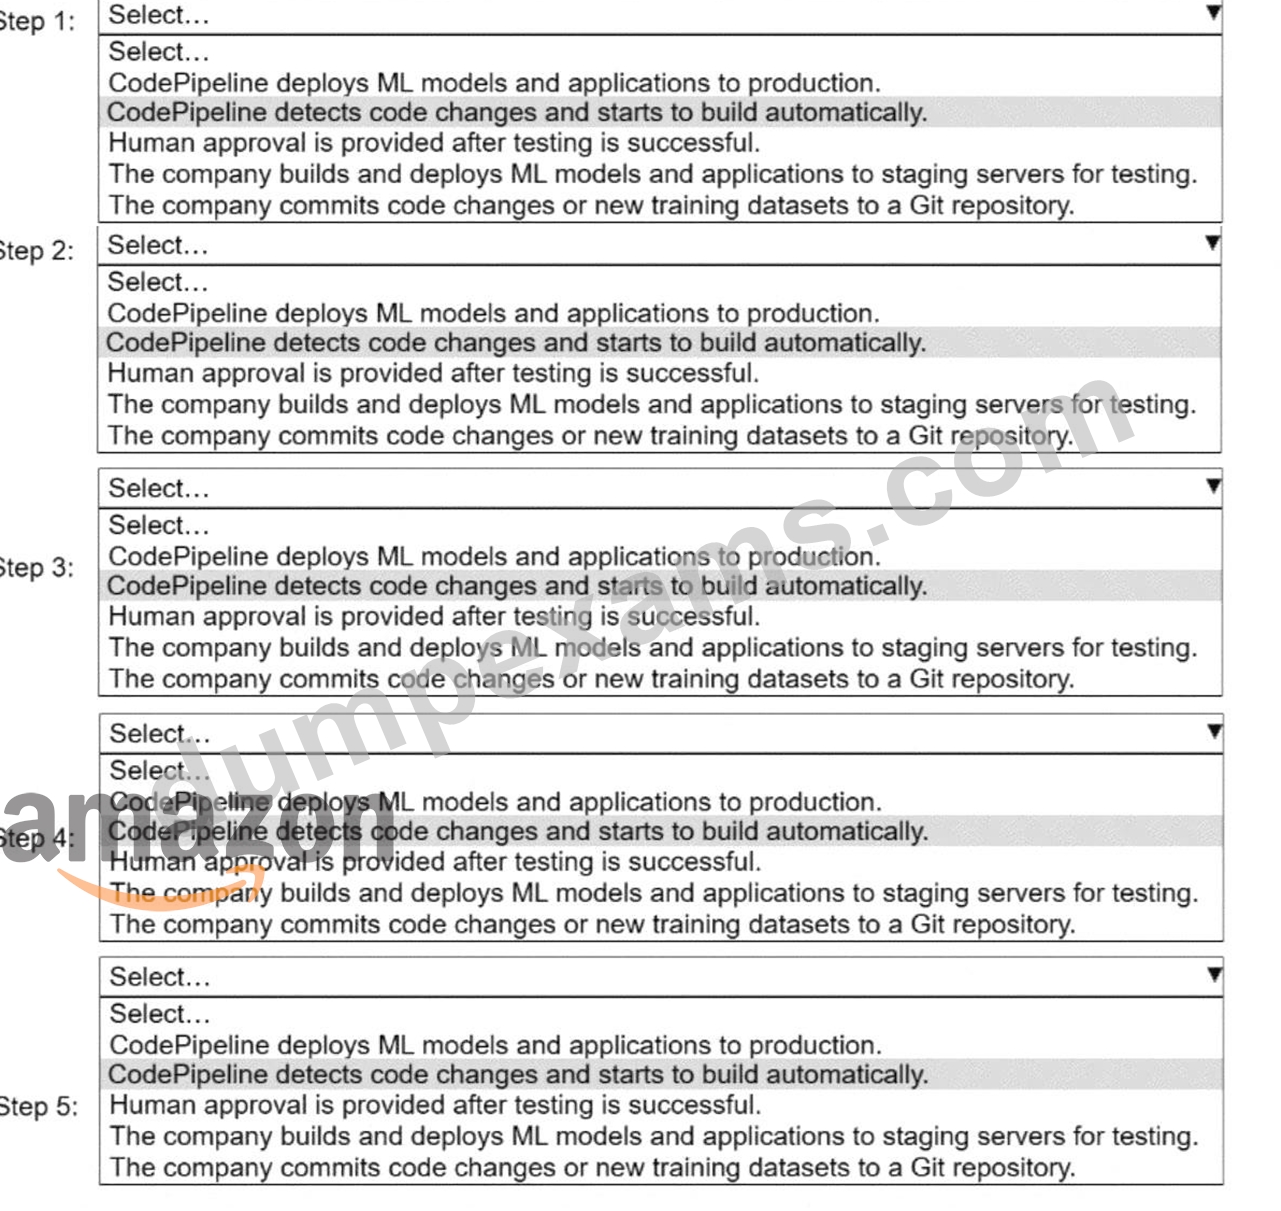
Explanation:
Step 1:
The company commits code changes or new training datasets to a Git repository.
This is the trigger point. A source code or data change initiates the CI/CD pipeline.
Step 2:
CodePipeline detects code changes and starts to build automatically.
CodePipeline monitors the Git repository (for example, AWS CodeCommit, GitHub, or Bitbucket) and automatically triggers the pipeline when changes are detected.
Step 3:
The company builds and deploys ML models and applications to staging servers for testing.
The pipeline runs build, training, and test stages (often using AWS CodeBuild and SageMaker) and deploys artifacts to a staging or test environment for validation.
Step 4:
Human approval is provided after testing is successful.
A manual approval action is a best practice for ML workflows to ensure governance, compliance, and quality checks before production deployment.
Step 5:
CodePipeline deploys ML models and applications to production.
After approval, the pipeline automatically deploys the validated model or application to the production environment.
NEW QUESTION # 13
A company needs to host a custom ML model to perform forecast analysis. The forecast analysis will occur with predictable and sustained load during the same 2-hour period every day.
Multiple invocations during the analysis period will require quick responses. The company needs AWS to manage the underlying infrastructure and any auto scaling activities.
Which solution will meet these requirements?
Answer: D
NEW QUESTION # 14
A company has built more than 50 models and deployed the models on Amazon SageMaker Al as real-time inference endpoints. The company needs to reduce the costs of the SageMaker Al inference endpoints. The company used the same ML framework to build the models. The company ' s customers require low-latency access to the models.
Select and order the correct steps from the following list to reduce the cost of inference and keep latency low.
Select each
step one time or not at all. (Select and order FIVE.)
Create an endpoint configuration that references a multi-model container.
. Create a SageMaker Al model with multi-model endpoints enabled.
. Deploy a real-time inference endpoint by using the endpoint configuration.
. Deploy a serverless inference endpoint configuration by using the endpoint configuration.
Spread the existing models to multiple different Amazon S3 bucket paths.
. Upload the existing models to the same Amazon S3 bucket path.
. Update the models to use the new endpoint ID. Pass the model IDs to the new endpoint.
Answer:
Explanation: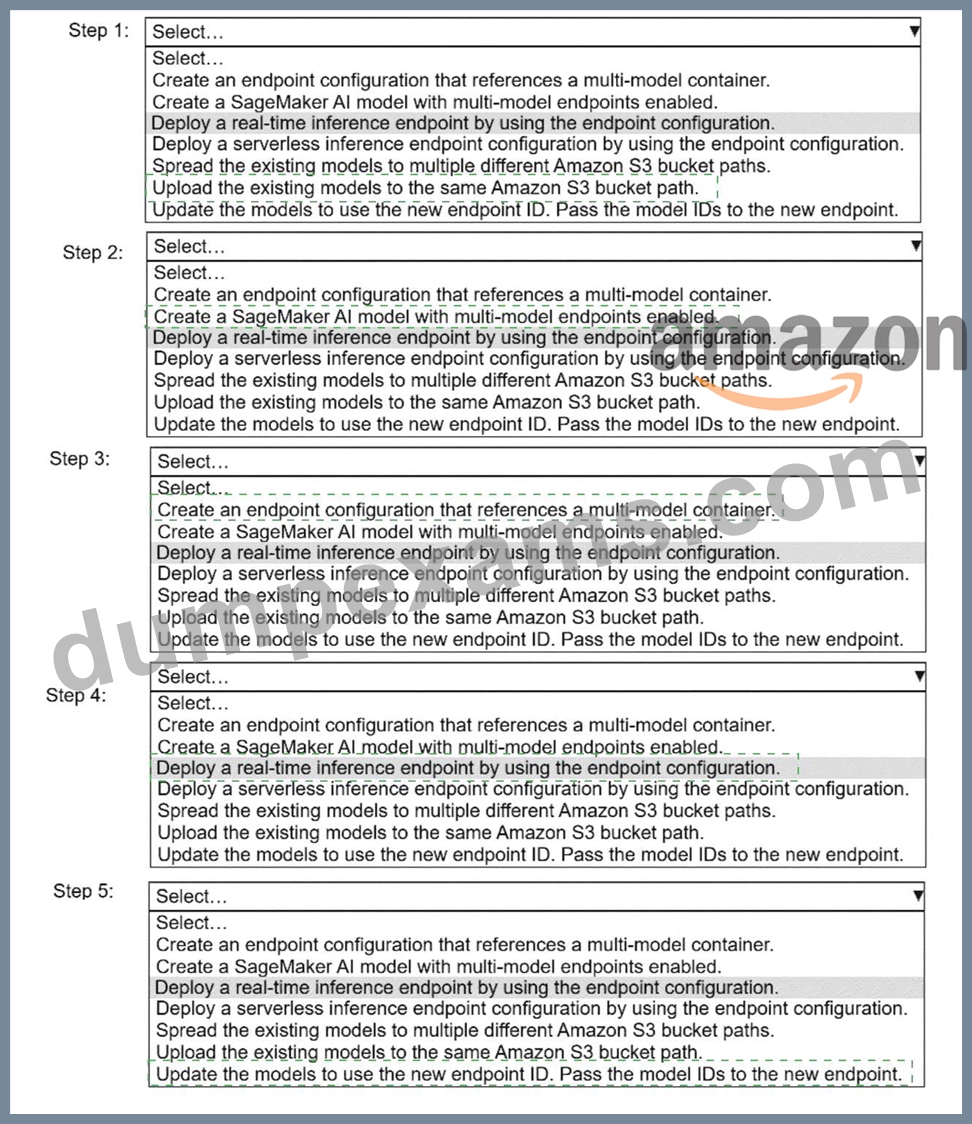
Explanation:
Step 1
Upload the existing models to the same Amazon S3 bucket path.
Multi-model endpoints require all models to be stored under a single S3 prefix so SageMaker can dynamically load them on demand.
Step 2
Create a SageMaker AI model with multi-model endpoints enabled.
This creates a SageMaker model resource that uses a multi-model-capable container (for example, XGBoost, PyTorch, or TensorFlow MME-compatible containers).
Step 3
Create an endpoint configuration that references a multi-model container.
The endpoint configuration defines:
Instance type
Initial instance count
The multi-model container reference
Step 4
Deploy a real-time inference endpoint by using the endpoint configuration.
Real-time endpoints ensure low-latency inference, which is a strict customer requirement.
Step 5
Update the models to use the new endpoint ID. Pass the model IDs to the new endpoint.
Each inference request specifies a model ID so SageMaker knows which model to load from S3.
NEW QUESTION # 15
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
The training dataset includes categorical data and numerical data. The ML engineer must prepare the training dataset to maximize the accuracy of the model.
Which action will meet this requirement with the LEAST operational overhead?
Answer: B
Explanation:
Preparing a training dataset that includes both categorical and numerical data is essential for maximizing the accuracy of a machine learning model. Transforming categorical data into numerical format is a critical step, as most ML algorithms require numerical input.
Why Transform Categorical Data into Numerical Data?
* Model Compatibility: Many ML algorithms cannot process categorical data directly and require numerical representations.
* Improved Performance: Proper encoding of categorical variables can enhance model accuracy and convergence speed.
Why Use Amazon SageMaker Data Wrangler?
Amazon SageMaker Data Wrangler offers a visual interface with over 300 built-in data transformations, including tools for encoding categorical variables.
Implementation Steps:
* Import Data:
* Load the dataset into SageMaker Data Wrangler from sources like Amazon S3 or on-premises databases.
* Identify Categorical Features:
* Use Data Wrangler's data type inference to detect categorical columns.
* Apply Categorical Encoding:
* Choose appropriate encoding techniques (e.g., one-hot encoding or ordinal encoding) from Data Wrangler's transformation options.
* Apply the selected transformation to convert categorical features into numerical format.
* Validate Transformations:
* Review the transformed dataset to ensure accuracy and completeness.
Advantages of Using SageMaker Data Wrangler:
* Ease of Use: Provides a user-friendly interface for data transformation without extensive coding.
* Operational Efficiency: Integrates data preparation steps, reducing the need for multiple tools and minimizing operational overhead.
* Flexibility: Supports various data sources and transformation techniques, accommodating diverse datasets.
By utilizing SageMaker Data Wrangler to transform categorical data into numerical format, the ML engineer can efficiently prepare the dataset, thereby enhancing the model's accuracy with minimal operational overhead.
Transform Data - Amazon SageMaker
Prepare ML Data with Amazon SageMaker Data Wrangler
NEW QUESTION # 16
......
Our company is a multinational company with sales and after-sale service of MLA-C01 exam torrent compiling departments throughout the world. In addition, our company has become the top-notch one in the fields, therefore, if you are preparing for the exam in order to get the related certification, then the AWS Certified Machine Learning Engineer - Associate exam question compiled by our company is your solid choice. We have always set great store by superior after sale service, since we all tend to take responsibility for our customers who decide to choose our MLA-C01 Training Materials. We pride ourselves on our industry-leading standards of customer care.
Free MLA-C01 Download: https://www.dumpexams.com/MLA-C01-real-answers.html
BONUS!!! Download part of Dumpexams MLA-C01 dumps for free: https://drive.google.com/open?id=1-XxU1qSzyfS7jwAaRokxqjFMiNiSVX3j