BONUS!!! Download part of RealVCE AI-500 dumps for free: https://drive.google.com/open?id=154pURJXgJYALsbRanvRQVg03Y0KWBXF7
Now we live in a highly competitive world. If you want to find a decent job and earn a high salary you must own excellent competences and rich knowledge. Under this circumstance, owning a AI-500 guide torrent is very important because it means you master good competences in certain areas and can handle the job well. The AI-500 Exam Prep we provide can help you realize your dream to pass AI-500 exam and then own a AI-500 exam torrent easily.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop multi-agent solutions in Azure | 30-35% | - Build and integrate tool ecosystems
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize prompt and model performance
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Topic 4: Architect multi-agent solutions | 15-20% | - Specify technology components for multi-agent solutions
|
>> Online Microsoft AI-500 Test <<
Highlight a person's learning effect is not enough, because it is difficult to grasp the difficulty of testing, a person cannot be effective information feedback, in order to solve this problem, our AI-500 real exam materials provide a powerful platform for users, allow users to exchange of experience. Here, the all users of our AI-500 learning reference files can through own id to login to the platform, realize the exchange and sharing with other users, even on the platform and more users to become good friends, encourage each other, to deal with the difficulties encountered in the process of preparation each other. Our AI-500 learning reference files not only provide a single learning environment for users, but also create a learning atmosphere like home, where you can learn and communicate easily.
NEW QUESTION # 21
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.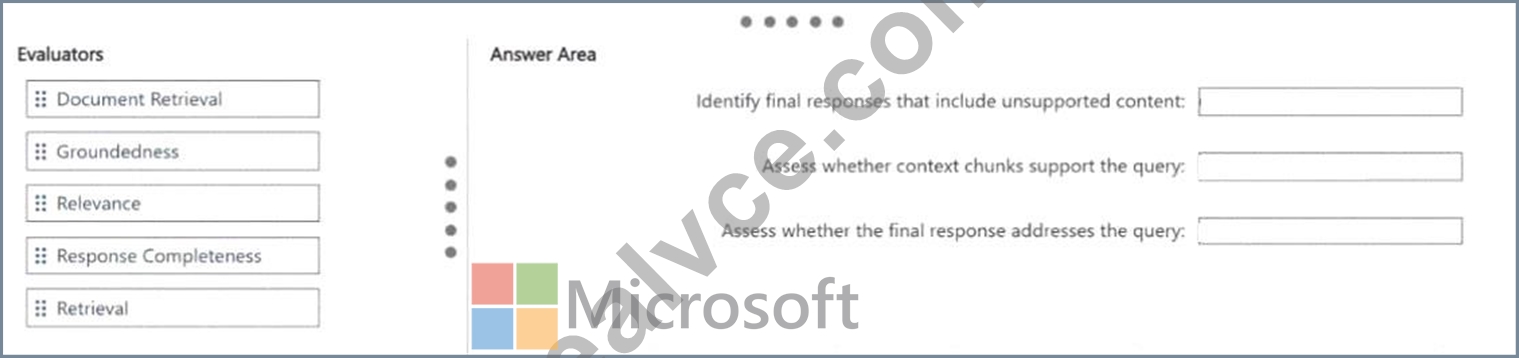
Answer:
Explanation: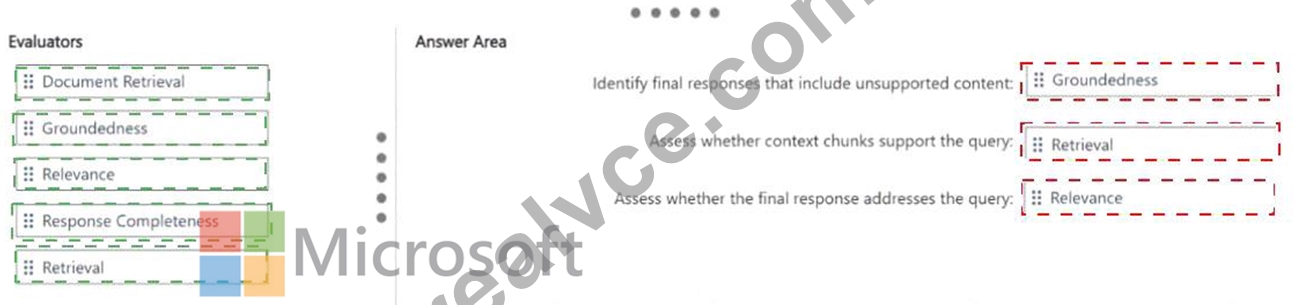
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators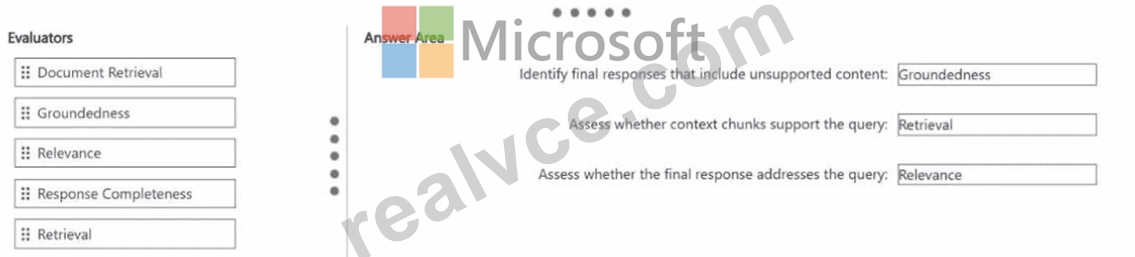
NEW QUESTION # 22
You have a LangGraph multi-agent workflow that uses Azure Cosmos DB as a checkpointer.
You plan to change the pruning rules for the running message list before the next release You need to implement evaluations tor memory. The solution must meet the following requirements:
* Verify that claim-related state values remain correct at transition points.
* Verify that conversation context is preserved after an interruption.
* Identify the source of any loss of continuity during a run
Which three actions should you perform Each correct answer presents part of the solution NOTE: Each correct selection is worth one point.
Answer: A,D,E
Explanation:
Memory evaluation must verify persistence across interruption, correctness of checkpointed state, and enough telemetry to locate where continuity was lost. Running a scripted multi-turn case with one stable `thread_id` before and after a restart directly tests whether the Cosmos-backed LangGraph checkpointer restores the same conversation/workflow. Comparing persisted checkpoint documents with expected state values at each handoff verifies that claim-related state has not been corrupted by the new pruning rules. Correlating the evaluation run with trace spans then provides the diagnostic path to identify which agent transition or state- management operation caused a failure. Changing the thread ID each turn would intentionally create separate state scopes, and removing durable artifacts would defeat the persistence test. Tool-call arguments alone do not prove workflow-memory continuity. Therefore D, E, and F are the complementary actions required. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Azure Cosmos DB integrations for LangGraph and agent state
NEW QUESTION # 23
You have a Microsoft Foundry multi-agent solution that uses Microsoft Agent Framework and LangGraph.
Telemetry from the workload is sent to Application Insights.
You need to implement observability components to meet the following requirements:
* Support the investigation of user interactions across agents, models, tools, functions, and API boundaries without relying on verbose production logs.
* Produce recurring and comparable measurements of deployed response quality and safety over time.
What should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.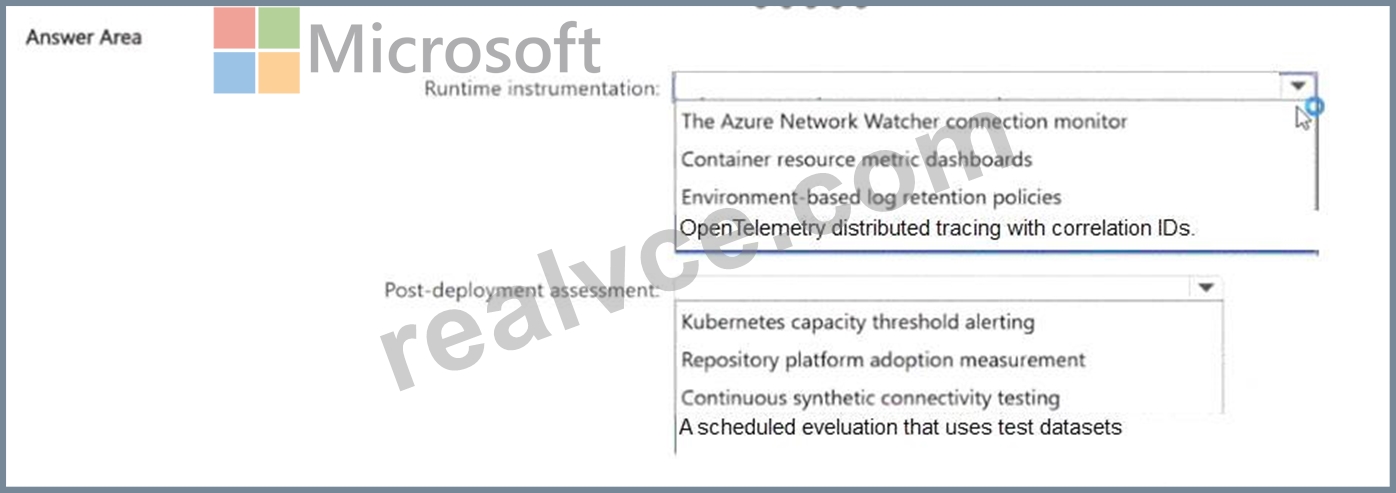
Answer:
Explanation: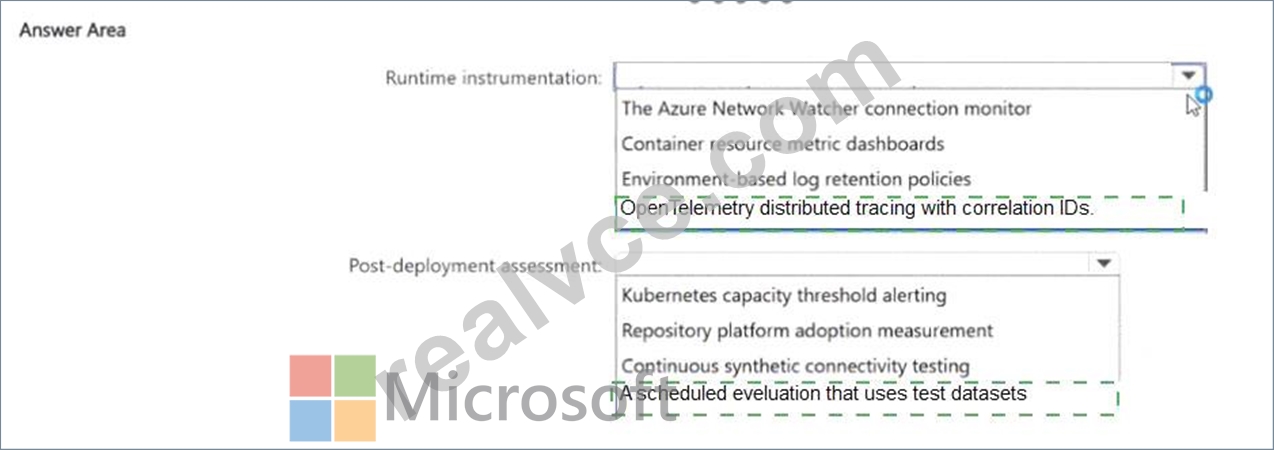
Explanation:
Runtime instrumentation: OpenTelemetry distributed tracing with correlation IDs; Post-deployment assessment: A scheduled evaluation that uses test datasets.
Distributed tracing is the correct runtime mechanism because the objective is to reconstruct a user interaction across agents, models, tools, functions, and API boundaries without relying on verbose log text. Microsoft Foundry uses OpenTelemetry-compatible traces and Application Insights so related spans can be correlated into one execution path. Correlation identifiers allow operators to isolate one conversation and inspect where latency, failures, or unexpected behavior originated. The second requirement is different: it asks for recurring, comparable measurements of deployed response quality and safety. Scheduled evaluations against stable test datasets provide that longitudinal benchmark and are more appropriate than ad hoc tracing or infrastructure- only dashboards. Together, OpenTelemetry answers "what happened in this run?" while scheduled evaluation answers "is behavior getting better or worse over time?" The selected pair therefore covers both operational diagnosis and quality regression monitoring. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry observability concepts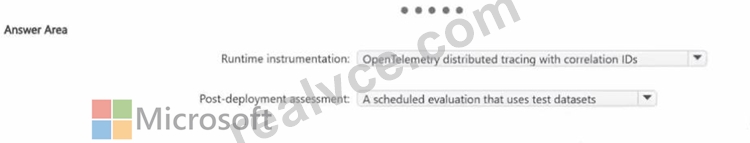
NEW QUESTION # 24
You have a Microsoft Foundry multi-agent solution.
Historical chat logs are limited and include customer Personally Identifiable Information (Pll).
The agents frequently produce invalid arguments when they call APIs by using structured function calls.
You need to create an initial fine-tuning dataset to improve the API-call behavior. The solution must minimize privacy exposure.
How should you configure the pipeline? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.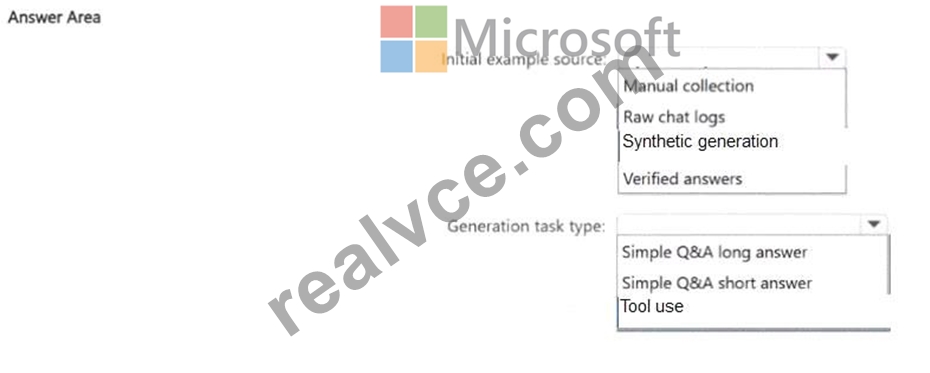
Answer:
Explanation: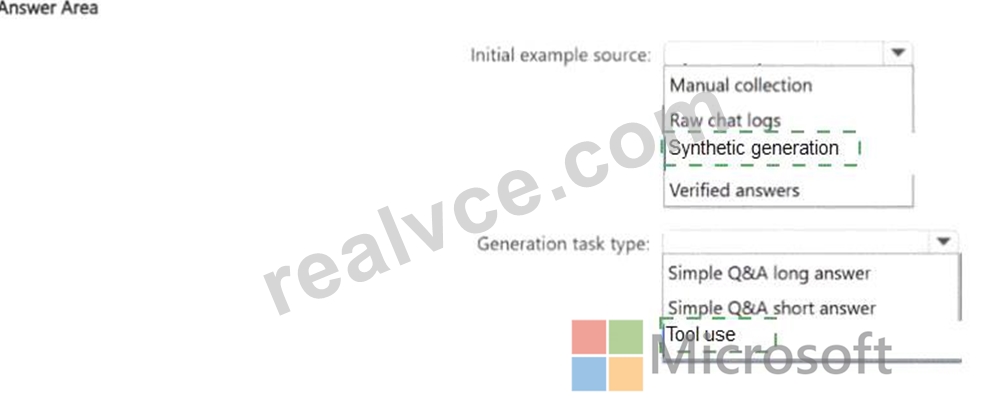
Explanation:
Initial example source: Synthetic generation; Generation task type: Tool use.
The historical chat logs are both sparse and privacy-sensitive, so using them directly as the initial fine-tuning corpus creates unnecessary PII exposure. Microsoft Foundry synthetic-data generation is intended to create diverse training examples when production data is limited and can avoid carrying customer identifiers into the dataset. The specific behavior that needs improvement is structured API/function calling, so the generator should use the Tool use task type. Tool-use generation can use an API/OpenAPI definition to create conversations that include valid tool selection and parameter construction, which directly trains the failure mode described. A general Q & A generator would not systematically teach function-call schemas. Therefore Synthetic generation plus Tool use is the configuration that both targets invalid arguments and minimizes privacy exposure. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Foundry - synthetic fine-tuning data generation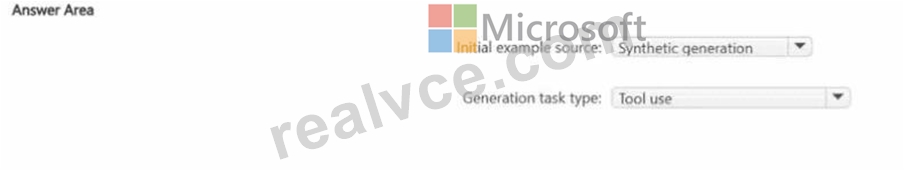
NEW QUESTION # 25
You have a Microsoft Foundry multi-agent solution that routes requests from an intake agent to a retrieval agent, and then to a resolution agent. The retrieval agent uses a knowledge search tool.
Security testing reveals the following recurring issues:
* Some users submit jailbreak-style prompts at the start of a conversation.
* Some retrieved documents contain hidden instructions intended to manipulate the downstream agent The legal department at your company requires that final responses be flagged for review if they contain protected text. You need to configure guardrails to resolve the security issues and meet the legal requirements.
What should you configure?
Answer: A
Explanation:
The three risks occur at three different intervention points. Direct jailbreak attempts originate in the user prompt, so User input attacks should be evaluated at the User input boundary and blocked. Malicious instructions embedded in retrieved documents are indirect prompt-injection attacks and belong at the Tool response boundary before the retrieved content can influence downstream reasoning. Protected material in the final response must be flagged for legal review, not necessarily blocked, so an Output control using annotate- only behavior matches the requirement. Options A and B misplace at least one control or block content that the scenario says should only be flagged. Microsoft Foundry guardrails are explicitly designed around these intervention points, making C the configuration that aligns each risk with the stage where it can be detected and acted upon. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry guardrails - intervention points
NEW QUESTION # 26
......
You may be also one of them, you may still struggling to find a high quality and high pass rate AI-500 study question to prepare for your exam. Our product is elaborately composed with major questions and answers. Our study materials are choosing the key from past materials to finish our AI-500 Torrent prep. It only takes you 20 hours to 30 hours to do the practice. After your effective practice, you can master the examination point from the AI-500 exam torrent. Then, you will have enough confidence to pass it. So start with our AI-500 torrent prep from now on.
AI-500 Valid Braindumps Sheet: https://www.realvce.com/AI-500_free-dumps.html
What's more, part of that RealVCE AI-500 dumps now are free: https://drive.google.com/open?id=154pURJXgJYALsbRanvRQVg03Y0KWBXF7