Individuals who pass the Operationalizing Machine Learning and Generative AI Solutions (AI-300) certification exam demonstrate to their employers and clients that they have the knowledge and skills necessary to succeed in the industry. TroytecDumps is aware that preparing with outdated Operationalizing Machine Learning and Generative AI Solutions (AI-300) study material results in a loss of time and money.
| Section | Weight | Objectives |
|---|---|---|
| Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
| Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
>> Exam Dumps AI-300 Provider <<
In addition to the advantages of high quality, our AI-300 exam questions also provide various versions. In order to meet your personal habits, you can freely choose any version of our AI-300 study materials within PDF, APP or PC version. Among them, the PDF version is most suitable for candidates who prefer paper materials, because it supports printing. And our PDF version of the AI-300 training guide can be carried with you for it takes on place.
NEW QUESTION # 114
You manage an Azure Machine Learning workspace.
You need to define an environment from a Docker image by using the Azure Machine Learning Python SDK v2.
Which parameter should you use?
Answer: B
Explanation:
The correct parameter is image . In Azure Machine Learning Python SDK v2, the Environment entity supports defining an execution environment directly from an existing Docker image by specifying the image URI through the image parameter . Microsoft provides the explicit SDK v2 pattern:
Environment(image= " pytorch/pytorch:latest " , ...)
The resulting environment can then be registered by using ml_client.environments.create_or_update().
The image value can reference an image hosted in a supported container registry such as Docker Hub or Azure Container Registry. Azure Machine Learning then uses that image as the container environment for training or deployment workloads.
build is different: it is used when Azure Machine Learning must build a Docker image from a Docker build context , typically a directory containing a Dockerfile and related files. Microsoft specifies that image and build represent alternative environment-definition approaches.
conda_file specifies Python and Conda dependencies layered on top of a base Docker image; it does not identify the Docker image itself. properties stores arbitrary metadata and cannot define the execution container.
Therefore, to create an SDK v2 environment directly from an existing Docker image, use image .
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning environments, Python SDK v2, Docker images, reusable execution environments, and dependency management.
NEW QUESTION # 115
Hotspot Question
You are reviewing a dataset that will be used for an advanced fine-tuning job in Microsoft Foundry.
The fine-tuning job uses preference comparison data.
You review the following dataset excerpt.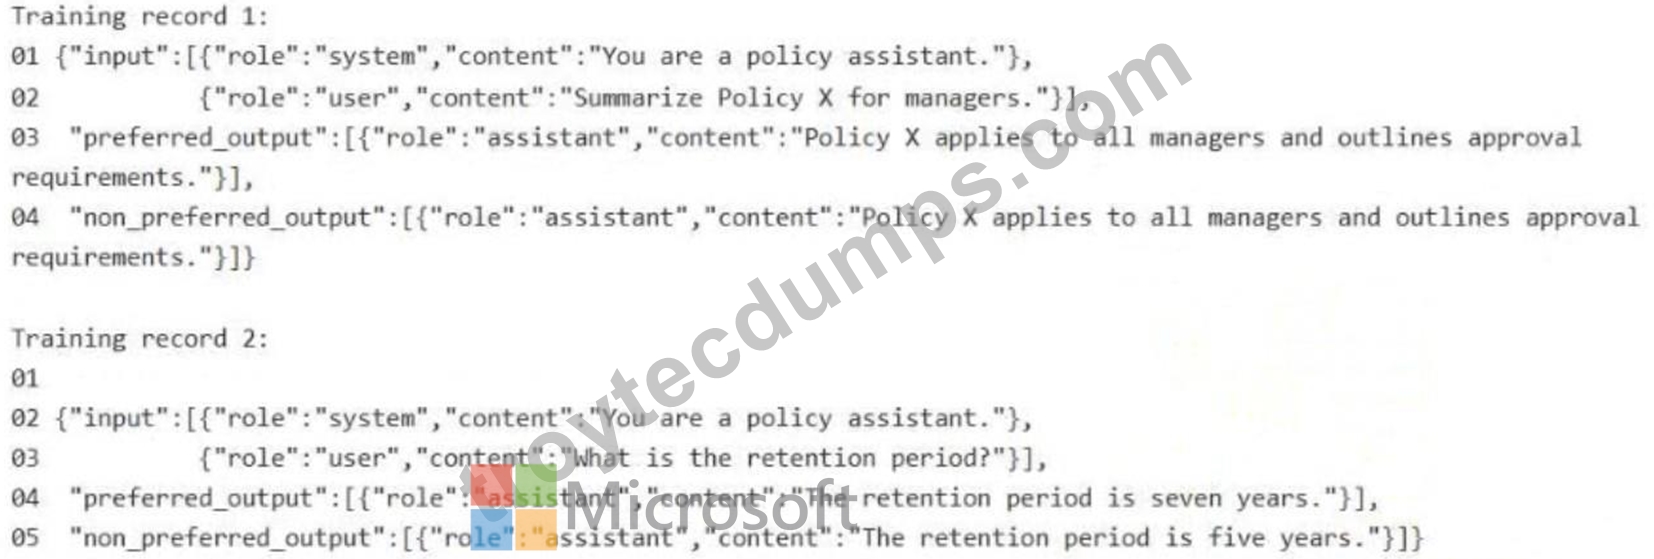
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.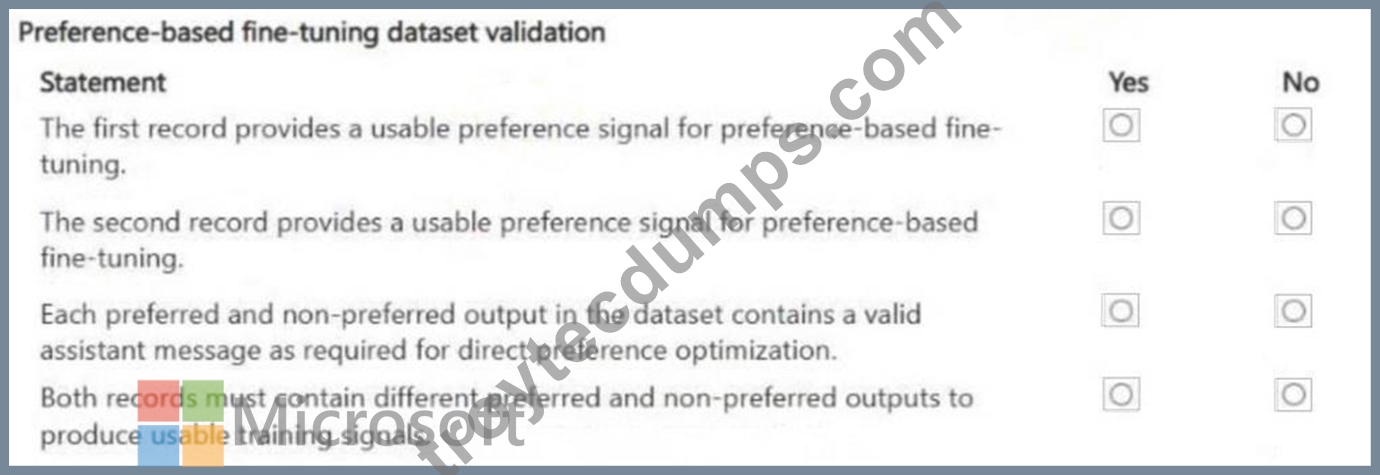
Answer:
Explanation: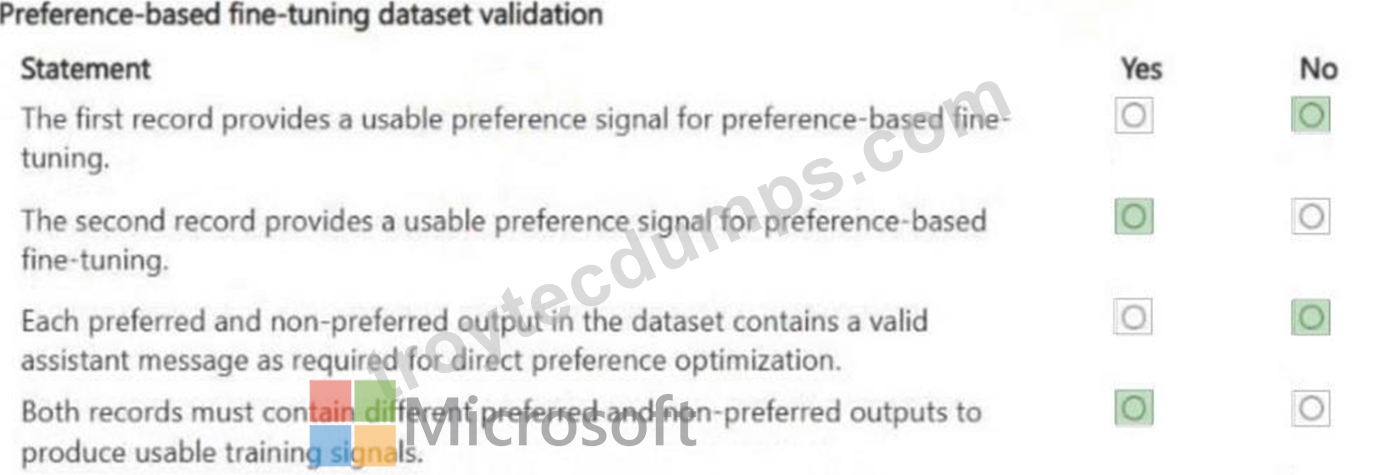
NEW QUESTION # 116
You manage an Azure Machine Learning workspace. You create an experiment named experiment1 by using the Azure Machine Learning Python SDK v2 and MLflow.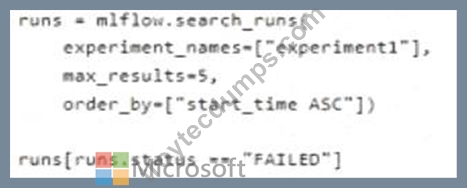
For each of the following statements, select Yes if the statement is true. Otherwise, select No.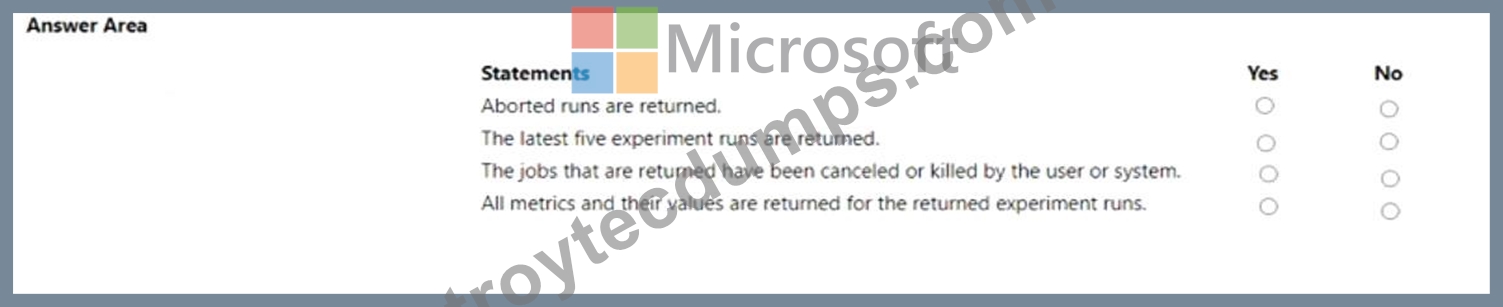
Answer:
Explanation: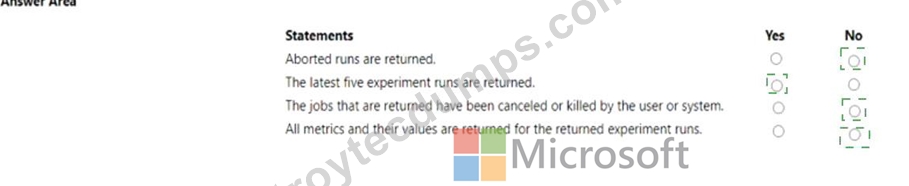
Explanation: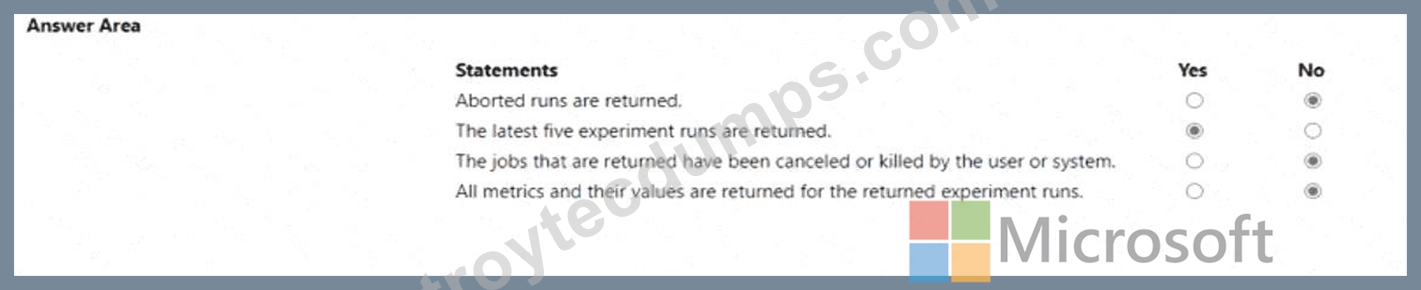
NEW QUESTION # 117
You need to standardize how Fabrikam Inc. manages machine learning assets.
Which action should you perform first?
Answer: C
Explanation:
In Azure Machine Learning, a workspace is the top-level resource that acts as a centralized hub for every ML activity. It stores experiments, pipelines, datasets, models, environments, and compute targets all in one place.
Before you can register assets or deploy endpoints, the workspace itself must exist and be shared across the team. Fabrikam ' s core challenge is inconsistent experiment tracking, ad-hoc versioning, and no standardized deployment path - all symptoms of the absence of a single, governed workspace. Option A (registering assets) is a subsequent action only possible after the workspace exists. Option C (online endpoint) is a deployment concern, not an asset-management foundation. Option D (Foundry project) is appropriate for generative AI workloads, not for the traditional ML pipeline standardization described here. The workspace is the prerequisite that makes every other governance action possible.
Microsoft Learn Reference Topic: Azure Machine Learning workspaces - Microsoft Learn: Manage Azure Machine Learning workspaces
NEW QUESTION # 118
You create an Azure Machine Learning workspace.
You must use the Python SDK v2 to implement an experiment from a Jupyter notebook in the workspace. The experiment must log a list of numerical metrics.
You need to implement a method to log a list of numerical metrics.
Which method should you use?
Answer: D
Explanation:
For Azure Machine Learning SDK v2, Microsoft recommends MLflow Tracking for experiment logging.
When a requirement specifically calls for logging a list of numerical metric values , the appropriate operation is log_batch() . Microsoft provides an explicit SDK v2 migration example in which a list of numeric values is converted into MLflow Metric objects and submitted through MlflowClient().log_batch().
Technically, the concrete Python implementation uses the tracking client:
MlflowClient().log_batch(run_id, metrics=metrics)
where metrics contains a sequence of Metric objects representing the numerical values. Microsoft likewise documents batch metric logging as preferable when multiple metrics or multiple values of the same metric need to be recorded efficiently.
mlflow.log_metric() records an individual numeric metric value. It can be invoked repeatedly, but Microsoft specifically demonstrates log_batch() for a curve or list of numeric values . mlflow.log_artifact() stores files and other artifacts rather than numerical tracking metrics, while mlflow.log_image() is intended for images and therefore does not satisfy the requirement.
Therefore, A is the intended answer. In actual Python SDK v2 code, this operation is normally invoked as MlflowClient().log_batch() .
Study Guide Reference: Implement machine learning model lifecycle and operations - Azure Machine Learning experiments, MLflow tracking, metric logging, experiment observability, and SDK v2 migration.
NEW QUESTION # 119
......
If you buy our AI-300 study tool successfully, you will have the right to download our AI-300 exam torrent in several minutes, and then you just need to click on the link and log on to your website’s forum, you can start to learn our AI-300 question torrent. We believe the operation is very convenient for you, and you can operate it quickly. At the same time, we believe that the convenient purchase process will help you save much time. More importantly, we provide all people with the trial demo for free before you buy our AI-300 Exam Torrent and it means that you have the chance to download from our web page for free; you do not need to spend any money.
Discount AI-300 Code: https://www.troytecdumps.com/AI-300-troytec-exam-dumps.html