BONUS!!! Download part of Lead2PassExam Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1VGiRV-Aq545XFFL6AmaY-ZRUKJ9ck-Gp
There may be a lot of people feel that the preparation process for exams is hard and boring, and hard work does not necessarily mean good results, which is an important reason why many people are afraid of examinations. Today, our Data-Engineer-Associate exam materials will radically change this. High question hit rate makes you no longer aimless when preparing for the exam, so you just should review according to the content of our Data-Engineer-Associate Study Guide prepared for you. Instant answer feedback allows you to identify your vulnerabilities in a timely manner, so as to make up for your weaknesses. With our Data-Engineer-Associate practice quiz, you will find that the preparation process is not only relaxed and joyful, but also greatly improves the probability of passing the exam.
| Section | Weight | Objectives |
|---|---|---|
| Data Security and Governance | 18% | - Manage data privacy and compliance
|
| Data Operations and Support | 22% | - Manage and troubleshoot data processes
|
| Data Store Management | 26% | - Design data models
|
| Data Ingestion and Transformation | 34% | - Transform and process data
|
>> Data-Engineer-Associate Key Concepts <<
Getting a Amazon Data-Engineer-Associate trusted certification is a way to prove your expertise and show you that you are ready all the time to take the additional responsibilities. The Lead2PassExam Data-Engineer-Associate certification exam assists you to climb the corporate ladder easily and helps you to achieve your professional career objectives. With the Lead2PassExam Data-Engineer-Associate Certification Exam you can get industry prestige and a significant competitive advantage.
NEW QUESTION # 253
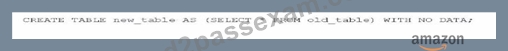
A data engineer needs to create a new empty table in Amazon Athena that has the same schema as an existing table named old-table.
Which SQL statement should the data engineer use to meet this requirement?



Answer: C
Explanation:
* Problem Analysis:
* The goal is to create anew empty tablein Athena with the same schema as an existing table (old_table).
* The solution must avoid copying any data.
* Key Considerations:
* CREATE TABLE AS (CTAS)is commonly used in Athena for creating new tables based on an existing table.
* Adding the WITH NO DATA clause ensures only the schema is copied, without transferring any data.
* Solution Analysis:
* Option A: Copies both schema and data. Does not meet the requirement for an empty table.
* Option B: Inserts data into an existing table, which does not create a new table.
* Option C: Creates an empty table but does not copy the schema.
* Option D: Creates a new table with the same schema and ensures it is empty by using WITH NO DATA.
* Final Recommendation:
* UseD. CREATE TABLE new_table AS (SELECT * FROM old_table) WITH NO DATAto create an empty table with the same schema.
:
Athena CTAS Queries
CREATE TABLE Statement in Athena
NEW QUESTION # 254
A company stores data from an application in an Amazon DynamoDB table that operates in provisioned capacity mode. The workloads of the application have predictable throughput load on a regular schedule.
Every Monday, there is an immediate increase in activity early in the morning. The application has very low usage during weekends.
The company must ensure that the application performs consistently during peak usage times.
Which solution will meet these requirements in the MOST cost-effective way?
Answer: B
Explanation:
Amazon DynamoDB is a fully managed NoSQL database service that provides fast and predictable performance with seamless scalability. DynamoDB offers two capacity modes for throughput capacity:
provisioned and on-demand. In provisioned capacity mode, you specify the number of read and write capacity units per second that you expect your application to require. DynamoDB reserves the resources to meet your throughput needs with consistent performance. In on-demand capacity mode, you pay per request and DynamoDB scales the resources up and down automatically based on the actual workload. On-demand capacity mode is suitable for unpredictable workloads that can vary significantly over time1.
The solution that meets the requirements in the most cost-effective way is to use AWS Application Auto Scaling to schedule higher provisioned capacity for peak usage times and lower capacity during off-peak times. This solution has the following advantages:
It allows you to optimize the cost and performance of your DynamoDB table by adjusting the provisioned capacity according to your predictable workload patterns. You can use scheduled scaling to specify the date and time for the scaling actions, and the new minimum and maximum capacity limits. For example, you can schedule higher capacity for every Monday morning and lower capacity for weekends2.
It enables you to take advantage of the lower cost per unit of provisioned capacity mode compared to on- demand capacity mode. Provisioned capacity mode charges a flat hourly rate for the capacity you reserve, regardless of how much you use. On-demand capacity mode charges for each read and write request you consume, with no minimum capacity required. For predictable workloads, provisioned capacity mode can be more cost-effective than on-demand capacity mode1.
It ensures that your application performs consistently during peak usage times by having enough capacity to handle the increased load. You can also use auto scaling to automatically adjust the provisioned capacity based on the actual utilization of your table, and set a target utilization percentage for your table or global secondary index. This way, you can avoid under-provisioning or over-provisioning your table2.
Option A is incorrect because it suggests increasing the provisioned capacity to the maximum capacity that is currently present during peak load times. This solution has the following disadvantages:
It wastes money by paying for unused capacity during off-peak times. If you provision the same high capacity for all times, regardless of the actual workload, you are over-provisioning your table and paying for resources that you don't need1.
It does not account for possible changes in the workload patterns over time. If your peak load times increase or decrease in the future, you may need to manually adjust the provisioned capacity to match the new demand. This adds operational overhead and complexity to your application2.
Option B is incorrect because it suggests dividing the table into two tables and provisioning each table with half of the provisioned capacity of the original table. This solution has the following disadvantages:
It complicates the data model and the application logic by splitting the data into two separate tables. You need to ensure that the queries are evenly distributed across both tables, and that the data is consistent and synchronized between them. This adds extra development and maintenance effort to your application3.
It does not solve the problem of adjusting the provisioned capacity according to the workload patterns. You still need to manually or automatically scale the capacity of each table based on the actual utilization and demand. This may result in under-provisioning or over-provisioning your tables2.
Option D is incorrect because it suggests changing the capacity mode from provisioned to on-demand. This solution has the following disadvantages:
It may incur higher costs than provisioned capacity mode for predictable workloads. On-demand capacity mode charges for each read and write request you consume, with no minimum capacity required. For predictable workloads, provisioned capacity mode can be more cost-effective than on-demand capacity mode, as you can reserve the capacity you need at a lower rate1.
It may not provide consistent performance during peak usage times, as on-demand capacity mode may take some time to scale up the resources to meet the sudden increase in demand. On-demand capacity mode uses adaptive capacity to handle bursts of traffic, but it may not be able to handle very large spikes or sustained high throughput. In such cases, you may experience throttling or increased latency.
1: Choosing the right DynamoDB capacity mode - Amazon DynamoDB
2: Managing throughput capacity automatically with DynamoDB auto scaling - Amazon DynamoDB
3: Best practices for designing and using partition keys effectively - Amazon DynamoDB
[4]: On-demand mode guidelines - Amazon DynamoDB
[5]: How to optimize Amazon DynamoDB costs - AWS Database Blog
[6]: DynamoDB adaptive capacity: How it works and how it helps - AWS Database Blog
[7]: Amazon DynamoDB pricing - Amazon Web Services (AWS)
NEW QUESTION # 255
A data engineer needs to use AWS Step Functions to design an orchestration workflow. The workflow must parallel process a large collection of data files and apply a specific transformation to each file.
Which Step Functions state should the data engineer use to meet these requirements?
Answer: D
Explanation:
Option C is the correct answer because the Map state is designed to process a collection of data in parallel by applying the same transformation to each element. The Map state can invoke a nested workflow for each element, which can be another state machine ora Lambda function. The Map state will wait until all the parallel executions are completed before moving to the next state.
Option A is incorrect because the Parallel state is used to execute multiple branches of logic concurrently, not to process a collection of data. The Parallel state can have different branches with different logic and states, whereas the Map state has only one branch that is applied to each element of the collection.
Option B is incorrect because the Choice state is used to make decisions based on a comparison of a value to a set of rules. The Choice state does not process any data or invoke any nested workflows.
Option D is incorrect because the Wait state is used to delay the state machine from continuing for a specified time. The Wait state does not process any data or invoke any nested workflows.
References:
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 5: Data Orchestration, Section 5.3: AWS Step Functions, Pages 131-132 Building Batch Data Analytics Solutions on AWS, Module 5: Data Orchestration, Lesson 5.2: AWS Step Functions, Pages 9-10 AWS Documentation Overview, AWS Step Functions Developer Guide, Step Functions Concepts, State Types, Map State, Pages 1-3
NEW QUESTION # 256
A manufacturing company wants to collect data from sensors. A data engineer needs to implement a solution that ingests sensor data in near real time.
The solution must store the data to a persistent data store. The solution must store the data in nested JSON format. The company must have the ability to query from the data store with a latency of less than 10 milliseconds.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: B
Explanation:
Amazon Kinesis Data Streams is a service that enables you to collect, process, and analyze streaming data in real time. You can use Kinesis Data Streams to capture sensor data from various sources, such as IoT devices, web applications, or mobile apps. You can create data streams that can scale up to handle any amount of data from thousands of producers. You can also use the Kinesis Client Library (KCL) or the Kinesis Data Streams API to write applications that process and analyze the data in the streams1.
Amazon DynamoDB is a fully managed NoSQL database service that provides fast and predictable performance with seamless scalability. You can use DynamoDB to store the sensor data in nested JSON format, as DynamoDB supports document data types, such as lists and maps. You can also use DynamoDB to query the data with a latency of less than 10 milliseconds, as DynamoDB offers single-digit millisecond performance for any scale of data. You can use the DynamoDB API or the AWS SDKs to perform queries on the data, such as using key-value lookups, scans, or queries2.
The solution that meets the requirements with the least operational overhead is to use Amazon Kinesis Data Streams to capture the sensor data and store the data in Amazon DynamoDB for querying. This solution has the following advantages:
It does not require you to provision, manage, or scale any servers, clusters, or queues, as Kinesis Data Streams and DynamoDB are fully managed services that handle all the infrastructure for you. This reduces the operational complexity and cost of running your solution.
It allows you to ingest sensor data in near real time, as Kinesis Data Streams can capture data records as they are produced and deliver them to your applications within seconds. You can also use Kinesis Data Firehose to load the data from the streams to DynamoDB automatically and continuously3.
It allows you to store the data in nested JSON format, as DynamoDB supports document data types, such as lists and maps. You can also use DynamoDB Streams to capture changes in the data and trigger actions, such as sending notifications or updating other databases.
It allows you to query the data with a latency of less than 10 milliseconds, as DynamoDB offers single-digit millisecond performance for any scale of data. You can also use DynamoDB Accelerator (DAX) to improve the read performance by caching frequently accessed data.
Option A is incorrect because it suggests using a self-hosted Apache Kafka cluster to capture the sensor data and store the data in Amazon S3 for querying. This solution has the following disadvantages:
It requires you to provision, manage, and scale your own Kafka cluster, either on EC2 instances or on-premises servers. This increases the operational complexity and cost of running your solution.
It does not allow you to query the data with a latency of less than 10 milliseconds, as Amazon S3 is an object storage service that is not optimized for low-latency queries. You need to use another service, such as Amazon Athena or Amazon Redshift Spectrum, to query the data in S3, which may incur additional costs and latency.
Option B is incorrect because it suggests using AWS Lambda to process the sensor data and store the data in Amazon S3 for querying. This solution has the following disadvantages:
It does not allow you to ingest sensor data in near real time, as Lambda is a serverless compute service that runs code in response to events. You need to use another service, such as API Gateway or Kinesis Data Streams, to trigger Lambda functions with sensor data, which may add extra latency and complexity to your solution.
It does not allow you to query the data with a latency of less than 10 milliseconds, as Amazon S3 is an object storage service that is not optimized for low-latency queries. You need to use another service, such as Amazon Athena or Amazon Redshift Spectrum, to query the data in S3, which may incur additional costs and latency.
Option D is incorrect because it suggests using Amazon Simple Queue Service (Amazon SQS) to buffer incoming sensor data and use AWS Glue to store the data in Amazon RDS for querying. This solution has the following disadvantages:
It does not allow you to ingest sensor data in near real time, as Amazon SQS is a message queue service that delivers messages in a best-effort manner. You need to use another service, such as Lambda or EC2, to poll the messages from the queue and process them, which may add extra latency and complexity to your solution.
It does not allow you to store the data in nested JSON format, as Amazon RDS is a relational database service that supports structured data types, such as tables and columns. You need to use another service, such as AWS Glue, to transform the data from JSON to relational format, which may add extra cost and overhead to your solution.
Reference:
1: Amazon Kinesis Data Streams - Features
2: Amazon DynamoDB - Features
3: Loading Streaming Data into Amazon DynamoDB - Amazon Kinesis Data Firehose
[4]: Capturing Table Activity with DynamoDB Streams - Amazon DynamoDB
[5]: Amazon DynamoDB Accelerator (DAX) - Features
[6]: Amazon S3 - Features
[7]: AWS Lambda - Features
[8]: Amazon Simple Queue Service - Features
[9]: Amazon Relational Database Service - Features
[10]: Working with JSON in Amazon RDS - Amazon Relational Database Service
[11]: AWS Glue - Features
NEW QUESTION # 257
A company stores server logs in an Amazon 53 bucket. The company needs to keep the logs for 1 year. The logs are not required after 1 year.
A data engineer needs a solution to automatically delete logs that are older than 1 year.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: D
Explanation:
Problem Analysis:
The company uses AWS Glue for ETL pipelines and requires automatic data quality checks during pipeline execution.
The solution must integrate with existing AWS Glue pipelines and evaluate data quality rules based on predefined thresholds.
Key Considerations:
Ensure minimal implementation effort by leveraging built-in AWS Glue features.
Use a standardized approach for defining and evaluating data quality rules.
Avoid custom libraries or external frameworks unless absolutely necessary.
Solution Analysis:
Option A: SQL Transform
Adding SQL transforms to define and evaluate data quality rules is possible but requires writing complex queries for each rule.
Increases operational overhead and deviates from Glue's declarative approach.
Option B: Evaluate Data Quality Transform with DQDL
AWS Glue provides a built-in Evaluate Data Quality transform.
Allows defining rules in Data Quality Definition Language (DQDL), a concise and declarative way to define quality checks.
Fully integrated with Glue Studio, making it the least effort solution.
Option C: Custom Transform with PyDeequ
PyDeequ is a powerful library for data quality checks but requires custom code and integration.
Increases implementation effort compared to Glue's native capabilities.
Option D: Custom Transform with Great Expectations
Great Expectations is another powerful library for data quality but adds complexity and external dependencies.
Final Recommendation:
Use Evaluate Data Quality transform in AWS Glue.
Define rules in DQDL for checking thresholds, null values, or other quality criteria.
This approach minimizes development effort and ensures seamless integration with AWS Glue.
Reference:
AWS Glue Data Quality Overview
DQDL Syntax and Examples
Glue Studio Transformations
NEW QUESTION # 258
......
Amazon Data-Engineer-Associate certification exam is a high demand exam tests in IT field because it proves your ability and professional technology. To get the authoritative certification, you need to overcome the difficulty of Data-Engineer-Associate Test Questions and complete the actual test perfectly. Our training materials contain the latest exam questions and valid Data-Engineer-Associate exam answers for the exam preparation, which will ensure you clear exam 100%.
Simulated Data-Engineer-Associate Test: https://www.lead2passexam.com/Amazon/valid-Data-Engineer-Associate-exam-dumps.html
What's more, part of that Lead2PassExam Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1VGiRV-Aq545XFFL6AmaY-ZRUKJ9ck-Gp