MicrosoftのDP-750認定試験を受けることを決めたら、JPNTestがそばにいて差し上げますよ。JPNTestはあなたが自分の目標を達成することにヘルプを差し上げられます。あなたがMicrosoftのDP-750「Implementing Data Engineering Solutions Using Azure Databricks」認定試験に合格する需要を我々はよく知っていますから、あなたに高品質の問題集と科学的なテストを提供して、あなたが気楽に認定試験に受かることにヘルプを提供するのは我々の約束です。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 2: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 4: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
MicrosoftのDP-750認定試験と言ったら、人々は迷っています。異なる考えがありますが、要約は試験が大変難しいことです。MicrosoftのDP-750認定試験は確かに難しい試験ですが、JPNTest を選んだら、これは大丈夫です。JPNTestのMicrosoftのDP-750試験トレーニング資料は受験生としてのあなたが欠くことができない資料です。それは受験生のために特別に作成したものですから、100パーセントの合格率を保証します。信じないになら、JPNTestのサイトをクリックしてください。購入する人々が大変多いですから、あなたもミスしないで速くショッピングカートに入れましょう。
質問 # 39
You need to curate Unity Catalog objects that reference the ERP data. The solution must meet the governance requirements.
What should you do?
正解:C
解説:
A foreign catalog mirrors the external ERP database and provides read-only access through Lakehouse Federation. Consequently, it cannot host managed volumes or locally created Delta tables, and its foreign tables cannot be altered to add analytics columns. The appropriate design is to create governed views in the managed analytics catalog and have those views reference the foreign tables through fully qualified catalog.
schema.table names. This preserves the ERP data in its source system, avoids duplication, and exposes standardized curated objects through Unity Catalog. Permissions can then be granted on the managed views while access to underlying foreign objects remains controlled. Unity Catalog uses a three-level namespace, and foreign catalogs are specifically intended to make external database data queryable without copying it into Databricks-managed storage. Microsoft Learn
質問 # 40
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Finance
* A schema named Purchases in the Finance catalog
* A table named Transactions in the Purchases schema
You need to ensure that a user named finance_user can query the Transactions table. The solution must follow the principle of least privilege.
Which permission should you grant to finance_user for each object? To answer, drag the appropriate permissions to the correct objects. Each permission may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.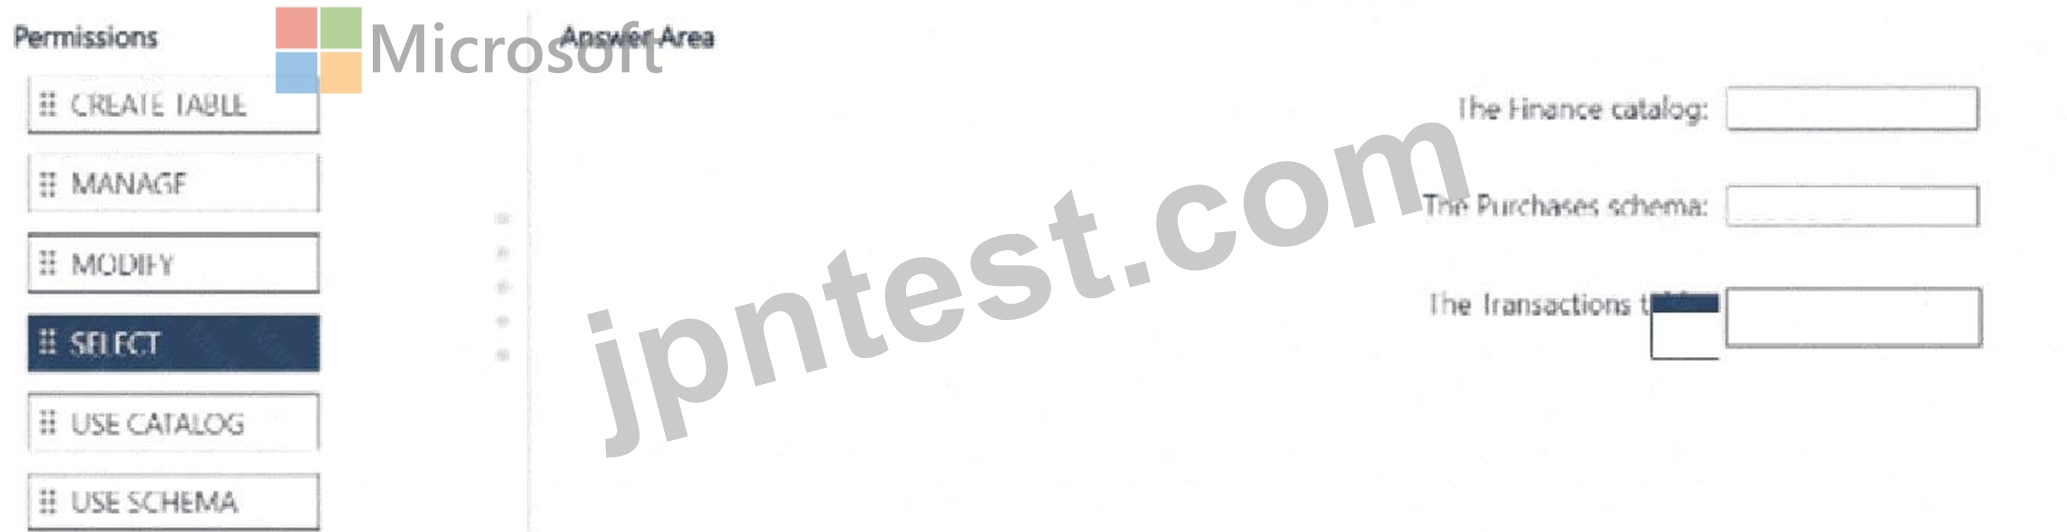
正解:
解説: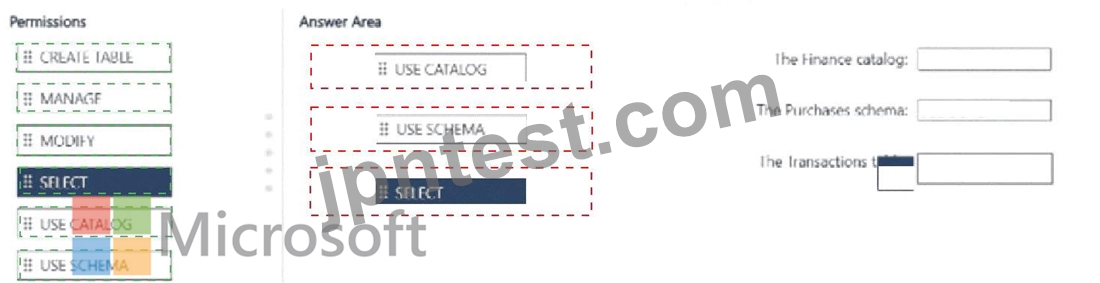
* The Finance catalog: USE CATALOG
* The Purchases schema: USE SCHEMA
* The Transactions table: SELECT
質問 # 41
A Delta table receives new fields in incoming JSON data. You want to automatically adapt without breaking pipelines. What should you enable?
正解:C
解説:
Auto Loader supports schema inference and schema evolution, allowing new columns to be added automatically during ingestion. This reduces pipeline maintenance and avoids failures due to schema drift. Disabling enforcement is unsafe and risks data corruption. Overwrite mode deletes existing data. Manual updates are not scalable.
質問 # 42
You have an Azure Databricks workspace
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically. You need to configure compute for the pipeline. The solution must minimize operational costs and effort. What should you use?
正解:A
解説:
The correct answer is C - a job cluster that uses autoscaling.
Job clusters (also called pipeline clusters in the SDP context) are created exclusively for a pipeline run and terminated when the pipeline stops. You pay only for what the pipeline uses, and there's no idle cost between runs. Autoscaling on a job cluster lets the pipeline expand during heavy processing and contract during lighter stages - the combination of on-demand lifecycle and elastic scaling gives the lowest operational cost.
Option A (all-purpose cluster) runs at a higher DBU rate and persists beyond the pipeline's lifecycle, meaning you're paying for it even when the pipeline isn't running. Option B (SQL warehouse) is optimised for interactive BI and ad-hoc queries, not for the batch/streaming workloads SDP pipelines run. Option D (single- node all-purpose) has no scaling, runs at the all-purpose DBU rate, and is capped at one node - unsuitable for any production pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/configure-pipeline
質問 # 43
You have an Azure Databricks workspace that uses Databricks SQL.
You have a table named sales_goals_source that contains the following columns:
* Salesperson
* Item
* 2019
* 2020
* 2021
You need to transform the year columns into rows and return the columns Salesperson, Item, Year, and Value.
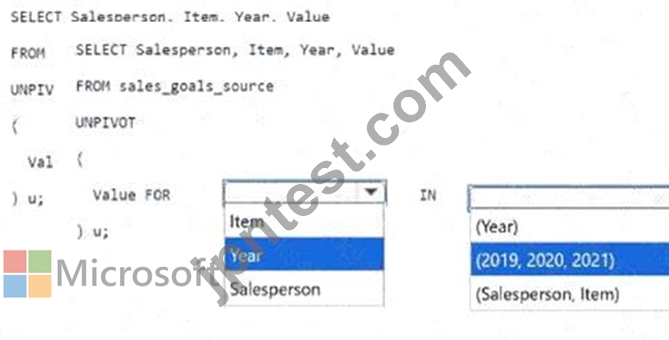
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
SELECT Salesperson, Item, Year, Value
FROM sales_goals_source
UNPIVOT
(
Value FOR [first dropdown] IN [second dropdown]
);
正解:
解説: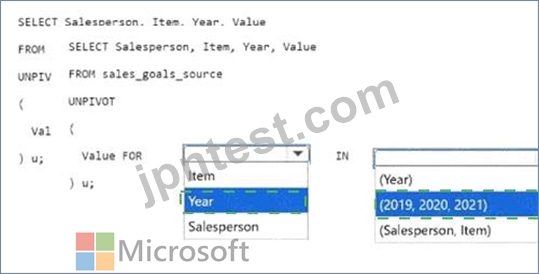
Explanation:
First dropdown: Year
Second dropdown: (2019, 2020, 2021)
The UNPIVOT operator converts the separate 2019, 2020, and 2021 columns into rows. Value becomes the output column containing the values previously stored in those year columns. Year becomes the output name column that identifies the original column from which each value came. Therefore, the expression must use Value FOR Year IN (2019, 2020, 2021). The Salesperson and Item columns are not included in the IN list because they remain identifier columns and are repeated for every resulting year row. A single source row consequently produces three output rows-one for each listed year. Selecting (Year) would reference an output name rather than the source columns that must be rotated.
質問 # 44
......
関連する認定を取得し、自分自身を向上させるためにDP-750試験の準備をしようとするなら、あなたは非常に幸運に違いありません。すべての関係者の共同の努力により、当社は非常に便利で有用なDP-750学習教材を設計しました。さらに重要なことは、当社の学習教材が多くの人々が目標を達成し、関連する認証を取得するのに役立っていることを実践が証明していることです。当社のDP-750学習教材は、DP-750試験に合格し、関連する認定を取得することを切望している人々に最適な学習ツールです。
DP-750全真問題集: https://www.jpntest.com/shiken/DP-750-mondaishu