DOWNLOAD the newest Actual4Cert SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1G0Iv5hSqttVKLwcUChJPyf1MYfxqHF1V
We offer free demos and updates if there are any for your reference beside real SPS-C01 real materials. By downloading the free demos you will catch on the basic essences of our SPS-C01 guide question and just look briefly at our practice materials you can feel the thoughtful and trendy of us. About difficult or equivocal points, our experts left notes to account for them. So SPS-C01 Exam Dumps are definitely valuable acquisitions. Wrong practice materials will upset your pace of review, which is undesirable. Only high-class SPS-C01 guide question like us can be your perfect choice.
| Section | Objectives |
|---|---|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Data Engineering with Snowpark | - Pipeline development
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Testing, Debugging, and Deployment | - Production readiness
|
>> SPS-C01 Certification Exam <<
People who want to pass the exam have difficulty in choosing the suitable SPS-C01 guide questions. They do not know which study materials are suitable for them, and they do not know which the study materials are best. Our company can promise that the SPS-C01 study materials from our company are best among global market. As is known to us, the SPS-C01 Certification guide from our company is the leading practice materials in this dynamic market for SPS-C01 study materials from our company are designed by a lot of experts and professors. Yon can rely on our SPS-C01 exam questions!
NEW QUESTION # 66
You are working with a Snowpark application designed to process data from an event table. While testing a complex transformation involving several joins and window functions, you encounter the following error: 'java.lang.OutOfMemoryError: Java heap space'. The application uses Snowpark DataFrames and is running on a reasonably sized virtual warehouse. What is the MOST likely cause of this error in the context of Snowpark and Snowflake?
Answer: E
Explanation:
OutOfMemoryError in Snowpark is most often due to the driver process attempting to load a large result set into memory. Snowpark is designed to push down computations to Snowflake, but certain operations can force data to be collected on the driver. The correct response highlight this. While the other options might contribute, they are less likely to be the direct cause of a Java heap space error specifically.
NEW QUESTION # 67
You are working with two large Snowpark DataFrames: 'transaction_df and 'product df. 'transaction_df contains transaction data including 'transaction id', 'product id', and 'transaction_date'. 'product df contains product details including 'product id', product_name', and 'product category'. You need to join these DataFrames to analyze transaction data by product category. The 'transaction_df is significantly larger than 'product_df. Which of the following strategies can significantly improve the performance of the join operation in Snowpark? (Select all that apply)
Answer: A,C,D
Explanation:
Options A, B, and D are correct. A ensures efficient comparison and join execution. B leverages broadcast join when smaller dataframe is broadcasted to all nodes, reducing data movement. D reduces the size of the larger DataFrame before the join, improving performance. C is incorrect because caching the larger 'transaction_df DataFrame before the join won't significantly improve performance; Snowpark automatically optimizes query execution. E is wrong because Snowflake manages join algorithms efficiently, forcing a specific algorithm might be counterproductive.
NEW QUESTION # 68
A data engineering team is using Snowpark Python to build a data pipeline. They need to create a User-Defined Function (UDF) that transforms a JSON string column representing customer information into a STRUCT type containing flattened fields for 'name', 'age', and 'city'. The UDF should handle null values gracefully and return NULL if the input JSON is invalid or if the 'name' field is missing. Considering performance implications and error handling, which of the following approaches is MOST optimal for defining and registering this UDF?
Answer: B
Explanation:
Option B is the most optimal. Using allows Snowpark to understand the schema of the returned data, enabling efficient type checking and query optimization. 'snowflake.snowpark.functions.parse_json' leverages Snowflake's internal JSON parsing capabilities, leading to better performance. Returning None from UDF handles nulls gracefully. Other options either involve less efficient StringType return types, manual VARIANT object creation which is less type-safe, or suggest stored procedures when a simple UDF is sufficient.
NEW QUESTION # 69
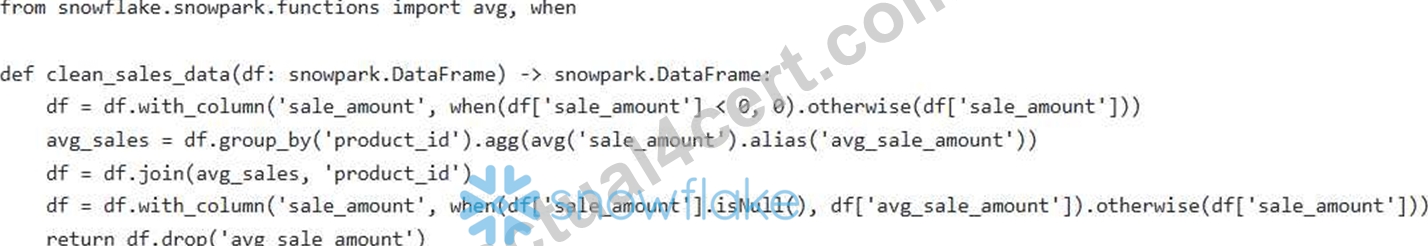
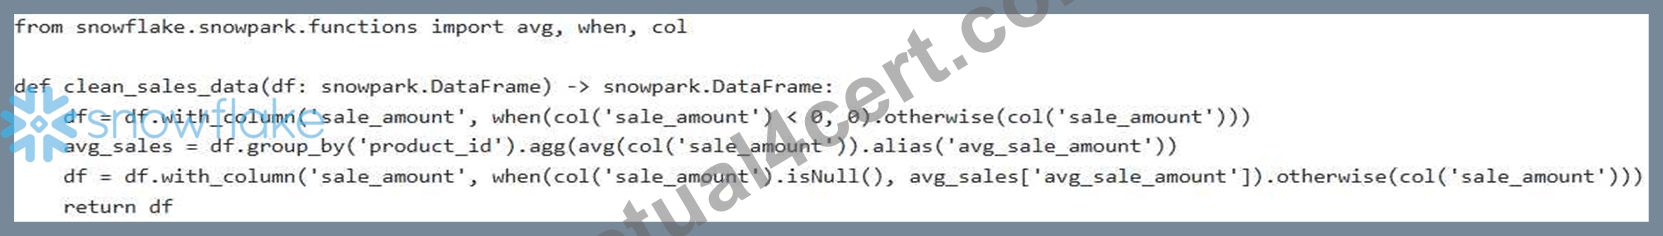
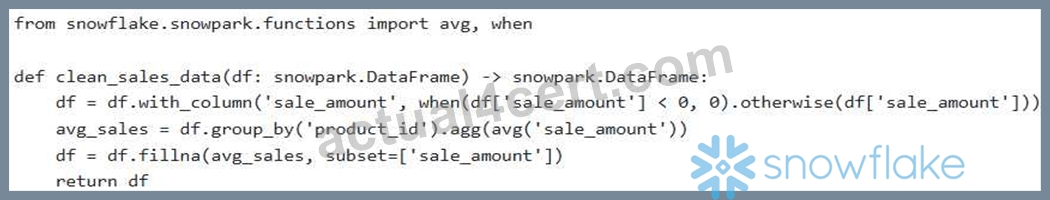
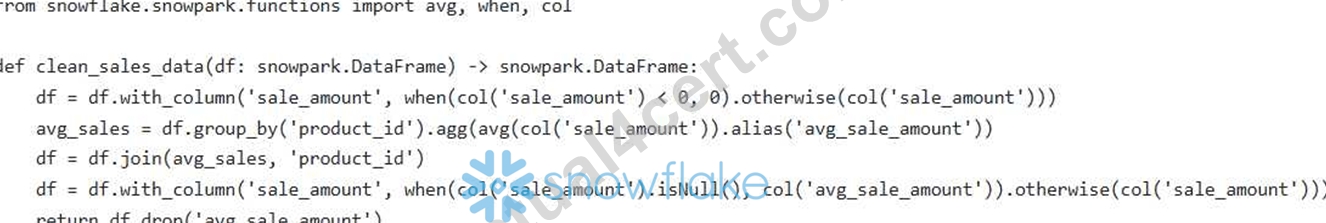
You have a Snowpark DataFrame with columns 'product_id', 'customer_id', and 'sale_amount'. Some values are negative, indicating returns, and others are null. You need to replace negative values with 0 and fill null values with the average 'sale_amount' for each 'product_id'. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark?
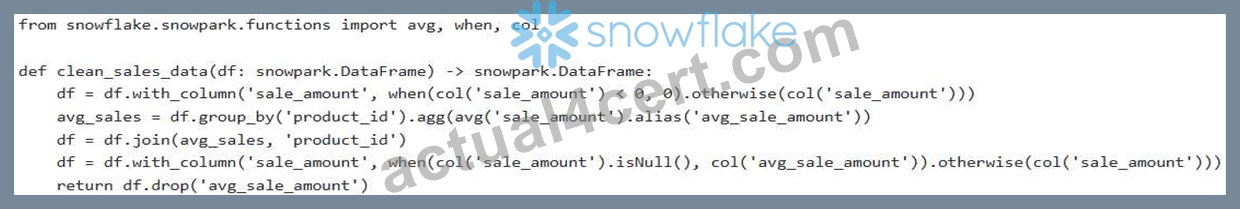
Answer: D
Explanation:
Option E first replaces negative values with 0. Then, it calculates the average sales amount per product and joins it back to the original DataFrame. Finally, it fills null values with the calculated average sales amount and drops the temporary column. This is efficient because it utilizes Snowpark's DataFrame operations. other options does not handle nulls or gives errors.
NEW QUESTION # 70
You are developing a Snowpark application that performs feature engineering on a dataset of customer transactions. This involves calculating several complex aggregate features such as rolling averages, medians, and custom ratios. You want to optimize the performance of this feature engineering process using a Snowpark-optimized warehouse. Which of the following strategies would be MOST effective in achieving optimal performance?
Answer: A,C
Explanation:
Using 'GROUP BY and window functions allows Snowflake to optimize the calculations within its engine. Leveraging UDTFs allows custom computations while still benefiting from Snowflake's optimization capabilities. Python UDFs are generally slower than equivalent SQL or Java/Scala UDTFs due to inter-process communication overhead. Materializing intermediate DataFrames can help in some scenarios but can also introduce overhead if not managed carefully. Java Stored procedures could be used, but UDTF would be more optimized way.
NEW QUESTION # 71
......
It is SPS-C01 exam qualification certification that gives you capital of standing in society and serving your company. Nowadays, using the Internet to study on our SPS-C01 exam questions has been a new trend of making people access to knowledge and capability-building. Our SPS-C01 Preparation materials display a brand-new learning model and a comprehensive knowledge structure on our official exam bank, which aims at improving your technical skills and creating your value to your future.
Exam Topics SPS-C01 Pdf: https://www.actual4cert.com/SPS-C01-real-questions.html
DOWNLOAD the newest Actual4Cert SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1G0Iv5hSqttVKLwcUChJPyf1MYfxqHF1V