Trustworthy Databricks Databricks-Certified-Data-Engineer-Professional Pdf | Databricks-Certified-Data-Engineer-Professional Exam Pattern

Once our customers pay successfully, we will check about your email address and other information to avoid any error, and send you the Databricks-Certified-Data-Engineer-Professional prep guide in 5-10 minutes, so you can get our Databricks-Certified-Data-Engineer-Professional exam questions at first time. And then you can start your study after downloading the Databricks-Certified-Data-Engineer-Professional exam questions in the email attachments. High efficiency service has won reputation for us among multitude of customers, so choosing our Databricks-Certified-Data-Engineer-Professional real study dumps we guarantee that you won’t be regret of your decision. Helping our candidates to pass the Databricks-Certified-Data-Engineer-Professional exam and achieve their dream has always been our common ideal. We believe that your satisfactory is the drive force for our company.
| Section | Weight | Objectives |
|---|
| Monitoring and Troubleshooting | 16% | - Performance Optimization
- Monitoring
- Troubleshooting
|
| Data Processing | 28% | - Spark SQL
- Structured Streaming
- ETL Pipelines
- Data Transformation
|
| Data Quality and Governance | 12% | - Data Quality
- Data Lineage
- Governance
|
| Data Modeling and Storage | 20% | - Data Modeling
- File Formats
- Storage Optimization
|
| Databricks Lakehouse Platform | 24% | - Lakehouse Architecture
- Data Management
- Unity Catalog
- Delta Lake
|
>> Trustworthy Databricks Databricks-Certified-Data-Engineer-Professional Pdf <<
Databricks-Certified-Data-Engineer-Professional Exam Pattern - Exam Databricks-Certified-Data-Engineer-Professional Testking
Our latest Databricks-Certified-Data-Engineer-Professional vce braindumps are written by our IT experts' wealth of knowledge and experience and can fully meet the demand of Databricks-Certified-Data-Engineer-Professional real exam. From related websites or books, you might also see some Databricks free download study materials, but our Databricks-Certified-Data-Engineer-Professional Exam crams are affordable, latest and comprehensive.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q76-Q81):
NEW QUESTION # 76
A nightly job ingests data into a Delta Lake table using the following code:
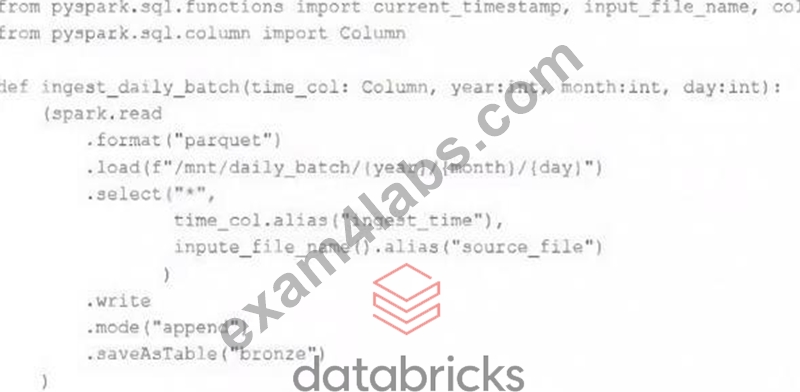
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
- A. return spark.readStream.load("bronze")
- B. return spark.read.option("readChangeFeed", "true").table ("bronze")
- C. def new_records():
- D.
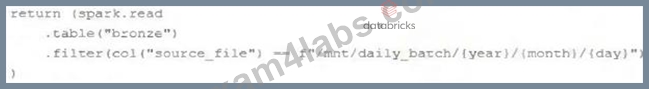
- E. return spark.readStream.table("bronze")
Answer: D
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
NEW QUESTION # 77
A data architect has heard about lake's built-in versioning and time travel capabilities. For auditing purposes they have a requirement to maintain a full of all valid street addresses as they appear in the customers table.
The architect is interested in implementing a Type 1 table, overwriting existing records with new values and relying on Delta Lake time travel to support long-term auditing. A data engineer on the project feels that a Type 2 table will provide better performance and scalability. Which piece of Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from information is critical to this decision?
- A. Delta Lake only supports Type 0 tables; once records are inserted to a Delta Lake table, they cannot be modified.
- B. Delta Lake time travel does not scale well in cost or latency to provide a long-term versioning solution.
- C. Shallow clones can be combined with Type 1 tables to accelerate historic queries for long-term versioning.
- D. Data corruption can occur if a query fails in a partially completed state because Type 2 tables requires setting multiple fields in a single update.
- E. Delta Lake time travel cannot be used to query previous versions of these tables because Type 1 changes modify data files in place.
Answer: B
Explanation:
Delta Lake's time travel feature allows users to access previous versions of a table, providing a powerful tool for auditing and versioning. However, using time travel as a long-term versioning solution for auditing purposes can be less optimal in terms of cost and performance, especially as the volume of data and the number of versions grow. For maintaining a full history of valid street addresses as they appear in a customers table, using a Type 2 table (where each update creates a new record with versioning) might provide better scalability and performance by avoiding the overhead associated with accessing older versions of a large table. While Type 1 tables, where existing records are overwritten with new values, seem simpler and can leverage time travel for auditing, the critical piece of information is that time travel might not scale well in cost or latency for long-term versioning needs, making a Type 2 approach more viable for performance and scalability.
NEW QUESTION # 78
A table in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
- A. Calculate the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers before making new predictions; only make predictions on those customers not in the previous predictions.
- B. Modify the overwrite logic to include a field populated by calling
spark.sql.functions.current_timestamp() as data are being written; use this field to identify records written on a particular date. - C. Replace the current overwrite logic with a merge statement to modify only those records that have changed; write logic to make predictions on the changed records identified by the change data feed.
- D. Convert the batch job to a Structured Streaming job using the complete output mode; configure a Structured Streaming job to read from the customer_churn_params table and incrementally predict against the churn model.
- E. Apply the churn model to all rows in the customer_churn_params table, but implement logic to perform an upsert into the predictions table that ignores rows where predictions have not changed.
Answer: C
Explanation:
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed.
This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
NEW QUESTION # 79
A platform team is creating a standardized template for Databricks Asset Bundles to support CI/CD. The template must specify defaults for artifacts, workspace root paths, and a run identity, while allowing a "dev" target to be the default and override specific paths. How should the team use databricks.yml to satisfy these requirements?
- A. Use roots, modules, profiles, actor, and targets; where profiles contain workspace and artifacts defaults and actor sets run identity.
- B. Use project, packages, environment, identity, and stages; set dev as default stage and override workspace under environment.
- C. Use bundle, artifacts, workspace, run_as, and targets at the top level; set one target with default:true and override workspace paths or artifacts under that target.
- D. Use deployment, builds, context, identity, and environments; set dev as default environment and override paths under builds.
Answer: C
Explanation:
In Databricks Asset Bundles, the databricks.yml file defines all top-level configuration keys, including bundle, artifacts, workspace, run_as, and targets. The targets section defines specific deployment contexts (for example, dev, test, prod). Setting default: true for a target marks it as the default environment. Overrides for workspace paths and artifact configurations can be defined inside each target while keeping defaults at the top level.
NEW QUESTION # 80
A company processes semi-structured JSON files from an external source using Auto Loader in a classic Databricks job. Occasionally, records arrive with null critical fields, invalid types, or unexpected nested schema variations. The engineer must ensure that malformed or non- conforming records are not dropped silently and are captured in a separate quarantine table. The pipeline should continue processing good records into the Bronze layer without failing the job, and the approach must support both batch and streaming ingestion.
The data engineer needs to build a robust ingestion pattern that automatically routes bad records to a quarantine Delta table, while still ingesting good records into the Bronze layer for further processing.
Which approach fulfills the quarantine mechanism in this ingestion architecture?
- A. Use Lakeflow Spark Declarative Pipelines with a SQL pipeline; configure it to drop rows with nulls using where critical_fields is not null, and rely on audit logs for malformed data.
- B. Use Auto Loader with LDP and implement an EXPECT () constraint with a record audit logic to route bad records.
- C. Use Auto Loader with failFast mode to set to false, and enable schema evolution; invalid records will be silently ignored during ingestion.
- D. Create a notebook job with inferSchema=True, write a streaming query with .foreachBatch() and catch exceptions using try/except to redirect failed batches to quarantine.
Answer: B
Explanation:
Lakeflow Spark Declarative Pipelines provide built-in support for data quality enforcement using EXPECT clauses. By defining expectations on critical fields and configuring the pipeline to audit or quarantine failed records, malformed or non-conforming JSON records are automatically routed to a quarantine Delta table while valid records continue flowing into the Bronze layer. This approach is robust, auditable, works for both batch and streaming ingestion, and avoids silently dropping bad data or failing the pipeline.
NEW QUESTION # 81
......
As one of the leading brand in the market, our Databricks-Certified-Data-Engineer-Professional exam materials can be obtained on our website within five minutes. As long as you pay for our Databricks-Certified-Data-Engineer-Professional study guide successfully, then you will receive it quickly. That is the expression of our efficiency. The amazing quality of our Databricks-Certified-Data-Engineer-Professional learning questions can totally catch eyes of exam candidates with passing rate up to 98 to 100 percent.
Databricks-Certified-Data-Engineer-Professional Exam Pattern: https://www.exam4labs.com/Databricks-Certified-Data-Engineer-Professional-practice-torrent.html
- Databricks-Certified-Data-Engineer-Professional Trusted Exam Resource 🍶 Databricks-Certified-Data-Engineer-Professional Valid Real Exam 🍚 Databricks-Certified-Data-Engineer-Professional Valid Real Exam 🚇 Open website ▶ www.troytecdumps.com ◀ and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ for free download 🤘Databricks-Certified-Data-Engineer-Professional Review Guide
- Latest Databricks Certified Data Engineer Professional Exam practice test - Databricks-Certified-Data-Engineer-Professional troytec pdf 🐖 Search on 【 www.pdfvce.com 】 for 【 Databricks-Certified-Data-Engineer-Professional 】 to obtain exam materials for free download ↩Frenquent Databricks-Certified-Data-Engineer-Professional Update
- Databricks-Certified-Data-Engineer-Professional New Braindumps Free 👾 Databricks-Certified-Data-Engineer-Professional Review Guide 🧿 Databricks-Certified-Data-Engineer-Professional Exam Prep 🤞 Download [ Databricks-Certified-Data-Engineer-Professional ] for free by simply searching on “ www.pass4test.com ” 🏗Databricks-Certified-Data-Engineer-Professional Valid Exam Sims
- Latest Databricks-Certified-Data-Engineer-Professional Exam Labs 🌱 Databricks-Certified-Data-Engineer-Professional New Braindumps Free 🐀 Databricks-Certified-Data-Engineer-Professional Valid Exam Sims 🚑 Easily obtain free download of ▶ Databricks-Certified-Data-Engineer-Professional ◀ by searching on 「 www.pdfvce.com 」 🧽Trustworthy Databricks-Certified-Data-Engineer-Professional Pdf
- Databricks Databricks-Certified-Data-Engineer-Professional Web-Based Practice Exam Questions Software 🧅 ☀ www.dumpsmaterials.com ️☀️ is best website to obtain ▷ Databricks-Certified-Data-Engineer-Professional ◁ for free download 🕍Databricks-Certified-Data-Engineer-Professional Book Pdf
- Trustworthy Databricks-Certified-Data-Engineer-Professional Pdf 🎣 Databricks-Certified-Data-Engineer-Professional Valid Real Exam 😲 Databricks-Certified-Data-Engineer-Professional Trusted Exam Resource 🤨 Simply search for 【 Databricks-Certified-Data-Engineer-Professional 】 for free download on ⮆ www.pdfvce.com ⮄ 💸New Databricks-Certified-Data-Engineer-Professional Test Review
- Free PDF 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Trustable Trustworthy Databricks Certified Data Engineer Professional Exam Pdf 🏖 Search for { Databricks-Certified-Data-Engineer-Professional } on { www.pdfdumps.com } immediately to obtain a free download 🧱Test Databricks-Certified-Data-Engineer-Professional Guide Online
- New Databricks-Certified-Data-Engineer-Professional Test Review ⚖ Databricks-Certified-Data-Engineer-Professional Valid Torrent 😦 Databricks-Certified-Data-Engineer-Professional Reliable Test Cost 🍃 Open ➠ www.pdfvce.com 🠰 and search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 to download exam materials for free 🆎Databricks-Certified-Data-Engineer-Professional New Braindumps Free
- Quiz Databricks - Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam –Trustable Trustworthy Pdf 👤 Enter 【 www.testkingpass.com 】 and search for { Databricks-Certified-Data-Engineer-Professional } to download for free 🏍Databricks-Certified-Data-Engineer-Professional Exam Prep
- Databricks-Certified-Data-Engineer-Professional Study Materials - Databricks-Certified-Data-Engineer-Professional Exam Preparatory - Databricks-Certified-Data-Engineer-Professional Test Prep 💮 Search for “ Databricks-Certified-Data-Engineer-Professional ” and download exam materials for free through { www.pdfvce.com } 🦡Frenquent Databricks-Certified-Data-Engineer-Professional Update
- Databricks-Certified-Data-Engineer-Professional Exam Fees 📒 Frenquent Databricks-Certified-Data-Engineer-Professional Update 🍭 Latest Databricks-Certified-Data-Engineer-Professional Test Fee ⬛ Go to website ➥ www.practicevce.com 🡄 open and search for ( Databricks-Certified-Data-Engineer-Professional ) to download for free 🎬Latest Databricks-Certified-Data-Engineer-Professional Test Fee
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes