Google Professional-Data-Engineer Exam | Professional-Data-Engineer日本語対策 -手助けするクリアProfessional-Data-Engineer: Google Certified Professional Data Engineer Exam試験

ちなみに、Xhs1991 Professional-Data-Engineerの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1KJGrrn_L5APoMFxjHljV1Ss2BpM8nPaM
当社からProfessional-Data-Engineer学習教材を購入する場合、高品質のProfessional-Data-Engineer学習問題と最高のサービスを提供できてうれしいです。当社の理念は「品質は命、顧客は神」です。当社はすべての顧客に完璧な品質保証システムと健全な管理システムを提供することを約束できます。当社のProfessional-Data-Engineer学習教材の品質とサービスについて心配する必要はありません。弊社からProfessional-Data-Engineer学習問題を購入することを決めた場合、想像をはるかに超えるものを受け取ることになります。
Google Professional-Data-Engineer試験は、Google Cloud Platformで作業するプロフェッショナルのスキルと知識をテストするために設計されています。データ処理システムの設計、構築、管理の経験があり、機械学習モデルやデータ分析ツールを扱う人々に向けたものです。この試験は、ビジネスのニーズに応えるためにGoogle Cloud Platformツールを使用してソリューションを開発・実装する能力をプロフェッショナルが持っているかどうかをテストするために設計されています。
Google Professional-Data-Engineer認定は、データ処理の専門家がGoogle Cloudプラットフォームでデータ処理システムの設計と構築の知識とスキルを実証する優れた方法です。この認定は、個人が自分のキャリアを前進させ、データエンジニアリングの分野で新しい機会を開くのに役立ちます。
>> Professional-Data-Engineer日本語対策 <<
Professional-Data-Engineer試験 & Professional-Data-Engineer資格問題対応
有益な取引を行うだけでなく、GoogleユーザーがProfessional-Data-Engineer証明書を取得するまでの最短時間で試験に合格できるようにしたいと考えています。 Professional-Data-Engineer試験のプラクティスを選択すると、Xhs1991試験の準備に20〜30時間しかかかりません。 Professional-Data-Engineerの学習教材は試験の概要とProfessional-Data-Engineerガイドの質問の質問に密接に関連しているため、このような短い時間ですべてのコンテンツを終了できるかどうかを尋ねる場合があります。 最新の基本的なGoogle Certified Professional Data Engineer Exam知識に関連しています。 Professional-Data-Engineer試験問題に合格した場合のみ、Professional-Data-Engineer試験に合格します。
Google Professional-Data-Engineer認定は、データエンジニアリングの分野で働く専門家にとって挑戦的で価値のある資格です。認定試験では、データ処理、ストレージ、分析、視覚化に関連するさまざまな分野で候補者の知識とスキルをテストし、Google Cloudプラットフォームでの経験がある個人向けに設計されています。この認定を達成することは、専門家がキャリアを進め、データエンジニアリングの分野での専門知識を実証するのに役立ちます。
Google Certified Professional Data Engineer Exam 認定 Professional-Data-Engineer 試験問題 (Q257-Q262):
質問 # 257
You are deploying a new storage system for your mobile application, which is a media streaming service. You decide the best fit is Google Cloud Datastore. You have entities with multiple properties, some of which can take on multiple values. For example, in the entity `Movie' the property `actors' and the property `tags' have multiple values but the property `date released' does not. A typical query would ask for all movies with actor=<actorname> ordered by date_released or all movies with tag=Comedy ordered by date_released. How should you avoid a combinatorial explosion in the number of indexes?
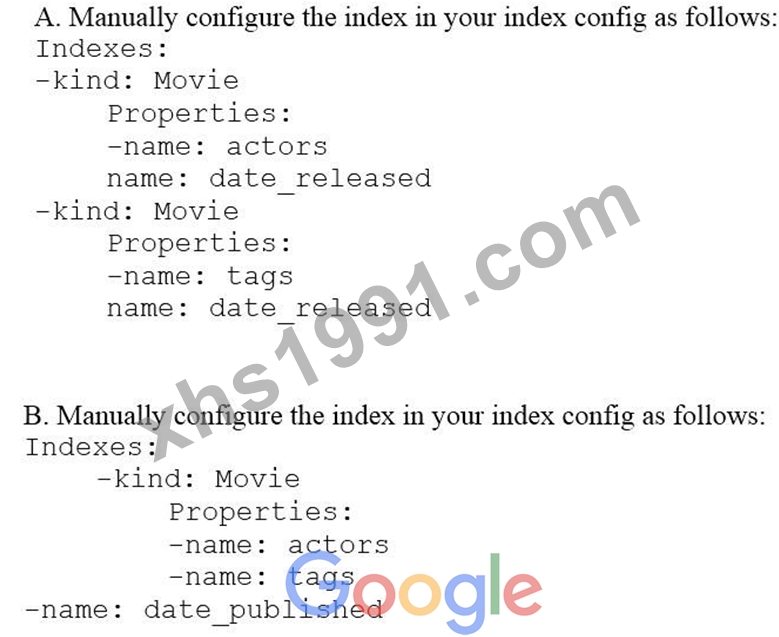
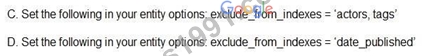
- A. Option A
- B. Option C
- C. Option B.
- D. Option D
正解:A
質問 # 258
Suppose you have a dataset of images that are each labeled as to whether or not they contain a human face. To create a neural network that recognizes human faces in images using this labeled dataset, what approach would likely be the most effective?
- A. Use feature engineering to add features for eyes, noses, and mouths to the input data.
- B. Use deep learning by creating a neural network with multiple hidden layers to automatically detect features of faces.
- C. Build a neural network with an input layer of pixels, a hidden layer, and an output layer with two categories.
- D. Use K-means Clustering to detect faces in the pixels.
正解:B
解説:
Explanation
Traditional machine learning relies on shallow nets, composed of one input and one output layer, and at most one hidden layer in between. More than three layers (including input and output) qualifies as "deep" learning.
So deep is a strictly defined, technical term that means more than one hidden layer.
In deep-learning networks, each layer of nodes trains on a distinct set of features based on the previous layer's output. The further you advance into the neural net, the more complex the features your nodes can recognize, since they aggregate and recombine features from the previous layer.
A neural network with only one hidden layer would be unable to automatically recognize high-level features of faces, such as eyes, because it wouldn't be able to "build" these features using previous hidden layers that detect low-level features, such as lines.
Feature engineering is difficult to perform on raw image data.
K-means Clustering is an unsupervised learning method used to categorize unlabeled data.
Reference: https://deeplearning4j.org/neuralnet-overview
質問 # 259
Suppose you have a table that includes a nested column called "city" inside a column called "person", but when you try to submit the following query in BigQuery, it gives you an error.
SELECT person FROM `project1.example.table1` WHERE city = "London"
How would you correct the error?
- A. Change "person" to "person.city".
- B. Add ", UNNEST(city)" before the WHERE clause.
- C. Change "person" to "city.person".
- D. Add ", UNNEST(person)" before the WHERE clause.
正解:D
解説:
To access the person.city column, you need to "UNNEST(person)" and JOIN it to table1 using a comma.
Reference:
https://cloud.google.com/bigquery/docs/reference/standard-sql/migrating-from-legacy-sql#nested_repeated_results
質問 # 260
You have a job that you want to cancel. It is a streaming pipeline, and you want to ensure that any data that is in-flight is processed and written to the output. Which of the following commands can you use on the Dataflow monitoring console to stop the pipeline job?
- A. Stop
- B. Finish
- C. Cancel
- D. Drain
正解:D
解説:
Using the Drain option to stop your job tells the Dataflow service to finish your job in its current state. Your job will immediately stop ingesting new data from input sources, but the Dataflow
service will preserve any existing resources (such as worker instances) to finish processing and writing any buffered data in your pipeline.
質問 # 261
You want to migrate an on-premises Hadoop system to Cloud Dataproc. Hive is the primary tool in use, and the data format is Optimized Row Columnar (ORC). All ORC files have been successfully copied to a Cloud Storage bucket. You need to replicate some data to the cluster's local Hadoop Distributed File System (HDFS) to maximize performance. What are two ways to start using Hive in Cloud Dataproc? (Choose two.)
- A. Leverage Cloud Storage connector for Hadoop to mount the ORC files as external Hive tables. Replicate external Hive tables to the native ones.
- B. Run the gsutil utility to transfer all ORC files from the Cloud Storage bucket to the master node of the Dataproc cluster. Then run the Hadoop utility to copy them do HDFS. Mount the Hive tables from HDFS.
- C. Run the gsutil utility to transfer all ORC files from the Cloud Storage bucket to HDFS. Mount the Hive tables locally.
- D. Load the ORC files into BigQuery. Leverage BigQuery connector for Hadoop to mount the BigQuery tables as external Hive tables. Replicate external Hive tables to the native ones.
- E. Run the gsutil utility to transfer all ORC files from the Cloud Storage bucket to any node of the Dataproc cluster. Mount the Hive tables locally.
正解:B、E
質問 # 262
......
Professional-Data-Engineer試験: https://www.xhs1991.com/Professional-Data-Engineer.html
- Professional-Data-Engineer試験の準備方法|更新するProfessional-Data-Engineer日本語対策試験|権威のあるGoogle Certified Professional Data Engineer Exam試験 🌎 “ www.it-passports.com ”を開いて⮆ Professional-Data-Engineer ⮄を検索し、試験資料を無料でダウンロードしてくださいProfessional-Data-Engineer問題数
- パススルーProfessional-Data-Engineer日本語対策 - 資格試験におけるリーダーオファー - 素晴らしいProfessional-Data-Engineer: Google Certified Professional Data Engineer Exam 🕸 “ www.goshiken.com ”で☀ Professional-Data-Engineer ️☀️を検索して、無料で簡単にダウンロードできますProfessional-Data-Engineer試験過去問
- Professional-Data-Engineer受験対策書 🔆 Professional-Data-Engineer日本語版復習資料 🚾 Professional-Data-Engineer最新問題 🍈 ➥ www.topexam.jp 🡄に移動し、▶ Professional-Data-Engineer ◀を検索して無料でダウンロードしてくださいProfessional-Data-Engineer真実試験
- Professional-Data-Engineer日本語版復習資料 ➡️ Professional-Data-Engineer模擬資料 💆 Professional-Data-Engineer日本語版対策ガイド 🌽 ➠ www.goshiken.com 🠰には無料の▷ Professional-Data-Engineer ◁問題集がありますProfessional-Data-Engineer勉強の資料
- パススルーProfessional-Data-Engineer日本語対策 - 資格試験におけるリーダーオファー - 素晴らしいProfessional-Data-Engineer: Google Certified Professional Data Engineer Exam 🦖 ➤ www.goshiken.com ⮘から⮆ Professional-Data-Engineer ⮄を検索して、試験資料を無料でダウンロードしてくださいProfessional-Data-Engineer最新問題
- Professional-Data-Engineer日本語版復習資料 👋 Professional-Data-Engineer日本語資格取得 🌟 Professional-Data-Engineer受験対策解説集 🧘 URL ➠ www.goshiken.com 🠰をコピーして開き、⏩ Professional-Data-Engineer ⏪を検索して無料でダウンロードしてくださいProfessional-Data-Engineer試験番号
- パススルーProfessional-Data-Engineer日本語対策 - 資格試験におけるリーダーオファー - 素晴らしいProfessional-Data-Engineer: Google Certified Professional Data Engineer Exam 🟡 ☀ www.it-passports.com ️☀️を開き、“ Professional-Data-Engineer ”を入力して、無料でダウンロードしてくださいProfessional-Data-Engineer模擬解説集
- Professional-Data-Engineer試験の準備方法|更新するProfessional-Data-Engineer日本語対策試験|権威のあるGoogle Certified Professional Data Engineer Exam試験 🚎 Open Webサイト⇛ www.goshiken.com ⇚検索☀ Professional-Data-Engineer ️☀️無料ダウンロードProfessional-Data-Engineer真実試験
- ハイパスレートのProfessional-Data-Engineer日本語対策 - 合格スムーズProfessional-Data-Engineer試験 | 検証するProfessional-Data-Engineer資格問題対応 💮 今すぐ《 www.it-passports.com 》で⇛ Professional-Data-Engineer ⇚を検索し、無料でダウンロードしてくださいProfessional-Data-Engineerテキスト
- Professional-Data-Engineer試験の準備方法|更新するProfessional-Data-Engineer日本語対策試験|権威のあるGoogle Certified Professional Data Engineer Exam試験 😋 ( www.goshiken.com )で使える無料オンライン版➽ Professional-Data-Engineer 🢪 の試験問題Professional-Data-Engineer模擬モード
- Professional-Data-Engineerテキスト ☸ Professional-Data-Engineer受験対策書 🏀 Professional-Data-Engineer真実試験 📲 ウェブサイト▶ www.passtest.jp ◀から✔ Professional-Data-Engineer ️✔️を開いて検索し、無料でダウンロードしてくださいProfessional-Data-Engineer模擬モード
- ehoroskop.net, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Xhs1991 Professional-Data-Engineerダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1KJGrrn_L5APoMFxjHljV1Ss2BpM8nPaM