참고: KoreaDumps에서 Google Drive로 공유하는 무료, 최신 DP-100 시험 문제집이 있습니다: https://drive.google.com/open?id=1AaWEKmfVuqb9ulWhRUHTG-F5fkdaA5jv
만약 시험만 응시하고 싶으시다면 우리의 최신Microsoft DP-100자료로 시험 패스하실 수 있습니다. KoreaDumps 의 학습가이드에는Microsoft DP-100인증시험의 예상문제, 시험문제와 답 임으로 100% 시험을 패스할 수 있습니다.우리의Microsoft DP-100시험자료로 충분한 시험준비하시는것이 좋을것 같습니다. 그리고 우리는 일년무료 업데이트를 제공합니다.
| Section | Weight | Objectives |
|---|---|---|
| Explore data and run experiments | 20-25% | - Implement pipelines
|
| Design and prepare a machine learning solution | 20-25% | - Manage data assets
|
| Train and deploy models | 25-30% | - Train models
|
| Optimize language models for AI applications | 25-30% | - Evaluate and improve models
|
Microsoft인증 DP-100시험을 등록했는데 마땅한 공부자료가 없어 고민중이시라면KoreaDumps의Microsoft인증 DP-100덤프를 추천해드립니다. KoreaDumps의Microsoft인증 DP-100덤프는 거의 모든 시험문제를 커버하고 있어 시험패스율이 100%입니다. KoreaDumps제품을 선택하시면 어려운 시험공부도 한결 가벼워집니다.
질문 # 308
You run an experiment that uses an AutoMLConfig class to define an automated machine learning task with a maximum of ten model training iterations. The task will attempt to find the best performing model based on a metric named accuracy.
You submit the experiment with the following code:
You need to create Python code that returns the best model that is generated by the automated machine learning task. Which code segment should you use?
A)
B)
C)
D)
정답:B
설명:
The get_output method returns the best run and the fitted model.
Reference:
https://notebooks.azure.com/azureml/projects/azureml-getting-started/html/how-to-use-azureml/automated-machine-learning/classification/auto-ml-classification.ipynb
질문 # 309
You are building an experiment using the Azure Machine Learning designer.
You split a dataset into training and testing sets. You select the Two-Class Boosted Decision Tree as the algorithm.
You need to determine the Area Under the Curve (AUC) of the model.
Which three modules should you use in sequence? To answer, move the appropriate modules from the list of modules to the answer area and arrange them in the correct order.
정답:
설명:
Explanation
Step 1: Train Model
Two-Class Boosted Decision Tree
First, set up the boosted decision tree model.
1. Find the Two-Class Boosted Decision Tree module in the module palette and drag it onto the canvas.
2. Find the Train Model module, drag it onto the canvas, and then connect the output of the Two-Class Boosted Decision Tree module to the left input port of the Train Model module.
The Two-Class Boosted Decision Tree module initializes the generic model, and Train Model uses training data to train the model.
3. Connect the left output of the left Execute R Script module to the right input port of the Train Model module (in this tutorial you used the data coming from the left side of the Split Data module for training).
This portion of the experiment now looks something like this:
Step 2: Score Model
Score and evaluate the models
You use the testing data that was separated out by the Split Data module to score our trained models. You can then compare the results of the two models to see which generated better results.
Add the Score Model modules
1. Find the Score Model module and drag it onto the canvas.
2. Connect the Train Model module that's connected to the Two-Class Boosted Decision Tree module to the left input port of the Score Model module.
3. Connect the right Execute R Script module (our testing data) to the right input port of the Score Model module.
Step 3: Evaluate Model
To evaluate the two scoring results and compare them, you use an Evaluate Model module.
1. Find the Evaluate Model module and drag it onto the canvas.
2. Connect the output port of the Score Model module associated with the boosted decision tree model to the left input port of the Evaluate Model module.
3. Connect the other Score Model module to the right input port.
질문 # 310
You have a Python data frame named salesData in the following format:
The data frame must be unpivoted to a long data format as follows: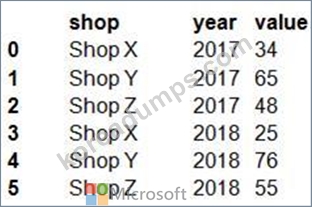
You need to use the pandas.melt() function in Python to perform the transformation.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
정답:
설명:
Explanation: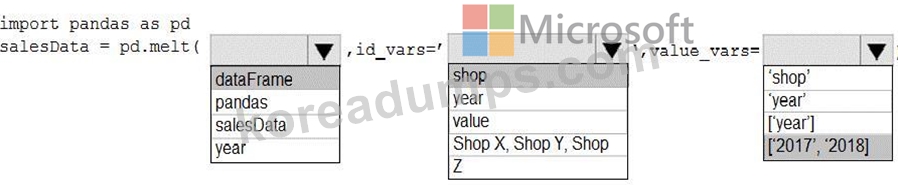
Box 1: dataFrame
Syntax: pandas.melt(frame, id_vars=None, value_vars=None, var_name=None, value_name='value', col_level=None)[source] Where frame is a DataFrame Box 2: shop Paramter id_vars id_vars : tuple, list, or ndarray, optional Column(s) to use as identifier variables.
Box 3: ['2017','2018']
value_vars : tuple, list, or ndarray, optional
Column(s) to unpivot. If not specified, uses all columns that are not set as id_vars.
Example:
df = pd.DataFrame({'A': {0: 'a', 1: 'b', 2: 'c'},
'B': {0: 1, 1: 3, 2: 5},
'C': {0: 2, 1: 4, 2: 6}})
pd.melt(df, id_vars=['A'], value_vars=['B', 'C'])
A variable value
0 a B 1
1 b B 3
2 c B 5
3 a C 2
4 b C 4
5 c C 6
References:
https://pandas.pydata.org/pandas-docs/stable/reference/api/pandas.melt.html
질문 # 311
You are developing a linear regression model in Azure Machine Learning Studio. You run an experiment to compare different algorithms.
The following image displays the results dataset output:
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the image.
NOTE: Each correct selection is worth one point.
정답:
설명:
Explanation:
Box 1: Boosted Decision Tree Regression
Mean absolute error (MAE) measures how close the predictions are to the actual outcomes; thus, a lower score is better.
Box 2:
Online Gradient Descent: If you want the algorithm to find the best parameters for you, set Create trainer mode option to Parameter Range. You can then specify multiple values for the algorithm to try.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/evaluate-model
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/linear-regression
질문 # 312 
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
정답:
설명:
질문 # 313
......
인재도 많고 경쟁도 많은 이 사회에, 업계인재들은 인기가 아주 많습니다.하지만 팽팽한 경쟁률도 무시할 수 없습니다.많은 Microsoft인재들도 어려운 인증시험을 패스하여 자기만의 자리를 지키고 있습니다.우리KoreaDumps에서는 마침 전문적으로 이러한 Microsoft인사들에게 편리하게 시험을 DP-100패스할수 있도록 유용한 자료들을 제공하고 있습니다.
DP-100최고덤프데모: https://www.koreadumps.com/DP-100_exam-braindumps.html
그 외, KoreaDumps DP-100 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1AaWEKmfVuqb9ulWhRUHTG-F5fkdaA5jv