Wir sind uns darüber klar, dass die IT-Brache ein neuartiges Industriewesen ist. Sie ist auch eine der Ketten, die die Wirtschaft vorantreiben. Deswegen spielt sie eine gewichtige Rolle und man soll sie nicht ignorieren. Unsere Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung sind das Ergebnis der langjährigen ständigen Untersuchung und Erforschung von den erfahrenen IT-Experten aus Zertpruefung. An ihrer Autorität besteht kein Zweifel. Falls Sie unsere Prüfungsmaterialien gekauft haben, werden wir Ihnen einjähriger Aktualisierung versprechen.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30–35% | - Ingest and transform data
|
| Topic 2: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 4: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
>> DP-750 Ausbildungsressourcen <<
Durch die kontinuierliche Entwicklung und das Wachstum der IT-Branche in den letzten Jahren ist DP-750 Prüfung schon zu einem Meilenstein in der Microsoft-Prüfung geworden. DP-750 Prüfung kann Ihnen helfen, ein IT-Profi zu werden. Es gibt Hunderte von Online-Ressourcen, die Microsoft DP-750 Zertifizierungsprüfung bieten. Der Grund, warum die meisten Menschen Zertpruefung wählen, liegt darin, dass Zertpruefung ein riesiges IT-Elite Team hat. Um Ihnen Zugänglichkeit zur Microsoft DP-750 Zertifizierungsprüfung zu gewährleisten, spezialisieren sich unser Eliteteam auf die neuesten Materialien der Microsoft DP-750 Prüfung. Zertpruefung verpricht, dass Sie zum ersten Mal die Zertifizierung von Microsoft erhalten Microsoft DP-750 Prüfung können. Zertpruefung steht immer mit Ihnen durch dick und dünn.
31. Frage
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to ensure that data lineage is captured and can be reviewed for tables accessed by Databricks notebooks and jobs. The solution must minimize administrative effort.
Which compute configuration should you use to capture the data lineage and what should you use to review the data lineage? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.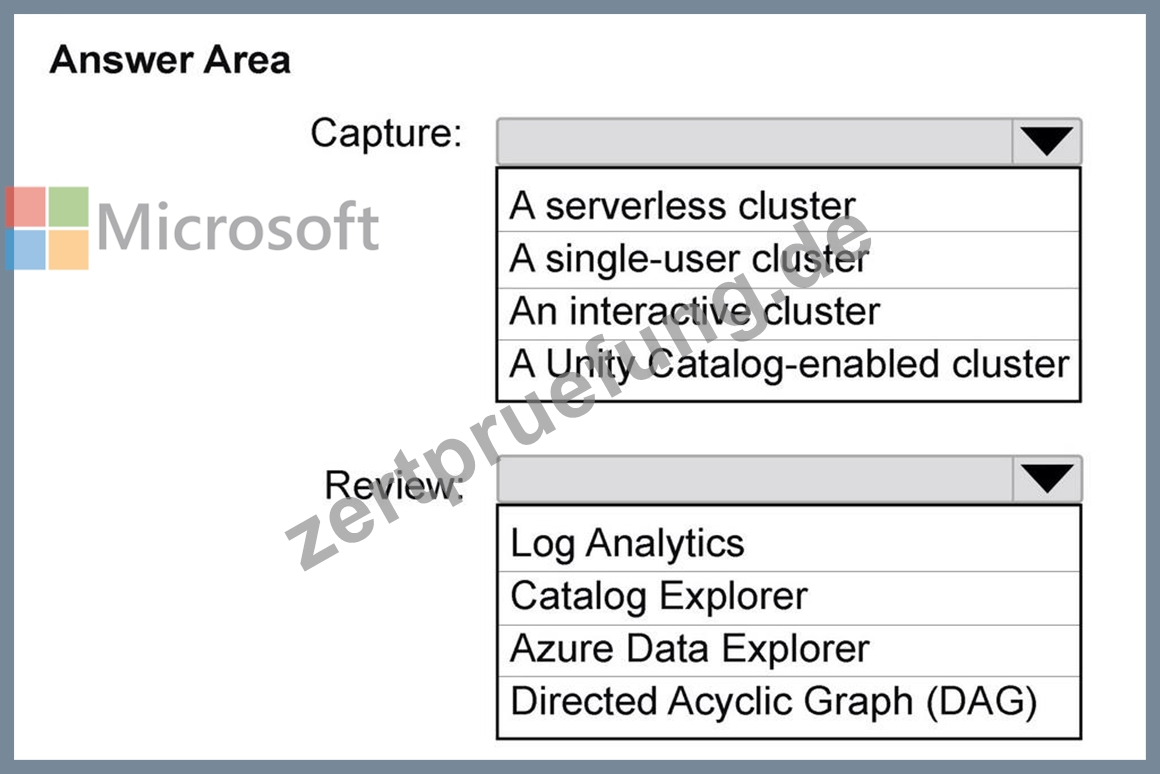
Antwort:
Begründung: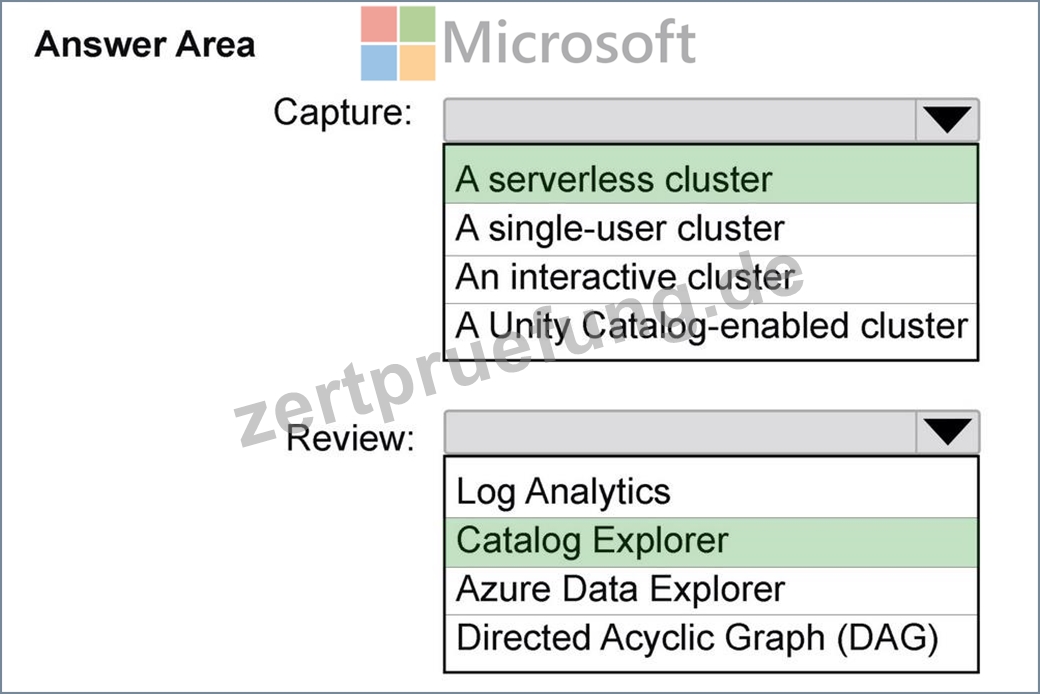
32. Frage
You manage Declarative Automation Bundles by using the Databricks CLI.
You run the following command in a terminal window.
databricks bundle init
What occurs when you run the command?
Antwort: D
Begründung:
The databricks bundle init command initializes a new bundle project from a selected default or custom project template. It prompts for relevant project values and creates the local project structure and starter configuration files. It does not deploy resources; deployment is performed with databricks bundle deploy. It does not merely validate an existing configuration, because validation uses databricks bundle validate. Running deployed bundle resources requires databricks bundle run followed by the resource key. The distinction matters in an automated bundle lifecycle: initialization scaffolds the project, validation checks configuration, deployment creates or updates workspace resources, and run starts a configured job or pipeline. Therefore, option A accurately describes the initialization command's function. Microsoft Learn
33. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have an Apache Spark Structured Streaming job that writes data to a Delta table.
After the cluster restarts, the streaming job reprocesses previously ingested data.
You need to prevent the streaming job from reprocessing the data after the cluster restarts.
What should you do?
Antwort: C
Begründung:
To prevent your Apache Spark Structured Streaming job from reprocessing previously ingested data after a cluster restart, you must configure a streaming checkpoint directory.
Core Solution
Enable Checkpointing: Define the checkpointLocation option in your streaming write configuration.
Track Progress: Spark uses this directory to save the exact offset ranges of processed data.
Automatic Recovery: Upon restart, the engine reads the checkpoint and resumes precisely where it left off.
Implementation Example in python
# Configure the streaming write with a checkpoint path
(df.writeStream
.format("delta")
.outputMode("append")
.option("checkpointLocation",
"/Volumes/catalog/schema/volume_name/checkpoints/job_name")
.toTable("catalog.schema.target_table"))
Reference:
https://medium.com/@salah.uddin_75300/architecture-of-a-streaming-machine-learning-data- pipeline-042200c8e7ff
34. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Corpdb
* A schema named Finance in the Corpdb catalog
* A table named Sales in the Finance schema
You have a group named Analysts.
You assign the following permissions to Analysts:
* USE CATALOG on the Corpdb catalog
* USE SCHEMA on the Finance schema
* SELECT on the Sales table
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.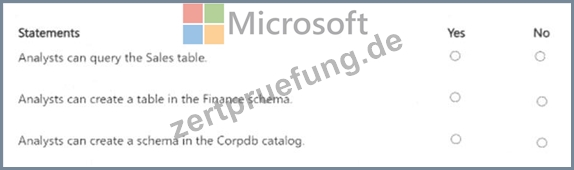
Antwort:
Begründung: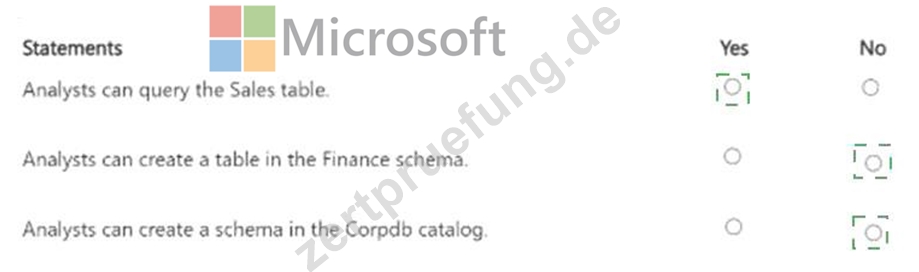
Explanation: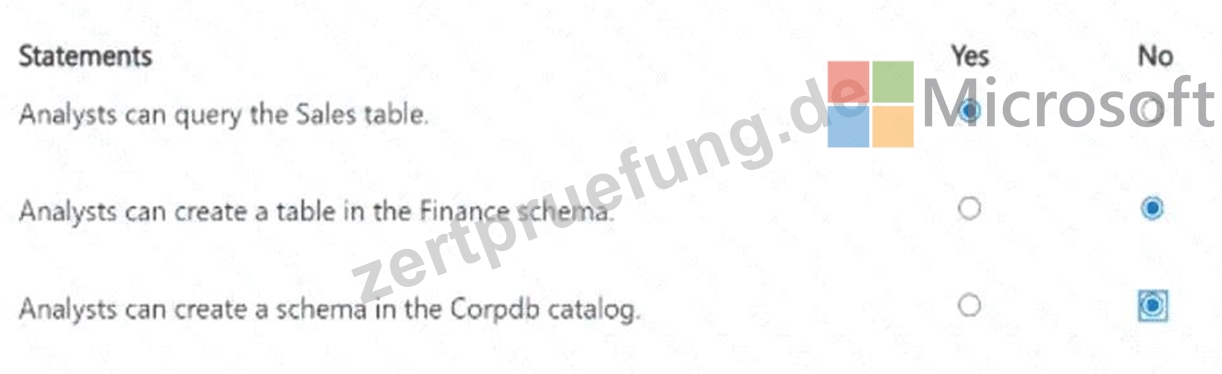
The Analysts group can query the Sales table because it has all three privileges required by the Unity Catalog hierarchy: USE CATALOG on Corpdb, USE SCHEMA on Finance, and SELECT on Sales. These permissions allow the group to navigate through the catalog and schema and read the table. However, USE SCHEMA does not grant permission to create tables. Creating a table in Finance would additionally require CREATE TABLE on that schema. Similarly, USE CATALOG only permits access to the catalog; it does not permit schema creation. Creating a schema in Corpdb would require the CREATE SCHEMA privilege on the catalog. Therefore, only the first statement is true.
35. Frage
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a Databricks access connector.
Does this meet the goal?
Antwort: A
Begründung:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
36. Frage
......
Der Vorhang der Lebensbühne wird jederzeit geöffnet werden. Die Hauptsache ist, ob Sie spielen wollen oder einfach weglaufen. Diejenigen, die die Chancen ergreifen können, können Erfolg erlangen. Deshalb müssen Sie Zertpruefung wählen. Sie können jederzeit Ihre Fertigkeiten zeigen. Die Prüfungsmaterialien zur Microsoft DP-750 Zertifizierungsprüfung von Zertpruefung ist die effziente Methode, die DP-750 Prüfung zu bestehen. Mit DP-750 Zertifikat können Sie Ihren Traum verwirklichen und Erfolg erlangen.
DP-750 Prüfungsmaterialien: https://www.zertpruefung.de/DP-750_exam.html