Our Certified-Data-Engineer-Professional study tool boost three versions for you to choose and they include PDF version, PC version and APP online version. Each version is suitable for different situation and equipment and you can choose the most convenient method to learn our Certified-Data-Engineer-Professional test torrent. For example, APP online version is printable and boosts instant access to download. You can study the Certified-Data-Engineer-Professional Guide Torrent at any time and any place. The PC version of Certified-Data-Engineer-Professional study tool can stimulate the real exam's scenarios. We provide 365-days free update and free demo available.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Implement scalable Python/SQL code and project structures - Manage dependencies, libraries, and UDFs |
>> Study Certified-Data-Engineer-Professional Dumps <<
If you can get a certification, it will be help you a lot, for instance, it will help you get a more job and a better title in your company than before, and the Certified-Data-Engineer-Professional certification will help you get a higher salary. We believe that our company has the ability to help you successfully pass your exam and get a Certified-Data-Engineer-Professional certification by our Certified-Data-Engineer-Professional exam torrent. We can promise that you would like to welcome this opportunity to kill two birds with one stone. If you choose our Certified-Data-Engineer-Professional Test Questions as your study tool, you will be glad to study for your exam and develop self-discipline, our Certified-Data-Engineer-Professional latest question adopt diversified teaching methods, and we can sure that you will have passion to learn by our products.
NEW QUESTION # 183
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on task A.
If tasks A and B complete successfully but task C fails during a scheduled run, which statement describes the resulting state?
Answer: C
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The resulting state after running the second command is that an external table will be created in the storage container mounted to /mnt/finance_eda_bucket with the new name prod.sales_by_store. The command will not change any data or move any files in the storage container; it will only update the table reference in the metastore and create a new Delta transaction log for the renamed table.
NEW QUESTION # 184
A data engineer is creating a daily reporting job. There are two reporting notebooks--one for weekdays and one for weekends. An "if/else condition" task is configured as
{{job.start_time.is_weekday}} == true to route the job to either the weekday or weekend notebook tasks. The same job would be used across multiple time zones. Which action should a senior data engineer take upon reviewing the job to merge or reject the pull request?
Answer: C
Explanation:
Databricks parameter templates like {{job.start_time.is_weekday}} evaluate in UTC time by default, not in local workspace or regional time zones. Therefore, when jobs are configured to run across different time zones, relying on is_weekday using UTC may cause scheduling and task routing mismatches (for example, triggering the weekday notebook in one region while it's still the weekend locally).
Databricks recommends adjusting conditional logic or pipeline parameters explicitly to handle time zone conversions if business requirements depend on local times. Because the engineer's configuration does not account for this behavior, a senior data engineer should reject the pull request and suggest time-zone-aware logic before merging.
NEW QUESTION # 185
A data engineer wants to ingest a large collection of image files (JPEG and PNG) from cloud object storage into a Unity Catalog-managed table for analysis and visualization. Which two configurations and practices are recommended to incrementally ingest these images into the table? (Choose two.)
Answer: A,C
Explanation:
Databricks Auto Loader supports ingestion of binary file formats using the cloudFiles.format option. For ingesting JPEG or PNG image files, the correct setting is "BINARYFILE", which loads the raw binary content and file metadata into a DataFrame. Additionally, when processing files from object storage, it is best practice to apply pathGlobFilter to limit ingestion to specific file types and reduce unnecessary scanning of non-image files. Options like "IMAGE" or "TEXT" are invalid, and using volumes with SQL editors does not provide incremental ingestion. Therefore, combining Auto Loader with cloudFiles.format="BINARYFILE" and pathGlobFilter ensures scalable, incremental ingestion of image data into Unity Catalog tables.
NEW QUESTION # 186
A team of data engineer are adding tables to a DLT pipeline that contain repetitive expectations for many of the same data quality checks.
One member of the team suggests reusing these data quality rules across all tables defined for this pipeline.
What approach would allow them to do this?
Answer: C
Explanation:
Maintaining data quality rules in a centralized Delta table allows for the reuse of these rules across multiple DLT (Delta Live Tables) pipelines. By storing these rules outside the pipeline's target schema and referencing the schema name as a pipeline parameter, the team can apply the same set of data quality checks to different tables within the pipeline. This approach ensures consistency in data quality validations and reduces redundancy in code by not having to replicate the same rules in each DLT notebook or file.
NEW QUESTION # 187
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query: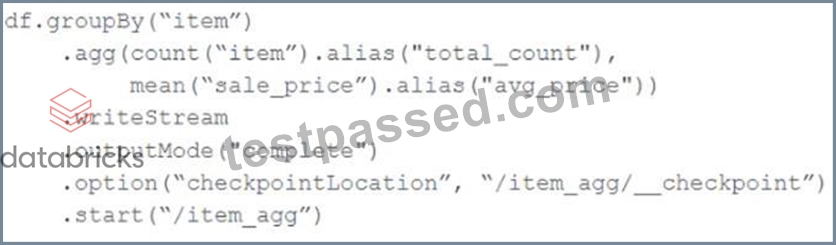
Proposed query: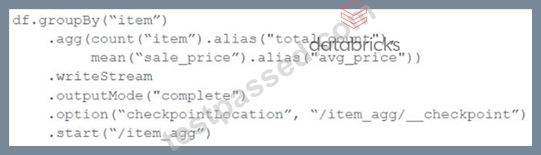
Which step must also be completed to put the proposed query into production?
Answer: B
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
NEW QUESTION # 188
......
Certified-Data-Engineer-Professional practice test can be your optimum selection and useful tool to deal with the urgent challenge. With over a decade’s striving, our Certified-Data-Engineer-Professional training materials have become the most widely-lauded and much-anticipated products in industry. We will look to build up R&D capacity by modernizing innovation mechanisms and fostering a strong pool of professionals. Therefore, rest assured of full technical support from our professional elites in planning and designing Certified-Data-Engineer-Professional Practice Test.
Exam Certified-Data-Engineer-Professional Bible: https://www.testpassed.com/Certified-Data-Engineer-Professional-still-valid-exam.html