BONUS!!! Download part of Pass4sures DP-800 dumps for free: https://drive.google.com/open?id=1TyR1MshCOPH1CMsioD9x5BaP7-xulqpi
The 24/7 support team is just an e-mail away for our customers so that they can contact us anytime. Our team will solve all of their issues as quickly as possible. Free demos and up to 1 year of free updates of our Microsoft Exams are also available at Pass4sures. Buy updated and Real DP-800 Exam Questions now and earn your dream DP-800 certification with Pass4sures!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
We aim to leave no misgivings to our customers so that they are able to devote themselves fully to their studies on DP-800 guide materials and they will find no distraction from us. I suggest that you strike while the iron is hot since time waits for no one. With our DP-800 Exam Questions, you will be bound to pass the exam with the least time and effort for its high quality. With our DP-800 study guide for 20 to 30 hours, you will be ready to take part in the exam and pass it with ease.
NEW QUESTION # 40
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.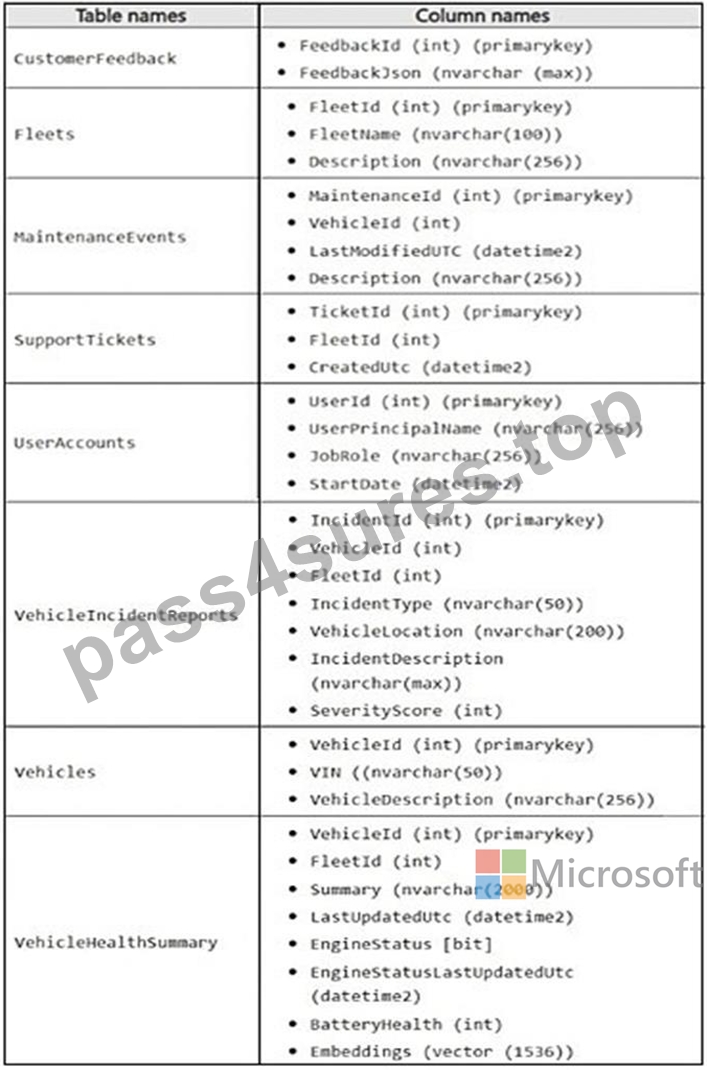
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.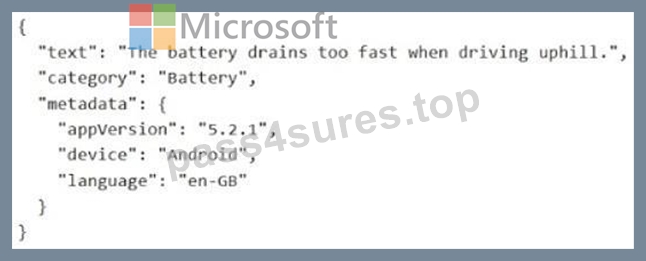
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.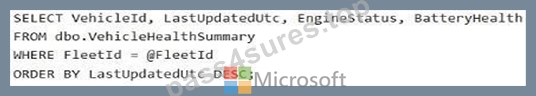
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution for the development team to retrieve the live metadata. The solution must meet the development requirements. What should you include in the recommendation?
Answer: C
Explanation:
Scenario: Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
To retrieve live metadata from Azure SQL databases and use it with GitHub Copilot in Visual Studio Code (VS Code), you must use the SQL Server (mssql) extension. This extension provides the native capability to extract a database schema as a .dacpac file directly within the editor.
1. Export the Schema as a .dacpac File
You can extract the schema of your live Azure SQL database using the SQL Server (mssql) extension.
2. Load the .dacpac into GitHub Copilot Context
Once the .dacpac file is saved in your VS Code workspace, you can provide it as context to GitHub Copilot Chat using #-mentions or Drag & Drop.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sql-database-projects/concepts/data-tier- applications/extract-dacpac-from-database
NEW QUESTION # 41
You have a SQL database in Microsoft Fabric that contains a table named WebSite. Logs. WebSite.Logs stores application telemetry data. Website.Logs contains a nvarehar(iMx) column named log that stores JSON documents You have a daily report that filters by the $.severity JSON property and returns Logld. LogDateTime, and log.
The report frequently causes full table scans.
You need to modify Website. Logs to support efficient filtering by $. severity and avoid key lookups for the columns returned by the report.
How should you complete the Transact-SQL code to avoid full table scans? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.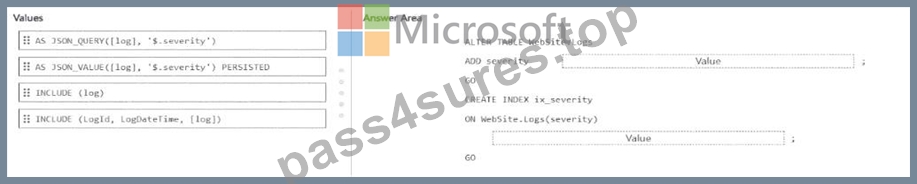
Answer:
Explanation: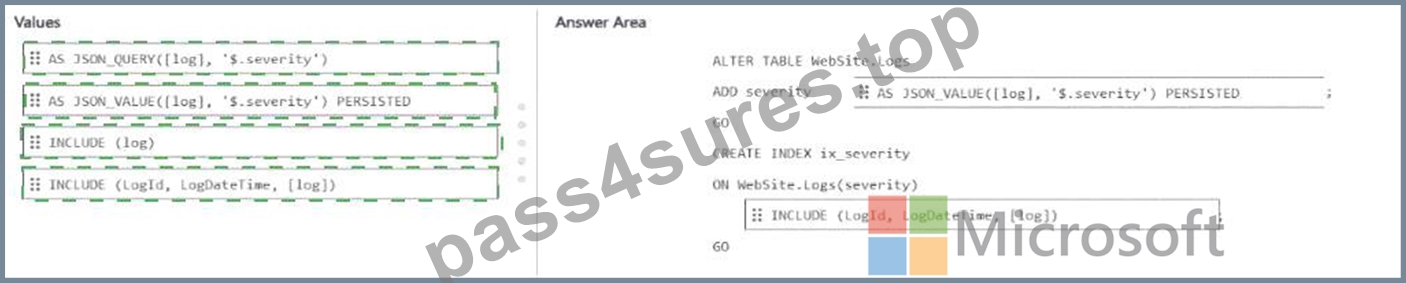
Explanation: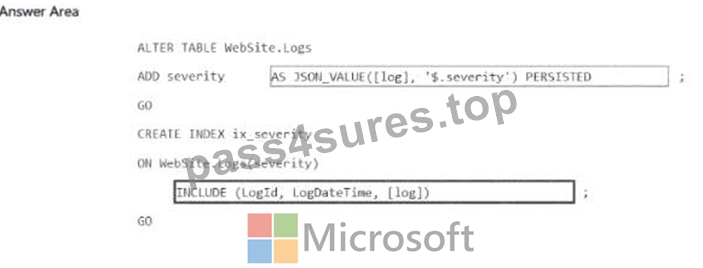
The correct way to avoid full table scans here is to add a computed column that extracts the JSON scalar property with JSON_VALUE , and then create a nonclustered index on that computed column with the report's returned columns in the INCLUDE list. Microsoft's JSON indexing guidance specifically recommends creating a computed column that exposes the JSON property you filter on, using the same expression as in the query, and then indexing that computed column.
So the computed column must be:
AS JSON_VALUE([log], ' $.severity ' ) PERSISTED
This is correct because $.severity is a scalar JSON value, so JSON_VALUE is the proper function.
JSON_QUERY would be for extracting an object or array, not a scalar property. Microsoft also notes that persisted computed columns can improve access speed for JSON-derived values.
The index should then include:
INCLUDE (LogId, LogDateTime, [log])
That is the right covering strategy because the report filters by severity but returns LogId, LogDateTime, and log. Microsoft's guidance on included columns explains that nonkey included columns let a nonclustered index cover more queries and reduce extra lookups to the base table.
So the completed code is:
ALTER TABLE WebSite.Logs
ADD severity AS JSON_VALUE([log], ' $.severity ' ) PERSISTED;
GO
CREATE INDEX ix_severity
ON WebSite.Logs(severity)
INCLUDE (LogId, LogDateTime, [log]);
GO
NEW QUESTION # 42
You have an Azure SQL database that contains the following SQL graph tables:
* A NODE table named dbo.Person
* An EDGE table named dbo.Knows
Each row in dbo.Person contains the following columns:
* Personid (int)
* DisplayName (nvarchar(100))
You need to use a HATCH operator and exactly two directed Knows relationships to return the Personid and DisplayName of people that are reachable from the person identified by an input parameter named
@startPersonid.
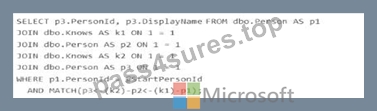
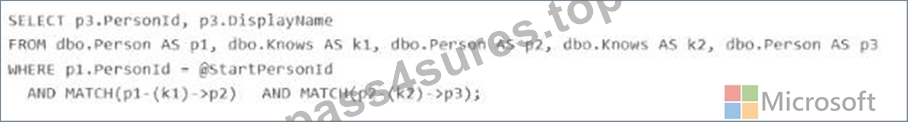
Which Transact-SQL query should you use?
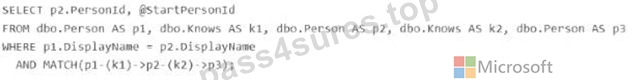
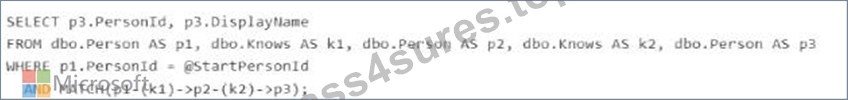
Answer: D
Explanation:
The correct query is Option D because it starts from the input person and uses exactly two directed Knows edges in a single MATCH pattern:
MATCH(p1-(k1)- > p2-(k2)- > p3)
Microsoft documents that SQL Graph uses the MATCH predicate in the WHERE clause to express graph traversal patterns over node and edge tables, and directed relationships are written with arrow syntax such as node1-(edge)- > node2.
Why D is correct:
* It anchors the starting node with p1.PersonId = @StartPersonId.
* It traverses two directed hops : p1 - > p2 - > p3.
* It returns p3.PersonId, p3.DisplayName, which are the people reachable in exactly two Knows relationships.
Why the others are wrong:
* A filters on DisplayName = DisplayName, which is unrelated to the required input parameter and does not correctly anchor the start node.
* B reverses the traversal direction in the pattern.
* C uses two separate MATCH predicates instead of the required single two-hop directed pattern. The proper graph pattern syntax supports chaining the hops directly in one MATCH expression.
NEW QUESTION # 43
You have an Azure SQL database that contains tables named dbo.Tickets and dbo.TicketNotes.
dbo.Tickets contains support tickets and dbo.TicketNotes contains ticket notes.
A retrieval query returns the top five relevant ticket notes for a user question.
You plan to implement a Retrieval Augmented Generation (RAG) pattern that meets the following requirements:
- Formats the retrieved relational data for large language model (LLM)
processing
- Sends the user question and retrieved context to an Azure OpenAI REST endpoint for chat completions
- Extracts the response text from the LLM response
Which Transact-SQL function should you use to extract the response text?
Answer: B
Explanation:
The Transact-SQL function used to extract the response text from the Azure OpenAI REST endpoint is JSON_VALUE.
When you call the Azure OpenAI REST endpoint using sp_invoke_external_rest_endpoint, the response is returned as a JSON string. To isolate the actual text content from the LLM, you must parse this JSON structure.
Function: JSON_VALUE(response_body, '$.choices[0].message.content')
Purpose: It extracts a scalar (text) value from a JSON string.
Path: In the OpenAI schema, the generated response is always located at
$.choices[0].message.content.
Reference:
https://pub.towardsai.net/mastering-retrieval-augmented-generation-from-zero-to-expert-in-rag- for-quickly-building-a-08141a308836
NEW QUESTION # 44
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.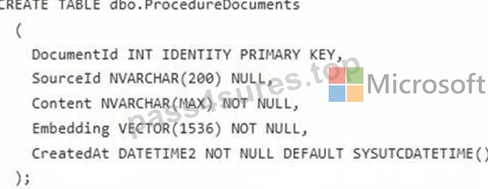
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.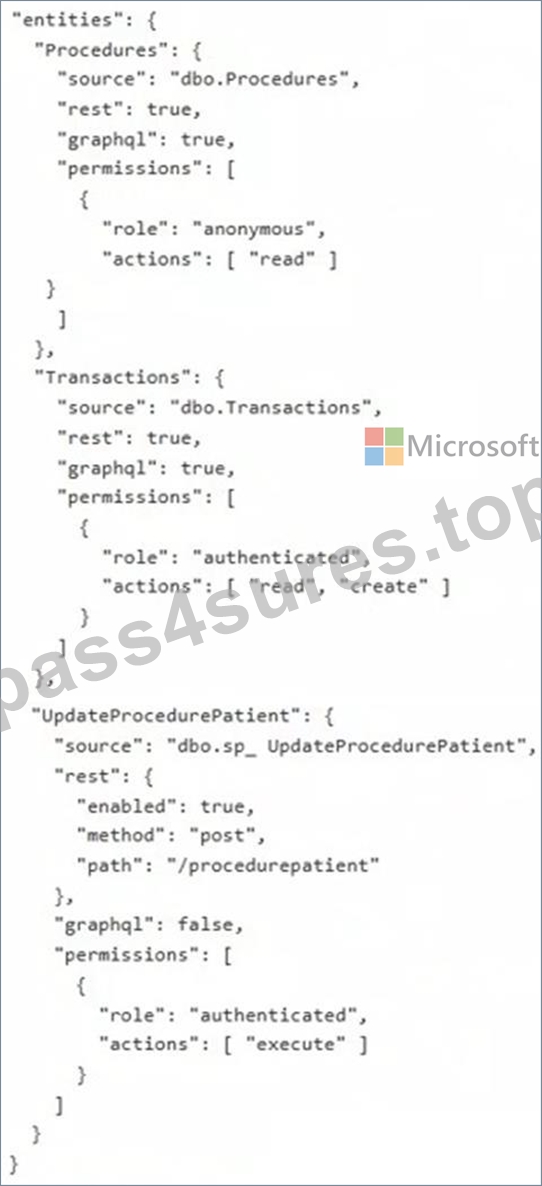
You implement ProcedureDocuments to support the planned changes.
When users consume data through the Retrieval Augmented Generation (RAG) pattern, they experience data retrieval delays.
You need to improve the data retrieval performance and reduce the number of tokens per retrieval.
What should you implement?
Answer: B
Explanation:
Scenario: Fabrikam identifies the following AI-related requirements: Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
To remedy data retrieval delays in a Retrieval Augmented Generation (RAG) pattern using Reciprocal Rank Fusion (RRF) on an Azure SQL Database table, you should use embeddings.
In a RAG architecture, retrieval delays often stem from inefficient or computationally heavy search processes. While RRF is excellent for merging results from multiple sources (like combining keyword and vector searches), the core of the speed problem typically lies in how the initial data is indexed and retrieved.
Role of Embeddings
Vector Search Acceleration: Embeddings convert text into high-dimensional vectors. Azure SQL Database can perform similarity searches on these vectors much faster than complex semantic text matching.
Hybrid Search Synergy: RRF is most effective when it fuses results from a keyword search (fast) and a vector search (powered by embeddings). Using embeddings ensures that the "semantic" side of the retrieval is streamlined.
Pre-computation: Since embeddings are generated once during ingestion, the retrieval phase only requires a distance calculation (e.g., Cosine Similarity), which is significantly faster than real- time natural language parsing during each query.
Reference:
https://pratikbarjatya.medium.com/unlocking-the-power-of-language-with-retrieval-augmented- generation-rag-14123cc275e6
NEW QUESTION # 45
......
One of the main unique qualities of the Pass4sures Microsoft Exam Questions is its ease of use. Our practice exam simulators are user and beginner friendly. You can use Developing AI-Enabled Database Solutions (DP-800) PDF dumps and Web-based software without installation. Developing AI-Enabled Database Solutions (DP-800) PDF questions work on all the devices like smartphones, Macs, tablets, Windows, etc. We know that it is hard to stay and study for the Developing AI-Enabled Database Solutions (DP-800) exam dumps in one place for a long time.
DP-800 Reliable Cram Materials: https://www.pass4sures.top/Microsoft-Certified-SQL-AI-Developer/DP-800-testking-braindumps.html
2026 Latest Pass4sures DP-800 PDF Dumps and DP-800 Exam Engine Free Share: https://drive.google.com/open?id=1TyR1MshCOPH1CMsioD9x5BaP7-xulqpi