2026 Latest FreeDumps Databricks-Certified-Data-Engineer-Associate PDF Dumps and Databricks-Certified-Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1YvMy9okCstZboDJFQj2LRKjJlDDwoH18
According to the survey from our company, the experts and professors from our company have designed and compiled the best Databricks-Certified-Data-Engineer-Associate cram guide in the global market. We can assure to all people that our Databricks-Certified-Data-Engineer-Associate study materials will have a higher quality and it can help all people to remain an optimistic mind when they are preparing for the Databricks-Certified-Data-Engineer-Associate Exam. On the contrary, people who want to pass the exam will persist in studying all the time. We deeply believe that the latest Databricks-Certified-Data-Engineer-Associate study questions from our company will is most suitable and helpful for all people.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Engineer Associate Exam |
| Exam Number: | DE-A |
| Certificate Validity Period: | 2 years |
| Related Certifications: | Databricks Certified Data Engineer Professional |
| Passing Score: | Approximately ~70% (not officially fixed/publicly guaranteed) |
| Exam Duration: | 90 minutes |
| Real Exam Qty: | 45 scored multiple-choice questions |
| Exam Format: | Multiple-choice, Scenario-based questions, Proctored online or test center |
| Available Languages: | English |
| Exam Price: | USD 200 |
| Recommended Training: | Databricks Data Engineering Learning Path (Databricks Academy) Official Data Engineering with Databricks Course |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Certified-Data-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored exam or test center |
| Pre Condition: | No formal prerequisites required; recommended ~6 months hands-on experience with Databricks, Spark SQL, and PySpark. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-associate |
>> Reliable Databricks-Certified-Data-Engineer-Associate Dumps Pdf <<
You can practice all the difficulties and hurdles which could be faced in an actual Databricks exam. It also assists you in boosting confidence and reducing problem-solving time. The Pass4future designs Databricks-Certified-Data-Engineer-Associate desktop-based practice software for desktops, so you can install it from a website and then use it without an internet connection. You only need an internet connection to verify the license of the products. No other plugins are required to employ it.
The Databricks Certified Data Engineer Associate Exam certification exam consists of 60 multiple-choice questions that must be answered within 90 minutes. Databricks-Certified-Data-Engineer-Associate Exam is available in English and can be taken online, making it accessible to candidates worldwide. The passing score for the exam is 70%, and candidates who pass the exam receive a certificate that demonstrates their proficiency in data engineering using Databricks.
NEW QUESTION # 207
In which of the following scenarios should a data engineer use the MERGE INTO command instead of the INSERT INTO command?
Answer: A
Explanation:
The MERGE INTO command is used to perform upserts, which are a combination of insertions and updates, based on a source table into a target Delta table1. The MERGE INTO command can handle scenarios where the target table cannot contain duplicate records, such as when there is a primary key or a unique constraint on the target table. The MERGE INTO command can match the source and target rows based on a merge condition and perform different actions depending on whether the rows are matched or not. For example, the MERGE INTO command can update the existing target rows with the new source values, insert the new source rows that do not exist in the target table, or delete the target rows that do not exist in the source table1.
The INSERT INTO command is used to append new rows to an existing table or create a new table from a query result2. The INSERT INTO command does not perform any updates or deletions on the existing target table rows. The INSERT INTO command can handle scenarios where the location of the data needs to be changed, such as when the data needs to be moved from one table to another, or when the data needs to be partitioned by a certain column2. The INSERT INTO command can also handle scenarios where the target table is an external table, such as when the data is stored in an external storage system like Amazon S3 or Azure Blob Storage3. The INSERT INTO command can also handle scenarios where the source table can be deleted, such as when the source table is a temporary table or a view4. The INSERT INTO command can also handle scenarios where the source is not a Delta table, such as when the source is a Parquet, CSV, JSON, or Avro file5.
References:
* 1: MERGE INTO | Databricks on AWS
* 2: [INSERT INTO | Databricks on AWS]
* 3: [External tables | Databricks on AWS]
* 4: [Temporary views | Databricks on AWS]
* 5: [Data sources | Databricks on AWS]
NEW QUESTION # 208
A data engineer is inspecting an ETL pipeline based on a Pyspark job that consistently encounters performance bottlenecks. Based on developer feedback, the data engineer assumes the job is low on compute resources. To pinpoint the issue, the data engineer observes the Spark UI and finds out the job has a high CPU time vs Task time. Which course of action should the data engineer take?
Answer: D
Explanation:
A high CPU time vs Task time indicates that tasks are CPU-bound and the job is over-utilizing CPU resources. The appropriate action is to tune executors and cores or resize the cluster to ensure adequate compute resources.
NEW QUESTION # 209
A data engineer has a Python notebook in Databricks, but they need to use SQL to accomplish a specific task within a cell. They still want all of the other cells to use Python without making any changes to those cells.
Which of the following describes how the data engineer can use SQL within a cell of their Python notebook?
Answer: E
Explanation:
In Databricks, you can use different languages within the same notebook by using magic commands. Magic commands are special commands that start with a percentage sign (%) and allow you to change the behavior of the cell. To use SQL within a cell of a Python notebook, you can add %sql to the first line of the cell. This will tell Databricks to interpret the rest of the cell as SQL code and execute it against the default database. You can also specify a different database by using the USE statement. The result of the SQL query will be displayed as a table or a chart, depending on the output mode. You can also assign the result to a Python variable by using the -o option. For example, %sql -o df SELECT * FROM my_table will run the SQL query and store the result as a pandas DataFrame in the Python variable df. Option A is incorrect, as it is possible to use SQL in a Python notebook using magic commands. Option B is incorrect, as attaching the cell to a SQL endpoint is not necessary and will not change the language of the cell. Option C is incorrect, as simply writing SQL syntax in the cell will result in a syntax error, as the cell will still be interpreted as Python code. Option E is incorrect, as changing the default language of the notebook to SQL will affect all the cells, not just one. Reference: Use SQL in Notebooks - Knowledge Base - Noteable, [SQL magic commands - Databricks], [Databricks SQL Guide - Databricks]
NEW QUESTION # 210
A global retail company sells products across multiple categories (e.g., Electronics, Clothing) and regions (e.g., North, South, East, West). The sales team has provided the data engineer with a PySpark dataframe named sales_df as below and the team wants the data engineer to analyze the sales data to help them make strategic decisions.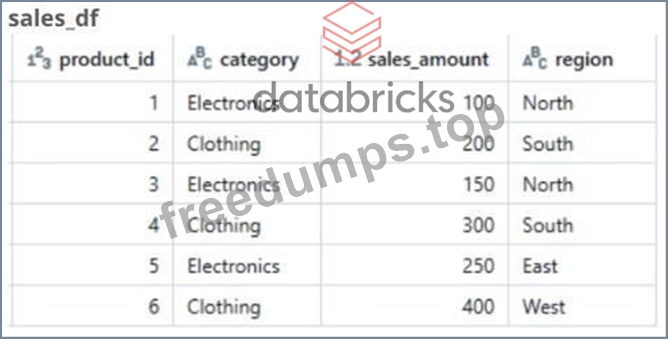
Calculate the total sales amount for each product category and store the results in a new dataframe called category_sales.
What will generate the expected result of category_sales?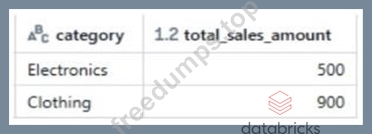
Answer: C
Explanation:
The correct approach is to group by the product category and then aggregate the sum of sales_amount, aliasing it as total_sales_amount. This produces the expected totals: 500 for Electronics and 900 for Clothing.
NEW QUESTION # 211
A single Job runs two notebooks as two separate tasks. A data engineer has noticed that one of the notebooks is running slowly in the Job's current run. The data engineer asks a tech lead for help in identifying why this might be the case.
Which of the following approaches can the tech lead use to identify why the notebook is running slowly as part of the Job?
Answer: E
Explanation:
The Tasks tab in the Jobs UI shows the list of tasks that are part of a job, and allows the user to view the details of each task, such as the notebook path, the cluster configuration, the run status, and the duration. By clicking on the active run of a task, the user can access the Spark UI, the notebook output, and the logs of the task. These can help the user to identify the performance bottlenecks and errors in the task. The Runs tab in the Jobs UI only shows the summary of the job runs, such as the start time, the end time, the trigger, and the status. It does not provide the details of the individual tasks within a job run. References: Jobs UI, Monitor running jobs with a Job Run dashboard, How to optimize jobs performance
NEW QUESTION # 212
......
New Databricks-Certified-Data-Engineer-Associate Test Registration: https://www.freedumps.top/Databricks-Certified-Data-Engineer-Associate-real-exam.html
P.S. Free & New Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by FreeDumps: https://drive.google.com/open?id=1YvMy9okCstZboDJFQj2LRKjJlDDwoH18