DOWNLOAD the newest itPass4sure Professional-Machine-Learning-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1UHWIa3cBai6l1nFVjpWAVboa8DofpK_-
If you are preparing for an exam, it may spend lots of time, but don't worry, if you are preparing for the Professional-Machine-Learning-Engineer exam, the product of our company will help you save your time. The product of our company will list the major key points of the Professional-Machine-Learning-Engineer exam, and you can grasp the knowledge points as quickly as possible, therefore the time is saving. Besides, the product for Professional-Machine-Learning-Engineer Exam also provide specific training materials for the exam. And the PDF version is convenient to read, and sopport printing, while the software version stimulate the real environment of the Professional-Machine-Learning-Engineer exam. The APP online version is slao available of the product, you can learn at any time and at any place. Choosing our product, it wil help you.
| Section | Objectives |
|---|---|
| Scaling prototypes into ML models | - Hyperparameter tuning - Training at scale (Distributed training, TPUs) - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) |
| Collaborating within and across teams to manage data and models | - Version control and reproducibility (e.g., DVC, MLOps) - Data management and governance - Collaboration between Data Scientists, Data Engineers, and ML Engineers |
| Automating and orchestrating ML pipelines | - Vertex AI Pipelines (Kubeflow Pipelines) - CI/CD for ML systems - Triggering and scheduling pipelines |
| Monitoring ML solutions | - Performance monitoring and drift detection - Model retraining strategies - Logging and alerting (Cloud Monitoring) |
| Architecting low-code ML solutions | - AutoML capabilities and implementation - Implementing BigQuery ML for basic models - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) |
| Serving and scaling models | - Hardware accelerators (GPU/TPU) in serving - Model optimization (Quantization, Distillation) - Online prediction (Vertex AI Prediction) - Batch prediction |
>> Professional-Machine-Learning-Engineer Exam Dump <<
The contents of our Professional-Machine-Learning-Engineer study materials are all compiled by industry experts based on the examination outlines and industry development trends over the years. Professional-Machine-Learning-Engineer exam guide is not simply a patchwork of test questions, but has its own system and levels of hierarchy, which can make users improve effectively. Our Professional-Machine-Learning-Engineer Study Materials contain test papers prepared by examination specialists according to the characteristics and scope of different subjects. And if you study with our Professional-Machine-Learning-Engineer exam questions, you are bound to pass the Professional-Machine-Learning-Engineer exam.
NEW QUESTION # 282
You work for a gaming company that has millions of customers around the world. All games offer a chat feature that allows players to communicate with each other in real time. Messages can be typed in more than 20 languages and are translated in real time using the Cloud Translation API.
You have been asked to build an ML system to moderate the chat in real time while assuring that the performance is uniform across the various languages and without changing the serving infrastructure.
You trained your first model using an in-house word2vec model for embedding the chat messages translated by the Cloud Translation API. However, the model has significant differences in performance across the different languages. How should you improve it?
Answer: B
Explanation:
Since the performance of the model varies significantly across different languages, it suggests that the translation process might have introduced some noise in the chat messages, making it difficult for the model to generalize across languages. One way to address this issue is to train a classifier using the chat messages in their original language.
NEW QUESTION # 283
You are an ML engineer at a travel company. You have been researching customers' travel behavior for many years, and you have deployed models that predict customers' vacation patterns. You have observed that customers' vacation destinations vary based on seasonality and holidays; however, these seasonal variations are similar across years. You want to quickly and easily store and compare the model versions and performance statistics across years. What should you do?
Answer: C
NEW QUESTION # 284
You are developing a model to predict whether a failure will occur in a critical machine part. You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook. You want to log data and track artifacts from each run. How should you set up your experiments?
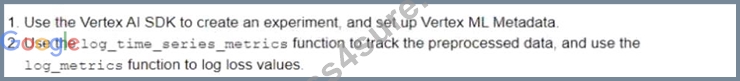
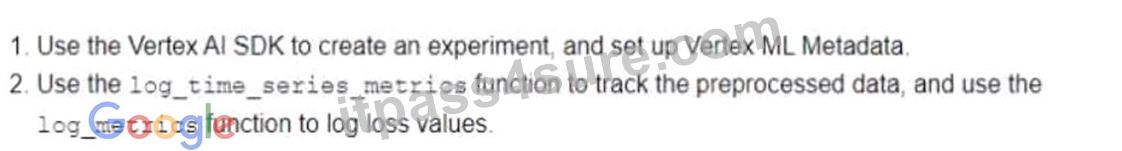
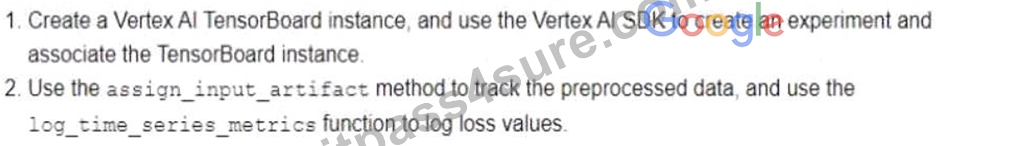
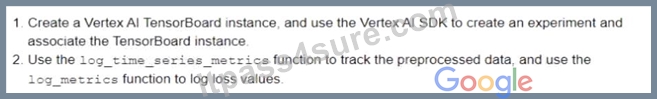
Answer: B
Explanation:
The option A is the most suitable solution for logging data and tracking artifacts from each run of a model development experiment in a Vertex AI Workbench notebook. Vertex AI Workbench is a service that allows you to create and run interactive notebooks on Google Cloud. You can use Vertex AI Workbench to experiment with different preprocessing and modeling approaches for your time series prediction problem.
You can also use the Vertex AI TensorBoard instance and the Vertex AI SDK to create an experiment and associate the TensorBoard instance. TensorBoard is a tool that allows you to visualize and monitor the metrics and artifacts of your ML experiments. You can use the Vertex AI SDK to create an experiment object, which is a logical grouping of runs that share a common objective. You can also use the Vertex AI SDK to associate the experiment object with a TensorBoard instance, which is a managed service that hosts a TensorBoard web app. By using the Vertex AI TensorBoard instance and the Vertex AI SDK, you can easily set up and manage your experiments, and access the TensorBoard web app from the Vertex AI console. You can also use the log_time_series_metrics function and the log_metrics function to log data and track artifacts from each run.
The log_time_series_metrics function is a function that allows you to log the time series data, such as the multivariate time series and the labels, to the TensorBoard instance. The log_metrics function is a function that allows you to log the scalar metrics, such as the loss values, to the TensorBoard instance. By using these functions, you can record the data and artifacts from each run of your experiment, and compare them in the TensorBoard web app. You can also use the TensorBoard web app to visualize the data and artifacts, such as the time series plots, the scalar charts, the histograms, and the distributions. By using the Vertex AI TensorBoard instance, the Vertex AI SDK, and the log functions, you can log data and track artifacts from each run of your experiment in a Vertex AI Workbench notebook. References:
* Vertex AI Workbench documentation
* Vertex AI TensorBoard documentation
* Vertex AI SDK documentation
* log_time_series_metrics function documentation
* log_metrics function documentation
* [Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
NEW QUESTION # 285
You developed a custom model by using Vertex Al to forecast the sales of your company s products based on historical transactional data You anticipate changes in the feature distributions and the correlations between the features in the near future You also expect to receive a large volume of prediction requests You plan to use Vertex Al Model Monitoring for drift detection and you want to minimize the cost. What should you do?
Answer: B
Explanation:
The best option for using Vertex AI Model Monitoring for drift detection and minimizing the cost is to use the features and the feature attributions for monitoring, and set a prediction-sampling-rate value that is closer to 0 than 1. This option allows you to leverage the power and flexibility of Google Cloud to detect feature drift in the input predict requests for custom models, and reduce the storage and computation costs of the model monitoring job. Vertex AI Model Monitoring is a service that can track and compare the results of multiple machine learning runs. Vertex AI Model Monitoring can monitor the model's prediction input data for feature skew and drift. Feature drift occurs when the feature data distribution in production changes over time. If the original training data is not available, you can enable drift detection to monitor your models for feature drift.
Vertex AI Model Monitoring uses TensorFlow Data Validation (TFDV) to calculate the distributions and distance scores for each feature, and compares them with a baseline distribution. The baseline distribution is the statistical distribution of the feature's values in the training data. If the training data is not available, the baseline distribution is calculated from the first 1000 prediction requests that the model receives. If the distance score for a feature exceeds an alerting threshold that you set, Vertex AI Model Monitoring sends you an email alert. However, if you use a custom model, you can also enable feature attribution monitoring, which can provide more insights into the feature drift. Feature attribution monitoring analyzes the feature attributions, which are the contributions of each feature to the prediction output. Feature attribution monitoring can help you identify the features that have the most impact on the model performance, and the features that have the most significant drift over time. Feature attribution monitoring can also help you understand the relationship between the features and the prediction output, and the correlation between the features1. The prediction-sampling-rate is a parameter that determines the percentage of prediction requests that are logged and analyzed by the model monitoring job. Using a lower prediction-sampling-rate can reduce the storage and computation costs of the model monitoring job, but also the quality and validity of the data. Using a lower prediction-sampling-rate can introduce sampling bias and noise into the data, and make the model monitoring job miss some important features or patterns of the data. However, using a higher prediction-sampling-rate can increase the storage and computation costs of the model monitoring job, and also the amount of data that needs to be processed and analyzed. Therefore, there is a trade-off between the prediction-sampling-rate and the cost and accuracy of the model monitoring job, and the optimal prediction-sampling-rate depends on the business objective and the data characteristics2. By using the features and the feature attributions for monitoring, and setting a prediction-sampling-rate value that is closer to 0 than 1, you can use Vertex AI Model Monitoring for drift detection and minimize the cost.
The other options are not as good as option D, for the following reasons:
* Option A: Using the features for monitoring and setting a monitoring-frequency value that is higher than the default would not enable feature attribution monitoring, and could increase the cost of the model monitoring job. The monitoring-frequency is a parameter that determines how often the model monitoring job analyzes the logged prediction requests and calculates the distributions and distance
* scores for each feature. Using a higher monitoring-frequency can increase the frequency and timeliness of the model monitoring job, but also the computation costs of the model monitoring job. Moreover, using the features for monitoring would not enable feature attribution monitoring, which can provide more insights into the feature drift and the model performance1.
* Option B: Using the features for monitoring and setting a prediction-sampling-rate value that is closer to
1 than 0 would not enable feature attribution monitoring, and could increase the cost of the model monitoring job. The prediction-sampling-rate is a parameter that determines the percentage of prediction requests that are logged and analyzed by the model monitoring job. Using a higher prediction-sampling-rate can increase the quality and validity of the data, but also the storage and computation costs of the model monitoring job. Moreover, using the features for monitoring would not enable feature attribution monitoring, which can provide more insights into the feature drift and the model performance12.
* Option C: Using the features and the feature attributions for monitoring and setting a monitoring-frequency value that is lower than the default would enable feature attribution monitoring, but could reduce the frequency and timeliness of the model monitoring job. The monitoring-frequency is a parameter that determines how often the model monitoring job analyzes the logged prediction requests and calculates the distributions and distance scores for each feature. Using a lower monitoring-frequency can reduce the computation costs of the model monitoring job, but also the frequency and timeliness of the model monitoring job. This can make the model monitoring job less responsive and effective in detecting and alerting the feature drift1.
References:
* Preparing for Google Cloud Certification: Machine Learning Engineer, Course 3: Production ML Systems, Week 4: Evaluation
* Google Cloud Professional Machine Learning Engineer Exam Guide, Section 3: Scaling ML models in production, 3.3 Monitoring ML models in production
* Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6:
Production ML Systems, Section 6.3: Monitoring ML Models
* Using Model Monitoring
* Understanding the score threshold slider
NEW QUESTION # 286
You are designing an architecture with a serverless ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.
The proposed architecture has the following flow: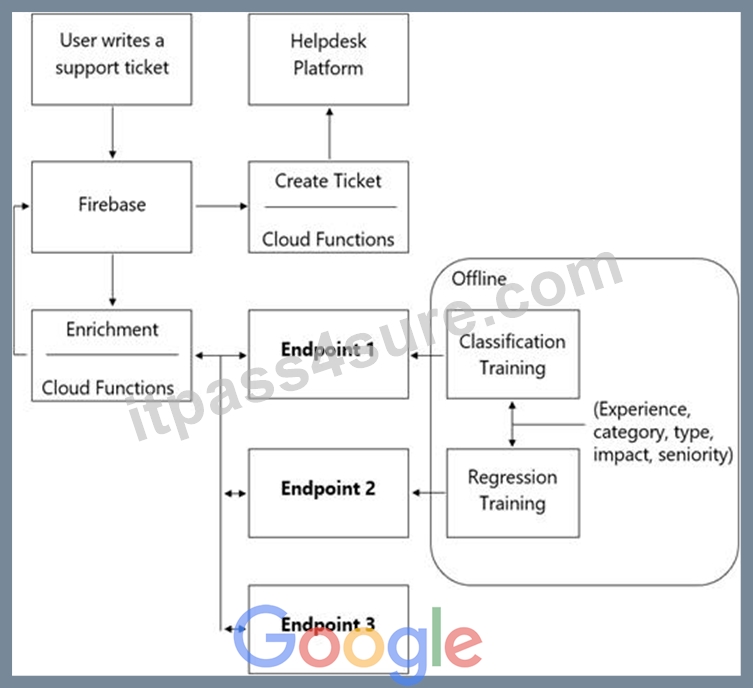
Which endpoints should the Enrichment Cloud Functions call?
Answer: D
Explanation:
The architecture has the following flow:
A user writes a ticket to Firebase, which triggers a Cloud Function.
- The Cloud Function calls 3 different endpoints to enrich the ticket:
- An AI Platform endpoint, where the function can predict the priority.
- An AI Platform endpoint, where the function can predict the resolution time.
- The Natural Language API to do sentiment analysis and word salience.
- For each reply, the Cloud Function updates the Firebase real-time database.
- The Cloud Function then creates a ticket into the helpdesk platform using the RESTful API.
https://cloud.google.com/architecture/architecture-of-a-serverless-ml-model#architecture
NEW QUESTION # 287
......
Mock tests are outstandingly worked for you to make heads or tails of your goofs while giving Professional-Machine-Learning-Engineer Exam. Google Professional-Machine-Learning-Engineer gives practice material that is as per the legitimate Google Professional-Machine-Learning-Engineer exam. A free demo is other than open to test the parts prior to buying the entire thing for the Professional-Machine-Learning-Engineer Exam. You can pass Google Professional-Machine-Learning-Engineer certification on the off chance that you use Google Professional-Machine-Learning-Engineer Dumps material.
Key Professional-Machine-Learning-Engineer Concepts: https://www.itpass4sure.com/Professional-Machine-Learning-Engineer-practice-exam.html
2026 Latest itPass4sure Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1UHWIa3cBai6l1nFVjpWAVboa8DofpK_-