有了Microsoft AI-500認證考試的證書就相當於人生有了個新的里程牌,工作將會有很大的提升,相信作為IT行業人士的每個人都很想擁有吧。很多人都在討論說這麼好的一個證書是很難通過的,實際上確實通過率是相當的低。沒有做過任何的努力當然是不容易通過的,畢竟通過Microsoft AI-500認證考試需要相當過硬的專業知識。我們NewDumps是可以為你提供通過Microsoft AI-500認證考試捷徑的網站。我們NewDumps有針對Microsoft AI-500認證考試的培訓工具,可以有效的確保你通過Microsoft AI-500認證考試,獲得Microsoft AI-500認證考試證書。而且我們還可以幫你節約很多時間,這樣一個可以花更少時間更少金錢就可以獲得如此有價值的證書的方案對你是非常划算的。
| Section | Weight | Objectives |
|---|---|---|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Develop multi-agent solutions in Azure | 30-35% | - Implement agent memory, context management, and knowledge integration
|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize prompt and model performance
|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
現在有許多IT培訓機構都能為你提供Microsoft AI-500 認證考試相關的培訓資料,但通常考生通過這些網站得不到詳細的資料。因為他們提供的關於Microsoft AI-500 認證考試資料都比較寬泛,不具有針對性,所以吸引不了考生的注意力。
問題 #20
You have a Microsoft Foundry agent built by using LangGraph. The agent retrieves policy content from a vector store. The LangGraph orchestration runs in Azure Container Apps, and the operations team uses Azure Monitor to inspect agent runs.
You discover that the vector store is sometimes unreachable during Azure regional maintenance windows You need to configure the tool ecosystem to ensure that the agent can answer policy questions during outages The solution must meet the following requirements:
* Use the project vector store without adding a local retrieval node for the primary path.
* Run the cached-policy lookup in the same compute environment as the LangGraph code.
* Emit agent, model, and tool spans that can be inspected in Azure Monitor How should you configure the tool ecosystem? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.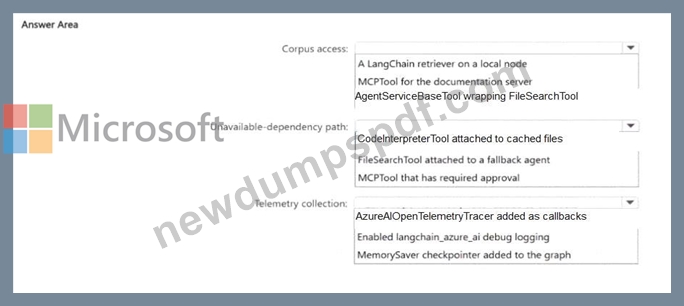
答案:
解題說明: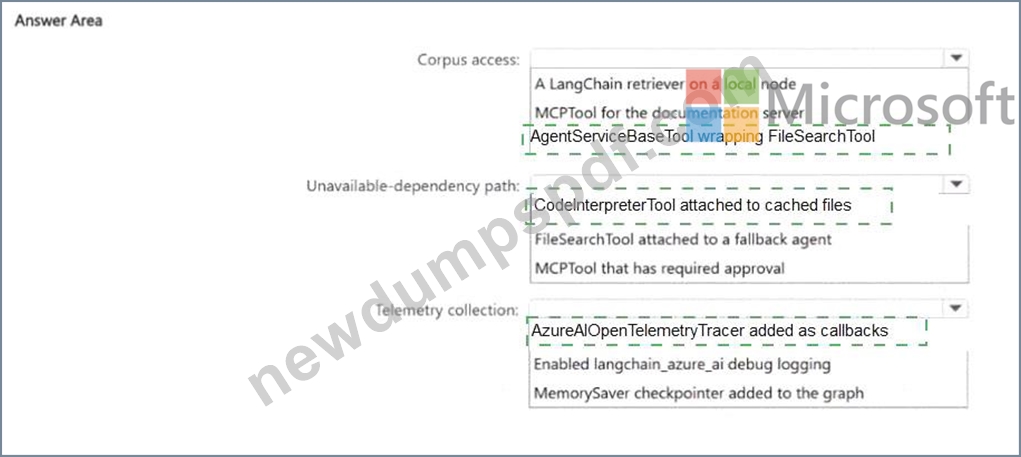
Explanation:
Corpus access: AgentServiceBaseTool wrapping FileSearchTool; Outage fallback: No listed option fully satisfies the requirement to run the cached-policy lookup in the same Azure Container Apps compute; Telemetry: AzureAIOpenTelemetryTracer added as callbacks.
Current Microsoft LangGraph integration guidance supports wrapping Foundry ' s FileSearchTool through AgentServiceBaseTool for the primary project-vector-store path and attaching AzureAIOpenTelemetryTracer through LangGraph callbacks for OpenTelemetry traces. The problematic part is the proposed outage fallback. Code Interpreter is a Foundry-hosted built-in tool, so it does not execute in the same Azure Container Apps compute environment as the LangGraph application. That means a CodeInterpreterTool- based fallback cannot satisfy the explicit same-compute requirement. A technically correct design would use a local LangGraph/LangChain callable or tool over cached policy content mounted or stored with the Container Apps workload. Because that local-tool option is absent from the answer set, there is no fully valid listed selection for the fallback row. The updated answer therefore preserves the two valid selections and explicitly identifies the missing valid option rather than endorsing an inconsistent one. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents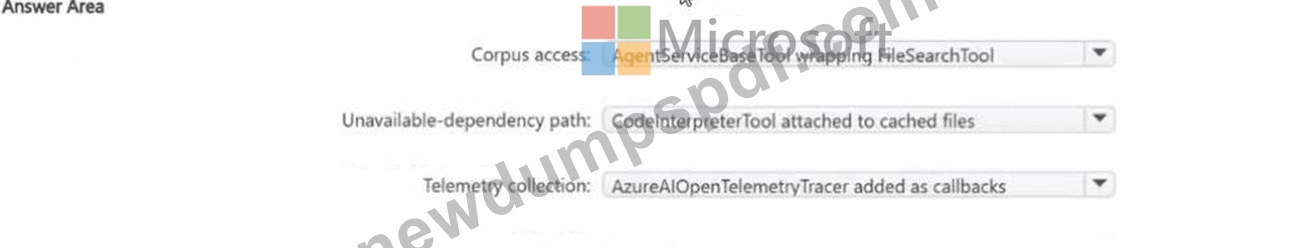
問題 #21
You are designing a Microsoft Foundry multi-agent solution. The solution includes a triage agent that receives a request and passes the request to one of three specialist agents.
Only one agent will be active at a time. The active agent must be able to transfer control to a better-suited agent based on context.
Which orchestration pattern should you recommend for the planned solution?
答案:A
解題說明:
Only one agent should be active at a time, and the active agent must be able to transfer control dynamically when another specialist is better suited. Microsoft Agent Framework defines handoff orchestration for precisely that situation: task and conversational ownership move from one agent to another according to context. Concurrent orchestration would activate multiple specialists at the same time, contradicting the requirement. Sequential orchestration follows a predetermined order rather than allowing contextual transfer.
Group chat keeps multiple agents participating in a shared conversation rather than modeling single-owner control. The decisive requirement is therefore transfer of ownership, not merely calling another agent for a subtask. That makes B, handoff, the correct orchestration pattern. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Handoff orchestration
問題 #22
You have a production-readiness review that includes the following Microsoft Foundry Agent Service Model Context Protocol (MCP) tool configuration, discovered MCP tool metadata, and quality-gate rules.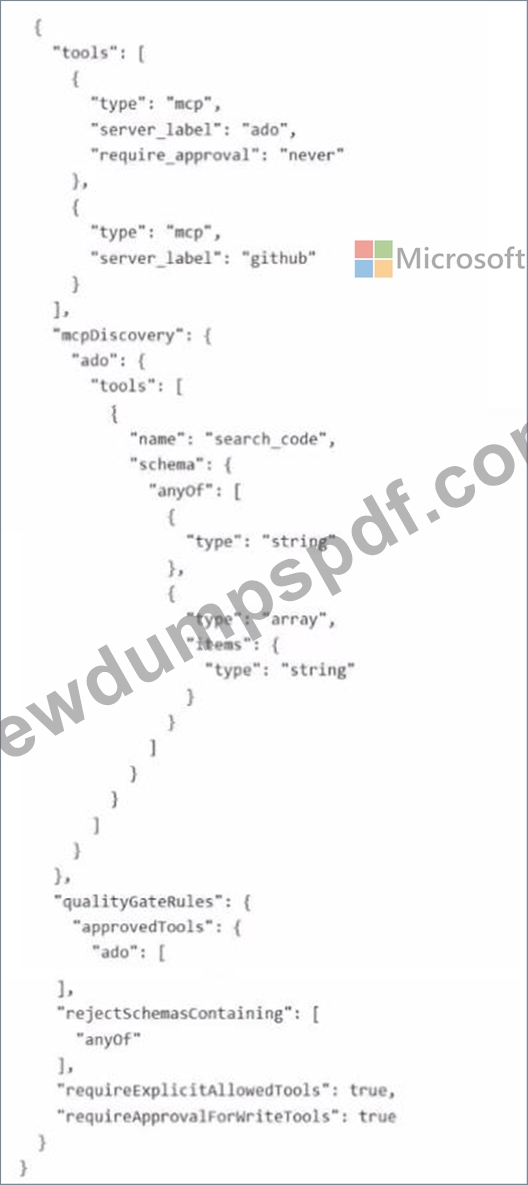
For each of the following statements, select Yes if the statement is true Otherwise, select No.
NOTE: Each correct selection is worth one point.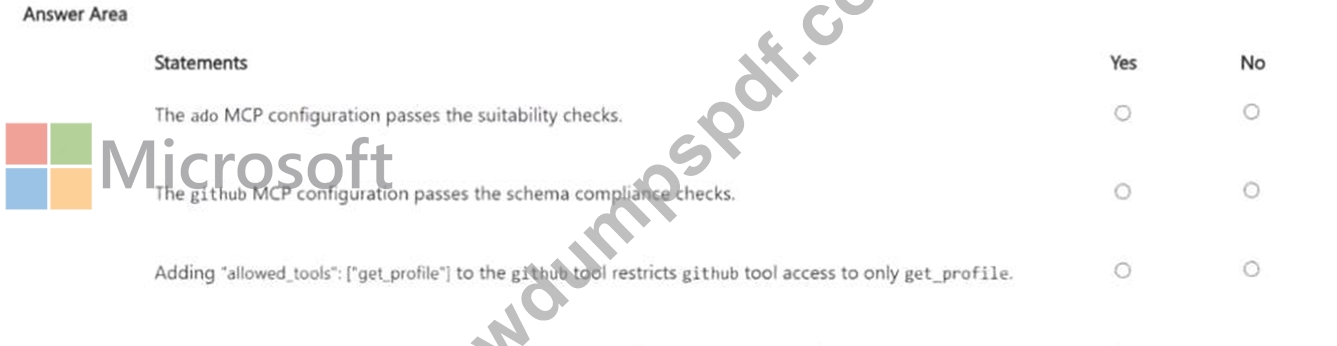
答案:
解題說明: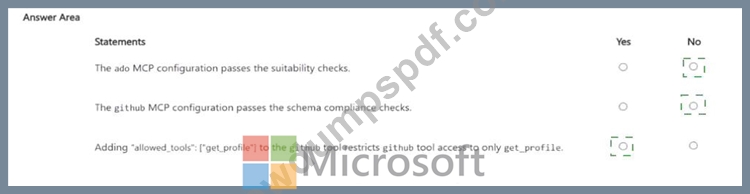
Explanation:
No / No / Yes
The ADO MCP configuration does not satisfy the stated production gate because it lacks the required allowed- tool restriction and disables approval; its discovered schema also conflicts with the gate ' s schema restrictions. The GitHub configuration likewise cannot be considered schema-compliant based on the shown metadata. The third statement, however, is true: Microsoft Foundry MCP tool configuration supports an
`allowed_tools` allowlist that limits which discovered MCP tools are exposed to the agent. Adding ` " allowed_tools " : [ " get_profile " ]` therefore restricts the GitHub MCP integration to that tool, assuming the name matches the discovered tool exactly. This control is materially stronger tha n relying on prompt instructions because excluded tools are not presented as available choices. The corrected sequence is No, No, Yes. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Foundry agents - Model Context Protocol tools
問題 #23
You need to design a solution to resolve the Scheduling agent issue.
What should you include in the design?
答案:C
解題說明:
The Scheduling agent ' s MCP server fails transiently during peak load. Microsoft Azure reliability guidance recommends retries with exponential backoff for transient faults so that callers do not immediately repeat requests at the same rate and worsen a temporarily overloaded dependency. Immediate retries can create a retry storm, especially when many agent requests encounter the same service condition. Routing the tool call through a different agent does not remove the underlying MCP dependency and would only add coupling. A well-designed retry policy should normally include a bounded retry count, increasing delay, jitter where appropriate, and respect for server-provided retry guidance when available. The scenario asks which design element directly addresses the timeouts, and exponential backoff is the established resilience pattern for transient service saturation. Therefore A is the correct choice. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Azure Well-Architected Framework - Handle transient faults
問題 #24
You have a Microsoft Foundry resource that hosts Azure OpenAI model deployments for three projects. Each project is for a different business unit. The projects share the same Foundry resource.
You need to implement a Microsoft Cost Management view that separates the shared model spend by the project The solution must meet the following requirements:
* Use cost data that can be reconciled by using Azure Cost Management.
* Minimize manual tagging.
What should you use?
答案:B
解題說明:
When multiple projects share one Foundry resource, grouping costs only by Azure resource cannot distinguish project consumption because the resource boundary is shared. Microsoft Foundry integrates with Azure Cost Management by attributing model usage to project metadata/tags, allowing a Cost Analysis view to filter shared resource spending by project. This supports showback or chargeback without requiring administrators to manually tag every usage event. Subscription-level service filters or meter grouping identify the service or billing meter but not which of the three business-unit projects generated the usage. Therefore a Foundry-resource-scoped Cost Analysis view filtered by the project tag is the configuration that both reconciles to Azure Cost Management and minimizes manual tagging. D remains correct. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - Manage costs
問題 #25
......
怎樣才能確保我們的生活可更快的得到改善?你需要通過AI-500認證考試,獲得證書。而NewDumps是IT專業人士的最佳選擇,獲得AI-500認證是IT職業發展的有力保證,我們高品質的題庫能幫助你做到這一點。AI-500考試題庫也會不定期的更新,為你提供最有效的學習資料。使用我們的AI-500考試題庫進行考前復習,可以節約你大量的學習時間和費用,這是最適合獲得AI-500認證的所必須的學習資料。
AI-500認證: https://www.newdumpspdf.com/AI-500-exam-new-dumps.html