P.S. Free & New ARA-C01 dumps are available on Google Drive shared by Exam4Labs: https://drive.google.com/open?id=11urpnNvZwqNYvgLql_2d8Je1NOnwXV3F
Exam4Labs provides accurate valid products which are regards as the best provider in this field since 2015. If you still hesitate how to choose ARA-C01 new exam cram review, many candidates will advise us to you. Although IT exams are difficult it is key to IT staff's career so that IT staff can have an achievement. So our Snowflake ARA-C01 new exam cram review can help thousands of candidates to pass exam and get certification they dream.
| Section | Weight | Objectives |
|---|---|---|
| Snowflake Architecture | 30% | - Data sharing architecture design - Data protection and recovery strategies - Development lifecycle and workload support - Object hierarchy and architectural impact - Data modeling and use cases |
| Performance Optimization | 20% | - Virtual warehouse configuration and sizing - Query performance tuning - Clustering and partitioning strategies - Cost optimization and resource management |
| Accounts and Security | 25% | - Security, compliance and governance architecture - Account and database strategy design - Security principles and implementation scenarios |
| Data Engineering | 25% | - Transformation and processing frameworks - Data pipeline and integration design - Data loading and unloading solutions |
>> Valid Study Snowflake ARA-C01 Questions <<
With the complete collection of Snowflake practice questions and answers, our website offers you the most reliable ARA-C01 vce files for your exam preparation. In the ARA-C01 actual test we have compiled real questions and answers so that you can prepare and pas exam in your first attempt. You can also check the demo of ARA-C01 Dumps PDF before you decide to buy it.
NEW QUESTION # 75
You have turned on auto clustering in your table.
How will you monitor how much credit is getting burnt for the auto clustering in the past week for a specific table?
Answer: B
NEW QUESTION # 76
How can the Snowflake context functions be used to help determine whether a user is authorized to see data that has column-level security enforced? (Select TWO).
Answer: C,E
Explanation:
Snowflake context functions are functions that return information about the current session, user, role, warehouse, database, schema, or object. They can be used to help determine whether a user is authorized to see data that has column-level security enforced by setting masking policy conditions based on the context functions. The following context functions are relevant for column-level security:
* current_role: This function returns the name of the role in use for the current session. It can be used to set masking policy conditions that target the current session and are not affected by the execution context of the SQL statement. For example, a masking policy condition using current_role can allow or deny access to a column based on the role that the user activated in the session.
* invoker_role: This function returns the name of the executing role in a SQL statement. It can be used to set masking policy conditions that target the executing role and are affected by the execution context of the SQL statement. For example, a masking policy condition using invoker_role can allow or deny access to a column based on the role that the user specified in the SQL statement, such as using the AS ROLE clause or a stored procedure.
* is_role_in_session: This function returns TRUE if the user's current role in the session (i.e. the role returned by current_role) inherits the privileges of the specified role. It can be used to set masking policy conditions that involve role hierarchy and privilege inheritance. For example, a masking policy condition using is_role_in_session can allow or deny access to a column based on whether the user's current role is a lower privilege role in the specified role hierarchy.
The other options are not valid ways to use the Snowflake context functions for column-level security:
* Set masking policy conditions using is_role_in_session targeting the role in use for the current account.
This option is incorrect because is_role_in_session does not target the role in use for the current account, but rather the role in use for the current session. Also, the current account is not a role, but rather a logical entity that contains users, roles, warehouses, databases, and other objects.
* Determine if there are ownership privileges on the masking policy that would allow the use of any function. This option is incorrect because ownership privileges on the masking policy do not affect the use of any function, but rather the ability to create, alter, or drop the masking policy. Also, this is not a way to use the Snowflake context functions, but rather a way to check the privileges on the masking policy object.
* Assign the accountadmin role to the user who is executing the object. This option is incorrect because assigning the accountadmin role to the user who is executing the object does not involve using the Snowflake context functions, but rather granting the highest-level role to the user. Also, this is not a recommended practice for column-level security, as it would give the user full access to all objects and data in the account, which could compromise data security and governance.
Context Functions
Advanced Column-level Security topics
Snowflake Data Governance: Column Level Security Overview
Data Security Snowflake Part 2 - Column Level Security
NEW QUESTION # 77
An Architect entered the following commands in sequence: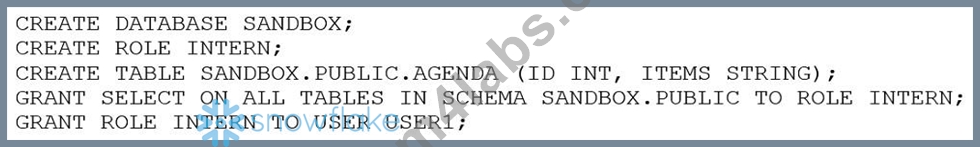
USER1 cannot find the table.
Which of the following commands does the Architect need to run for USER1 to find the tables using the Principle of Least Privilege? (Choose two.)
Answer: A,D
NEW QUESTION # 78
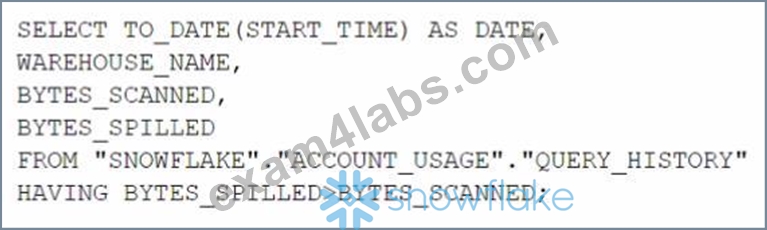
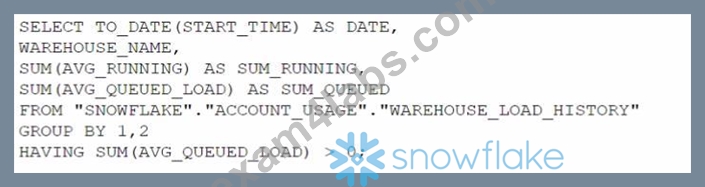
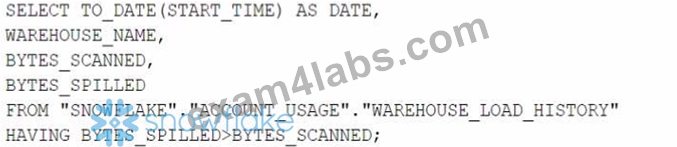
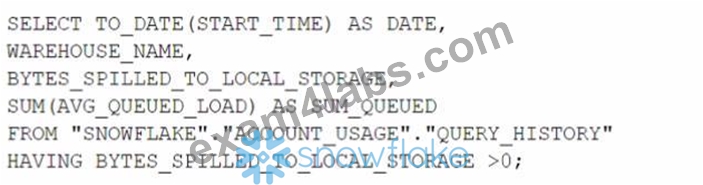
Which query will identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse to improve the performance of a particular workload?
Answer: C
Explanation:
A multi-cluster warehouse is a virtual warehouse that can scale compute resources by adding or removing clusters based on the workload demand. A multi-cluster warehouse can improve the performance of a particular workload by reducing the query queue time and the data spillage to local storage. To identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse, you need to analyze the query history and look for the following indicators:
* High average queued load: This metric shows the average number of queries waiting in the queue for each warehouse cluster. A high value indicates that the warehouse is overloaded and cannot handle the concurrency demand.
* High bytes spilled to local storage: This metric shows the amount of data that was spilled from memory to local disk during query processing. A high value indicates that the warehouse size is too small and cannot fit the data in memory.
* High variation in workload: This metric shows the fluctuation in the number of queries submitted to the warehouse over time. A high variation indicates that the workload is unpredictable and dynamic, and requires a flexible scaling policy.
The query in option C is the best one to identify these indicators, as it selects the date, warehouse name, bytes spilled to local storage, and sum of average queued load from the query history table, and filters the results where bytes spilled to local storage is greater than zero. This query will show the days and warehouses that experienced data spillage and high queue time, and could benefit from a multi-cluster warehouse with auto-scale mode.
The query in option A is not correct, as it only selects the date and warehouse name, and does not include any metrics to measure the performance of the workload. The query in option B is not correct, as it selects the date, warehouse name, and average execution time, which is not a good indicator of the need for a multi-cluster warehouse. The query in option D is not correct, as it selects the date, warehouse name, and average credits used, which is not a good indicator of the need for a multi-cluster warehouse either.
References: Multi-cluster Warehouses, Query History View, Reducing Queues
NEW QUESTION # 79
What step will im the performance of queries executed against an external table?
Answer: D
Explanation:
Partitioning an external table is a technique that improves the performance of queries executed against the table by reducing the amount of data scanned. Partitioning an external table involves creating one or more partition columns that define how the table is logically divided into subsets of data based on the values in those columns. The partition columns can be derived from the file metadata (such as file name, path, size, or modification time) or from the file content (such as a column value or a JSON attribute). Partitioning an external table allows the query optimizer to prune the files that do not match the query predicates, thus avoiding unnecessary data scanning and processing2 The other options are not effective steps for improving the performance of queries executed against an external table:
Shorten the names of the source files. This option does not have any impact on the query performance, as the file names are not used for query processing. The file names are only used for creating the external table and displaying the query results3 Convert the source files' character encoding to UTF-8. This option does not affect the query performance, as Snowflake supports various character encodings for external table files, such as UTF-8, UTF-16, UTF-32, ISO-8859-1, and Windows-1252. Snowflake automatically detects the character encoding of the files and converts them to UTF-8 internally for query processing4 Use an internal stage instead of an external stage to store the source files. This option is not applicable, as external tables can only reference files stored in external stages, such as Amazon S3, Google Cloud Storage, or Azure Blob Storage. Internal stages are used for loading data into internal tables, not external tables5 References:
1: SnowPro Advanced: Architect | Study Guide
2: Snowflake Documentation | Partitioning External Tables
3: Snowflake Documentation | Creating External Tables
4: Snowflake Documentation | Supported File Formats and Compression for Staged Data Files
5: Snowflake Documentation | Overview of Stages
SnowPro Advanced: Architect | Study Guide
Partitioning External Tables
Creating External Tables
Supported File Formats and Compression for Staged Data Files
Overview of Stages
NEW QUESTION # 80
......
Snowflake ARA-C01 questions are available in PDF format. Our Snowflake ARA-C01 PDF is embedded with questions relevant to the actual exam content only. Snowflake ARA-C01 PDF is printable and portable, so you can learn with ease and share it on multiple devices. You can use this Snowflake ARA-C01 PDF on your mobile and tablet anywhere, anytime, without the internet and installation process.
ARA-C01 Latest Exam Camp: https://www.exam4labs.com/ARA-C01-practice-torrent.html
BTW, DOWNLOAD part of Exam4Labs ARA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=11urpnNvZwqNYvgLql_2d8Je1NOnwXV3F