PassTIP Databricks-Generative-AI-Engineer-Associate 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1gjuHRCaly0qF9MJcK03k-RITdZvUsc_O
PassTIP는 자격증 응시자에게Databricks Databricks-Generative-AI-Engineer-Associate 시험 준비를 위한 현재 그리고 가장 최근의 자료들을 제공하는 이 산업 영역의 리더입니다. PassTIP는Databricks Databricks-Generative-AI-Engineer-Associate덤프를 시험문제변경에 따라 계속 갱신하여 고객님께서 받은 것이Databricks Databricks-Generative-AI-Engineer-Associate 시험의 가장 최신 기출문제임을 보증해드립니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
>> Databricks-Generative-AI-Engineer-Associate시험패스 가능한 공부하기 <<
PassTIP 에서 출시한Databricks인증Databricks-Generative-AI-Engineer-Associate 덤프는Databricks인증Databricks-Generative-AI-Engineer-Associate 실제시험의 출제범위와 출제유형을 대비하여 제작된 최신버전 덤프입니다. 시험문제가 바뀌면 제일 빠른 시일내에 덤프를 업데이트 하도록 최선을 다하고 있으며 1년 무료 업데이트서비스를 제공해드립니다. 1년 무료 업데이트서비스를 제공해드리기에 시험시간을 늦추어도 시험성적에 아무런 페를 끼치지 않습니다. PassTIP에 믿음을 느낄수 있도록 구매사이트마다 무료샘플 다운가능기능을 설치하였습니다.무료샘플을 체험해보시고PassTIP을 선택해주세요.
질문 # 78
A Generative Al Engineer is building a system which will answer questions on latest stock news articles.
Which will NOT help with ensuring the outputs are relevant to financial news?
정답:A
설명:
In the context of ensuring that outputs are relevant to financial news, increasing compute power (option B) does not directly improve therelevanceof the LLM-generated outputs. Here's why:
* Compute Power and Relevancy:Increasing compute power can help the model process inputs faster, but it does not inherentlyimprove therelevanceof the answers. Relevancy depends on the data sources, the retrieval method, and the filtering mechanisms in place, not on how quickly the model processes the query.
* What Actually Helps with Relevance:Other methods, like content filtering, guardrails, or manual review, can directly impact the relevance of the model's responses by ensuring the model focuses on pertinent financial content. These methods help tailor the LLM's responses to the financial domain and avoid irrelevant or harmful outputs.
* Why Other Options Are More Relevant:
* A (Comprehensive Guardrail Framework): This will ensure that the model avoids generating content that is irrelevant or inappropriate in the finance sector.
* C (Profanity Filter): While not directly related to financial relevancy, ensuring the output is clean and professional is still important in maintaining the quality of responses.
* D (Manual Review): Incorporating human oversight to catch and correct issues with the LLM's output ensures the final answers are aligned with financial content expectations.
Thus, increasing compute power does not help with ensuring the outputs are more relevant to financial news, making option B the correct answer.
질문 # 79
A Generative AI Engineer I using the code below to test setting up a vector store: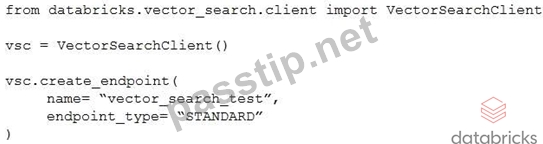
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
정답:B
설명:
Context : The Generative AI Engineer is setting up a vector store using Databricks ' VectorSearchClient.
This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options :
* Option A: vsc.get_index() : This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index() : After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index() : This function would create an index that directly accesses the data without synchronization. While also a valid approach, it ' s less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search() : This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B .
질문 # 80
A Generative Al Engineer is tasked with developing a RAG application that will help a small internal group of experts at their company answer specific questions, augmented by an internal knowledge base. They want the best possible quality in the answers, and neither latency nor throughput is a huge concern given that the user group is small and they're willing to wait for the best answer. The topics are sensitive in nature and the data is highly confidential and so, due to regulatory requirements, none of the information is allowed to be transmitted to third parties.
Which model meets all the Generative Al Engineer's needs in this situation?
정답:D
설명:
Problem Context : The Generative AI Engineer needs a model for a Retrieval-Augmented Generation (RAG) application that provides high-quality answers, where latency and throughput are not major concerns.
The key factors are confidentiality and sensitivity of the data, as well as the requirement for all processing to be confined to internal resources without external data transmission.
Explanation of Options :
* Option A: Dolly 1.5B : This model does not typically support RAG applications as it ' s more focused on image generation tasks.
* Option B: OpenAI GPT-4 : While GPT-4 is powerful for generating responses, its standard deployment involves cloud-based processing, which could violate the confidentiality requirements due to external data transmission.
* Option C: BGE-large : The BGE (Big Green Engine) large model is a suitable choice if it is configured to operate on-premises or within a secure internal environment that meets regulatory requirements. Assuming this setup, BGE-large can provide high-quality answers while ensuring that data is not transmitted to third parties, thus aligning with the project ' s sensitivity and confidentiality needs.
* Option D: Llama2-70B : Similar to GPT-4, unless specifically set up for on-premises use, it generally relies on cloud-based services, which might risk confidential data exposure.
Given the sensitivity and confidentiality concerns, BGE-large is assumed to be configurable for secure internal use, making it the optimal choice for this scenario.
질문 # 81
A Generative AI Engineer is designing a RAG application for answering user questions on technical regulations as they learn a new sport.
What are the steps needed to build this RAG application and deploy it?
정답:D
설명:
The Generative AI Engineer needs to follow a methodical pipeline to build and deploy a Retrieval- Augmented Generation (RAG) application. The steps outlined in option B accurately reflect this process:
* Ingest documents from a source : This is the first step, where the engineer collects documents (e.g., technical regulations) that will be used for retrieval when the application answers user questions.
* Index the documents and save to Vector Search : Once the documents are ingested, they need to be embedded using a technique like embeddings (e.g., with a pre-trained model like BERT) and stored in a vector database (such as Pinecone or FAISS). This enables fast retrieval based on user queries.
* User submits queries against an LLM : Users interact with the application by submitting their queries. These queries will be passed to the LLM.
* LLM retrieves relevant documents : The LLM works with the vector store to retrieve the most relevant documents based on their vector representations.
* LLM generates a response : Using the retrieved documents, the LLM generates a response that is tailored to the user ' s question.
* Evaluate model : After generating responses, the system must be evaluated to ensure the retrieved documents are relevant and the generated response is accurate. Metrics such as accuracy, relevance, and user satisfaction can be used for evaluation.
* Deploy it using Model Serving : Once the RAG pipeline is ready and evaluated, it is deployed using a model-serving platform such as Databricks Model Serving. This enables real-time inference and response generation for users.
By following these steps, the Generative AI Engineer ensures that the RAG application is both efficient and effective for the task of answering technical regulation questions.
질문 # 82
A generative AI engineer is deploying an AI agent authored with MLflow's ChatAgent interface for a retail company ' s customer support system on Databricks. The agent must handle thousands of inquiries daily, and the engineer needs to track its performance and quality in real-time to ensure it meets service-level agreements. Which metrics are automatically captured by default and made available for monitoring when the agent is deployed using the Mosaic AI Agent Framework?
정답:C
설명:
When deploying an agent via the Mosaic AI Agent Framework (which leverages Databricks Model Serving), operational metrics are captured automatically by default. These include system-level telemetry such as the number of requests per second (volume), the time taken for the model to respond (latency), and the rate of 4xx
/5xx HTTP errors. These are essential for monitoring Service Level Agreements (SLAs). However, Quality metrics (B), such as correctness, groundedness, or adherence to custom guidelines, cannot be determined " automatically " by the serving infrastructure because they require either human feedback or an LLM-as-a- judge evaluation (using Databricks Agent Evaluation). While Databricks makes it easy to generate quality metrics using the mlflow.evaluate API or the inference table, they are not " default operational metrics " that appear without additional evaluation configuration.
질문 # 83
......
PassTIP에서 제공하는 제품들은 품질이 아주 좋으며 또 업뎃속도도 아주 빠릅니다 만약 우리가제공하는Databricks Databricks-Generative-AI-Engineer-Associate인증시험관련 덤프를 구매하신다면Databricks Databricks-Generative-AI-Engineer-Associate시험은 손쉽게 성공적으로 패스하실 수 있습니다.
Databricks-Generative-AI-Engineer-Associate최신 인증시험 기출문제: https://www.passtip.net/Databricks-Generative-AI-Engineer-Associate-pass-exam.html
참고: PassTIP에서 Google Drive로 공유하는 무료 2026 Databricks Databricks-Generative-AI-Engineer-Associate 시험 문제집이 있습니다: https://drive.google.com/open?id=1gjuHRCaly0qF9MJcK03k-RITdZvUsc_O