Snowflake SPS-C01認定試験に楽に合格する対策

ちなみに、MogiExam SPS-C01の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1pfvCr563j-ZiPGXk8PSk5s_jiOo4kRQ0
時代に対応するために、科学技術は人々の学習方法を向上させると信じています。特にこのようなペースの速い生活テンポでは、効率の高い学習を非常に重視しています。したがって、当社のSPS-C01学習資料は、過去の試験問題と現在の試験の傾向に基づいており、実際の試験環境に配置するためのこのような効果的なシミュレーション機能を設計します。高度なSPS-C01学習教材を備えた高品質のシミュレーションシステムを提供することをお約束します。シミュレーション機能により、SPS-C01トレーニングガイドの理解が容易になり、SPS-C01試験に合格できます。
Snowflake SPS-C01 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Snowpark Concepts and Architecture | 25% | - Session management and connection
- 1. Create and configure Snowpark sessions
- 2. Authentication and connection settings
- Snowpark architecture and execution model
- 1. Client-side vs server-side processing
- 2. Transformations vs actions
- 3. Lazy evaluation and DAG execution
|
| Topic 2: Performance and Best Practices | 10% | - Optimization techniques
- 1. Caching and warehouse sizing
- 2. Minimizing data movement
- 3. Query pushdown and execution plans
- Security and governance
- 1. Access control and permissions
- 2. Data protection and compliance
|
| Topic 3: Snowpark API and Development | 30% | - Python API fundamentals
- 1. Data persistence and writing results
- 2. Column operations and functions
- 3. DataFrame creation from tables, views, SQL
- Multi-language support
- 1. Environment setup and dependencies
- 2. Java and Scala API basics
|
| Topic 4: Data Transformations and Operations | 35% | - Advanced operations
- 1. Pivot and unpivot transformations
- 2. Window functions and analytics
- 3. Semi-structured data processing
- DataFrame manipulation
- 1. Filtering, sorting, grouping, aggregation
- 2. Selection, projection, renaming, casting
- 3. Joins, unions, set operations
- User-defined logic
- 1. Stored procedures with Snowpark
- 2. UDFs, UDAFs, UDTFs
|
>> SPS-C01受験対策 <<
信頼できるSPS-C01受験対策 & 合格スムーズSPS-C01模擬問題集 | 大人気SPS-C01認定資格試験
MogiExamは、すべてのユーザーから賞賛されている効果的なSPS-C01研究ブレーンダンプを候補者に提供するための信頼できるプラットフォームです。 より良い仕事を見つけるために、多くの候補者がSPS-C01試験の準備に一生懸命勉強しています。 ほとんどの人がSPS-C01試験に合格するのは簡単なことではありません。したがって、当社のウェブサイトは効率的で便利な学習プラットフォームを提供できるため、最短時間でSnowflakeのSPS-C01証明書を取得できます。 Snowflake Certified SnowPro Specialty - Snowpark試験の質問を20〜30時間学習するだけで、SPS-C01試験に自信を持って合格することができます。
Snowflake Certified SnowPro Specialty - Snowpark 認定 SPS-C01 試験問題 (Q323-Q328):
質問 # 323
You are developing a Snowpark application that uses a Python UDF to perform geocoding operations. This UDF relies on a third-party geocoding library and a large dataset of geographical data stored in a file named 'geodata.db'. The UDF needs to be operationalized with minimal latency. Which of the following strategies will result in the FASTEST execution of the UDF and optimal resource utilization?
- A. Create a Java UDF that performs the geocoding using a Java geocoding library. Upload the JAR file and 'geodata.db' to a stage and reference them using the 'imports' clause. Java UDFs always perform faster than Python UDFs.
- B. Create a custom Anaconda channel containing the geocoding library and 'geodata.db'. Configure the Snowflake account to use this channel. No need to use virtual environment.
- C. Package the geocoding library and 'geodata.db' file into a ZIP file. Upload the ZIP file to a Snowflake stage and reference it using 'imports' in the UDF definition. Ensure 'geodata.db' is loaded only once into memory per worker process using global variable and proper caching for subsequent UDF invocations. Use a virtual environment to manage package dependencies.
- D. Package the geocoding library and 'geodata.db' file into a ZIP file. Upload the ZIP file to a Snowflake stage and reference it using 'imports' in the UDF definition. Use a virtual environment to manage package dependencies.
- E. Use an external function that calls a geocoding service over the internet. Store 'geodata.db' in an S3 bucket and access it from the external function. Call the external service whenever it requires it.
正解:C
解説:
Option E is the most efficient strategy. Packaging the library and data file in a ZIP, referencing it with 'imports' , and using a global variable with caching within the UDF minimizes latency by loading the data only once per worker. It also benefits from utilizing the parallel processing capabilities of Snowpark. Using Java UDF's (C) is less efficient, unless it is highly optimized since java conversion can happen and adds overhead . Relying on external geocoding services (D) introduces network latency and is not ideal for performance. While a custom Anaconda channel (B) can simplify dependency management, it does not address the issue of loading the large 'geodata.db' file efficiently. Option A addresses the dependency managment but performance is not addressed.
質問 # 324
A data engineer is tasked with creating a Snowpark Python application that needs to access data from multiple Snowflake accounts and regions. All accounts are using Snowflake's Business Critical edition. Which of the following approaches would be the MOST efficient and maintainable for managing and switching between different Snowpark sessions in this scenario?
- A. Use a single Snowpark session object and dynamically update the connection parameters (account identifier, username, password) whenever switching to a different account and region.
- B. Create a configuration file (e.g., YAML or JSON) that stores the account identifiers and other connection details for each Snowflake account and region. Load this configuration and create separate Snowpark session objects for each account, storing them in a dictionary or list.
- C. Create a new Anaconda environment for each Snowflake account and install the necessary packages in each environment.
- D. Create separate Python scripts for each account and region, hardcoding the account identifiers and credentials within each script.
- E. Use the 'snowflake.connector.connect' method to directly establish connections without using the Snowpark Session object.
正解:B
解説:
Storing connection details in a configuration file and creating separate Snowpark session objects is the most maintainable and efficient approach. It allows for easy switching between accounts and regions without modifying the core application logic. Option A is not scalable. Option B is risky because changing connection parameters on a live session can lead to unexpected behavior. Option D bypasses Snowpark functionalities. Option E is an overkill.
質問 # 325
You are tasked with building a Snowpark application to perform sentiment analysis on customer reviews stored in a Snowflake table named 'CUSTOMER REVIEWS'. The application should be deployed as a UDF. The sentiment analysis is performed by a third-party Python library, 'sentiment_analyzer'. Due to security constraints, direct internet access is prohibited from within the Snowflake environment. What steps are necessary to ensure the 'sentiment_analyzer' library can be used by your Snowpark UDF?
- A. Use the 'packages' parameter in the UDF creation statement to specify the 'sentiment_analyzer' library from Anaconda.
- B. Package the 'sentiment_analyzer' library into a ZIP file and upload it to a Snowflake stage, then specify the ZIP in the 'imports' parameter of the UDF creation statement.
- C. Install the 'sentiment_analyzer' library using 'conda install' directly within the Snowpark session before creating the UDF.
- D. Package the 'sentiment_analyzer' library into a JAR file and upload it to a Snowflake stage, then specify the JAR in the 'imports' parameter of the UDF creation statement.
- E. Request Snowflake support to whitelist the 'sentiment_analyzer' library for direct download during UDF execution.
正解:A
解説:
The 'packages' parameter in the UDF creation statement allows specifying Python packages from the Anaconda repository, which are then automatically made available to the UDF during execution. This is the recommended approach when direct internet access is restricted. Options A and B are incorrect because these steps would be used to include a Java library, not a Python library. Option C is incorrect because you cannot directly install packages within a Snowpark session in this way. Option D is not a standard procedure.
質問 # 326
You have a Snowpark DataFrame named 'transactions' containing transaction data'. You need to create a UDTF using Python to categorize transactions into 'High Value', 'Medium Value', and 'Low Value' based on the transaction amount and the customer's region. The categorization logic requires access to a dynamically updated lookup table stored in a Snowflake stage. Which approach would be MOST efficient and scalable, minimizing data transfer and maximizing Snowpark's vectorized operations?
- A. Use a UDTF with the parameter, reading the lookup table directly into the UDTF using a Snowpark DataFrame and joining it with each batch of the 'transactions DataFrame. Materialize the result to a temporary table.
- B. Define a scalar UDF that queries the lookup table directly from Snowflake using a Snowflake connector. This avoids data transfer to the UDF but introduces external dependency and connection management overhead for each row.
- C. Use a scalar UDF, reading the lookup table from the stage for each transaction. This ensures data consistency but may incur significant overhead for each row processed.
- D. Create a vectorized UDF. Load the lookup table from the stage into the UDF's environment once during initialization. Then, process transactions in batches using pandas DataFrames within the UDF.
- E. Create a vectorized UDTF that loads the lookup table into memory during the first call, and then caches it for subsequent calls. Implement a refresh mechanism using a Snowflake external function triggered by stage updates.
正解:D
解説:
A vectorized UDF is the most efficient approach. It allows processing data in batches using pandas DataFrames, leveraging vectorized operations for faster execution. Loading the lookup table once during initialization and reusing it avoids repeated data transfer. While option E sounds appealing, caching mechanisms can get complex to manage for data recency. Snowflake stages are generally more suitable as temporary lookup tables rather than permanent caching solution as they're design for data loading operations.
質問 # 327
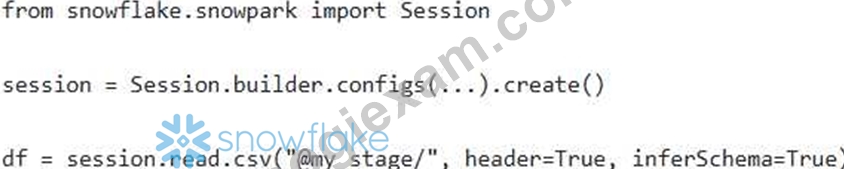
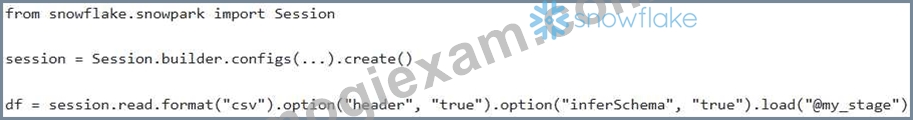
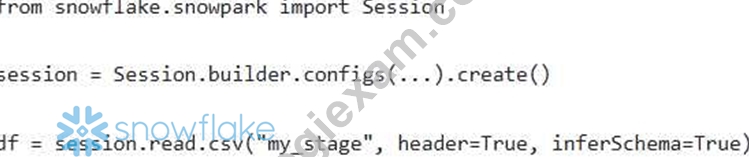
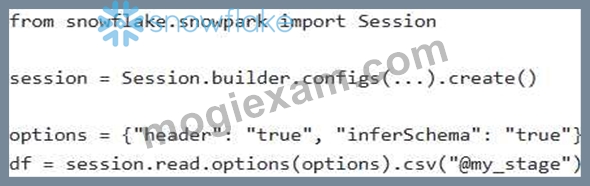
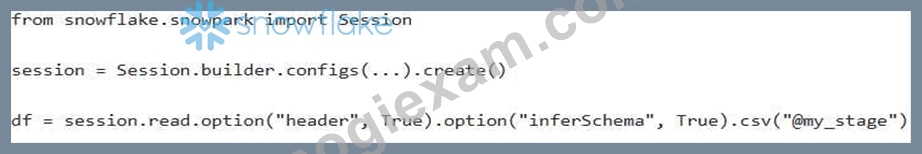
You are developing a Snowpark application that needs to read data from a set of CSV files stored in a Snowflake stage named ' my_stage'. The files have a header row and are comma-delimited. You want to use the Snowpark API to create a DataFrame from these files, automatically inferring the schema. Which of the following code snippets correctly achieves this?
正解:B
解説:
Option D is the correct way to read CSV files from a stage in Snowpark with header and schema inference using .format("csv").option(...y. Option A is close, but it doesn't use the correct syntax for specifying the stage location; it expects a file path relative to the current working directory.Option B incorrectly uses .csv()' with directly.Option C correctly passes options, but must use the load method in conjunction with format option. Option E has incorrect path specification in addition to incorrect function chain. Option D uses .load()" after setting the format and options is most appropriate.
質問 # 328
......
当社MogiExamの専門家のほとんどは、長年プロの分野で勉強しており、SPS-C01練習問題で多くの経験を蓄積しています。当社は、才能の選択にかなり慎重であり、常に専門知識とスキルのある従業員を雇用しています。専門家と作業スタッフの全員が高い責任感を維持しているため、SPS-C01試験の資料を選択して長期的なパートナーになる人が非常に多くいます。
SPS-C01模擬問題集: https://www.mogiexam.com/SPS-C01-exam.html
- 優秀なSnowflake SPS-C01受験対策 は主要材料 - 有効的なSPS-C01模擬問題集 ⛄ [ www.passtest.jp ]で▶ SPS-C01 ◀を検索し、無料でダウンロードしてくださいSPS-C01日本語版復習指南
- SPS-C01認定テキスト 🏇 SPS-C01学習指導 💿 SPS-C01認定資格 🤝 [ www.goshiken.com ]は、➡ SPS-C01 ️⬅️を無料でダウンロードするのに最適なサイトですSPS-C01関連合格問題
- SPS-C01認定資格 🌐 SPS-C01資格復習テキスト ✨ SPS-C01関連復習問題集 🌕 ⏩ www.mogiexam.com ⏪にて限定無料の☀ SPS-C01 ️☀️問題集をダウンロードせよSPS-C01資格受験料
- SPS-C01試験の準備方法|効率的なSPS-C01受験対策試験|最高のSnowflake Certified SnowPro Specialty - Snowpark模擬問題集 🔩 今すぐ( www.goshiken.com )で➽ SPS-C01 🢪を検索し、無料でダウンロードしてくださいSPS-C01合格資料
- SPS-C01資格模擬 ⌨ SPS-C01認定テキスト 🛄 SPS-C01的中率 👻 ▷ www.shikenpass.com ◁にて限定無料の「 SPS-C01 」問題集をダウンロードせよSPS-C01認定テキスト
- SPS-C01関連復習問題集 📪 SPS-C01的中率 😿 SPS-C01関連合格問題 🐶 ▷ www.goshiken.com ◁にて限定無料の▛ SPS-C01 ▟問題集をダウンロードせよSPS-C01認定テキスト
- SPS-C01資格受験料 😧 SPS-C01オンライン試験 🥿 SPS-C01シュミレーション問題集 🎲 ⏩ www.japancert.com ⏪は、[ SPS-C01 ]を無料でダウンロードするのに最適なサイトですSPS-C01オンライン試験
- 権威のあるSPS-C01受験対策 - 合格スムーズSPS-C01模擬問題集 | 信頼的なSPS-C01認定資格試験 👽 ➡ SPS-C01 ️⬅️を無料でダウンロード( www.goshiken.com )ウェブサイトを入力するだけSPS-C01関連復習問題集
- 素晴らしいSPS-C01受験対策一回合格-便利なSPS-C01模擬問題集 👖 Open Webサイト( www.shikenpass.com )検索[ SPS-C01 ]無料ダウンロードSPS-C01学習指導
- SPS-C01関連問題資料 📻 SPS-C01認定テキスト ‼ SPS-C01受験料 🕓 ▷ SPS-C01 ◁を無料でダウンロード➤ www.goshiken.com ⮘ウェブサイトを入力するだけSPS-C01認定資格
- 素晴らしいSPS-C01受験対策一回合格-便利なSPS-C01模擬問題集 🔓 ➤ SPS-C01 ⮘の試験問題は「 www.passtest.jp 」で無料配信中SPS-C01資格復習テキスト
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.pass4training.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.scener.com, Disposable vapes
無料でクラウドストレージから最新のMogiExam SPS-C01 PDFダンプをダウンロードする:https://drive.google.com/open?id=1pfvCr563j-ZiPGXk8PSk5s_jiOo4kRQ0