It is universally accepted that in this competitive society in order to get a good job we have no choice but to improve our own capacity and explore our potential constantly, and try our best to get the related AI-200 certification is the best way to show our professional ability, however, the AI-200 Exam is hard nut to crack but our AI-200 preparation questions are closely related to the exam, it is designed for you to systematize all of the key points needed for the AI-200 exam.
| Section | Objectives |
|---|---|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Connect to and consume Azure services | - Integrate Azure services
|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
>> AI-200 Trusted Exam Resource <<
It is a common sense that in terms of a kind of AI-200 test torrent, the pass rate would be the best advertisement, since only the pass rate can be the most powerful evidence to show whether the AI-200 guide torrent is effective and useful or not. We are so proud to tell you that according to the statistics from the feedback of all of our customers, the pass rate of our AI-200 Exam Questions among our customers who prepared for the exam under the guidance of our AI-200 test torrent has reached as high as 98%to 100%.
NEW QUESTION # 88
You have an Azure web app that uses Azure Cosmos DB as a data store. You create a Cosmos DB container by running the following PowerShell script: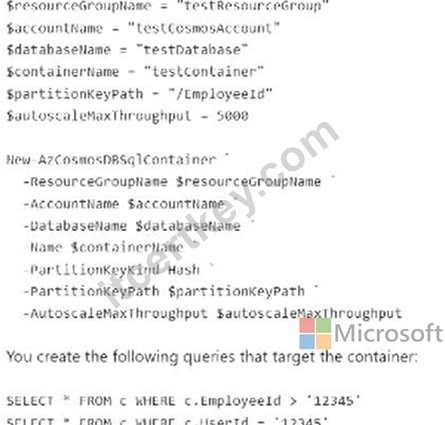
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.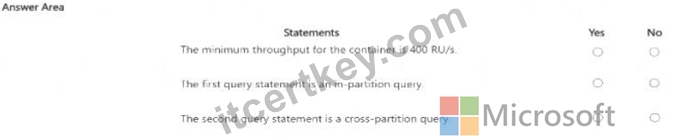
Answer:
Explanation: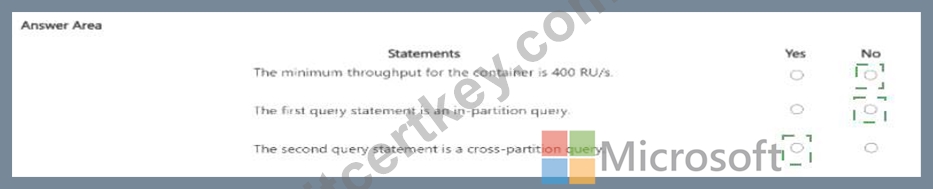
Explanation: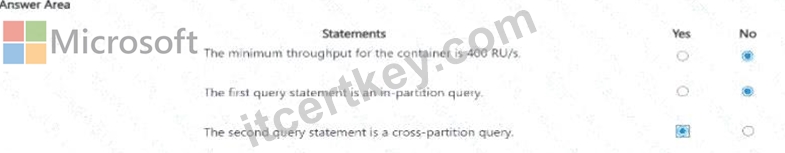
The question maps directly to the AI-200 objective "Develop AI solutions by using Azure Cosmos DB for NoSQL," which includes running queries and optimizing query performance and Request Unit (RU) consumption.
Statement 1: No - The minimum throughput is not 400 RU/s.
The PowerShell command provisions the container with:
-AutoscaleMaxThroughput 5000
Azure Cosmos DB autoscale operates between approximately 10% and 100% of the configured maximum throughput . Microsoft documentation specifically gives the example of an autoscale container provisioned with 5,000 RU/s scaling between 500 RU/s and 5,000 RU/s . Therefore, for this container, the minimum operating autoscale throughput is 500 RU/s , not 400 RU/s.
Therefore:
"The minimum throughput for the container is 400 RU/s." # No
Statement 2: No - The first query is not an in-partition query.
The container uses:
/EmployeeId
as its partition key.
The first query is:
SELECT * FROM c WHERE c.EmployeeId > ' 12345 '
Although the query references the partition key, it uses a range predicate ( > ) , not an equality predicate.
Microsoft explicitly states that a range filter on a partition key is not scoped to a single physical partition .
To qualify as an in-partition query, the filter must identify the applicable partition, typically through an equality predicate such as:
WHERE c.EmployeeId = ' 12345 '
Microsoft ' s documentation provides essentially the same example: a query using DeviceId > ... against a container partitioned by DeviceId is not an in-partition query .
Therefore:
"The first query statement is an in-partition query." # No
Statement 3: Yes - The second query is a cross-partition query.
The second query is:
SELECT * FROM c WHERE c.UserId = ' 12345 '
The container ' s partition key is /EmployeeId, not /UserId. Because the query contains no filter on the partition key , Azure Cosmos DB cannot route it to one logical partition. It must fan out the query across the applicable physical partitions and combine the results.
Microsoft describes this behavior directly: when a query does not contain a filter on the partition key, it must execute across the partitions.
Therefore:
"The second query statement is a cross-partition query." # Yes
NEW QUESTION # 89
Your team wants to track token usage, latency, and error rates for an Azure OpenAI-backed application in production, with alerting on anomalies. What should you configure?
Answer: C
Explanation:
Azure Monitor, configured via diagnostic settings on the Azure OpenAI resource, collects logs and metrics such as token consumption, latency, and errors, and supports alert rules for anomaly detection in production.
NEW QUESTION # 90
You publish custom AI inference events to an Event Grid topic.
Downstream services must receive events only if the confidenceScore value is greater than 0.80.
You need to filter events based on a numeric value in the event payload.
Which filter should you configure?
Answer: A
Explanation:
An Advanced Filter using the NumberGreaterThan operator configured with a key path pointing to the payload value (e.g., data.confidenceScore) and a comparison value of 0.80 should be set up.
To filter custom payload data based on a numeric threshold in Azure Event Grid, configure the event subscription with these properties:
Key: data.confidenceScore (adjust the path depending on your exact JSON payload structure) Operator: NumberGreaterThanValue: 0.80 Reference:
https://learn.microsoft.com/en-us/azure/event-grid/event-filtering
NEW QUESTION # 91
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to optimize vector search queries based on the technical requirements. What should you do?
Answer: C
Explanation:
Scenario: Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
*-> Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
To optimize vector similarity queries that must be performed only against products satisfying mandatory metadata constraints, you should Create a B-tree index on metadata filter columns.
1. Evaluate Query Execution OrderIn PostgreSQL with pgvector, combining metadata filters with vector similarity searches often triggers a multi-stage execution plan. When metadata filtering is highly restrictive, creating a B-tree index allows the database engine to quickly narrow down the row scanned before or during the vector evaluation, preventing a costly full-table scan.
2. Assess Indexing Trade-offs
B-tree Index (Metadata): Directly addresses the requirement that vector calculations must be performed only against products satisfying mandatory metadata constraints. It optimizes the metadata filtering step, significantly reducing compute overhead and isolating the target rows for vector processing.
IVFFlat Index (Vector): While an IVFFlat index speeds up high-dimensional approximate nearest neighbor (ANN) searches, it divides vectors into lists. If a metadata filter is applied after an IVFFlat index scan, it can lead to severe recall degradation or inaccurate results because rows matching the metadata might reside in unsearched vector lists. (Note: For newer workloads, HNSW is generally preferred over IVFFlat for better recall and performance, but regular B-trees remain vital for the metadata layer).
3. Ensure Index Residency in RAM
By isolating the dataset using a compact B-tree index on metadata columns, you minimize the active working set. This helps fulfill your operational requirement to ensure that high-dimensional vector indexes and target rows remain resident in RAM for efficient mathematical throughput.
Reference:
https://www.applied-ai.com/briefings/enterprise-rag-architecture/
NEW QUESTION # 92
You have an Azure subscription named Sub1 that contains a resource group named RG1 and a Service Bus queue named SB1.
You plan to implement an Azure Event Grid push even: subscription that will deliver an event lo SB1 whenever a resource is created, modified, or deleted in RG1. You must minimize the development and configuration efforts.
You need to create an Event Grid topic for your planned implementation
Which type of event topic should you create?
Answer: B
NEW QUESTION # 93
......
Although the Microsoft AI-200 exam prep is of great importance, you do not need to be over concerned about it. With scientific review and arrangement from professional experts as your backup, and the most accurate and high quality content of our Microsoft AI-200 Study Materials, you will cope with it like a piece of cake. So our AI-200 learning questions will be your indispensable practice materials during your way to success.
AI-200 Exams Collection: https://www.itcertkey.com/AI-200_braindumps.html