ITDumpsKR Databricks-Generative-AI-Engineer-Associate 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1g40ZoroJgXlMh65faJY-ctH755KIs0g_
IT업계 취업 준비생이라면 국제적으로도 승인받는 IT인증자격증 정도는 몇개 취득해야 하지 않을가 싶습니다. Databricks인증 Databricks-Generative-AI-Engineer-Associate시험을 통과하여 인기 자격증을 취득하시면 취업경쟁율이 제고되어 취업이 쉬워집니다. ITDumpsKR의Databricks인증 Databricks-Generative-AI-Engineer-Associate덤프는 많은 시험본 분들에 의해 검증된 최신 최고의 덤프공부자료입니다.망설이지 마시고ITDumpsKR제품으로 한번 가보세요.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate Exam |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Exam Duration: | 90 minutes |
| Exam Format: | Multiple choice |
| Exam Price: | USD 200 |
| Certificate Validity Period: | 2 years |
| Available Languages: | English, Japanese, Brazilian Portuguese, Korean |
| Real Exam Qty: | 45 |
| Passing Score: | 700/1000 or 70% |
| Recommended Training: | Generative AI Engineering with Databricks |
| Exam Registration: | Databricks Certification Registration |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored or in-person test center |
| Pre Condition: | No formal prerequisites; recommended 6+ months hands-on experience building generative AI solutions |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks-Generative-AI-Engineer-Associate완벽한 인증자료 <<
ITDumpsKR 안에는 아주 거대한IT업계엘리트들로 이루어진 그룹이 있습니다. 그들은 모두 관련업계예서 권위가 있는 전문가들이고 자기만의 지식과 지금까지의 경험으로 최고의 IT인증관련자료를 만들어냅니다. ITDumpsKR의 Databricks-Generative-AI-Engineer-Associate문제와 답은 정확도가 아주 높으며 한번에 패스할수 있는 100%로의 보장도를 자랑하며 그리고 또 일년무료 업데이트를 제공합니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
| 주제 4 |
|
| 주제 5 |
|
질문 # 89
A Generative AI Engineer is deploying an agent using Mosaic AI Model Serving. The agent needs to access various Databricks resources, including Vector Search, Databricks SQL, and Functions. They need to find the easiest and best-practice way to authenticate the deployed agent to access these resources.
What approach should they choose?
정답:C
설명:
For agents deployed through Model Serving, Databricks supports automatic authentication passthrough for declared resources. The engineer records the agent's dependencies through the resources parameter when logging the model. During deployment, Databricks checks the deployer's access, creates a service principal for the agent model version, grants the required resource access, and supplies short-lived credentials.
Credential rotation is handled automatically. Supported dependencies include Vector Search indexes, SQL warehouses, and Unity Catalog functions. This approach avoids embedding secrets in source code or recording authentication tokens as model artifacts. Permissions on the serving endpoint govern access to that endpoint; they do not independently establish all downstream resource permissions. All required dependencies, including relevant underlying resources, must be declared correctly. Databricks documentation
질문 # 90
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: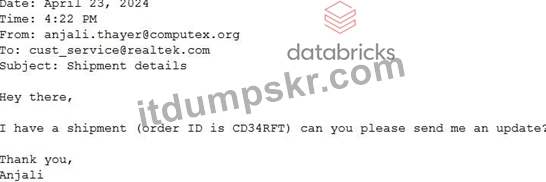
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
정답:A
설명:
* Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM's responses.
* Explanation of Options:
Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore, Option B is optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
질문 # 91
A Generative AI Engineer is developing a patient-facing healthcare-focused chatbot. If the patient's question is not a medical emergency, the chatbot should solicit more information from the patient to pass to the doctor' s office and suggest a few relevant pre-approved medical articles for reading. If the patient's question is urgent, direct the patient to calling their local emergency services.
Given the following user input:
"I have been experiencing severe headaches and dizziness for the past two days." Which response is most appropriate for the chatbot to generate?
정답:B
설명:
* Problem Context: The task is to design responses for a healthcare-focused chatbot that appropriately addresses the urgency of a patient's symptoms.
* Explanation of Options:
* Option A: Suggesting articles might be suitable for less urgent inquiries but is inappropriate for symptoms that could indicate a serious condition.
* Option B: Given the description of severe symptoms like headaches and dizziness, directing the patient to emergency services is prudent. This aligns with medical guidelines that recommend immediate professional attention for such severe symptoms.
* Option C: Offering well-wishes does not address the potential seriousness of the symptoms and lacks appropriate action.
* Option D: While gathering more information is part of a detailed assessment, the immediate need here suggests a more urgent response.
Given the potential severity of the described symptoms,Option Bis the most appropriate, ensuring the chatbot directs patients to seek urgent care when needed, potentially saving lives.
질문 # 92
A company selling gourmet mushroom-growing supplies has a script that runs once per day to scrape various social media platforms for posts that mention its name. The scraped text data is loaded into a Delta table each night for a downstream processing task that summarizes each post and its sentiment for internal use. Given the small size of the company, it only receives a couple hundred posts per day.
Which solution best optimizes for cost and ease of implementation?
정답:A
설명:
A scheduled SQL query using ai_query() is a straightforward way to process text already stored in a Delta table. The query can send each post to a supported model with instructions to return a summary and sentiment, then persist the results for internal reporting. A pay-per-token service avoids dedicating serving capacity to a workload containing only a few hundred daily records. Calling an external batch API introduces additional integration and result-handling work, while downloading and hosting a model adds infrastructure responsibilities. Provisioned throughput is generally more appropriate when sustained demand justifies dedicated capacity. B is the best fit among these choices; actual costs still depend on model selection, token volume, SQL compute, and the applicable inference pricing. Databricks documentation
질문 # 93
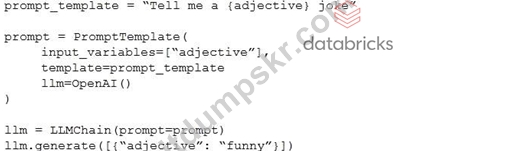
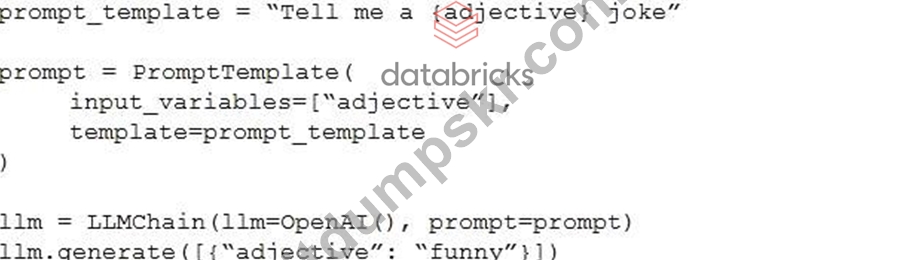
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.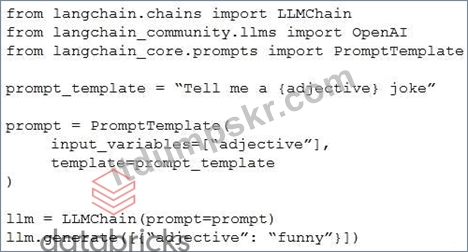
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
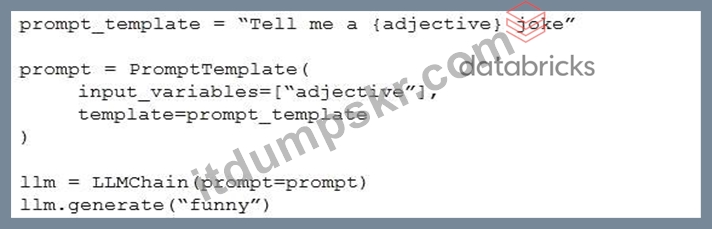
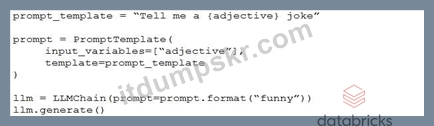
정답:C
설명:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
질문 # 94
......
Databricks-Generative-AI-Engineer-Associate최신 시험덤프공부자료: https://www.itdumpskr.com/Databricks-Generative-AI-Engineer-Associate-exam.html
BONUS!!! ITDumpsKR Databricks-Generative-AI-Engineer-Associate 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1g40ZoroJgXlMh65faJY-ctH755KIs0g_