Certified-Data-Engineer-Professional Valid Exam Vce | New Certified-Data-Engineer-Professional Test Test

In the past few years, Certified-Data-Engineer-Professional study materials have helped countless candidates pass the Certified-Data-Engineer-Professional exam. After having a Certified-Data-Engineer-Professional certification, some of them encountered better opportunities for development, some went to great companies, and some became professionals in the field. Certified-Data-Engineer-Professional study materials have stood the test of time and market and received countless praises. Through the good reputation of word of mouth, more and more people choose to use Certified-Data-Engineer-Professional Study Materials to prepare for the Certified-Data-Engineer-Professional exam, which makes us very gratified. Please be assured that we will stand firmly by every warrior who will pass the exam. Certified-Data-Engineer-Professional study materials have the following characteristics:
| Section | Objectives |
|---|
| Topic 1: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
|
| Topic 2: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Topic 3: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Topic 4: Cost & Performance Optimisation | - Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Apply data skipping and file pruning techniques
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Topic 5: Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use Query Profiler and Spark UI to monitor workloads
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Topic 6: Data Modelling | - Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Optimize data layout using Liquid Clustering
- 3. Design and implement scalable data models using Delta Lake
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 7: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 8: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Topic 9: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Manage and troubleshoot third-party library installations and dependencies
- Building and Testing ETL Pipelines
- 1. Develop unit and integration tests for data processing code
- 2. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 3. Compare streaming tables and materialized views
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Use APPLY CHANGES APIs for change data capture
- 6. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 7. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 8. Use control flow operators in pipeline components
|
| Topic 10: Ensuring Data Security and Compliance | - Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Apply anonymization and pseudonymization techniques
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
>> Certified-Data-Engineer-Professional Valid Exam Vce <<
Certified-Data-Engineer-Professional Valid Exam Vce | 100% Free Newest New Databricks Certified Data Engineer Professional Test Test
You can also trust Prep4SureReview Certified-Data-Engineer-Professional exam practice questions and start this journey with complete peace of mind and satisfaction. The Prep4SureReview is offering real, valid, and error-free Certified-Data-Engineer-Professional exam practice test questions in three different formats. These formats are Certified-Data-Engineer-Professional PDF Dumps Files, desktop practice test software, and web-based practice test software. All these three Certified-Data-Engineer-Professional exam question formats contain the real Certified-Data-Engineer-Professional exam practice questions that help you to prepare well for the final Databricks Certified Data Engineer Professional exam.
Databricks Certified Data Engineer Professional Sample Questions (Q200-Q205):
NEW QUESTION # 200
A data engineering team needs to implement a tagging system for their tables as part of an automated ETL process, and needs to apply tags programmatically to tables in Unity Catalog.
Which SQL command adds tags to a table programmatically?
- A. SET TAGS FOR table_name AS ('key1' = 'value1', 'key2' = 'value2');
- B. APPLY TAGS ON table_name VALUES ('key1' = 'value1', 'key2' = 'value2');
- C. COMMENT ON TABLE table_name TAGS ('key1' = 'value1', 'key2' = 'value2');
- D. ALTER TABLE table_name SET TAGS ('key1' = 'value1', 'key2' = 'value2');
Answer: D
Explanation:
Unity Catalog supports programmatic tagging through the ALTER TABLE statement. Using SET TAGS allows tags to be added or updated directly on a table as part of automated ETL workflows, making it the correct and supported SQL command for managing table tags.
NEW QUESTION # 201
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).
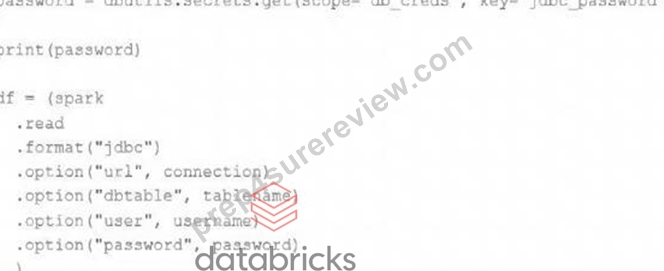
Which statement describes what will happen when the above code is executed?
- A. The connection to the external table will succeed; the string value of password will be printed in plain text.
- B. The connection to the external table will succeed; the string "redacted" will be printed.
- C. The connection to the external table will fail; the string "redacted" will be printed.
- D. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- E. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
Answer: B
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks.
NEW QUESTION # 202
A data engineer is building a Lakeflow Declarative Pipelines pipeline to process healthcare claims data. A metadata JSON file defines data quality rules for multiple tables, including:
{
"claims": [
{"name": "valid_patient_id", "constraint": "patient_id IS NOT NULL"},
{"name": "non_negative_amount", "constraint": "claim_amount >= 0"}
]
}
The pipeline must dynamically apply these rules to the claims table without hardcoding the rules.
How should the data engineer achieve this?
- A. Load the JSON metadata, loop through its entries, and apply expectations using dlt.expect_all.
- B. Invoke an external API to validate records against the metadata rules.
- C. Use a SQL CONSTRAINT block referencing the JSON file path.
- D. Reference each expectation with @dlt.expect decorators in the table declaration.
Answer: A
Explanation:
Lakeflow Declarative Pipelines provide the expect_all method for programmatically applying multiple data quality expectations at once. The documentation explains that @dlt.expect_all accepts a dictionary of expectation names mapped to SQL constraints, allowing rules to be dynamically loaded from metadata such as JSON files. This ensures that pipelines remain maintainable and scalable without needing to hardcode individual @dlt.expect decorators. The event logs will track each expectation's pass and fail counts individually, making it auditable.
NEW QUESTION # 203
A data engineering workspace was automatically enabled for Unity Catalog, creating a workspace catalog. New team members report they can create tables in the default schema but cannot access table in other schemas within the same workspace catalog. Why are the new team members unable to access tables in other schemas?
- A. Workspace users receive USE CATALOG and specific privileges on default schema only.
- B. Tables in other schemas require additional BROWSEprivileges that new users don't receive automatically
- C. New users only receive CREATE TABLE privileges on the default schema.
- D. Workspace catalog permissions are not subject to inheritance rules.
Answer: A
Explanation:
When a workspace catalog is automatically created, new users are granted USE CATALOG and limited privileges on the default schema only. Access to other schemas requires explicit grants, so users cannot see or query tables in those schemas without additional permissions.
NEW QUESTION # 204
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x- scala2.12' runtime. Which command should the data engineer use?
- A. databricks clusters create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name DataEngineer_cluster
- B. databricks compute add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- C. databricks clusters add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- D. databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name Data Engineer_cluster
Answer: A
Explanation:
The correct Databricks CLI command to create a new cluster is databricks clusters create. You specify the runtime with --spark-version (here '14.3.x-scala2.12'), the number of workers with -- num-workers, the node type with --node-type-id, and the cluster name with --cluster-name. This command properly initializes the cluster with the desired configuration.
NEW QUESTION # 205
......
Do you want to pass Certified-Data-Engineer-Professional exam certification at your first attempt to attend Certified-Data-Engineer-Professional test? With Prep4SureReview, we will meet all of your needs, and make you pass Certified-Data-Engineer-Professional certification exam at one time in a limited time. Because Prep4SureReview have Certified-Data-Engineer-Professional Exam Certification training materials, which are summarized by experienced IT experts with many years' practice, and is a combination of Certified-Data-Engineer-Professional exam dumps and answers, you can't regret to choose Prep4SureReview.
New Certified-Data-Engineer-Professional Test Test: https://www.prep4surereview.com/Certified-Data-Engineer-Professional-latest-braindumps.html
- Free PDF Unparalleled Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Valid Exam Vce 🚌 Easily obtain ▷ Certified-Data-Engineer-Professional ◁ for free download through ▛ www.prep4away.com ▟ ✨New Certified-Data-Engineer-Professional Test Discount
- Free PDF 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Latest Valid Exam Vce 🎄 Go to website [ www.pdfvce.com ] open and search for 《 Certified-Data-Engineer-Professional 》 to download for free 🔩New Certified-Data-Engineer-Professional Exam Question
- Free PDF Databricks - Reliable Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Valid Exam Vce 📽 Open website “ www.verifieddumps.com ” and search for ➥ Certified-Data-Engineer-Professional 🡄 for free download ❓New Certified-Data-Engineer-Professional Exam Question
- Free PDF 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Latest Valid Exam Vce 🗯 Search for ➠ Certified-Data-Engineer-Professional 🠰 on ▶ www.pdfvce.com ◀ immediately to obtain a free download ♻Dumps Certified-Data-Engineer-Professional Torrent
- Updated Certified-Data-Engineer-Professional Test Cram 📹 Certified-Data-Engineer-Professional Exam Papers 🙍 Certified-Data-Engineer-Professional Exam Papers 💆 Search for ➤ Certified-Data-Engineer-Professional ⮘ on ➡ www.vceengine.com ️⬅️ immediately to obtain a free download ♿Updated Certified-Data-Engineer-Professional Test Cram
- New Certified-Data-Engineer-Professional Dumps Files 🎓 Dumps Certified-Data-Engineer-Professional Torrent 🦠 New Certified-Data-Engineer-Professional Test Discount 🎬 Open ▶ www.pdfvce.com ◀ enter ⇛ Certified-Data-Engineer-Professional ⇚ and obtain a free download 🕛Reliable Certified-Data-Engineer-Professional Dumps Ebook
- First-grade Certified-Data-Engineer-Professional Valid Exam Vce by www.troytecdumps.com 🧉 Enter ➡ www.troytecdumps.com ️⬅️ and search for 「 Certified-Data-Engineer-Professional 」 to download for free 👺Certified-Data-Engineer-Professional Accurate Prep Material
- High Pass-Rate Certified-Data-Engineer-Professional Valid Exam Vce - Pass Certified-Data-Engineer-Professional in One Time - Perfect New Certified-Data-Engineer-Professional Test Test 🍒 Search for ➠ Certified-Data-Engineer-Professional 🠰 and obtain a free download on “ www.pdfvce.com ” 💄Certified-Data-Engineer-Professional Valid Test Voucher
- Updated Certified-Data-Engineer-Professional Test Cram 🌃 New Certified-Data-Engineer-Professional Exam Question 🌾 Valid Certified-Data-Engineer-Professional Test Practice 🎡 Simply search for 《 Certified-Data-Engineer-Professional 》 for free download on “ www.examdiscuss.com ” 🤕Certified-Data-Engineer-Professional Test Objectives Pdf
- Free PDF 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Latest Valid Exam Vce 📨 《 www.pdfvce.com 》 is best website to obtain ▷ Certified-Data-Engineer-Professional ◁ for free download 🎈Updated Certified-Data-Engineer-Professional Test Cram
- Reliable Certified-Data-Engineer-Professional Dumps Ebook 🕚 Standard Certified-Data-Engineer-Professional Answers 🎨 Dumps Certified-Data-Engineer-Professional Free Download 🕷 Simply search for ☀ Certified-Data-Engineer-Professional ️☀️ for free download on “ www.practicevce.com ” 🏢Certified-Data-Engineer-Professional Exam Cram Review
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, zenwriting.net, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes