We all know that pass the AI-500 exam will bring us many benefits, but it is not easy for every candidate to achieve it. The AI-500 guide torrent is a tool that aimed to help every candidate to pass the exam. Our exam materials can installation and download set no limits for the amount of the computers and persons. We guarantee you that the AI-500 study materials we provide to you are useful and can help you pass the test. Once you buy the product you can use the convenient method to learn the AI-500 Exam Torrent at any time and place. So please take it easy before and after the purchase and trust that our AI-500 study materials carry no virus. To let you be familiar with our product, we list the features and advantages of the AI-500 study materials as follow.
| Section | Weight | Objectives |
|---|---|---|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security for multi-agent solutions
|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Implement observability and monitoring
|
| Develop multi-agent solutions in Azure | 30-35% | - Implement multi-agent orchestration
|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
>> AI-500 Updated Testkings <<
More and more people look forward to getting the AI-500 certification by taking an exam. However, the exam is very difficult for a lot of people. Especially if you do not choose the correct study materials and find a suitable way, it will be more difficult for you to pass the exam and get the AI-500 related certification. If you want to get the related certification in an efficient method, please choose the AI-500 Study Materials from our company. We can guarantee that the study materials from our company will help you pass the exam and get the certification in a relaxed and efficient method.
NEW QUESTION # 59
You have a single-agent customer support copilot built by using Microsoft Foundry. The application that hosts the copilot runs on multiple stateless instances, and rolling upgrades restart the instances.
[Architect multi-agent solutions]
Customer investigations can last for several days. A user can have multiple unrelated investigations, and stable user preferences, such as a preferred contact method, must be available across sessions and devices Compliance reporting requires a one-year, queryable audit trail of thread messages and session metadata.
During long investigations, the model context window regularly approaches its limits. Temporary tool traces do NOT affect final outcomes after the run completes.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.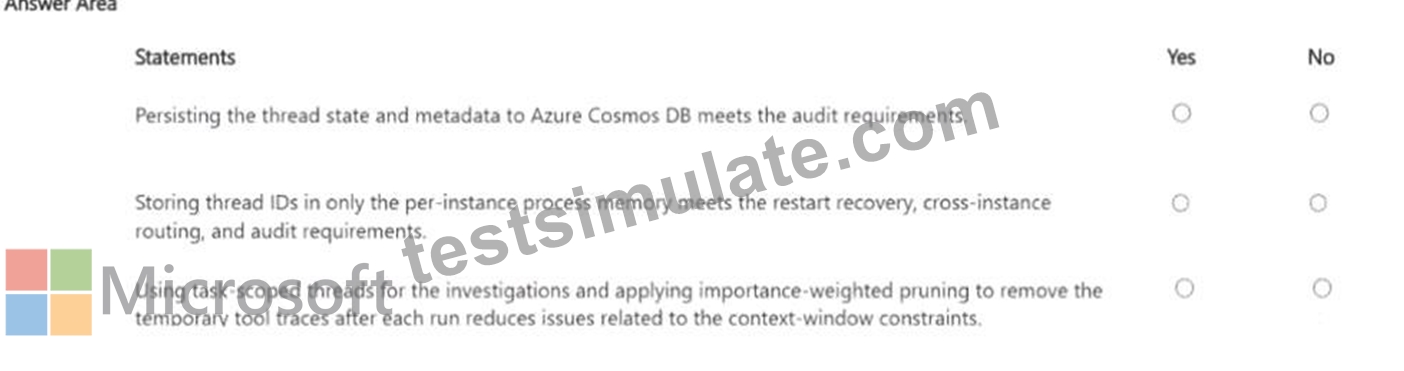
Answer:
Explanation: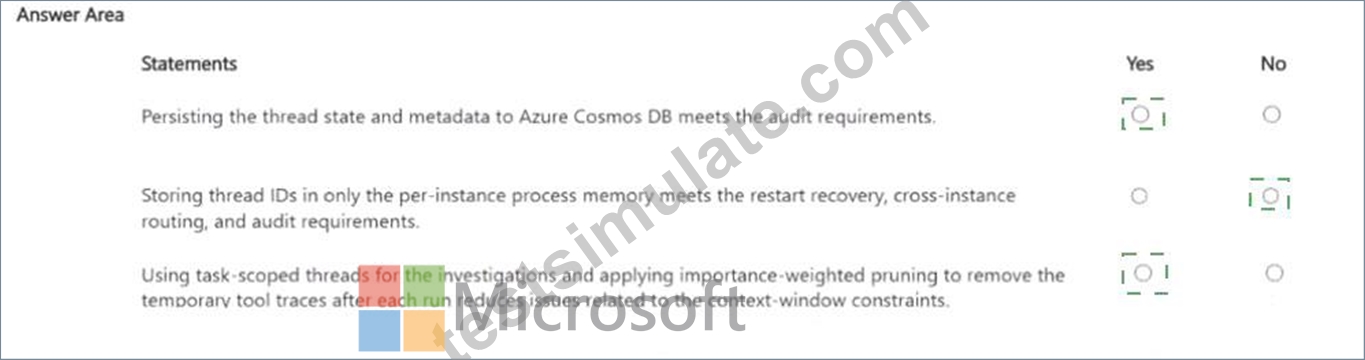
Explanation:
Yes / No / Yes
Persisting thread messages and session metadata in Azure Cosmos DB can satisfy the requirement for a durable, queryable audit trail when the appropriate retention and indexing policies are configured. Storing thread identifiers only in per-instance memory cannot survive rolling restarts and cannot support consistent routing across multiple stateless instances, so that statement is false. Separating unrelated investigations into task-scoped threads prevents one case from consuming the context budget of another. Removing temporary tool traces after the run when they no longer influence the outcome is also a valid compaction strategy for reducing context pressure. Current Agent Framework terminology commonly refers to this as compaction or tool-result eviction rather than "importance-weighted pruning," but the architectural effect described is sound.
Therefore the correct sequence is Yes, No, Yes. This choice also keeps the design composable as more agents are introduced. Clear interfaces, trust boundaries, and state ownership let a team change one domain without forcing unrelated agents to adopt the same permissions, context, or execution model.
Official Microsoft reference: Microsoft Foundry Agent Service - standard setup and durable state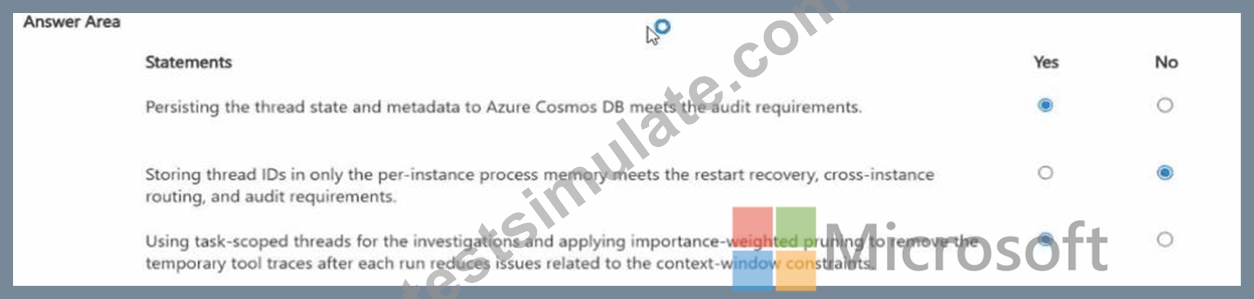
NEW QUESTION # 60
You need to implement a logging solution for claim Approval.
What should you use for each process? To answer, drag the appropriate resources to the correct processes.
Each resource may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.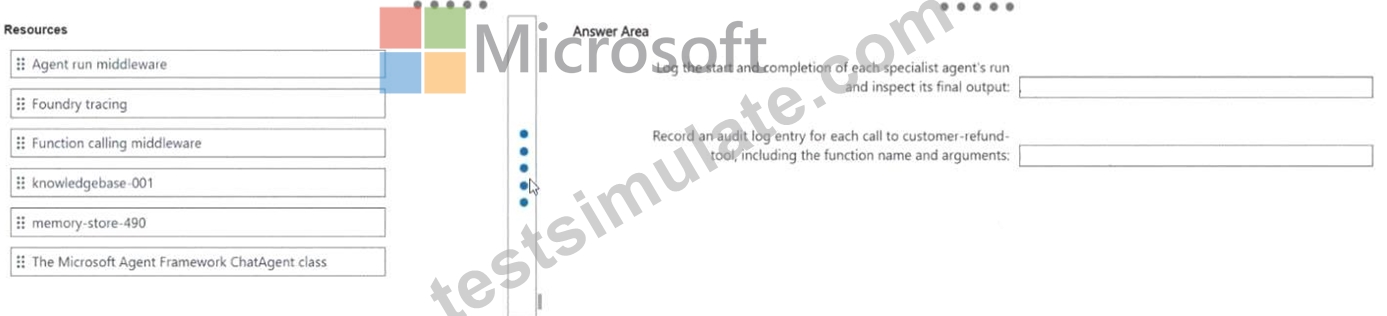
Answer:
Explanation: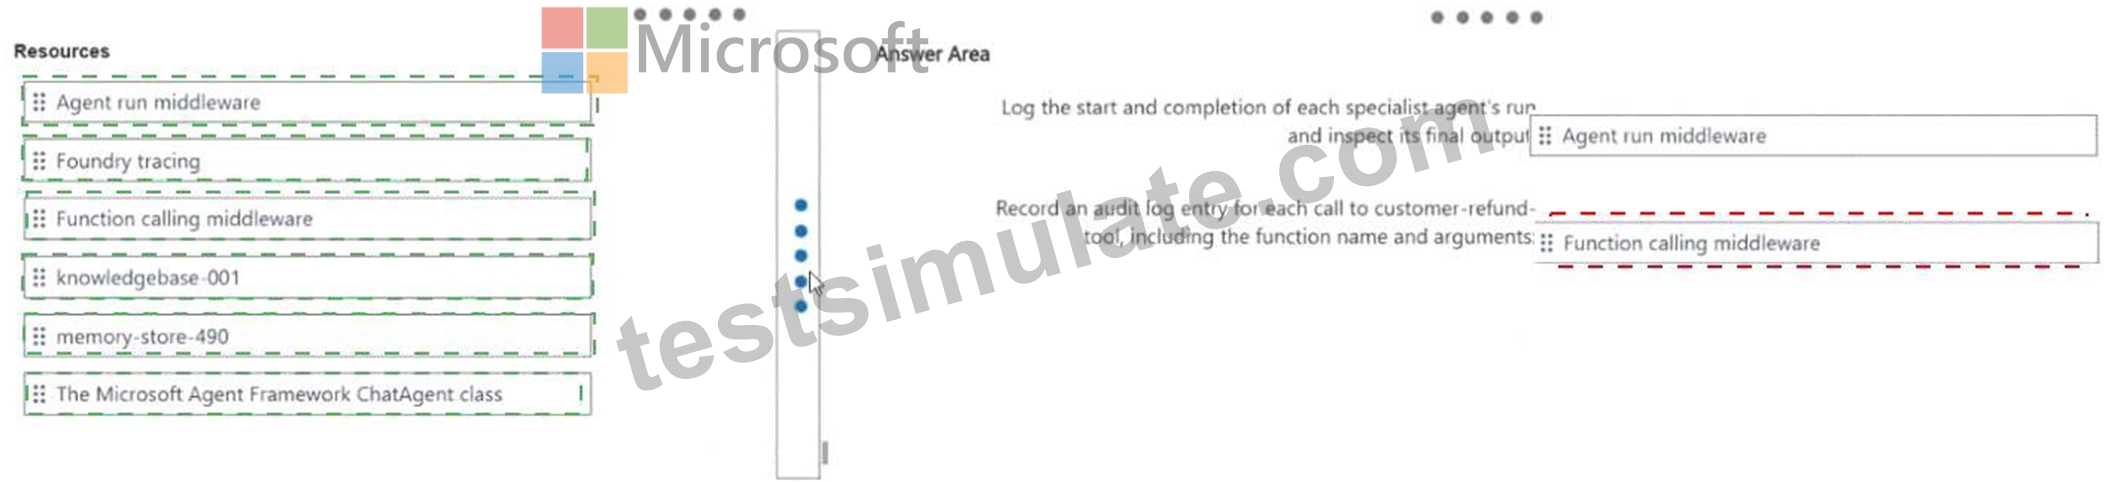
Explanation:
Log the start/completion of each specialist run and inspect the final output with Agent run middleware; record each customer-refund-tool call, including function name and arguments, with Function calling middleware.
The two logging requirements occur at different lifecycle boundaries. Agent run middleware surrounds an agent invocation, so it is the appropriate place to capture run start, run completion, exceptions, and the final agent result. Function calling middleware surrounds tool/function execution and can inspect the selected function, arguments, result, and failures. That makes it the correct boundary for an audit record of each customer-refund-tool invocation. Foundry tracing can provide broader distributed observability, but the question asks for reusable Microsoft Agent Framework middleware at the exact execution points. A knowledge store or memory store does not provide execution interception. Separating the two concerns also supports a cleaner audit model: agent-level middleware records specialist behavior, while function-level middleware records tool use. This aligns with Microsoft ' s middleware model, where cross-cutting concerns such as logging, validation, and exception handling can be implemented once and applied consistently rather than duplicated inside every agent or tool.
Official Microsoft reference: Microsoft Agent Framework - Defining middleware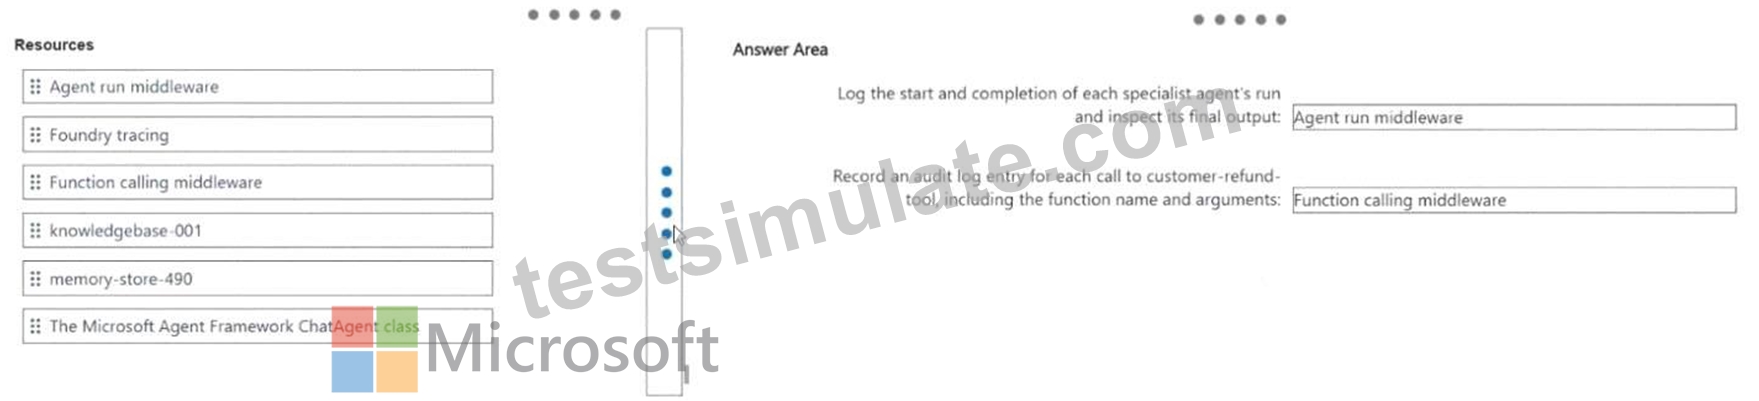
NEW QUESTION # 61
You have a LangGraph multi-agent workflow that uses Azure Cosmos DB as a checkpointer.
You plan to change the pruning rules for the running message list before the next release You need to implement evaluations tor memory. The solution must meet the following requirements:
* Verify that claim-related state values remain correct at transition points.
* Verify that conversation context is preserved after an interruption.
* Identify the source of any loss of continuity during a run
Which three actions should you perform Each correct answer presents part of the solution NOTE: Each correct selection is worth one point.
Answer: C,D,E
Explanation:
Memory evaluation must verify persistence across interruption, correctness of checkpointed state, and enough telemetry to locate where continuity was lost. Running a scripted multi-turn case with one stable `thread_id` before and after a restart directly tests whether the Cosmos-backed LangGraph checkpointer restores the same conversation/workflow. Comparing persisted checkpoint documents with expected state values at each handoff verifies that claim-related state has not been corrupted by the new pruning rules. Correlating the evaluation run with trace spans then provides the diagnostic path to identify which agent transition or state- management operation caused a failure. Changing the thread ID each turn would intentionally create separate state scopes, and removing durable artifacts would defeat the persistence test. Tool-call arguments alone do not prove workflow-memory continuity. Therefore D, E, and F are the complementary actions required. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Azure Cosmos DB integrations for LangGraph and agent state
NEW QUESTION # 62
You have a Microsoft Foundry multi-agent solution. The solution includes an orchestrator agent that sends a mix of simple requests, reasoning-heavy tasks, and tool-calling workflows to a single premium model deployment.
Response quality is acceptable, but costs are too high, and latency varies significantly across requests.
You need to recommend a solution to reduce token utilization based on the complexity of the user input.
What should you include in the recommendation?
Answer: D
Explanation:
The workload mixes simple prompts, reasoning-heavy tasks, and tool-calling workflows, so a single premium model is over-provisioned for many requests. Microsoft Foundry ' s model router evaluates request complexity and routes each request to an appropriate model from a configured pool. Simple work can use lower-cost, lower-latency models, while complex reasoning can still be assigned to a more capable model.
Structured outputs constrain response format but do not reduce model capability according to request complexity. Prompt Optimizer can improve prompt quality but does not perform per-request model selection, and choosing another flagship model would preserve the same all-requests-use-premium pattern. Therefore A directly addresses the cost and latency variability by matching model capacity to workload complexity. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - Model router
NEW QUESTION # 63
You have the following tool integration configuration for a Microsoft Foundry claims-processing assistant.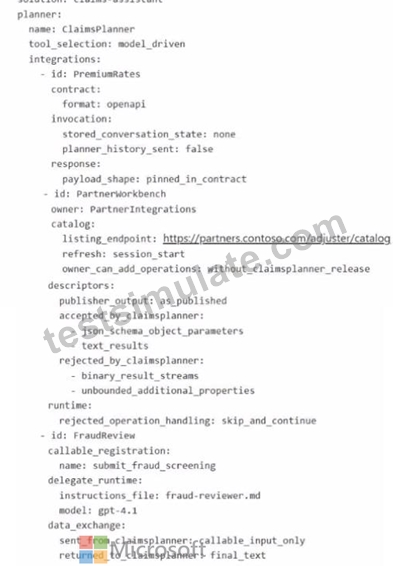
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.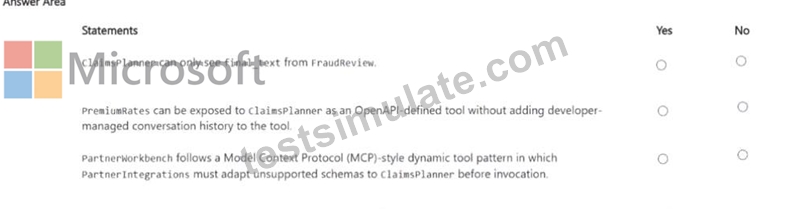
Answer:
Explanation: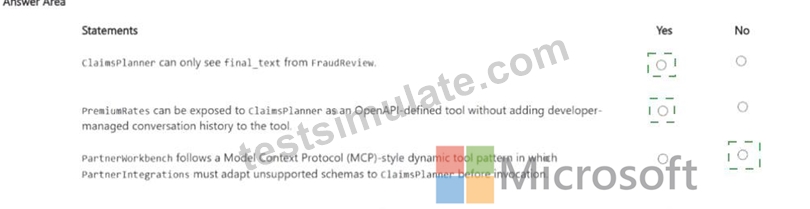
Explanation:
Yes / Yes / No
The first statement is true because the tool-integration contract returns only the explicitly defined `final_text` from FraudReview to ClaimsPlanner; the planner does not automatically receive the specialist ' s entire internal execution history. The second statement is also true because an external REST service such as PremiumRates can be exposed as an OpenAPI-defined tool. The OpenAPI schema describes operations and parameters, while the surrounding agent system retains conversational state; the REST tool itself does not need a developer-managed chat transcript. The third statement is false under the shown configuration because the partner publishes tool descriptors as published while the planner defines which schemas it accepts or rejects. Compatibility handling therefore occurs at the consumer/tool boundary rather than requiring PartnerIntegrations to rewrite every unsupported schema before invocation. The correct sequence is Yes, Yes, No. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Foundry agents - OpenAPI tools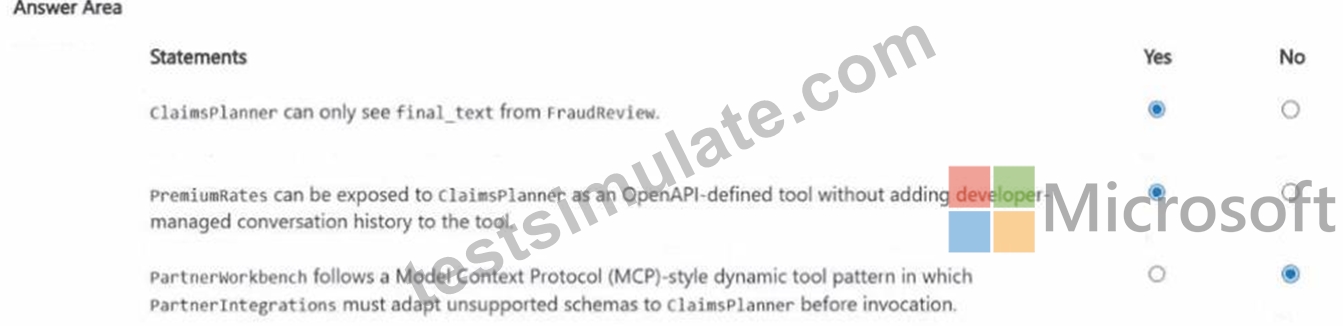
NEW QUESTION # 64
......
We have a team of experts curating the real AI-500 questions and answers for the end users. We are always working on updating the latest AI-500 questions and providing the correct AI-500 answers to all of our users. We provide free updates for one year from the date of purchase. You can benefit from the updates AI-500 Preparation material, and you will be able to pass the AI-500 exam in the first attempt.
AI-500 Latest Dumps Ebook: https://www.testsimulate.com/AI-500-study-materials.html