2026 Latest PassReview Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1vFMLqr9Qs_eghME7-RgYYifDTS8QW9l7
PassReview has been devoted itself to provide all candidates who are preparing for IT certification exam with the best and the most trusted reference materials in years. With regards to the questions of IT certification test, PassReview has a wealth of experience. PassReview has helped numerous candidates and got their reliance and praise. So, don't doubt the quality of PassReview Databricks Databricks-Generative-AI-Engineer-Associate Dumps. It is high quality dumps helping you 100% pass Databricks-Generative-AI-Engineer-Associate certification test. PassReview promises 100% FULL REFUND, if you fail the exam. With this guarantee, you don't need to hesitate whether to buy the dumps or not. Missing it is your losses.
| Section | Objectives |
|---|---|
| Topic 1: Databricks Mosaic AI Platform | - MLflow for GenAI
|
| Topic 2: Foundations of Generative AI | - Large Language Models (LLMs)
|
| Topic 3: Responsible AI and Governance | - Model governance
|
| Topic 4: Retrieval-Augmented Generation (RAG) | - Vector databases and embeddings
|
| Topic 5: Prompt Engineering | - Prompt evaluation
|
>> Certification Databricks-Generative-AI-Engineer-Associate Dumps <<
We PassReview are growing faster and faster owing to our high-quality latest Databricks-Generative-AI-Engineer-Associate certification guide materials with high pass rate. Based on our past data, our pass rate of Databricks-Generative-AI-Engineer-Associate training guide is high up to 99% to 100% recently years. Many customer will become regular customer and think of us once they have exams to clear after choosing our Databricks-Generative-AI-Engineer-Associate Exam Guide one time. So we have no need to spend much spirits to advertise but only put most into researching and after-sale service. As long as you study with our Databricks-Generative-AI-Engineer-Associate learning questions, you will find that it is a right choice.
NEW QUESTION # 57
A Generative Al Engineer is helping a cinema extend its website's chat bot to be able to respond to questions about specific showtimes for movies currently playing at their local theater. They already have the location of the user provided by location services to their agent, and a Delta table which is continually updated with the latest showtime information by location. They want to implement this new capability In their RAG application.
Which option will do this with the least effort and in the most performant way?
Answer: A
Explanation:
The task is to extend a cinema chatbot to provide movie showtime information using a RAG application, leveraging user location and a continuously updated Delta table, with minimal effort and high performance. Let's evaluate the options.
Option A: Create a Feature Serving Endpoint from a FeatureSpec that references an online store synced from the Delta table. Query the Feature Serving Endpoint as part of the agent logic / tool implementation Databricks Feature Serving provides low-latency access to real-time data from Delta tables via an online store. Syncing the Delta table to a Feature Serving Endpoint allows the chatbot to query showtimes efficiently, integrating seamlessly into the RAG agent's tool logic. This leverages Databricks' native infrastructure, minimizing effort and ensuring performance.
Databricks Reference: "Feature Serving Endpoints provide real-time access to Delta table data with low latency, ideal for production systems" ("Databricks Feature Engineering Guide," 2023).
Option B: Query the Delta table directly via a SQL query constructed from the user's input using a text-to-SQL LLM in the agent logic / tool Using a text-to-SQL LLM to generate queries adds complexity (e.g., ensuring accurate SQL generation) and latency (LLM inference + SQL execution). While feasible, it's less performant and requires more effort than a pre-built serving solution.
Databricks Reference: "Direct SQL queries are flexible but may introduce overhead in real-time applications" ("Building LLM Applications with Databricks").
Option C: Write the Delta table contents to a text column, then embed those texts using an embedding model and store these in the vector index. Look up the information based on the embedding as part of the agent logic / tool implementation Converting structured Delta table data (e.g., showtimes) into text, embedding it, and using vector search is inefficient for structured lookups. It's effort-intensive (preprocessing, embedding) and less precise than direct queries, undermining performance.
Databricks Reference: "Vector search excels for unstructured data, not structured tabular lookups" ("Databricks Vector Search Documentation").
Option D: Set up a task in Databricks Workflows to write the information in the Delta table periodically to an external database such as MySQL and query the information from there as part of the agent logic / tool implementation Exporting to an external database (e.g., MySQL) adds setup effort (workflow, external DB management) and latency (periodic updates vs. real-time). It's less performant and more complex than using Databricks' native tools.
Databricks Reference: "Avoid external systems when Delta tables provide real-time data natively" ("Databricks Workflows Guide").
Conclusion: Option A minimizes effort by using Databricks Feature Serving for real-time, low-latency access to the Delta table, ensuring high performance in a production-ready RAG chatbot.
NEW QUESTION # 58
A Generative Al Engineer interfaces with an LLM with prompt/response behavior that has been trained on customer calls inquiring about product availability. The LLM is designed to output "In Stock" if the product is available or only the term "Out of Stock" if not.
Which prompt will work to allow the engineer to respond to call classification labels correctly?
Answer: D
Explanation:
Problem Context: The Generative AI Engineer needs a prompt that will enable an LLM trained on customer call transcripts to classify and respond correctly regarding product availability. The desired response should clearly indicate whether a product is "In Stock" or "Out of Stock," and it should be formatted in a way that is structured and easy to parse programmatically, such as JSON.
Explanation of Options:
Option A: Respond with "In Stock" if the customer asks for a product. This prompt is too generic and does not specify how to handle the case when a product is not available, nor does it provide a structured output format.
Option B: This option is correctly formatted and explicit. It instructs the LLM to respond based on the availability mentioned in the customer call transcript and to format the response in JSON. This structure allows for easy integration into systems that may need to process this information automatically, such as customer service dashboards or databases.
Option C: Respond with "Out of Stock" if the customer asks for a product. Like option A, this prompt is also insufficient as it only covers the scenario where a product is unavailable and does not provide a structured output.
Option D: While this prompt correctly specifies how to respond based on product availability, it lacks the structured output format, making it less suitable for systems that require formatted data for further processing.
Given the requirements for clear, programmatically usable outputs, Option B is the optimal choice because it provides precise instructions on how to respond and includes a JSON format example for structuring the output, which is ideal for automated systems or further data handling.
NEW QUESTION # 59
A Generative AI Engineer is using LangGraph to define multiple tools in a single agentic application. They want to enable the main orchestrator LLM to decide on its own which tools are most appropriate to call for a given prompt. To do this, they must determine the general flow of the code. Which sequence will do this?
Answer: D
Explanation:
In modern agentic frameworks like LangGraph or LangChain, the standard workflow for creating an autonomous tool-calling agent follows a specific sequence. First, tools must be defined (often as Python functions with clear docstrings, which the LLM uses to understand the tool's purpose). Second, the agent logic is defined, which specifies how the LLM should think. Third, the agent is initialized using a logic pattern like ReAct (Reason + Act). The ReAct framework is essential here because it enables the "orchestrator" loop: the LLM receives a prompt, generates a "Thought" about which tool to use, generates an "Action" to call that tool, receives an "Observation" (the tool's output), and repeats until it can provide a final answer. Loading tools into "separate agents" (C) or defining tools "inside" agents (D) are non-standard patterns that add unnecessary complexity and do not align with the centralized orchestration model required for LangGraph.
NEW QUESTION # 60
A Generative AI Engineer I using the code below to test setting up a vector store: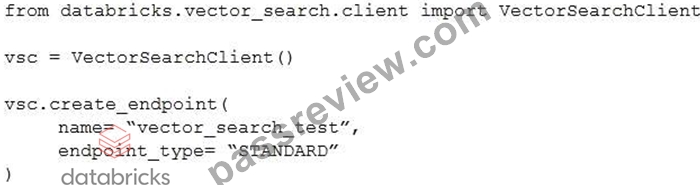
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 61
A Generative AI Engineer has a provisioned throughput model serving endpoint as part of a RAG application and would like to monitor the serving endpoint's incoming requests and outgoing responses. The current approach is to include a micro-service in between the endpoint and the user interface to write logs to a remote server.
Which Databricks feature should they use instead which will perform the same task?
Answer: C
Explanation:
Problem Context: The goal is to monitor theserving endpointfor incoming requests and outgoing responses in aprovisioned throughput model serving endpointwithin aRetrieval-Augmented Generation (RAG) application. The current approach involves using a microservice to log requests and responses to a remote server, but the Generative AI Engineer is looking for a more streamlined solution within Databricks.
Explanation of Options:
* Option A: Vector Search: This feature is used to perform similarity searches within vector databases.
It doesn't provide functionality for logging or monitoring requests and responses in a serving endpoint, so it's not applicable here.
* Option B: Lakeview: Lakeview is not a feature relevant to monitoring or logging request-response cycles for serving endpoints. It might be more related to viewing data in Databricks Lakehouse but doesn't fulfill the specific monitoring requirement.
* Option C: DBSQL: Databricks SQL (DBSQL) is used for running SQL queries on data stored in Databricks, primarily for analytics purposes. It doesn't provide the direct functionality needed to monitor requests and responses in real-time for an inference endpoint.
* Option D: Inference Tables: This is the correct answer.Inference Tablesin Databricks are designed to store the results and metadata of inference runs. This allows the system to logincoming requests and outgoing responsesdirectly within Databricks, making it an ideal choice for monitoring the behavior of a provisioned serving endpoint. Inference Tables can be queried and analyzed, enabling easier monitoring and debugging compared to a custom microservice.
Thus,Inference Tablesare the optimal feature for monitoring request and response logs within the Databricks infrastructure for a model serving endpoint.
NEW QUESTION # 62
......
There are more and more people to try their best to pass the Databricks-Generative-AI-Engineer-Associate exam, including many college students, a lot of workers, and even many housewives and so on. These people who want to pass the Databricks-Generative-AI-Engineer-Associate exam have regard the exam as the only one chance to improve themselves and make enormous progress. So they hope that they can be devoting all of their time to preparing for the Databricks-Generative-AI-Engineer-Associate Exam, but it is very obvious that a lot of people have not enough time to prepare for the important Databricks-Generative-AI-Engineer-Associate exam. Our Databricks-Generative-AI-Engineer-Associate exam questions can help you pass the Databricks-Generative-AI-Engineer-Associate exam with least time and energy.
Databricks-Generative-AI-Engineer-Associate Test Topics Pdf: https://www.passreview.com/Databricks-Generative-AI-Engineer-Associate_exam-braindumps.html
BONUS!!! Download part of PassReview Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1vFMLqr9Qs_eghME7-RgYYifDTS8QW9l7