If you want to pass your exam and get the certification in a short time, choosing the suitable Databricks-Certified-Professional-Data-Engineer exam questions are very important for you. You must pay more attention to the Databricks-Certified-Professional-Data-Engineer study materials. In order to provide all customers with the suitable study materials, a lot of experts from our company designed the Databricks-Certified-Professional-Data-Engineer Training Materials. We can promise that if you buy our Databricks-Certified-Professional-Data-Engineer exam questions, it will be very easy for you to pass your Databricks-Certified-Professional-Data-Engineer exam and get the certification.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks - Handling missing or inconsistent data - Standardization and normalization |
| Topic 2: Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Integration with Databricks APIs and tools - Batch and incremental processing logic |
| Topic 3: Data Modelling | 6% | - Medallion Architecture implementation - Delta Lake table design - Schema design and management |
| Topic 4: Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Auto Loader and streaming ingestion - Connecting to diverse data sources |
| Topic 5: Cost & Performance Optimisation | 13% | - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching |
| Topic 6: Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors - CI/CD and DevOps practices |
| Topic 7: Data Governance | 7% | - Policy enforcement - Unity Catalog management - Data lineage and metadata tracking |
| Topic 8: Monitoring and Alerting | 10% | - Setting up alerts and notifications - Pipeline observability and logging - Performance and health monitoring |
| Topic 9: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Topic 10: Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Data encryption and masking - Access control and permissions |
>> Databricks-Certified-Professional-Data-Engineer Download Demo <<
We can make sure that if you purchase our Databricks-Certified-Professional-Data-Engineer exam questions, you will have the right to enjoy our perfect after sale service and the high quality products. So do not hesitate and buy our Databricks-Certified-Professional-Data-Engineer study guide, we believe you will find surprise from our exam products. And not only you can enjoy the service before you pay for our Databricks-Certified-Professional-Data-Engineer learning guide, you can also have the right to have free updates for one year after your purchase.
NEW QUESTION # 151
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non- overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late- arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: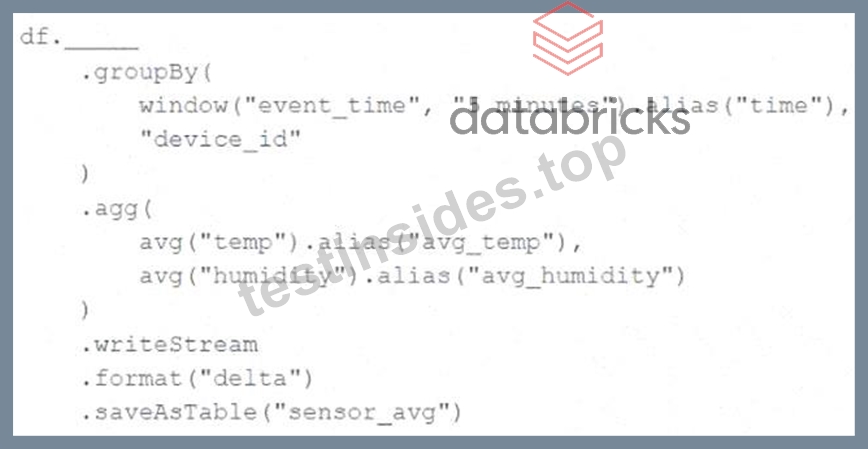
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: C
Explanation:
The correct answer is A. withWatermark("event_time", "10 minutes"). This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming. References:
* Watermarking: https://docs.databricks.com/spark/latest/structured-streaming/watermarks.html
* Windowed aggregations: https://docs.databricks.com/spark/latest/structured-streaming/window- operations.html
NEW QUESTION # 152
A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor.
When evaluating the Ganglia Metrics for this cluster, which indicator would signal a bottleneck caused by code executing on the driver?
Answer: E
Explanation:
Explanation
This is the correct answer because it indicates a bottleneck caused by code executing on the driver. A bottleneck is a situation where the performance or capacity of a system is limited by a single component or resource. A bottleneck can cause slow execution, high latency, or low throughput. A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor. When evaluating the Ganglia Metrics for this cluster, one can look for indicators that show how the cluster resources are being utilized, such as CPU, memory, disk, or network. If the overall cluster CPU utilization is around 25%, it means that only one out of the four nodes (driver + 3 executors) is using its full CPU capacity, while the other three nodes are idle or underutilized. This suggests that the code executing on the driver is taking too long or consuming too much CPU resources, preventing the executors from receiving tasks or data to process. This can happen when the code has driver-side operations that are not parallelized or distributed, such as collecting large amounts of data to the driver, performing complex calculations on the driver, or using non-Spark libraries on the driver. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under "View cluster status and event logs - Ganglia metrics" section; Databricks Documentation, under "Avoid collecting large RDDs" section.
In a Spark cluster, the driver node is responsible for managing the execution of the Spark application, including scheduling tasks, managing the execution plan, and interacting with the cluster manager. If the overall cluster CPU utilization is low (e.g., around 25%), it may indicate that the driver node is not utilizing the available resources effectively and might be a bottleneck.
NEW QUESTION # 153
Which statement describes integration testing?
Answer: A
Explanation:
This is the correct answer because it describes integration testing. Integration testing is a type of testing that validates interactions between subsystems of your application, such as modules, components, or services.
Integration testing ensures that the subsystems work together as expected and produce the correct outputs or results. Integration testing can be done at different levels of granularity, such as component integration testing, system integration testing, or end-to-end testing. Integration testing can help detect errors or bugs that may not be found by unit testing, which only validates behavior of individual elements of your application.
Verified References: [Databricks Certified Data Engineer Professional], under "Testing" section; Databricks Documentation, under "Integration testing" section.
NEW QUESTION # 154
A data engineer is designing a data pipeline. The source system generates files in a shared directory that is also
used by other processes. As a result, the files should be kept as is and will accumulate in the directory. The
data engineer needs to identify which files are new since the previous run in the pipeline, and set up the
pipeline to only ingest those new files with each run.
Which of the following tools can the data engineer use to solve this problem?
Answer: D
NEW QUESTION # 155
Spill occurs as a result of executing various wide transformations. However, diagnosing spill requires one to proactively look for key indicators.
Where in the Spark UI are two of the primary indicators that a partition is spilling to disk?
Answer: D
NEW QUESTION # 156
......
As is known to us, a suitable learning plan is very important for all people. For the sake of more competitive, it is very necessary for you to make a learning plan. We believe that our Databricks-Certified-Professional-Data-Engineer actual exam will help you make a good learning plan. You can have a model test in limited time by our Databricks-Certified-Professional-Data-Engineer Study Materials, if you finish the model test, our system will generate a report according to your performance. And in this way, you can have the best pass percentage on your Databricks-Certified-Professional-Data-Engineer exam.
New Databricks-Certified-Professional-Data-Engineer Exam Preparation: https://www.testinsides.top/Databricks-Certified-Professional-Data-Engineer-dumps-review.html