BONUS!!! Download part of PassLeader SPS-C01 dumps for free: https://drive.google.com/open?id=1iBtHfN0lok6c-fkVnBIMAeDhYnliJnO6
The Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice questions give you a feeling of a real exam which boost confidence. Practice under real Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam situations is an excellent way to learn more about the complexity of the Snowflake SPS-C01 Exam Dumps. You can learn from your Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice test mistakes and overcome them before the actual SPS-C01 exam.
| Section | Objectives |
|---|---|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Testing, Debugging, and Deployment | - Production readiness
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Data Engineering with Snowpark | - Pipeline development
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
>> SPS-C01 Reliable Torrent <<
In the PDF version, the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions are printable and portable. You can take these Snowflake SPS-C01 pdf dumps anywhere and even take a printout of Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions. The PDF version is mainly composed of real Snowflake SPS-C01 Exam Dumps. PassLeader updates regularly to improve its Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) pdf questions and also makes changes when required.
NEW QUESTION # 368
You've created a Snowpark Python UDF that uses a third-party library (e.g., scikit-learn) to perform machine learning inference. You need to ensure that this UDF is executed securely and efficiently in Snowflake. Which of the following approaches represent best practices for managing dependencies and securing the UDF environment? Select all that apply.
Answer: A,C
Explanation:
Including the library's code directly into the UDF is not manageable and maintainable. Snowflake's Anaconda channel simplifies dependency management by providing a curated set of packages. Snowflake's managed dependencies and secure execution environment ensure that the UDF runs in a secure and isolated environment. Disabling security is unacceptable. While external functions could manage dependencies, using the built-in Anaconda integration is simpler within Snowflake. It's also more performant than the overhead of an external function call.
NEW QUESTION # 369
You are working with a Snowpark DataFrame containing employee data, including columns 'employee_id', 'first_name', 'last_name', 'salary', and 'department'. You need to perform the following transformations: 1. Concatenate 'first_name' and into a new column called separating them with a space. 2. Increase each employee's salary by a percentage based on their 'department'. Department 'Sales' gets a 10% raise, 'Marketing' gets a 15% raise, and all other departments get a 5% raise. 3. Create a new column reflecting this raise. Which of the following Snowpark code snippets achieves these transformations correctly and efficiently? (Select all that apply)




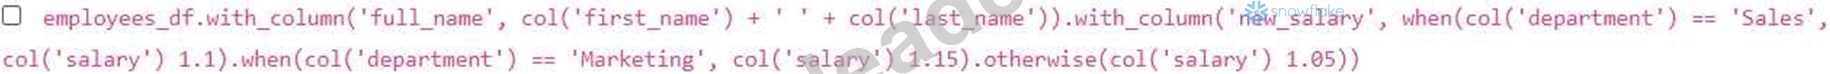
Answer: A,B
Explanation:
Options A and C are correct. Option A uses 'concat for string concatenation and 'when' for conditional salary calculation, which is a standard and efficient approach in Snowpark. Option C uses a Snowflake expression to achieve the same conditional salary calculation, which can be more concise for complex conditions and may leverage Snowflake's optimization. Option B is incorrect, because the '+' string concatenation will not work; string concatenation in Snowpark should happen using the 'concat' function. Option D is less efficient because it uses a Python UDF, which involves serialization/deserialization overhead. Option E will not work because of syntax 'select(' 'Y does not exist, therefore the user will need to specify all the columns. Also, there is a column called ' ' which will break the processing.
NEW QUESTION # 370
You have a Snowpark Python application that reads data from a Snowflake table named 'SALES DATA', performs several transformations using DataFrames, and then writes the results back to a new table named 'AGGREGATED SALES'. The application runs successfully, but you notice that the write operation to 'AGGREGATED SALES' is consistently slow. After examining the query profile, you observe significant skew in the data being written, causing some worker nodes to be overloaded. Which of the following techniques could you use within your Snowpark application to mitigate the data skew and improve the write performance to 'AGGREGATED SALES'?
Answer: B,E
Explanation:
Both options B and D address data skew directly. Option B, , attempts to redistribute data evenly, which can alleviate skew if the repartitioning strategy is effective (e.g., using a hash function). Option D, using a UDF and 'repartitionByRange' , allows for more sophisticated custom partitioning based on the skew key, potentially achieving a more balanced distribution. Increasing warehouse size (A) might provide more resources, but it doesn't directly address the skew. Sorting (C) can exacerbate skew by concentrating similar values on single nodes. Clustering (E) improves read performance after the data is written, but does not improve the write performance itself. Therefore, B and D are the best choices to reduce skew during the write operation.
NEW QUESTION # 371
A Snowpark application needs to manage multiple sessions concurrently, each connected to a different Snowflake warehouse for resource isolation. The application receives warehouse names dynamically at runtime. How can the application efficiently create and manage these sessions while ensuring proper resource cleanup?
Answer: A
Explanation:
Option B is the most reliable and recommended way to manage multiple sessions. It ensures resource isolation by creating separate sessions per warehouse. Closing each session properly, especially using a 'finally' block or context manager, prevents resource leaks and ensures sessions are closed even if errors occur. Option A can lead to unpredictable behavior if multiple threads or asynchronous tasks interact with the global session. Options C, D and E are generally incorrect or don't properly manage resource cleanup or isolation.
NEW QUESTION # 372
You are using Snowpark Python to transform a large DataFrame containing customer transaction data'. You need to persist the resulting DataFrame as a new Snowflake table named 'CUSTOMER TRANSACTIONS AGGREGATED', replacing the existing table if it exists. You want to explicitly define the schema of the new table to ensure data types are correctly enforced. Which of the following code snippets achieves this most efficiently and correctly?





Answer: A
Explanation:
Option A is the simplest and most direct way to achieve the desired outcome using the method with the 'overwrite' mode. While defining the schema is important, Snowflake infers the schema from the DataFrame if not explicitly provided. If schema inference isn't working, it should be investigated as a separate issue. Option B requires an intermediary view, which is less efficient. Options C and D are not valid Snowpark options. While you can specify file format related options (e.g. CSV options when writing to cloud storage), 'table_type' isn't one of them. Option E introduces the concept of schema definition, which, while important in general, is unnecessary if Snowflake can infer the correct schema. The question asks for the most efficient and correct answer, which is A.
NEW QUESTION # 373
......
The PDF file of SPS-C01 real exam questions is easy to use on laptops, tablets, and smartphones. We have added all the Snowflake SPS-C01 questions, which have a chance to appear in the Snowflake SPS-C01 real test. Our Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) dumps PDF exam questions are beneficial to prepare for the test in less time.
SPS-C01 Authorized Pdf: https://www.passleader.top/Snowflake/SPS-C01-exam-braindumps.html
BONUS!!! Download part of PassLeader SPS-C01 dumps for free: https://drive.google.com/open?id=1iBtHfN0lok6c-fkVnBIMAeDhYnliJnO6