Free demo is available for AI-300 training materials, so that you can have a deeper understanding of what you are going to buy. We also recommend you to have a try. In addition, AI-300 training materials are compiled by experienced experts, and they are quite familiar with the exam center, and if you choose us, you can know the latest information for the AI-300 Exam Dumps. We offer you free update for one year after buying AI-300 exam materials from us, and our system will send the latest version to your email automatically. So you just need to check your email, and change the your learning ways in accordance with new changes.
| Section | Objectives |
|---|---|
| Implement secure and scalable AI systems | - Security and governance
|
| Design and implement generative AI solutions | - Large language model integration
|
| Plan and design AI solutions using Azure AI services | - Responsible AI design
|
| Operationalizing machine learning solutions | - Deployment and monitoring
|
>> Practice Test AI-300 Fee <<
Taking the Microsoft AI-300 practice test is very beneficial to clear the Operationalizing Machine Learning and Generative AI Solutions AI-300 exam on the first try. You get awareness about the Microsoft AI-300 real exam environment because the AI-300 Practice Exam has an actual exam-like pattern. Furthermore, the Microsoft AI-300 practice test tracks and reports your performance.
NEW QUESTION # 171
Hotspot Question
You use Azure Machine Learning to train models across multiple experiments by using the same workspace.
You must record training runs in a centralized location to compare results from different jobs.
During training, performance values must be captured so they appear in the experiment run history.
You need to configure experiment tracking.
What should you configure for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.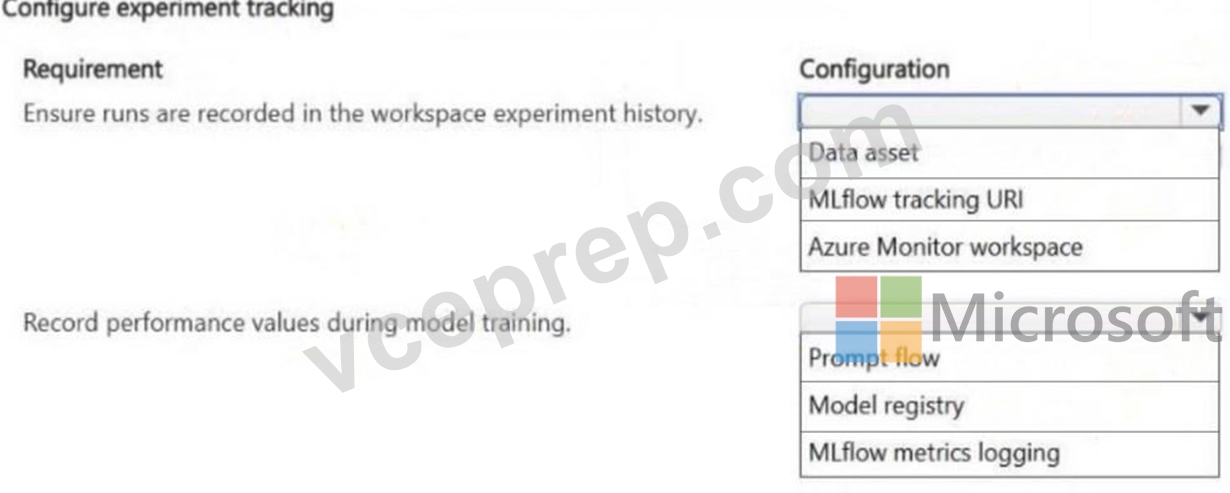
Answer:
Explanation: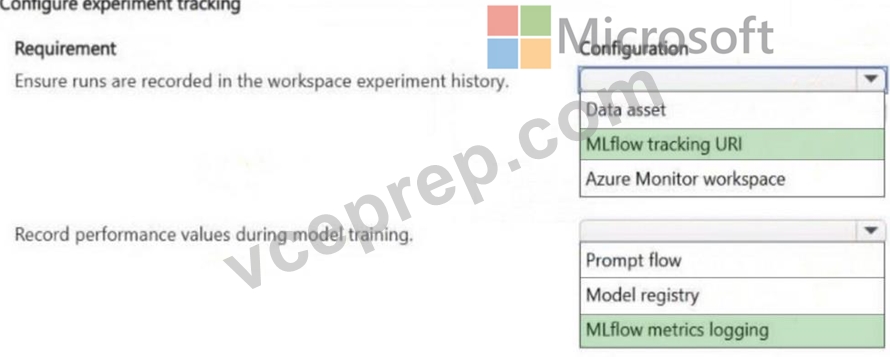
NEW QUESTION # 172
A Retrieval-Augmented Generation (RAG) solution returns incomplete answers because relevant content is inconsistently retrieved from the knowledge source.
You need to improve RAG accuracy without changing the embedding model currently in use. You need to achieve this goal while minimizing operational costs.
Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point. Choose two .
Answer: B,C
Explanation:
Microsoft ' s RAG optimization guidance identifies two high-impact, low-cost improvements for retrieval quality that do not require changing the embedding model. First, tuning chunk size and overlap (option A):
chunk size determines how much context each retrieved piece contains - too large and irrelevant content dilutes the signal; too small and answers may be split across chunks. Adjusting these parameters requires only re-indexing the documents with zero additional compute cost. Second, implementing a re-ranker (option B): a re-ranker is a cross-encoder model that takes the top-N retrieved chunks and re-scores them based on their specific relevance to the query, significantly improving precision by filtering out contextually irrelevant chunks. Re-rankers add modest compute cost but are far cheaper than changing the embedding model, which would require re-embedding the entire knowledge base. Increasing token limits (option C) and optimizing embedding vector length (option D) do not address retrieval accuracy without an embedding model change.
Microsoft Learn Reference Topic: Optimize RAG pipelines - Chunk size tuning and re-ranking in Azure AI Search and Azure Machine Learning
NEW QUESTION # 173
A team develops and manages a conversational assistant by using Microsoft Foundry.
The team requires generative AI to automatically evaluate every pull request of an agentic application and fail the build if safety thresholds are exceeded.
You need to automate evaluations as part of CI.
What should you configure?
Answer: C
Explanation:
The correct solution is a GitHub Actions workflow that executes Microsoft Foundry evaluations as part of the CI process . Microsoft provides an AI agent evaluation GitHub Action specifically for incorporating Foundry agent evaluations into CI/CD workflows. The action can invoke the agent against an evaluation dataset, execute configured evaluators-including safety evaluators-and publish evaluation results before a change reaches production.
For pull-request gating, the workflow can be configured to run whenever relevant application files change.
Evaluation commands can also enforce explicit thresholds and return a non-zero exit code when those thresholds are not satisfied. Microsoft documents evaluation gating through options such as --fail-on pass- rate= < threshold > or --fail-on any-failure; a non-zero result causes the CI job to fail, preventing unsafe changes from being promoted.
A blocklist or content filter provides runtime content protection but does not automate pull-request evaluation.
A retrieval chunking strategy affects RAG retrieval quality, not CI safety gates.
Therefore, the required mechanism is GitHub Actions integrated with Foundry evaluation runs and safety thresholds .
Study Guide Reference: Implement generative AI quality assurance and observability - automated evaluations, CI/CD quality gates, safety evaluators, GitHub Actions, and pre-production validation.
NEW QUESTION # 174
You manage an Azure Machine Learning workspace.
You must set up an event-driven process to trigger a retraining pipeline.
You need to configure an Azure service that will trigger a retraining pipeline in response to data drift in Azure Machine Learning datasets. Which Azure service should you use?
Answer: A
NEW QUESTION # 175
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_data.
The folder structure contains the following content: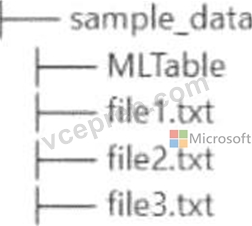
You write Python SDK v2 code to materialize the data from the files in the sample_data folder into a Pandas data frame.
You need to complete the Python SDK v2 code to use the MLTable folder as the materialization blueprint.
How should you complete the code? To answer, select the appropriate options in the answer area . NOTE:
Each correct selection is worth one point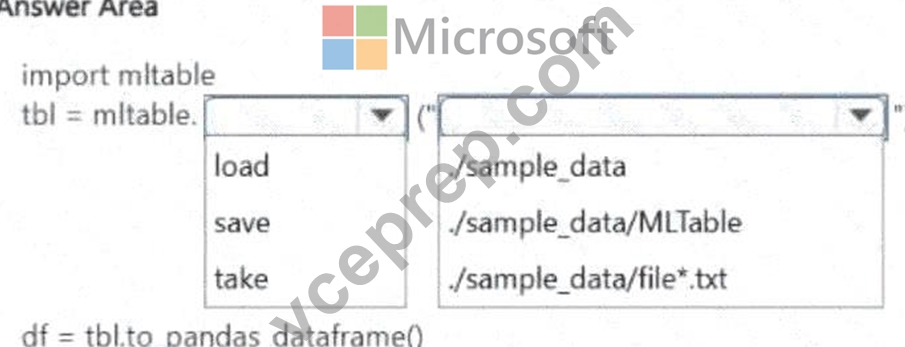
Answer:
Explanation: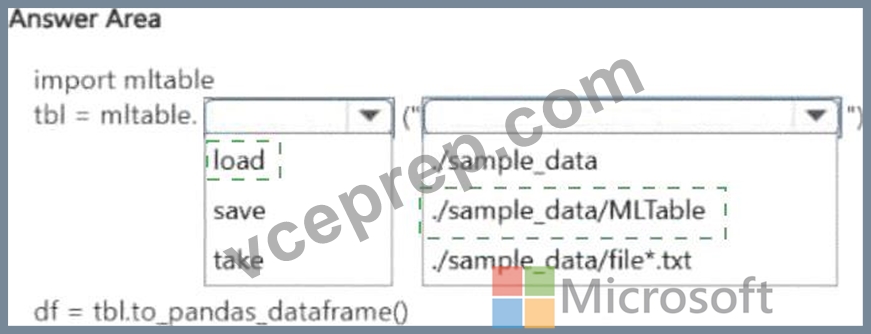
Explanation:
The MLTable format in Azure Machine Learning Python SDK v2 is a structured abstraction over tabular data sources. It stores a YAML file alongside data files, describing how to read and transform the data. To materialize this into a Pandas DataFrame, you use the mltable library: first call mltable.load with the path to the MLTable folder to load the definition, then call to_pandas_dataframe() on the returned object. The path parameter should point to the folder containing the MLTable YAML file on the default datastore. MLTable abstracts the storage location and transformation steps, making the code storage-agnostic - the same code works whether data lives in Blob Storage, ADLS Gen2, or a local path. The SDK v2 approach with MLTable is the recommended pattern for governed, reusable data access in Azure Machine Learning.
Microsoft Learn Reference Topic: Create and use MLTable data assets in Azure Machine Learning Python SDK v2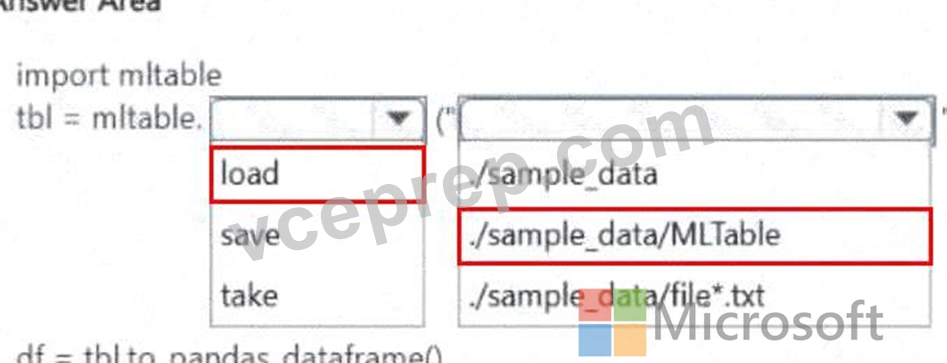
NEW QUESTION # 176
......
If you buy and use the AI-300 study materials from our company, you can complete the practice tests in a timed environment, receive grades and review test answers via video tutorials. You just need to download the software version of our AI-300 Study Materials after you buy our study materials. You will have the right to start to try to simulate the real examination. We believe that the AI-300 study materials from our company will not let you down.
Test AI-300 Engine Version: https://www.vceprep.com/AI-300-latest-vce-prep.html