All AI-200 online tests begin somewhere, and that is what the AI-200 training course will do for you: create a foundation to build on. Study guides are essentially a detailed AI-200 tutorial and are great introductions to new AI-200 training courses as you advance. The content is always relevant, and compound again to make you pass your AI-200 Exams on the first attempt. You will frequently find these AI-200 PDF files downloadable and can then archive or print them for extra reading or studying on-the-go.
| Section | Weight | Objectives |
|---|---|---|
| Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
| Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
>> AI-200 Latest Braindumps Sheet <<
DumpTorrent Developing AI Cloud Solutions on Azure (AI-200) practice material can be accessed instantly after purchase, so you won't have to face any excessive issues for preparation of your desired AI-200 certification exam. The AI-200 Exam Dumps of DumpTorrent has been made after seeking advice from many professionals. Our objective is to provide you with the best learning material to clear the Developing AI Cloud Solutions on Azure (AI-200) exam.
NEW QUESTION # 126
You are designing an Azure Database for PostgreSQL table for semantic search. Queries frequently filter on the created_at column.
The schema must support vector similarity search and reliable date filtering.
You need to ensure that the table meets the requirements.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
To meet the requirements, store embeddings in a pgvector column and use a typed timestamp column for created_at. These two steps enable high-dimensional vector similarity operations and allow efficient, reliable date-based filtering.
Store embeddings in a pgvector column: Enables the database to store and query high- dimensional vector embeddings using native similarity operators.
Use a typed timestamp column for created_at: Ensures accurate date-and-time comparisons, indexing, and dependable performance when filtering queries by creation date.
Reference:
https://learn.microsoft.com/en-us/training/modules/implement-vector-search-azure-database-postgresql/
NEW QUESTION # 127
Your chat application calls Azure OpenAI Service. You need to prevent the model from returning content that promotes self-harm, even if the prompt is crafted to bypass instructions. What should you configure?
Answer: A
Explanation:
System messages can be circumvented by adversarial prompting. Content Safety filters operate independently of the model and inspect both input and output, blocking harmful categories (including self-harm) regardless of prompt engineering.
NEW QUESTION # 128
You are developing several microservices to deploy to a new Azure Kubernetes Service cluster The microservices manage data stored m Azure Cosmos DB and Azure Blob storage. The data is secures by using customer managed keys stored in Azure Key Vault.
You must automate key rotation for all Azure Key Vault keys and allow for manual key rotation. Keys must rotate every three months. Notifications of expiring keys must be sent before key expiry.
You need to configure key rotation and enable key expiry notifications.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
NEW QUESTION # 129
Drag and Drop Question
You are developing a .NET application that uses Azure Cosmos DB for NoSQL to store application data.
The application uses the Azure Cosmos DB for NoSQL SDK to interact with the database account.
The application must perform the following tasks:
- Initialize the connection by using the account endpoint and key.
- Define shared throughput.
- Perform create, read, update, and delete (CRUD) operations on items
stored in a container.
You need to implement the SDK components required for the application to access and manage data in Azure Cosmos DB for NoSQL.
Which SDK components should you use? To answer, move the appropriate components to the correct requirements. You may use each component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.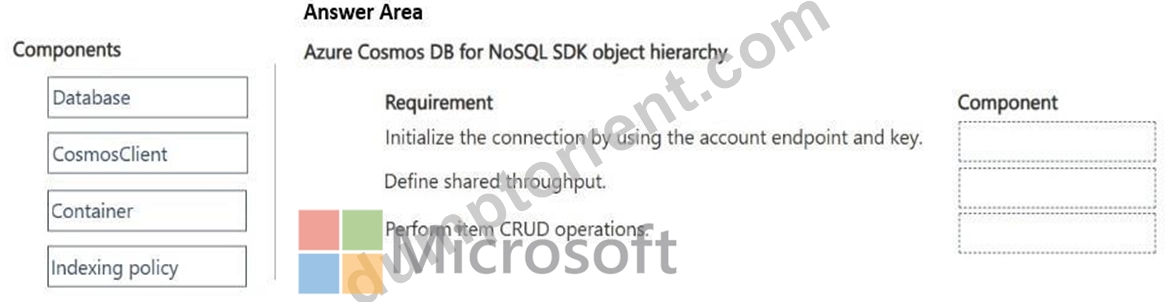
Answer:
Explanation: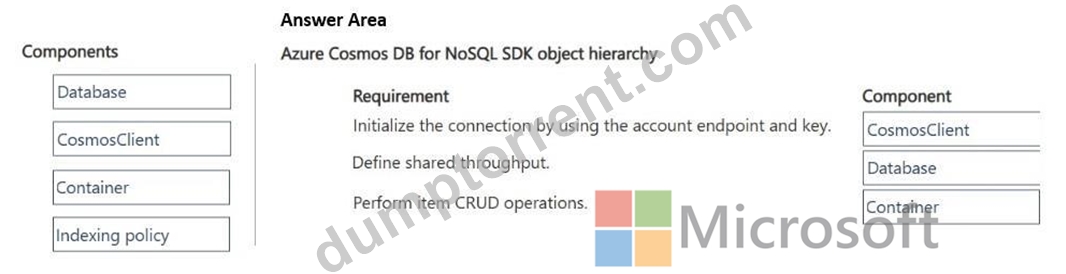
Explanation:
Box 1: CosmosClient
To initialize the connection to an Azure Cosmos DB for NoSQL account using the account endpoint and key, you must use the CosmosClient class.
Box 2: Database
The database SDK component should be used to define shared throughput.
In Azure Cosmos DB, shared throughput (provisioned Request Units per second or RU/s) is configured at the database level. When throughput is provisioned on a database, that capacity is shared among all the containers created within that specific database.
Box 3: Container
To perform item create, read, update, and delete (CRUD) operations, you should use the Container SDK component In the Azure Cosmos DB for NoSQL SDK for .NET, individual JSON documents (items) live inside a container. The Container class exposes the specific methods required to execute CRUD operations on these items.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/how-to-dotnet-get-started
NEW QUESTION # 130
A RAG application ' s retrieval step is returning documents that are topically related but not precisely relevant to the user ' s question.
You need to improve retrieval precision without retraining any model.
What should you do?
Answer: C
Explanation:
Enable semantic ranking in Azure AI Search . Semantic ranking is a query-time secondary re-ranking stage that evaluates the initial candidate results using Microsoft language-understanding models and promotes documents that are more semantically aligned with the user ' s actual query intent. It can operate over BM25 results, hybrid results, and the textual content associated with vector-search results.
This directly addresses the stated problem. Vector similarity retrieval often has strong recall but can return passages that are broadly related rather than specifically useful for answering the question. Microsoft ' s RAG guidance explains that reranking improves precision by taking the retrieved candidate set and reordering it so that the most query-relevant chunks are placed first. This reduces irrelevant context passed to the generation model and improves grounding quality without retraining either the embedding model or the LLM.
Increasing embedding dimensionality alone does not guarantee better relevance. Disabling vector search sacrifices semantic retrieval capability, while reducing the index size arbitrarily removes potentially useful content rather than improving ranking quality.
Therefore, semantic re-ranking is the correct precision-improvement mechanism .
Study Guide references: Azure AI Search # semantic ranker; RAG information retrieval; hybrid/vector search; secondary ranking; relevance optimization.
NEW QUESTION # 131
......
If you are preparing for the practice exam, we can make sure that the AI-200 study materials from our company will be the best choice for you, and you cannot find the better study materials than our company’. There are a lot of advantages of our AI-200 Study Materials, and then, I am going to introduce the special functions of our AI-200 study materials in detail to you. We are hopeful that you will like our products.
Reliable AI-200 Test Pattern: https://www.dumptorrent.com/AI-200-braindumps-torrent.html