Our accurate, reliable, and top-ranked Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam questions will help you qualify for your Databricks Databricks-Certified-Professional-Data-Engineer certification on the first try. Do not hesitate and check out Fast2test excellent Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice exam to stand out from the rest of the others.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Exam Format: | Multiple select, Multiple choice, Scenario-based questions |
| Related Certifications: | Databricks Certified Data Engineer Associate |
| Available Languages: | English |
| Passing Score: | 70% |
| Exam Price: | USD 200 |
| Real Exam Qty: | 60-70 |
| Certificate Validity Period: | 2 years |
| Exam Duration: | 120 minutes |
| Recommended Training: | Databricks Academy |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | Recommended: Databricks Certified Data Engineer Associate or equivalent experience with Spark and Databricks platform. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Reliable Databricks-Certified-Professional-Data-Engineer Test Practice <<
The page of our Databricks-Certified-Professional-Data-Engineer simulating materials provides demo which are sample questions. The purpose of providing demo is to let customers understand our part of the topic and what is the form of our study materials when it is opened? In our minds, these two things are that customers who care about the Databricks-Certified-Professional-Data-Engineer Exam may be concerned about most. We will give you our software which is a clickable website that you can visit the product page. Red box marked in our Databricks-Certified-Professional-Data-Engineer exam practice is demo; you can download PDF version for free, and you can click all three formats to see.
Databricks Certified Professional Data Engineer Exam is a comprehensive exam that covers a wide range of topics related to data engineering. It includes questions on data ingestion, data transformation, data storage, data processing, and data management using Databricks. Databricks-Certified-Professional-Data-Engineer Exam also covers topics such as cluster management, security, and performance optimization. Databricks-Certified-Professional-Data-Engineer exam is designed to test the candidate's ability to design, implement, and manage data engineering solutions using Databricks.
NEW QUESTION # 213
A table is registered with the following code: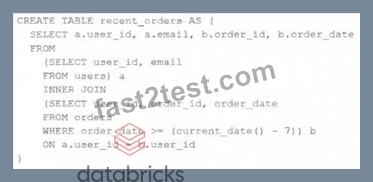
Bothusersandordersare Delta Lake tables. Which statement describes the results of queryingrecent_orders?
Answer: D
Explanation:
Explanation
This is the correct answer because Delta Lake supports time travel, which allows users to query data as of a specific version or timestamp. The code uses the VERSION AS OF syntax to specify the version of each source table to be used in the join. The result of querying recent_orders will be the same as joining those versions of the source tables at query time. The query will use snapshot isolation, which means it will use a consistent snapshot of the table at the time the query began, regardless of any concurrent updates or deletes.
Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Query an older snapshot of a table (time travel)" section.
NEW QUESTION # 214
When working with AUTO LOADER you noticed that most of the columns that were inferred as part of loading are string data types including columns that were supposed to be integers, how can we fix this?
Answer: D
Explanation:
Explanation
The answer is, Provide schema hints.
1.spark.readStream \
2.format("cloudFiles") \
3.option("cloudFiles.format", "csv") \
4.option("header", "true") \
5.option("cloudFiles.schemaLocation", schema_location) \
6.option("cloudFiles.schemaHints", "id int, description string")
7.load(raw_data_location)
8.writeStream \
9.option("checkpointLocation", checkpoint_location) \
10.start(target_delta_table_location)option("cloudFiles.schemaHints", "id int, description string")
# Here we are providing a hint that id column is int and the description is a string When cloudfiles.schemalocation is used to store the output of the schema inference during the load process, with schema hints you can enforce data types for known columns ahead of time.
NEW QUESTION # 215
An external object storage container has been mounted to the location/mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team: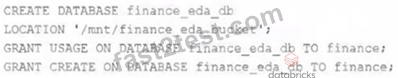
After the database was successfully created and permissions configured, a member of the finance team runs the following code: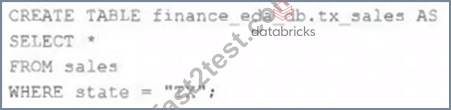
If all users on the finance team are members of thefinancegroup, which statement describes how thetx_sales table will be created?
Answer: A
Explanation:
Explanation
The code uses the CREATE TABLE USING DELTA command to create a Delta Lake table from an existing Parquet file stored in an external object storage container mounted to /mnt/finance_eda_bucket. The code also uses the LOCATION keyword to specify the path to the Parquet file as
/mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the code creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Create an external table" section.
NEW QUESTION # 216
A data engineer has configured their Databricks Asset Bundle with multiple targets in databricks.yml and deployed it to the production workspace. Now, to validate the deployment, they need to invoke a job named my_project_job specifically within the prod target context. Assuming the job is already deployed, they need to trigger its execution while ensuring the target-specific configuration is respected.
Which command will trigger the job execution?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks Asset Bundles (DABs) enable declarative configuration and deployment of Databricks resources such as jobs, pipelines, and dashboards across multiple environments.
Once deployed, jobs can be executed in a specific target context using the databricks bundle run command, which ensures all environment-specific configurations from the bundle definition (such as parameters, cluster settings, and workspace URLs) are respected.
The -t flag specifies the target environment (e.g., dev, staging, or prod). This ensures that the execution runs with the correct configuration defined under that target in databricks.yml.
Other options (A, B, and C) are invalid because they reference deprecated or incorrect command syntax that doesn't integrate with bundle targets. Therefore, D is the correct and verified answer.
NEW QUESTION # 217
The business intelligence team has a dashboard configured to track various summary metrics for retail stories. This includes total sales for the previous day alongside totals and averages for a variety of time periods. The fields required to populate this dashboard have the following schema:
For Demand forecasting, the Lakehouse contains a validated table of all itemized sales updated incrementally in near real-time. This table named products_per_order, includes the following fields:
Because reporting on long-term sales trends is less volatile, analysts using the new dashboard only require data to be refreshed once daily. Because the dashboard will be queried interactively by many users throughout a normal business day, it should return results quickly and reduce total compute associated with each materialization.
Which solution meets the expectations of the end users while controlling and limiting possible costs?
Answer: A
NEW QUESTION # 218
......
Practice Test Databricks-Certified-Professional-Data-Engineer Pdf: https://www.fast2test.com/Databricks-Certified-Professional-Data-Engineer-premium-file.html