그 외, KoreaDumps Databricks-Certified-Professional-Data-Engineer 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1yr6a1uNAC96tubpU9wvUdYI054IvO0aW
우리KoreaDumps 사이트에서Databricks Databricks-Certified-Professional-Data-Engineer관련자료의 일부 문제와 답 등 샘플을 제공함으로 여러분은 무료로 다운받아 체험해보실 수 있습니다.체험 후 우리의KoreaDumps에 신뢰감을 느끼게 됩니다.빨리 우리 KoreaDumps의 덤프를 만나보세요.
| Section | Objectives |
|---|---|
| Topic 1: Data Modeling and Storage | - Schema evolution and data partitioning strategies - Delta Lake table design and optimization - Design scalable data lakehouse architectures |
| Topic 2: Security, Governance, Monitoring, and Optimization | - Cost optimization and performance tuning - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads |
| Topic 3: Production Pipelines and Orchestration | - Build and manage workflows using Databricks Jobs - Automate ETL pipelines and scheduling - Pipeline reliability and fault tolerance |
| Topic 4: Data Ingestion and Transformation | - Handle batch and streaming data pipelines - Ingest data using Apache Spark and Databricks - Transform and clean datasets using Spark SQL and DataFrame APIs |
>> Databricks-Certified-Professional-Data-Engineer인증덤프공부문제 <<
Databricks인증 Databricks-Certified-Professional-Data-Engineer시험은 멋진 IT전문가로 거듭나는 길에서 반드시 넘어야할 높은 산입니다. Databricks인증 Databricks-Certified-Professional-Data-Engineer시험문제패스가 어렵다한들KoreaDumps덤프만 있으면 패스도 간단한 일로 변경됩니다. KoreaDumps의Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프는 100%시험패스율을 보장합니다. Databricks인증 Databricks-Certified-Professional-Data-Engineer시험문제가 업데이트되면Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프도 바로 업데이트하여 무료 업데이트서비스를 제공해드리기에 덤프유효기간을 연장해는것으로 됩니다.
질문 # 201
A data engineer is designing a pipeline in Databricks that processes records from a Kafka stream where late-arriving data is common.
Which approach should the data engineer use?
정답:B
설명:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
In Structured Streaming, event-time watermarks control how long the engine waits for late-arriving data before finalizing aggregations. By setting an appropriate watermark, Databricks can handle late data gracefully - incorporating records that arrive within the defined window while discarding excessively delayed events.
This approach ensures accurate aggregations, minimizes state size, and prevents memory leaks.
Manual reprocessing (A) or overwriting entire datasets (B) is inefficient and costly, while Auto CDC (C) is used for change tracking in Delta tables, not for streaming event lateness.
Thus, using watermarking is the recommended and official approach for managing late data in streaming pipelines.
질문 # 202
What is the main difference between AUTO LOADER and COPY INTO?
정답:A
설명:
Explanation
Auto loader supports both directory listing and file notification but COPY INTO only supports di-rectory listing.
Auto loader file notification will automatically set up a notification service and queue service that subscribe to file events from the input directory in cloud object storage like Azure blob storage or S3. File notification mode is more performant and scalable for large input directories or a high volume of files.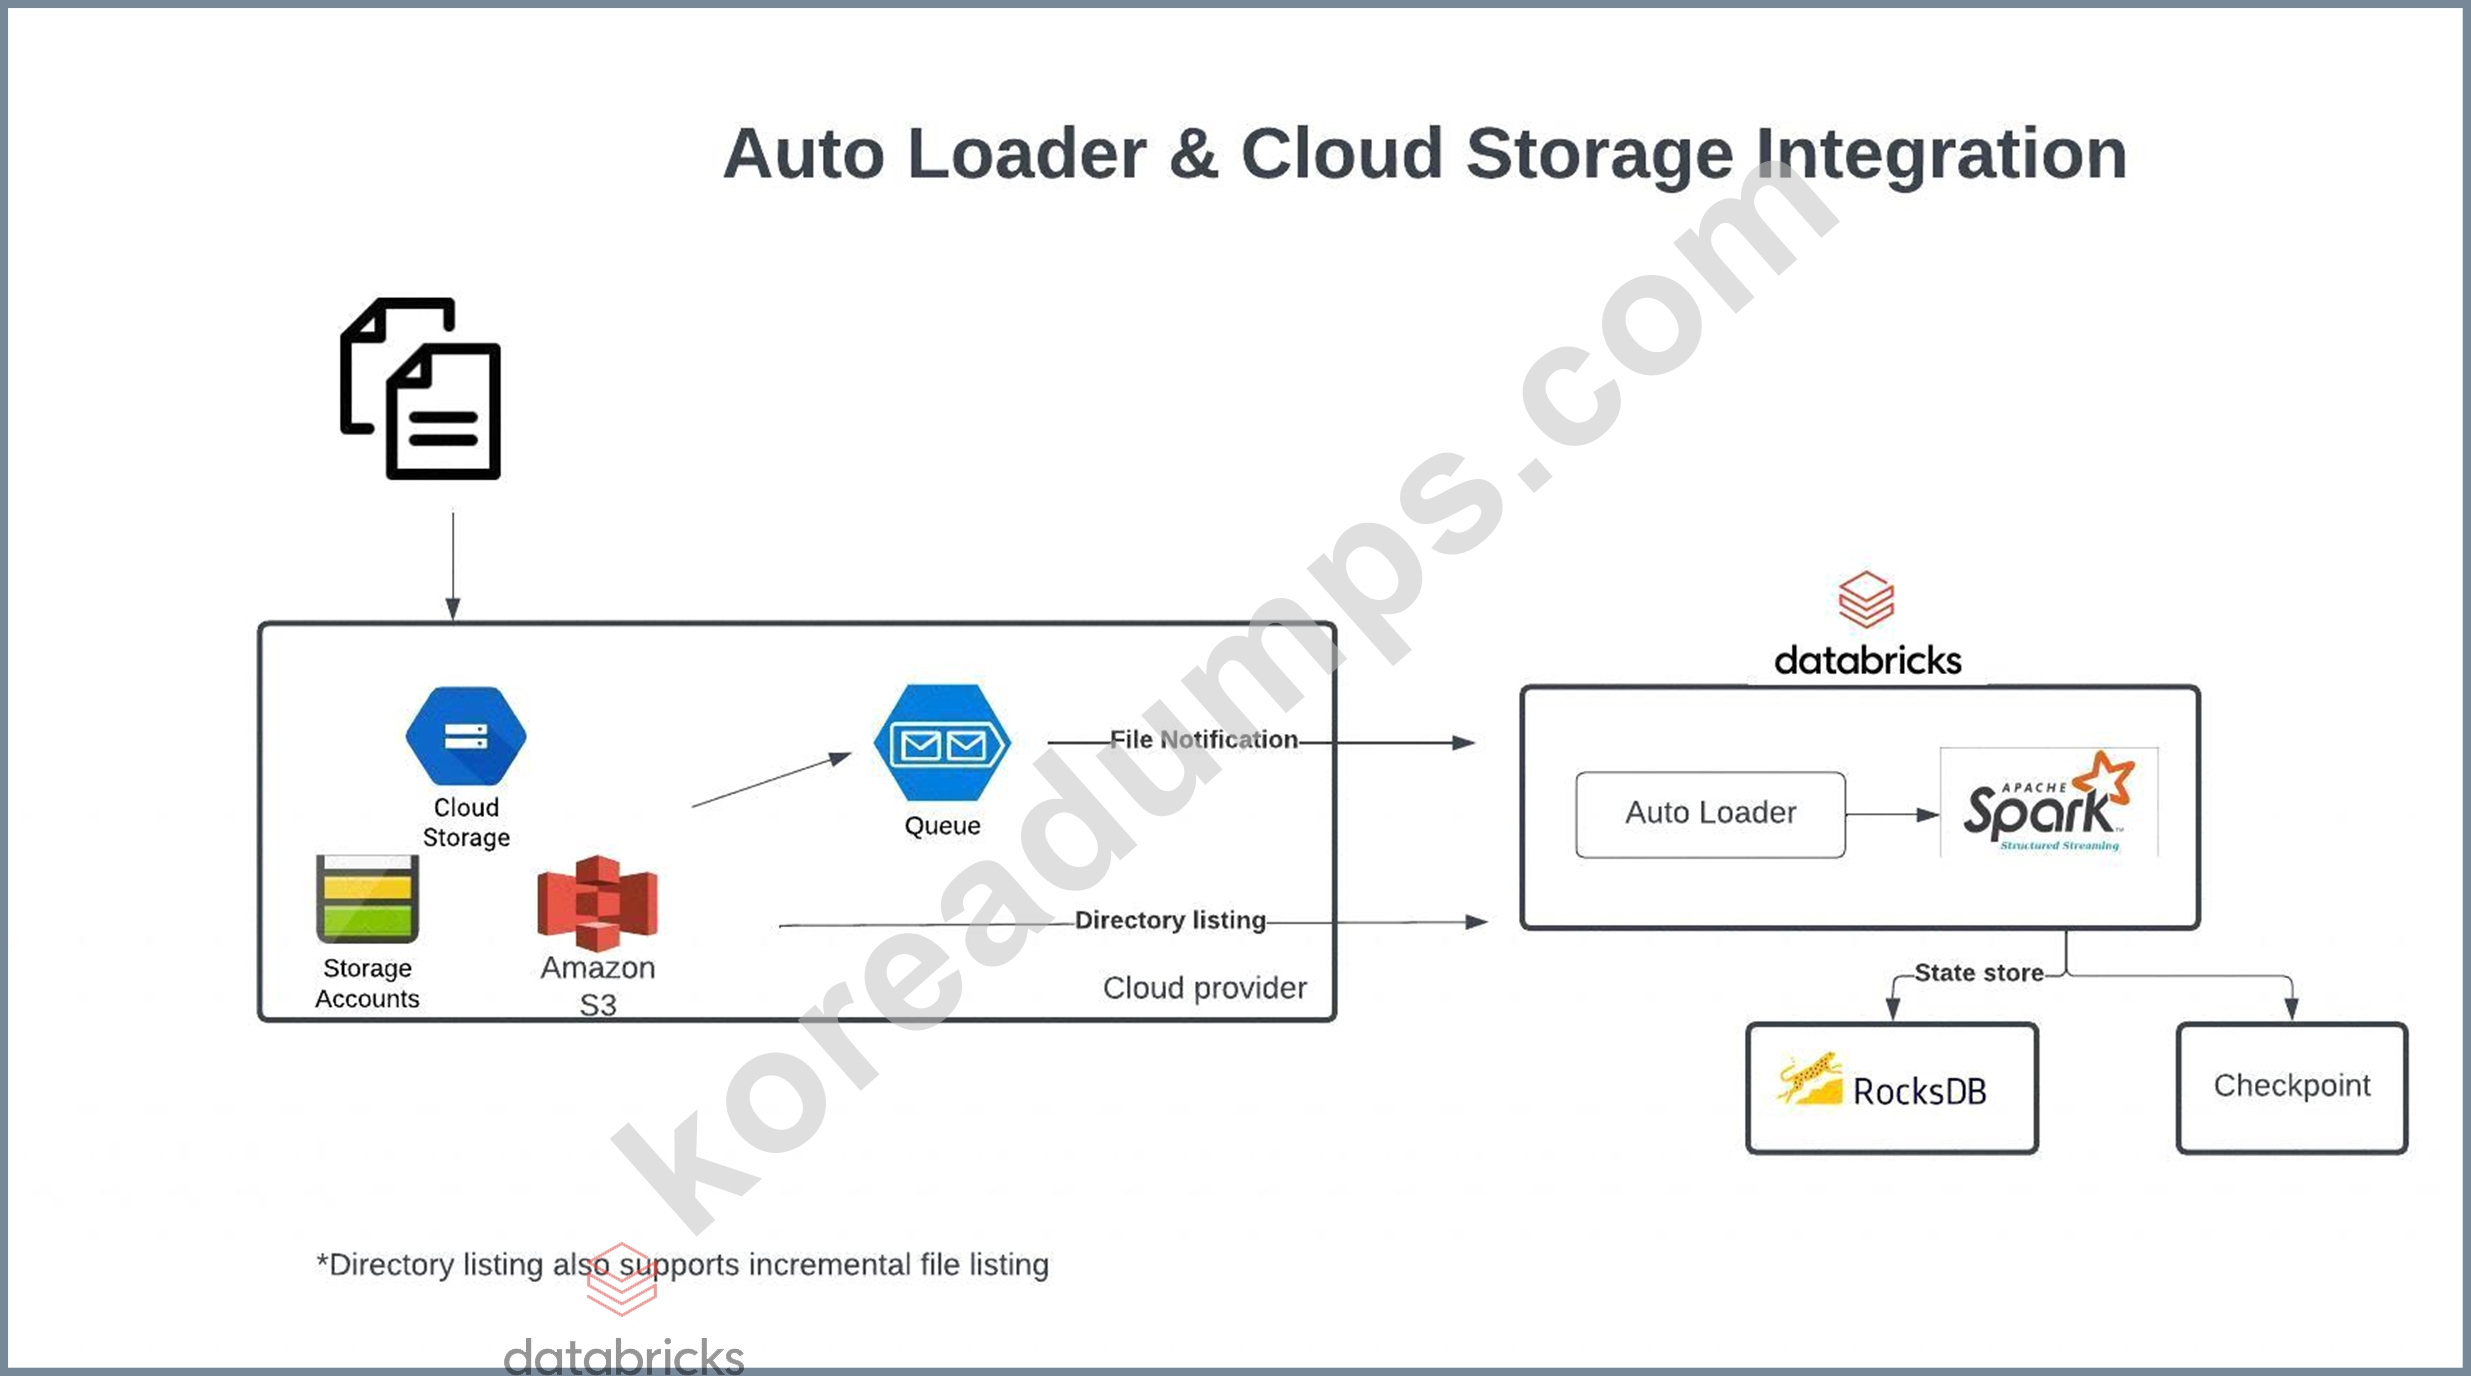
Auto Loader and Cloud Storage Integration
Auto Loader supports a couple of ways to ingest data incrementally
1.Directory listing - List Directory and maintain the state in RocksDB, supports incremental file listing
2.File notification - Uses a trigger+queue to store the file notification which can be later used to retrieve the file, unlike Directory listing File notification can scale up to millions of files per day.
[OPTIONAL]
Auto Loader vs COPY INTO?
Auto Loader
Auto Loader incrementally and efficiently processes new data files as they arrive in cloud storage without any additional setup. Auto Loader provides a new Structured Streaming source called cloudFiles. Given an input directory path on the cloud file storage, the cloudFiles source automatically processes new files as they arrive, with the option of also processing existing files in that directory.
When to use Auto Loader instead of the COPY INTO?
*You want to load data from a file location that contains files in the order of millions or higher. Auto Loader can discover files more efficiently than the COPY INTO SQL command and can split file processing into multiple batches.
*You do not plan to load subsets of previously uploaded files. With Auto Loader, it can be more difficult to reprocess subsets of files. However, you can use the COPY INTO SQL command to reload subsets of files while an Auto Loader stream is simultaneously running.
Auto loader file notification will automatically set up a notification service and queue service that subscribe to file events from the input directory in cloud object storage like Azure blob storage or S3. File notification mode is more performant and scalable for large input directories or a high volume of files.
Here are some additional notes on when to use COPY INTO vs Auto Loader
When to use COPY INTO
https://docs.databricks.com/delta/delta-ingest.html#copy-into-sql-command When to use Auto Loader
https://docs.databricks.com/delta/delta-ingest.html#auto-loader
질문 # 203
A data architect has heard about lake's built-in versioning and time travel capabilities. For auditing purposes they have a requirement to maintain a full of all valid street addresses as they appear in the customers table.
The architect is interested in implementing a Type 1 table, overwriting existing records with new values and relying on Delta Lake time travel to support long-term auditing. A data engineer on the project feels that a Type 2 table will provide better performance and scalability.
Which piece of information is critical to this decision?
정답:A
설명:
Setting multiple fields in a single update.
Explanation:
Delta Lake's time travel feature allows users to access previous versions of a table, providing a powerful tool for auditing and versioning. However, using time travel as a long-term versioning solution for auditing purposes can be less optimal in terms of cost and performance, especially as the volume of data and the number of versions grow. For maintaining a full history of valid street addresses as they appear in a customers table, using a Type 2 table (where each update creates a new record with versioning) might provide better scalability and performance by avoiding the overhead associated with accessing older versions of a large table. While Type 1 tables, where existing records are overwritten with new values, seem simpler and can leverage time travel for auditing, the critical piece of information is that time travel might not scale well in cost or latency for long-term versioning needs, making a Type 2 approach more viable for performance and scalability.
Reference:
Databricks Documentation on Delta Lake's Time Travel: Delta Lake Time Travel Databricks Blog on Managing Slowly Changing Dimensions in Delta Lake: Managing SCDs in Delta Lake
질문 # 204
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE This table is partitioned by the date column. A query is run with the following filter:
longitude < 20 and longitude > -20
Which statement describes how data will be filtered?
정답:B
설명:
This is the correct answer because it describes how data will be filtered when a query is run with the following filter: longitude < 20 and longitude > -20. The query is run on a Delta Lake table that has the following schema: user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE. This table is partitioned by the date column. When a query is run on a partitioned Delta Lake table, Delta Lake uses statistics in the Delta Log to identify data files that might include records in the filtered range. The statistics include information such as min and max values for each column in each data file. By using these statistics, Delta Lake can skip reading data files that do not match the filter condition, which can improve query performance and reduce I/O costs. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Data skipping" section.
질문 # 205
Which statement regarding stream-static joins and static Delta tables is correct?
정답:B
설명:
Explanation
This is the correct answer because stream-static joins are supported by Structured Streaming when one of the tables is a static Delta table. A static Delta table is a Delta table that is not updated by any concurrent writes, such as appends or merges, during the execution of a streaming query. In this case, each microbatch of a stream-static join will use the most recent version of the static Delta table as of each microbatch, which means it will reflect any changes made to the static Delta table before the start of each microbatch. Verified References:[Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Stream and static joins" section.
질문 # 206
......
KoreaDumps덤프를 IT국제인증자격증 시험대비자료중 가장 퍼펙트한 자료로 거듭날수 있도록 최선을 다하고 있습니다. Databricks Databricks-Certified-Professional-Data-Engineer 덤프에는Databricks Databricks-Certified-Professional-Data-Engineer시험문제의 모든 범위와 유형을 포함하고 있어 시험적중율이 높아 구매한 분이 모두 시험을 패스한 인기덤프입니다.만약 시험문제가 변경되어 시험에서 불합격 받으신다면 덤프비용 전액 환불해드리기에 안심하셔도 됩니다.
Databricks-Certified-Professional-Data-Engineer퍼펙트 덤프자료: https://www.koreadumps.com/Databricks-Certified-Professional-Data-Engineer_exam-braindumps.html
2026 KoreaDumps 최신 Databricks-Certified-Professional-Data-Engineer PDF 버전 시험 문제집과 Databricks-Certified-Professional-Data-Engineer 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1yr6a1uNAC96tubpU9wvUdYI054IvO0aW