DOWNLOAD the newest PrepAwayETE Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=18JmF56qcW5M65H31pjOBHHRFBx5oB4jB
PrepAwayETE offers actual and updated Databricks Databricks-Generative-AI-Engineer-Associate Dumps after seeing the students struggling to prepare quickly for the test. We have made this product after consulting with a lot of professionals so the students can be successful. PrepAwayETE has hired a team of professionals who work on a daily basis without caring about themselves to update the Databricks Databricks-Generative-AI-Engineer-Associate practice material.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Application Development | 30% | - Integrate with MLflow - Use Databricks Vector Search - Develop LLM chains and workflows - Build RAG applications |
| Topic 2: Design Applications | 14% | - Design solution architecture - Select appropriate models, tools and approaches - Decompose complex requirements into tasks |
| Topic 3: Evaluation and Monitoring | 12% | - Monitor application behavior and outputs - Evaluate model and application performance - Iterate and improve solutions |
| Topic 4: Governance | 8% | - Ensure compliance and security - Apply Unity Catalog for data governance - Manage access and permissions |
| Topic 5: Assembling and Deploying Apps | 22% | - Manage application lifecycle - Deploy models via Model Serving - Package and deploy applications |
| Topic 6: Data Preparation | 14% | - Implement data pipelines and transformations - Prepare and process data for LLM use - Manage data quality and format |
>> Certification Databricks-Generative-AI-Engineer-Associate Dumps <<
By reviewing these results, you will be able to know and remove your mistakes. These Databricks-Generative-AI-Engineer-Associate practice exams are created as per the pattern of the Databricks-Generative-AI-Engineer-Associate real examination. Therefore, Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) mock exam takers will experience the real exam environment. It will calm down their nerves so they can appear in the Databricks Databricks-Generative-AI-Engineer-Associate final test without anxiety or fear.
NEW QUESTION # 10
Which TWO chain components are required for building a basic LLM-enabled chat application that includes conversational capabilities, knowledge retrieval, and contextual memory?
Answer: D,F
Explanation:
Building a basic LLM-enabled chat application with conversational capabilities, knowledge retrieval, and contextual memory requires specific components that work together to process queries, maintain context, and retrieve relevant information. Databricks' Generative AI Engineer documentation outlines key components for such systems, particularly in the context of frameworks like LangChain or Databricks' MosaicML integrations. Let's evaluate the required components:
* Understanding the Requirements:
* Conversational capabilities: The app must generate natural, coherent responses.
* Knowledge retrieval: It must access external or domain-specific knowledge.
* Contextual memory: It must remember prior interactions in the conversation.
* Databricks Reference:"A typical LLM chat application includes a memory component to track conversation history and a retrieval mechanism to incorporate external knowledge"("Databricks Generative AI Cookbook," 2023).
* Evaluating the Options:
* A. (Q): This appears incomplete or unclear (possibly a typo). Without further context, it's not a valid component.
* B. Vector Stores: These store embeddings of documents or knowledge bases, enabling semantic search and retrieval of relevant information for the LLM. This is critical for knowledge retrieval in a chat application.
* Databricks Reference:"Vector stores, such as those integrated with Databricks' Lakehouse, enable efficient retrieval of contextual data for LLMs"("Building LLM Applications with Databricks").
* C. Conversation Buffer Memory: This component stores the conversation history, allowing the LLM to maintain context across multiple turns. It's essential for contextual memory.
* Databricks Reference:"Conversation Buffer Memory tracks prior user inputs and LLM outputs, ensuring context-aware responses"("Generative AI Engineer Guide").
* D. External tools: These (e.g., APIs or calculators) enhance functionality but aren't required for a basicchat app with the specified capabilities.
* E. Chat loaders: These might refer to data loaders for chat logs, but they're not a core chain component for conversational functionality or memory.
* F. React Components: These relate to front-end UI development, not the LLM chain's backend functionality.
* Selecting the Two Required Components:
* Forknowledge retrieval, Vector Stores (B) are necessary to fetch relevant external data, a cornerstone of Databricks' RAG-based chat systems.
* Forcontextual memory, Conversation Buffer Memory (C) is required to maintain conversation history, ensuring coherent and context-aware responses.
* While an LLM itself is implied as the core generator, the question asks for chain components beyond the model, making B and C the minimal yet sufficient pair for a basic application.
Conclusion: The two required chain components areB. Vector StoresandC. Conversation Buffer Memory, as they directly address knowledge retrieval and contextual memory, respectively, aligning with Databricks' documented best practices for LLM-enabled chat applications.
NEW QUESTION # 11
What is an effective method to preprocess prompts using custom code before sending them to an LLM?
Answer: A
Explanation:
The most effective way to preprocess prompts using custom code is to write a custom model, such as an MLflow PyFunc model. Here's a breakdown of why this is the correct approach:
* MLflow PyFunc Models:MLflow is a widely used platform for managing the machine learning lifecycle, including experimentation, reproducibility, and deployment. APyFuncmodel is a generic Python function model that can implement custom logic, which includes preprocessing prompts.
* Preprocessing Prompts:Preprocessing could include various tasks like cleaning up the user input, formatting it according to specific rules, or augmenting it with additional context before passing it to the LLM. Writing this preprocessing as part of a PyFunc model allows the custom code to be managed, tested, and deployed easily.
* Modular and Reusable:By separating the preprocessing logic into a PyFunc model, the system becomes modular, making it easier to maintain and update without needing to modify the core LLM or retrain it.
* Why Other Options Are Less Suitable:
* A (Modify LLM's Internal Architecture): Directly modifying the LLM's architecture is highly impractical and can disrupt the model's performance. LLMs are typically treated as black-box models for tasks like prompt processing.
* B (Avoid Custom Code): While it's true that LLMs haven't been explicitly trained with preprocessed prompts, preprocessing can still improve clarity and alignment with desired input formats without confusing the model.
* C (Postprocessing Outputs): While postprocessing the output can be useful, it doesn't address the need for clean and well-formatted inputs, which directly affect the quality of the model's responses.
Thus, using an MLflow PyFunc model allows for flexible and controlled preprocessing of prompts in a scalable way, making it the most effective method.
NEW QUESTION # 12
A Generative AI Engineer I using the code below to test setting up a vector store: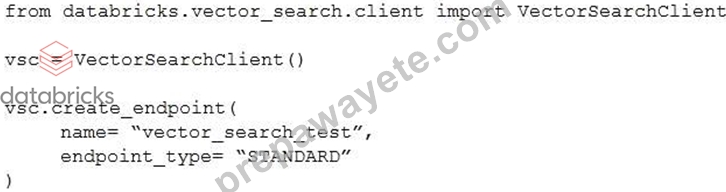
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 13
Generative AI Engineer at an electronics company just deployed a RAG application for customers to ask questions about products that the company carries. However, they received feedback that the RAG response often returns information about an irrelevant product.
What can the engineer do to improve the relevance of the RAG's response?
Answer: C
Explanation:
In a Retrieval-Augmented Generation (RAG) system, the key to providing relevant responses lies in the quality of the retrieved context. Here's why option A is the most appropriate solution:
* Context Relevance:The RAG model generates answers based on retrieved documents or context. If the retrieved information is about an irrelevant product, it suggests that the retrieval step is failing to select the right context. The Generative AI Engineer must first assess the quality of what is being retrieved and ensure it is pertinent to the query.
* Vector Search and Embedding Similarity:RAG typically uses vector search for retrieval, where embeddings of the query are matched against embeddings of product descriptions. Assessing the semantic similarity searchprocess ensures that the closest matches are actually relevant to the query.
* Fine-tuning the Retrieval Process:By improving theretrieval quality, such as tuning the embeddings or adjusting the retrieval strategy, the system can return more accurate and relevant product information.
* Why Other Options Are Less Suitable:
* B (Caching FAQs): Caching can speed up responses for frequently asked questions but won't improve the relevance of the retrieved content for less frequent or new queries.
* C (Use a Different LLM): Changing the LLM only affects the generation step, not the retrieval process, which is the core issue here.
* D (Different Semantic Search Algorithm): This could help, but the first step is to evaluate the current retrieval context before replacing the search algorithm.
Therefore, improving and assessing the quality of the retrieved context (option A) is the first step to fixing the issue of irrelevant product information.
NEW QUESTION # 14
A Generative AI Engineer is using LangGraph to define multiple tools in a single agentic application. They want to enable the main orchestrator LLM to decide on its own which tools are most appropriate to call for a given prompt. To do this, they must determine the general flow of the code. Which sequence will do this?
Answer: D
Explanation:
In modern agentic frameworks like LangGraph or LangChain, the standard workflow for creating an autonomous tool-calling agent follows a specific sequence. First, tools must be defined (often as Python functions with clear docstrings, which the LLM uses to understand the tool ' s purpose). Second, the agent logic is defined, which specifies how the LLM should think. Third, the agent is initialized using a logic pattern like ReAct (Reason + Act). The ReAct framework is essential here because it enables the " orchestrator " loop: the LLM receives a prompt, generates a " Thought " about which tool to use, generates an
" Action " to call that tool, receives an " Observation " (the tool ' s output), and repeats until it can provide a final answer. Loading tools into " separate agents " (C) or defining tools " inside " agents (D) are non-standard patterns that add unnecessary complexity and do not align with the centralized orchestration model required for LangGraph.
NEW QUESTION # 15
......
PrepAwayETE helps you in doing self-assessment so that you reduce your chances of failure in the examination of Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) certification. Similarly, this desktop Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) practice exam software of PrepAwayETE is compatible with all Windows-based computers. You need no internet connection for it to function. The Internet is only required at the time of product license validation.
Valid Databricks-Generative-AI-Engineer-Associate Test Online: https://www.prepawayete.com/Databricks/Databricks-Generative-AI-Engineer-Associate-practice-exam-dumps.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by PrepAwayETE: https://drive.google.com/open?id=18JmF56qcW5M65H31pjOBHHRFBx5oB4jB