Certified-Data-Engineer-Professional latest exam torrent & Certified-Data-Engineer-Professional pass-guaranteed dumps

It was never so easy to make your way to the world’s most rewarding professional qualification as it has become now! ITCertMagic’ Certified-Data-Engineer-Professional practice test questions answers are the best option to secure your success in just one go. You can easily answer all exam questions by doing our Certified-Data-Engineer-Professional exam dumps repeatedly. For further sharpening your skills, practice mock tests using our Certified-Data-Engineer-Professional Brain Dumps Testing Engine software and overcome your fear of failing exam. Our Databricks Certified Data Engineer Professional dumps are the most trustworthy, reliable and the best helpful study content that will prove the best alternative to your time and money.
| Section | Objectives |
|---|
| Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 2. Create pipeline components using control flow operators such as if/else and foreach
- 3. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 4. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 7. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 8. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
>> New Certified-Data-Engineer-Professional Test Objectives <<
Certified-Data-Engineer-Professional exam dumps
Preparation for the professional Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam is no more difficult because experts have introduced the preparatory products. With ITCertMagic products, you can pass the Databricks Certified-Data-Engineer-Professional Exam on the first attempt. If you want a promotion or leave your current job, you should consider achieving a professional certification like Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam.
Databricks Certified Data Engineer Professional Sample Questions (Q128-Q133):
NEW QUESTION # 128
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
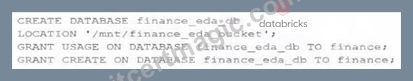
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
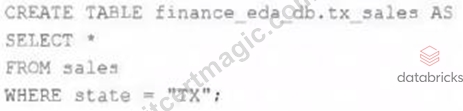
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. An managed table will be created in the storage container mounted to /mnt/finance_eda_bucket.
- B. A managed table will be created in the DBFS root storage container.
- C. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
- D. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
- E. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
Answer: A
Explanation:
https://docs.databricks.com/en/data-governance/unity-catalog/create-schemas.html#language-SQL
NEW QUESTION # 129
Where in the Spark UI can one diagnose a performance problem induced by not leveraging predicate push-down?
- A. In the Delta Lake transaction log. by noting the column statistics
- B. In the Storage Detail screen, by noting which RDDs are not stored on disk
- C. In the Stage's Detail screen, in the Completed Stages table, by noting the size of data read from the Input column
- D. In the Query Detail screen, by interpreting the Physical Plan
- E. In the Executor's log file, by gripping for "predicate push-down"
Answer: D
Explanation:
This is the correct answer because it is where in the Spark UI one can diagnose a performance problem induced by not leveraging predicate push-down. Predicate push-down is an optimization technique that allows filtering data at the source before loading it into memory or processing it further. This can improve performance and reduce I/O costs by avoiding reading unnecessary data. To leverage predicate push-down, one should use supported data sources and formats, such as Delta Lake, Parquet, or JDBC, and use filter expressions that can be pushed down to the source. To diagnose a performance problem induced by not leveraging predicate push-down, one can use the Spark UI to access the Query Detail screen, which shows information about a SQL query executed on a Spark cluster. The Query Detail screen includes the Physical Plan, which is the actual plan executed by Spark to perform the query. The Physical Plan shows the physical operators used by Spark, such as Scan, Filter, Project, or Aggregate, and their input and output statistics, such as rows and bytes. By interpreting the Physical Plan, one can see if the filter expressions are pushed down to the source or not, and how much data is read or processed by each operator.
NEW QUESTION # 130
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on Task A.
If task A fails during a scheduled run, which statement describes the results of this run?
- A. Unless all tasks complete successfully, no changes will be committed to the Lakehouse; because task A failed, all commits will be rolled back automatically.
- B. Tasks B and C will attempt to run as configured; any changes made in task A will be rolled back due to task failure.
- C. Tasks B and C will be skipped; some logic expressed in task A may have been committed before task failure.
- D. Because all tasks are managed as a dependency graph, no changes will be committed to the Lakehouse until all tasks have successfully been completed.
- E. Tasks B and C will be skipped; task A will not commit any changes because of stage failure.
Answer: C
Explanation:
When a Databricks job runs multiple tasks with dependencies, the tasks are executed in a dependency graph. If a task fails, the downstream tasks that depend on it are skipped and marked as Upstream failed. However, the failed task may have already committed some changes to the Lakehouse before the failure occurred, and those changes are not rolled back automatically. Therefore, the job run may result in a partial update of the Lakehouse. To avoid this, you can use the transactional writes feature of Delta Lake to ensure that the changes are only committed when the entire job run succeeds. Alternatively, you can use the Run if condition to configure tasks to run even when some or all of their dependencies have failed, allowing your job to recover from failures and continue running.
NEW QUESTION # 131
A data engineer is designing a pipeline in Databricks that processes records from a Kafka stream where late-arriving data is common. Which approach should the data engineer use?
- A. Use an Auto CDC pipeline with batch tables to simplify late data handling.
- B. Use a watermark to specify the allowed lateness to accommodate records that arrive after their expected window, ensuring correct aggregation and state management.
- C. Use batch processing and overwrite the entire output table each time to ensure late data is incorporated correctly.
- D. Implement a custom solution using Databricks Jobs to periodically reprocess all historical data.
Answer: B
Explanation:
In Structured Streaming, event-time watermarks control how long the engine waits for late- arriving data before finalizing aggregations. By setting an appropriate watermark, Databricks can handle late data gracefully -- incorporating records that arrive within the defined window while discarding excessively delayed events.
This approach ensures accurate aggregations, minimizes state size, and prevents memory leaks.
Manual reprocessing (A) or overwriting entire datasets (B) is inefficient and costly, while Auto CDC (C) is used for change tracking in Delta tables, not for streaming event lateness.
Thus, using watermarking is the recommended and official approach for managing late data in streaming pipelines.
NEW QUESTION # 132
When scheduling Structured Streaming jobs for production, which configuration automatically recovers from query failures and keeps costs low?
- A. Cluster: Existing All-Purpose Cluster;
Retries: Unlimited;
Maximum Concurrent Runs: 1 - B. Cluster: New Job Cluster;
Retries: None;
Maximum Concurrent Runs: 1 - C. Cluster: Existing All-Purpose Cluster;
Retries: Unlimited;
Maximum Concurrent Runs: 1 - D. Cluster: Existing All-Purpose Cluster;
Retries: None;
Maximum Concurrent Runs: 1 - E. Cluster: New Job Cluster;
Retries: Unlimited;
Maximum Concurrent Runs: Unlimited
Answer: A
Explanation:
The configuration that automatically recovers from query failures and keeps costs low is to use a new job cluster, set retries to unlimited, and set maximum concurrent runs to 1. This configuration has the following advantages:
A new job cluster is a cluster that is created and terminated for each job run. This means that the cluster resources are only used when the job is running, and no idle costs are incurred. This also ensures that the cluster is always in a clean state and has the latest configuration and libraries for the job.
Setting retries to unlimited means that the job will automatically restart the query in case of any failure, such as network issues, node failures, or transient errors. This improves the reliability and availability of the streaming job, and avoids data loss or inconsistency. Setting maximum concurrent runs to 1 means that only one instance of the job can run at a time. This prevents multiple queries from competing for the same resources or writing to the same output location, which can cause performance degradation or data corruption. Therefore, this configuration is the best practice for scheduling Structured Streaming jobs for production, as it ensures that the job is resilient, efficient, and consistent.
NEW QUESTION # 133
......
Might it be said that you are enthused about drifting through the Databricks Certified Data Engineer Professional on the chief endeavor? Then, you are at the ideal locale for Databricks Certified-Data-Engineer-Professional exam. Databricks Certified-Data-Engineer-Professional Dumps gives you the most recent review material that has been figured out for you to pass the Databricks Certified-Data-Engineer-Professional on the key endeavor. ITCertMagic is moving these days and is essential to finding a tremendous compensation calling. Different promising beginners stand around inactively and cash due to including an invalid prep material for the Databricks Certified-Data-Engineer-Professional exam.
Certified-Data-Engineer-Professional Actual Test: https://www.itcertmagic.com/Databricks/real-Certified-Data-Engineer-Professional-exam-prep-dumps.html
- Practice Certified-Data-Engineer-Professional Test Engine 🖐 Certified-Data-Engineer-Professional Examcollection Dumps Torrent 🔢 Certified-Data-Engineer-Professional Dumps Cost 🎉 Open ▶ www.dumpsmaterials.com ◀ and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download exam materials for free ⏰Certified-Data-Engineer-Professional Examcollection Dumps Torrent
- Exam Certified-Data-Engineer-Professional Study Guide 🦆 Certified-Data-Engineer-Professional Reliable Test Simulator 🌅 Certified-Data-Engineer-Professional Study Tool 🛹 Open website ➥ www.pdfvce.com 🡄 and search for ➽ Certified-Data-Engineer-Professional 🢪 for free download 😁Certified-Data-Engineer-Professional Dumps Cost
- Certified-Data-Engineer-Professional Study Tool 🐙 Certified-Data-Engineer-Professional Study Tool 👒 Sample Certified-Data-Engineer-Professional Questions Answers 🎿 Enter ➠ www.prep4sures.top 🠰 and search for ▷ Certified-Data-Engineer-Professional ◁ to download for free 🍱Practice Certified-Data-Engineer-Professional Test Engine
- Latest Updated Databricks New Certified-Data-Engineer-Professional Test Objectives - Certified-Data-Engineer-Professional Databricks Certified Data Engineer Professional Actual Test 🔇 Download “ Certified-Data-Engineer-Professional ” for free by simply searching on ☀ www.pdfvce.com ️☀️ 👽Latest Certified-Data-Engineer-Professional Exam Review
- High Pass-Rate New Certified-Data-Engineer-Professional Test Objectives – Find Shortcut to Pass Certified-Data-Engineer-Professional Exam 🚪 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and obtain a free download on ⮆ www.prep4away.com ⮄ 🥇Certified-Data-Engineer-Professional Exam Topics Pdf
- Quiz 2026 Databricks Efficient Certified-Data-Engineer-Professional: New Databricks Certified Data Engineer Professional Test Objectives 🏓 Easily obtain ▷ Certified-Data-Engineer-Professional ◁ for free download through ➡ www.pdfvce.com ️⬅️ 🙅Positive Certified-Data-Engineer-Professional Feedback
- Test Certified-Data-Engineer-Professional Questions Pdf 🥰 Latest Certified-Data-Engineer-Professional Exam Review 🎹 Exam Certified-Data-Engineer-Professional Study Guide 🍇 The page for free download of ➤ Certified-Data-Engineer-Professional ⮘ on ▷ www.torrentvce.com ◁ will open immediately ↪Valid Certified-Data-Engineer-Professional Exam Sample
- Certified-Data-Engineer-Professional Dumps Cost 🧉 Positive Certified-Data-Engineer-Professional Feedback 📐 Sample Certified-Data-Engineer-Professional Questions Answers 🧒 Search for ▛ Certified-Data-Engineer-Professional ▟ and easily obtain a free download on ➠ www.pdfvce.com 🠰 👇Certified-Data-Engineer-Professional Exam Fee
- Latest Certified-Data-Engineer-Professional Exam Review 🤼 Sample Certified-Data-Engineer-Professional Questions Answers 😗 Positive Certified-Data-Engineer-Professional Feedback 👔 Search on ▷ www.dumpsmaterials.com ◁ for ➥ Certified-Data-Engineer-Professional 🡄 to obtain exam materials for free download 🔣Certified-Data-Engineer-Professional Exams
- Certified-Data-Engineer-Professional Examcollection Dumps Torrent 🧡 Exam Certified-Data-Engineer-Professional Study Guide ➿ Exam Certified-Data-Engineer-Professional Training ⚠ Open ☀ www.pdfvce.com ️☀️ and search for ( Certified-Data-Engineer-Professional ) to download exam materials for free 🧔Test Certified-Data-Engineer-Professional Questions Pdf
- Valid Certified-Data-Engineer-Professional Exam Sample 🏅 Valid Certified-Data-Engineer-Professional Exam Sample 🥝 Certified-Data-Engineer-Professional Examcollection Dumps Torrent 🏎 Enter ➡ www.examcollectionpass.com ️⬅️ and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download for free 🖕Practice Certified-Data-Engineer-Professional Test Engine
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes