We aim to leave no misgivings to our customers so that they are able to devote themselves fully to their studies on Databricks-Generative-AI-Engineer-Associate guide materials and they will find no distraction from us. I suggest that you strike while the iron is hot since time waits for no one. With our Databricks-Generative-AI-Engineer-Associate Exam Questions, you will be bound to pass the exam with the least time and effort for its high quality. With our Databricks-Generative-AI-Engineer-Associate study guide for 20 to 30 hours, you will be ready to take part in the exam and pass it with ease.
| Section | Objectives |
|---|---|
| Topic 1: Prompt Engineering | - Prompt evaluation
|
| Topic 2: Responsible AI and Governance | - Model governance
|
| Topic 3: Retrieval-Augmented Generation (RAG) | - Vector databases and embeddings
|
| Topic 4: Databricks Mosaic AI Platform | - Model development and serving
|
| Topic 5: Foundations of Generative AI | - Large Language Models (LLMs)
|
>> Databricks-Generative-AI-Engineer-Associate Latest Test Bootcamp <<
Our Databricks-Generative-AI-Engineer-Associate learning materials are famous for high quality, and we have the experienced experts to compile and verify Databricks-Generative-AI-Engineer-Associate exam dumps, the correctness and the quality can be guaranteed. Databricks-Generative-AI-Engineer-Associate learning materials contain both questions and answers, and you can have a quickly check after you finish practicing. Moreover, we offer you free update for one year, and you can know the latest information about the Databricks-Generative-AI-Engineer-Associate Exam Materials if you choose us. The update version will be sent to your email automatically.
NEW QUESTION # 56
A Generative AI Engineer is creating an agent-based LLM system for their favorite monster truck team. The system can answer text based questions about the monster truck team, lookup event dates via an API call, or query tables on the team's latest standings.
How could the Generative AI Engineer best design these capabilities into their system?
Answer: A
Explanation:
In this scenario, the Generative AI Engineer needs to design a system that can handle different types of queries about the monster truck team. The queries may involve text-based information, API lookups for event dates, or table queries for standings. The best solution is to implement a tool-based agent system.
Here's how option B works, and why it's the most appropriate answer:
System Design Using Agent-Based Model:
In modern agent-based LLM systems, you can design a system where the LLM (Large Language Model) acts as a central orchestrator. The model can "decide" which tools to use based on the query. These tools can include API calls, table lookups, or natural language searches. The system should contain a system prompt that informs the LLM about the available tools.
System Prompt Listing Tools:
By creating a well-crafted system prompt, the LLM knows which tools are at its disposal. For instance, one tool may query an external API for event dates, another might look up standings in a database, and a third may involve searching a vector database for general text-based information. The agent will be responsible for calling the appropriate tool depending on the query.
Agent Orchestration of Calls:
The agent system is designed to execute a series of steps based on the incoming query. If a user asks for the next event date, the system will recognize this as a task that requires an API call. If the user asks about standings, the agent might query the appropriate table in the database. For text-based questions, it may call a search function over ingested data. The agent orchestrates this entire process, ensuring the LLM makes calls to the right resources dynamically.
Generative AI Tools and Context:
This is a standard architecture for integrating multiple functionalities into a system where each query requires different actions. The core design in option B is efficient because it keeps the system modular and dynamic by leveraging tools rather than overloading the LLM with static information in a system prompt (like option D).
Why Other Options Are Less Suitable:
A (RAG Architecture): While relevant, simply ingesting PDFs into a vector store only helps with text-based retrieval. It wouldn't help with API lookups or table queries.
C (Conditional Logic with RAG/API/TABLE): Although this approach works, it relies heavily on manual text parsing and might introduce complexity when scaling the system.
D (System Prompt with Event Dates and Standings): Hardcoding dates and table information into a system prompt isn't scalable. As the standings or events change, the system would need constant updating, making it inefficient.
By bundling multiple tools into a single agent-based system (as in option B), the Generative AI Engineer can best handle the diverse requirements of this system.
NEW QUESTION # 57
A Generative Al Engineer is building an LLM-based application that has an important transcription (speech-to-text) task. Speed is essential for the success of the application Which open Generative Al models should be used?
Answer: A
Explanation:
The task requires an open generative AI model for a transcription (speech-to-text) task where speed is essential. Let's assess the options based on their suitability for transcription and performance characteristics, referencing Databricks' approach to model selection.
Option A: Llama-2-70b-chat-hf
Llama-2 is a text-based LLM optimized for chat and text generation, not speech-to-text. It lacks transcription capabilities.
Databricks Reference: "Llama models are designed for natural language generation, not audio processing" ("Databricks Model Catalog").
Option B: MPT-30B-Instruct
MPT-30B is another text-based LLM focused on instruction-following and text generation, not transcription. It's irrelevant for speech-to-text tasks.
Databricks Reference: No specific mention, but MPT is categorized under text LLMs in Databricks' ecosystem, not audio models.
Option C: DBRX
DBRX, developed by Databricks, is a powerful text-based LLM for general-purpose generation. It doesn't natively support speech-to-text and isn't optimized for transcription.
Databricks Reference: "DBRX excels at text generation and reasoning tasks" ("Introducing DBRX," 2023)-no mention of audio capabilities.
Option D: whisper-large-v3 (1.6B)
Whisper, developed by OpenAI, is an open-source model specifically designed for speech-to-text transcription. The "large-v3" variant (1.6 billion parameters) balances accuracy and efficiency, with optimizations for speed via quantization or deployment on GPUs-key for the application's requirements.
Databricks Reference: "For audio transcription, models like Whisper are recommended for their speed and accuracy" ("Generative AI Cookbook," 2023). Databricks supports Whisper integration in its MLflow or Lakehouse workflows.
Conclusion: Only D. whisper-large-v3 is a speech-to-text model, making it the sole suitable choice. Its design prioritizes transcription, and its efficiency (e.g., via optimized inference) meets the speed requirement, aligning with Databricks' model deployment best practices.
NEW QUESTION # 58
When developing an LLM application, it's crucial to ensure that the data used for training the model complies with licensing requirements to avoid legal risks.
Which action is NOT appropriate to avoid legal risks?
Answer: C
Explanation:
* Problem Context: When using data to train a model, it's essential to ensure compliance with licensing to avoid legal risks. Legal issues can arise from using data without permission, especially when it comes from third-party sources.
* Explanation of Options:
* Option A: Reaching out to data curatorsbeforeusing the data is an appropriate action. This allows you to ensure you have permission or understand the licensing terms before starting to use the data in your model.
* Option B: Usingoriginal datathat you personally created is always a safe option. Since you have full ownership over the data, there are no legal risks, as you control the licensing.
* Option C: Using data that is explicitly labeled with an open license and adhering to the license terms is a correct and recommended approach. This ensures compliance with legal requirements.
* Option D: Reaching out to the data curatorsafteryou have already started using the trained model isnot appropriate. If you've already used the data without understanding its licensing terms, you may have already violated the terms of use, which could lead to legal complications. It's essential to clarify the licensing termsbeforeusing the data, not after.
Thus,Option Dis not appropriate because it could expose you to legal risks by using the data without first obtaining the proper licensing permissions.
NEW QUESTION # 59
A Generative Al Engineer interfaces with an LLM with prompt/response behavior that has been trained on customer calls inquiring about product availability. The LLM is designed to output "In Stock" if the product is available or only the term "Out of Stock" if not.
Which prompt will work to allow the engineer to respond to call classification labels correctly?
Answer: A
Explanation:
* Problem Context: The Generative AI Engineer needs a prompt that will enable an LLM trained on customer call transcripts to classify and respond correctly regarding product availability. The desired response should clearly indicate whether a product is "In Stock" or "Out of Stock," and it should be formatted in a way that is structured and easy to parse programmatically, such as JSON.
* Explanation of Options:
* Option A: Respond with "In Stock" if the customer asks for a product. This prompt is too generic and does not specify how to handle the case when a product is not available, nor does it provide a structured output format.
* Option B: This option is correctly formatted and explicit. It instructs the LLM to respond based on the availability mentioned in the customer call transcript and to format the response in JSON.
This structure allows for easy integration into systems that may need to process this information automatically, such as customer service dashboards or databases.
* Option C: Respond with "Out of Stock" if the customer asks for a product. Like option A, this prompt is also insufficient as it only covers the scenario where a product is unavailable and does not provide a structured output.
* Option D: While this prompt correctly specifies how to respond based on product availability, it lacks the structured output format, making it less suitable for systems that require formatted data for further processing.
Given the requirements for clear, programmatically usable outputs,Option Bis the optimal choice because it provides precise instructions on how to respond and includes a JSON format example for structuring the output, which is ideal for automated systems or further data handling.
NEW QUESTION # 60
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: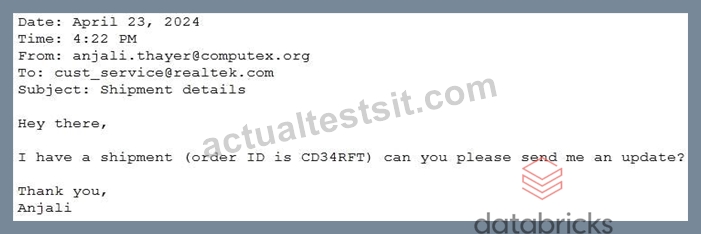
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: B
Explanation:
Problem Context : The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options :
* Option A : Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B : Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C : Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D : While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore, Option B is optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 61
......
According to different kinds of questionnaires based on study condition among different age groups, our Databricks-Generative-AI-Engineer-Associate test prep is totally designed for these study groups to improve their capability and efficiency when preparing for Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate Exams, thus inspiring them obtain the targeted Databricks Databricks-Generative-AI-Engineer-Associate certificate successfully.
Testking Databricks-Generative-AI-Engineer-Associate Learning Materials: https://www.actualtestsit.com/Databricks/Databricks-Generative-AI-Engineer-Associate-exam-prep-dumps.html