Databricks-Certified-Professional-Data-Engineer New Test Bootcamp - Databricks-Certified-Professional-Data-Engineer Dumps Torrent

The Databricks-Certified-Professional-Data-Engineer quiz torrent we provide is compiled by experts with profound experiences according to the latest development in the theory and the practice so they are of great value. Please firstly try out our product before you decide to buy our product. It is worthy for you to buy our Databricks-Certified-Professional-Data-Engineer exam preparation not only because it can help you pass the exam successfully but also because it saves your time and energy. If you buy our Databricks-Certified-Professional-Data-Engineer Test Prep you will pass the exam easily and successfully,and you will realize you dream to find an ideal job and earn a high income.
| Section | Weight | Objectives |
|---|
| Monitoring and Alerting | 10% | - Pipeline observability and logging
- Performance and health monitoring
- Setting up alerts and notifications
|
| Debugging and Deploying | 10% | - CI/CD and DevOps practices
- Deployment using bundles, CLI, and APIs
- Troubleshooting pipelines and errors
|
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access
- Unity Catalog data sharing
|
| Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion
- Connecting to diverse data sources
- Schema inference and evolution
|
| Cost & Performance Optimisation | 13% | - Cluster configuration and scaling
- Storage optimization (partitioning, Z-order, indexing)
- Query optimization and caching
|
| Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation
- Integration with Databricks APIs and tools
- Batch and incremental processing logic
|
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation
- Data encryption and masking
- Access control and permissions
|
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data
- Standardization and normalization
- Data validation and quality checks
|
| Data Modelling | 6% | - Delta Lake table design
- Medallion Architecture implementation
- Schema design and management
|
| Data Governance | 7% | - Unity Catalog management
- Data lineage and metadata tracking
- Policy enforcement
|
>> Databricks-Certified-Professional-Data-Engineer New Test Bootcamp <<
Another way to prepare for the Databricks-Certified-Professional-Data-Engineer Exam
We try to offer the best Databricks-Certified-Professional-Data-Engineer exam braindumps to our customers. First of all, in order to give users a better experience, we have been updating the system of Databricks-Certified-Professional-Data-Engineer simulating exam to meet the needs of more users. After the new version appears, we will also notify the user at the first time. Second, in terms of content, we guarantee that the content provided by our Databricks-Certified-Professional-Data-Engineer Study Materials is the most comprehensive.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q73-Q78):
NEW QUESTION # 73
An external object storage container has been mounted to the location/mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
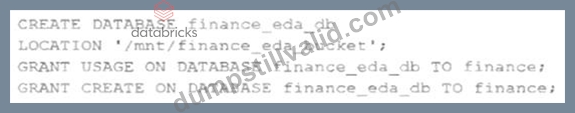
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
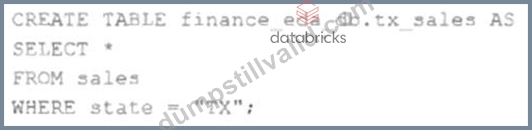
If all users on the finance team are members of thefinancegroup, which statement describes how thetx_sales table will be created?
- A. An managed table will be created in the storage container mounted to /mnt/finance eda bucket.
- B. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
- C. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
- D. A managed table will be created in the DBFS root storage container.
- E. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
Answer: A
Explanation:
https://docs.databricks.com/en/lakehouse/data-objects.html
NEW QUESTION # 74
What is the purpose of the bronze layer in a Multi-hop Medallion architecture?
- A. Contain aggregated data that is to be consumed into Silver
- B. Reduces data storage by compressing the data
- C. Copy of raw data, easy to query and ingest data for downstream processes.
- D. Data quality checks, corrupt data quarantined
- E. Powers ML applications
Answer: C
Explanation:
Explanation
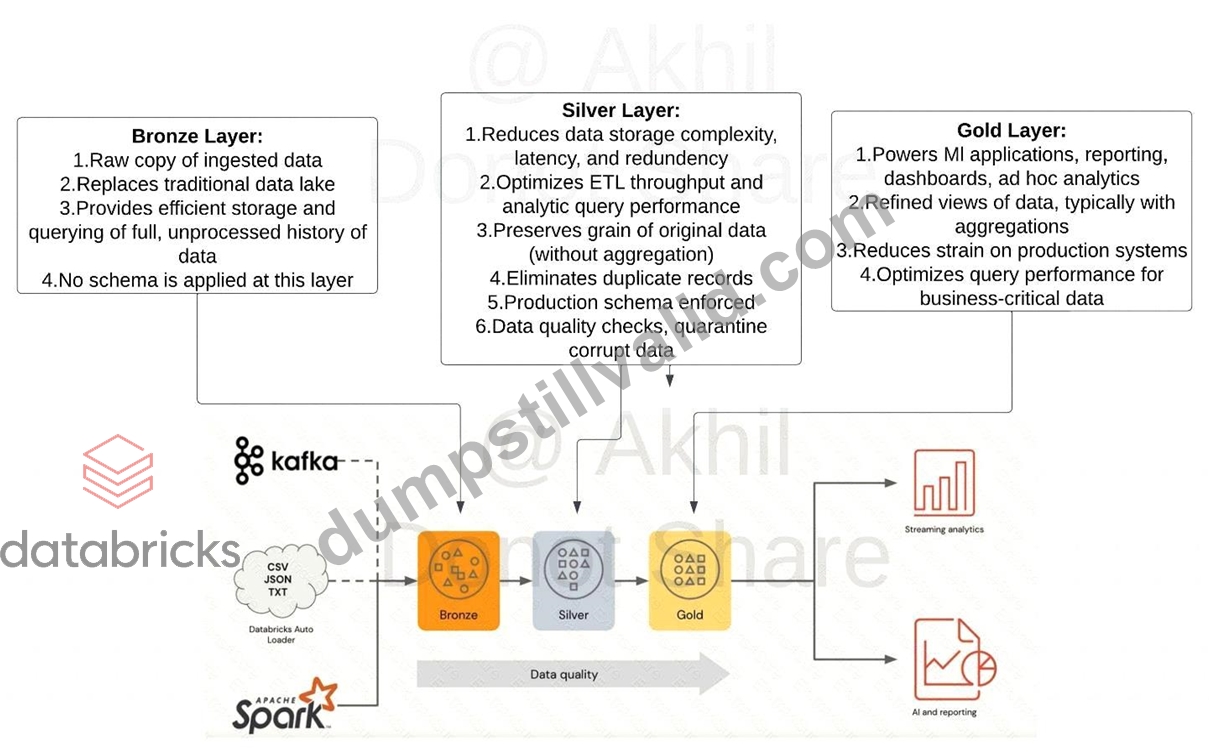
The answer is, copy of raw data, easy to query and ingest data for downstream processes, Medallion Architecture - Databricks Here are the typical role of Bronze Layer in a medallion architecture.
Bronze Layer:
1. Raw copy of ingested data
2. Replaces traditional data lake
3. Provides efficient storage and querying of full, unprocessed history of data
4. No schema is applied at this layer
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.
NEW QUESTION # 75
A dataset has been defined using Delta Live Tables and includes an expectations clause: CON-STRAINT valid_timestamp EXPECT (timestamp > '2020-01-01') ON VIOLATION DROP ROW What is the expected behavior when a batch of data containing data that violates these constraints is processed?
- A. Records that violate the expectation are added to the target dataset and recorded as invalid in the event log.
- B. Records that violate the expectation are added to the target dataset and flagged as in-valid in a field added to the target dataset.
- C. Records that violate the expectation are dropped from the target dataset and recorded as invalid in the event log.
- D. Records that violate the expectation are dropped from the target dataset and loaded into a quarantine table.
- E. Records that violate the expectation cause the job to fail.
Answer: C
Explanation:
Explanation
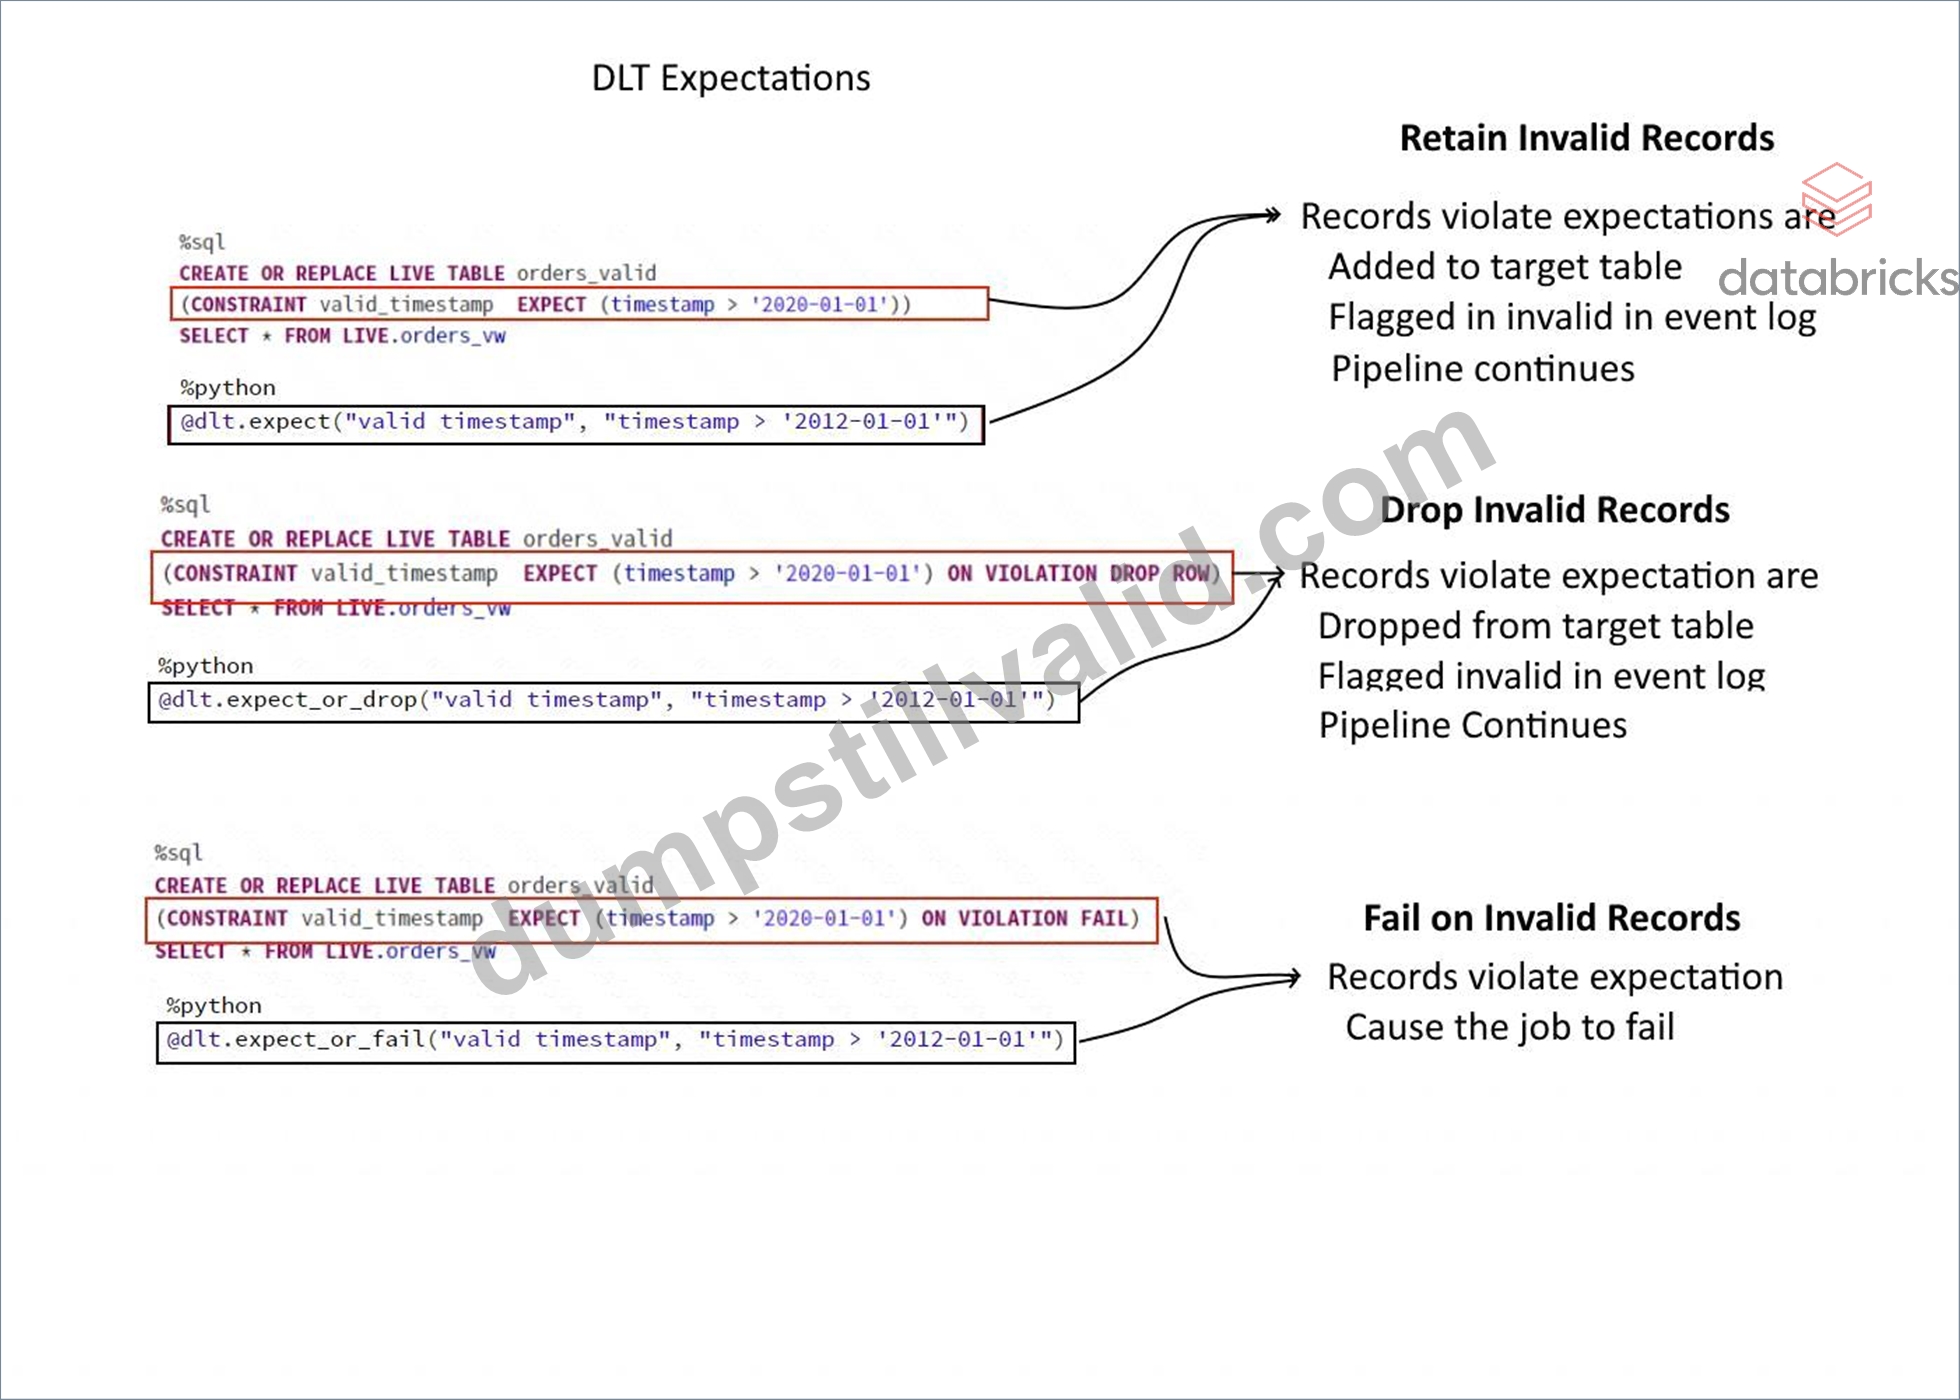
The answer is Records that violate the expectation are dropped from the target dataset and recorded as invalid in the event log.
Delta live tables support three types of expectations to fix bad data in DLT pipelines Review below example code to examine these expectations, Diagram Description automatically generated with medium confidence
NEW QUESTION # 76
Data engineering team has a job currently setup to run a task load data into a reporting table every day at 8: 00 AM takes about 20 mins, Operations teams are planning to use that data to run a second job, so they access latest complete set of data. What is the best to way to orchestrate this job setup?
- A. Add Operation reporting task in the same job and set the operations reporting task to depend on Data Engineering task
- B. Setup a Delta live to table based on the first table, set the job to run in continuous mode
- C. Use Auto Loader to run every 20 mins to read the initial table and set the trigger to once and create a second job
- D. Setup a second job to run at 8:20 AM in the same workspace
- E. Add Operation reporting task in the same job and set the Data Engineering task to de-pend on Operations reporting task
Answer: A
Explanation:
Explanation
The answer is Add Operation reporting task in the same job and set the operations reporting task to depend on Data Engineering task.
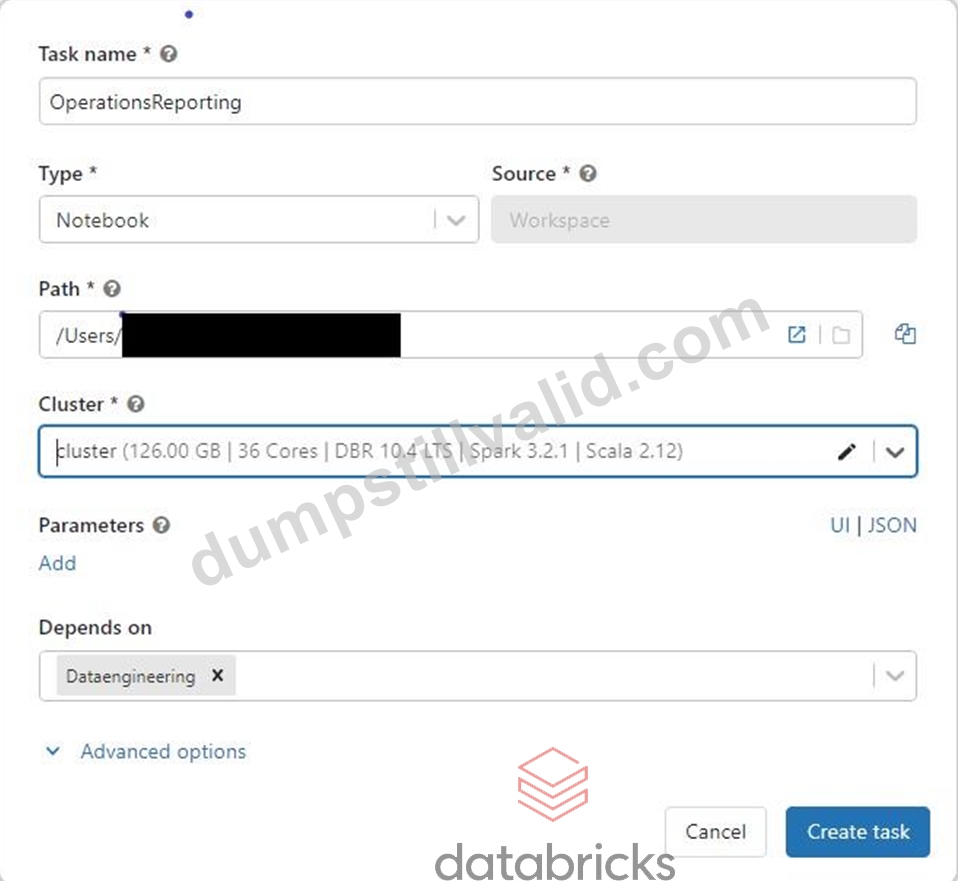
Diagram Description automatically generated with medium confidence
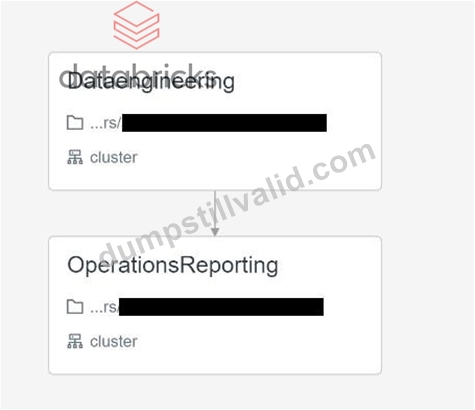
NEW QUESTION # 77
Given the following error traceback:
AnalysisException: cannot resolve ' heartrateheartrateheartrate ' given input columns:
[spark_catalog.database.table.device_id, spark_catalog.database.table.heartrate, spark_catalog.database.table.mrn, spark_catalog.database.table.time] The code snippet was:
display(df.select(3* " heartrate " ))
Which statement describes the error being raised?
- A. There is a syntax error because the heartrate column is not correctly identified as a column.
- B. There is a type error because a DataFrame object cannot be multiplied.
- C. There is no column in the table named heartrateheartrateheartrate.
- D. There is a type error because a column object cannot be multiplied.
Answer: C
Explanation:
* Exact extract: "select() expects column names or Column expressions."
* Exact extract: "When using strings directly, Spark SQL interprets them as literal column names."
* Exact extract: "Python string operations, such as " colname " *3, return repeated strings, not column expressions." The expression 3* " heartrate " is Python string multiplication, which evaluates to " heartrateheartrateheartrate
" . The select() method interprets this as a literal column name. Since there is no column with that name in the DataFrame schema, Spark raises AnalysisException saying it cannot resolve that column. To correctly multiply a column by a scalar, one must use the column expression form:
from pyspark.sql.functions import col
df.select((col( " heartrate " ) * 3).alias( " heartrate_x3 " ))
This ensures Spark evaluates the arithmetic operation on the column instead of misinterpreting the string.
References: PySpark DataFrame select; PySpark Column expressions with col().
NEW QUESTION # 78
......
We are benefiting more and more candidates for our excellent Databricks-Certified-Professional-Data-Engineer exam materials which is compiled by the professional experts accurately and skillfully. We are called the best friend on the way with our customers to help pass their Databricks-Certified-Professional-Data-Engineer exam and help achieve their dreaming certification. The reason is that we not only provide our customers with valid and reliable Databricks-Certified-Professional-Data-Engineer study questions, but also offer best service online since we uphold the professional ethical.
Databricks-Certified-Professional-Data-Engineer Dumps Torrent: https://www.dumpstillvalid.com/Databricks-Certified-Professional-Data-Engineer-prep4sure-review.html
- Pass Guaranteed 2026 Valid Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam New Test Bootcamp 🍡 Search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ and download it for free immediately on ⇛ www.pass4test.com ⇚ 😝Databricks-Certified-Professional-Data-Engineer Certification
- Detail Databricks-Certified-Professional-Data-Engineer Explanation 🧷 Databricks-Certified-Professional-Data-Engineer Hot Questions 🏩 Databricks-Certified-Professional-Data-Engineer Latest Test Labs 🦆 Easily obtain free download of “ Databricks-Certified-Professional-Data-Engineer ” by searching on [ www.pdfvce.com ] 💏Databricks-Certified-Professional-Data-Engineer Pdf Braindumps
- Databricks-Certified-Professional-Data-Engineer Latest Test Labs ⚗ High Databricks-Certified-Professional-Data-Engineer Quality ☮ Databricks-Certified-Professional-Data-Engineer Sample Test Online 💹 Download ➤ Databricks-Certified-Professional-Data-Engineer ⮘ for free by simply searching on ✔ www.practicevce.com ️✔️ 🛣Databricks-Certified-Professional-Data-Engineer Certification Torrent
- High Databricks-Certified-Professional-Data-Engineer Quality ✊ Databricks-Certified-Professional-Data-Engineer Latest Test Labs ℹ High Databricks-Certified-Professional-Data-Engineer Quality 🍵 Immediately open “ www.pdfvce.com ” and search for [ Databricks-Certified-Professional-Data-Engineer ] to obtain a free download 🚂Test Databricks-Certified-Professional-Data-Engineer Engine Version
- Excellent Databricks Databricks-Certified-Professional-Data-Engineer Practice Material's 3 formats 🤕 Search for [ Databricks-Certified-Professional-Data-Engineer ] and obtain a free download on 「 www.prepawayexam.com 」 👐Databricks-Certified-Professional-Data-Engineer Reliable Test Syllabus
- Latest Databricks Databricks-Certified-Professional-Data-Engineer of exam practice questions and answers free download 👓 Enter ▶ www.pdfvce.com ◀ and search for 【 Databricks-Certified-Professional-Data-Engineer 】 to download for free 💸High Databricks-Certified-Professional-Data-Engineer Quality
- Valid Braindumps Databricks-Certified-Professional-Data-Engineer Book 🍑 High Databricks-Certified-Professional-Data-Engineer Quality 🤛 Training Databricks-Certified-Professional-Data-Engineer Kit ☮ Search for [ Databricks-Certified-Professional-Data-Engineer ] and easily obtain a free download on ( www.easy4engine.com ) 💬Test Databricks-Certified-Professional-Data-Engineer Engine Version
- Excellent Databricks Databricks-Certified-Professional-Data-Engineer Practice Material's 3 formats 🈺 Search on ▛ www.pdfvce.com ▟ for ▷ Databricks-Certified-Professional-Data-Engineer ◁ to obtain exam materials for free download 😭Databricks-Certified-Professional-Data-Engineer Latest Version
- Avail Reliable Databricks-Certified-Professional-Data-Engineer New Test Bootcamp to Pass Databricks-Certified-Professional-Data-Engineer on the First Attempt 🥽 Open website “ www.dumpsquestion.com ” and search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 for free download 👤Reliable Databricks-Certified-Professional-Data-Engineer Exam Labs
- Databricks-Certified-Professional-Data-Engineer Test Dumps 👠 High Databricks-Certified-Professional-Data-Engineer Quality ➰ Training Databricks-Certified-Professional-Data-Engineer Kit 🤒 Open ⏩ www.pdfvce.com ⏪ and search for “ Databricks-Certified-Professional-Data-Engineer ” to download exam materials for free 🏃Databricks-Certified-Professional-Data-Engineer Latest Test Labs
- High Databricks-Certified-Professional-Data-Engineer Quality 🤙 Databricks-Certified-Professional-Data-Engineer Test Quiz 🎢 Test Databricks-Certified-Professional-Data-Engineer Engine Version 🕰 Easily obtain ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ for free download through ( www.vce4dumps.com ) ⛲Databricks-Certified-Professional-Data-Engineer Pdf Braindumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, github.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, telegra.ph, www.stes.tyc.edu.tw, Disposable vapes