We know that tenet from the bottom of our heart, so all parts of service are made due to your interests. You are entitled to have full money back if you fail the exam even after getting our Certified-Data-Engineer-Professional test prep. Our staff will help you with genial attitude. We esteem your variant choices so all these versions of Certified-Data-Engineer-Professional Study Materials are made for your individual preference and inclination.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Topic 2: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 3: Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Implement scalable Python/SQL code and project structures - Manage dependencies, libraries, and UDFs |
| Topic 4: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Topic 5: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Topic 6: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Topic 7: Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Topic 8: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Topic 9: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
>> Authentic Certified-Data-Engineer-Professional Exam Hub <<
Databricks Certified-Data-Engineer-Professional Exam is a very hot exam. Although it is difficult to pass the exam, the identification of entry point will make you easy to pass your exam. PassTestking practice test dumps are your best choice and hit rate is up to 100%. And our exam dumps can help you solve any questions of Certified-Data-Engineer-Professional exam. As long as you carefully study the questions in the dumps, all problems can be solved. Purchasing PassTestking certification training dumps, we provide you with free updates for a year. Within a year, as long as you want to update the dumps you have, you can get the latest version. Try it and see for yourself.
NEW QUESTION # 20
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats. After converting a subset of data to Delta Lake, they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join, whereas queries on legacy formats used Sort Merge Joins. The queries reading Delta Lake data also scanned less data. Which reason could be attributed to the difference in query performance?
Answer: C
Explanation:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage, data skipping, and file pruning. According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters, a process called data skipping and file pruning. Additionally, Delta uses a vectorized Parquet reader, which reduces I/O and CPU overhead. Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
NEW QUESTION # 21
A Delta Lake table in the Lakehouse named customer_parsams is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
Immediately after each update succeeds, the data engineer team would like to determine the difference between the new version and the previous of the table. Given the current implementation, which method can be used?
Answer: D
Explanation:
Delta Lake provides built-in versioning and time travel capabilities, allowing users to query previous snapshots of a table. This feature is particularly useful for understanding changes between different versions of the table. In this scenario, where the table is overwritten nightly, you can use Delta Lake's time travel feature to execute a query comparing the latest version of the table (the current state) with its previous version. This approach effectively identifies the differences (such as new, updated, or deleted records) between the two versions. The other options do not provide a straightforward or efficient way to directly compare different versions of a Delta Lake table.
NEW QUESTION # 22
A data engineer needs to design an efficient pipeline that automatically processes new CSV files as they arrive in S3 storage. Which Databricks feature should the data engineer use to meet these requirements?
Answer: D
Explanation:
Auto Loader is designed to efficiently and incrementally process new files as they arrive in cloud object storage. It provides scalable file discovery, supports schema inference and evolution, and minimizes overhead compared to traditional batch or manual streaming approaches.
NEW QUESTION # 23
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert: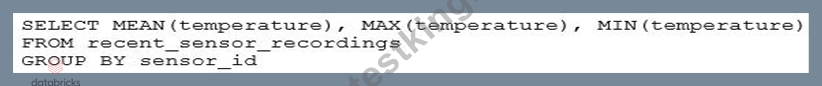
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
Answer: E
Explanation:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120.
NEW QUESTION # 24
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.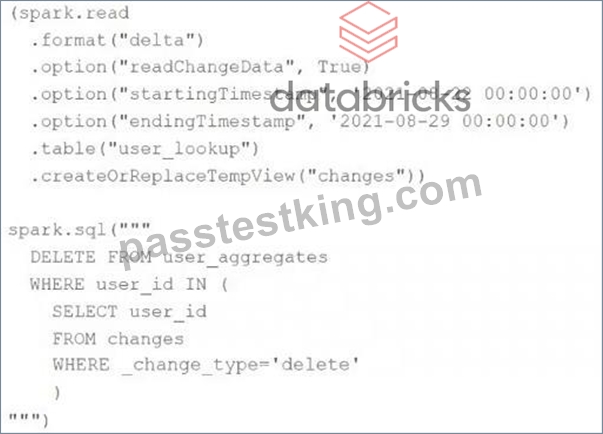
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
Answer: E
Explanation:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
NEW QUESTION # 25
......
Under coordinated synergy of all staff, our Certified-Data-Engineer-Professional guide materials achieved to a higher level of perfection by keeping close attention with the trend of dynamic market. They eliminated stereotypical content from our Certified-Data-Engineer-Professional practice materials. And if you download our Certified-Data-Engineer-Professional study quiz this time, we will send free updates for you one year long since we promise that our customers can enjoy free updates for one year.
Certified-Data-Engineer-Professional Dumps Torrent: https://www.passtestking.com/Databricks/Certified-Data-Engineer-Professional-practice-exam-dumps.html